DOWNLOAD the newest Real4Prep DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1MI65wUKObYtQBfq-OenOXJz8LAGZh-xm
Perhaps it was because of the work that there was not enough time to learn, or because the lack of the right method of learning led to a lot of time still failing to pass the DP-100 examination. Whether you are the first or the second or even more taking Microsoft examination, our DP-100 Exam Prep not only can help you to save much time and energy but also can help you pass the exam. In the other words, passing the exam once will no longer be a dream.
Microsoft DP-100 exam is a certification test that validates a candidate's knowledge and skills in designing and implementing data science solutions on Azure. DP-100 Exam is ideal for data scientists, data engineers, and AI developers who want to showcase their expertise in building and deploying intelligent solutions using Azure services. The DP-100 exam focuses on the core concepts of data science, including data exploration and preparation, modeling, feature engineering, and machine learning.
>> DP-100 Valid Exam Question <<
The Real4Prep is committed to providing the best possible study material to succeed in the Designing and Implementing a Data Science Solution on Azure (DP-100) exam. With actual PDF questions, customizable practice exams, and 24/7 support, customers can be confident that they are getting the best possible prep material. The Real4Prep DP-100 is an excellent choice for anyone looking to advance their career with the certification. Buy Now.
Microsoft DP-100 exam is an essential certification for data professionals who want to develop their skills in designing and implementing data solutions using Microsoft Azure. Designing and Implementing a Data Science Solution on Azure certification validates the candidate's knowledge of various aspects of data science, including data exploration, data preparation, data modeling, machine learning, and data visualization. The DP-100 Certification is recognized globally and can help the candidate to gain better job opportunities and career growth.
NEW QUESTION # 371
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are creating a new experiment in Azure Machine Learning Studio.
One class has a much smaller number of observations than the other classes in the training set.
You need to select an appropriate data sampling strategy to compensate for the class imbalance.
Solution: You use the Principal Components Analysis (PCA) sampling mode.
Does the solution meet the goal?
Answer: A
Explanation:
Instead use the Synthetic Minority Oversampling Technique (SMOTE) sampling mode.
Note: SMOTE is used to increase the number of underepresented cases in a dataset used for machine learning. SMOTE is a better way of increasing the number of rare cases than simply duplicating existing cases.
Incorrect Answers:
The Principal Component Analysis module in Azure Machine Learning Studio (classic) is used to reduce the dimensionality of your training data. The module analyzes your data and creates a reduced feature set that captures all the information contained in the dataset, but in a smaller number of features.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/smote
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/principal-component- analysis
NEW QUESTION # 372
You need to replace the missing data in the AccessibilityToHighway columns.
How should you configure the Clean Missing Data module? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.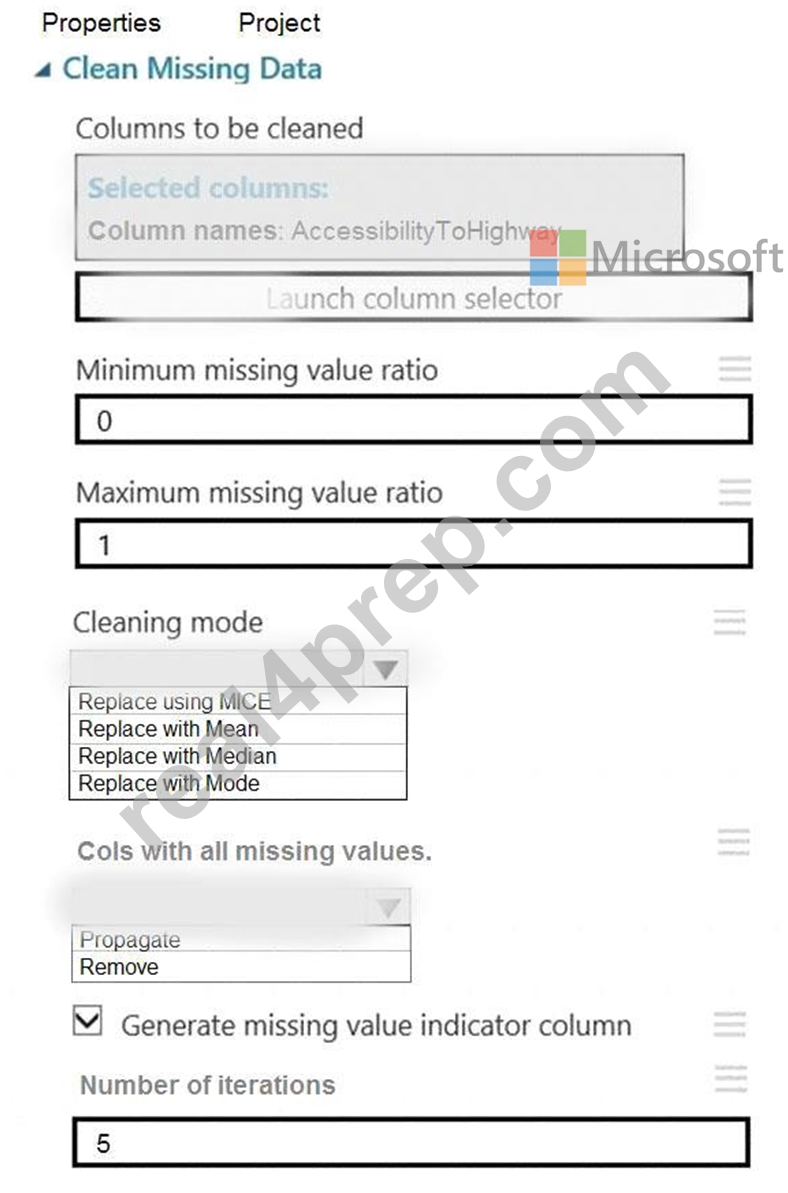
Answer:
Explanation: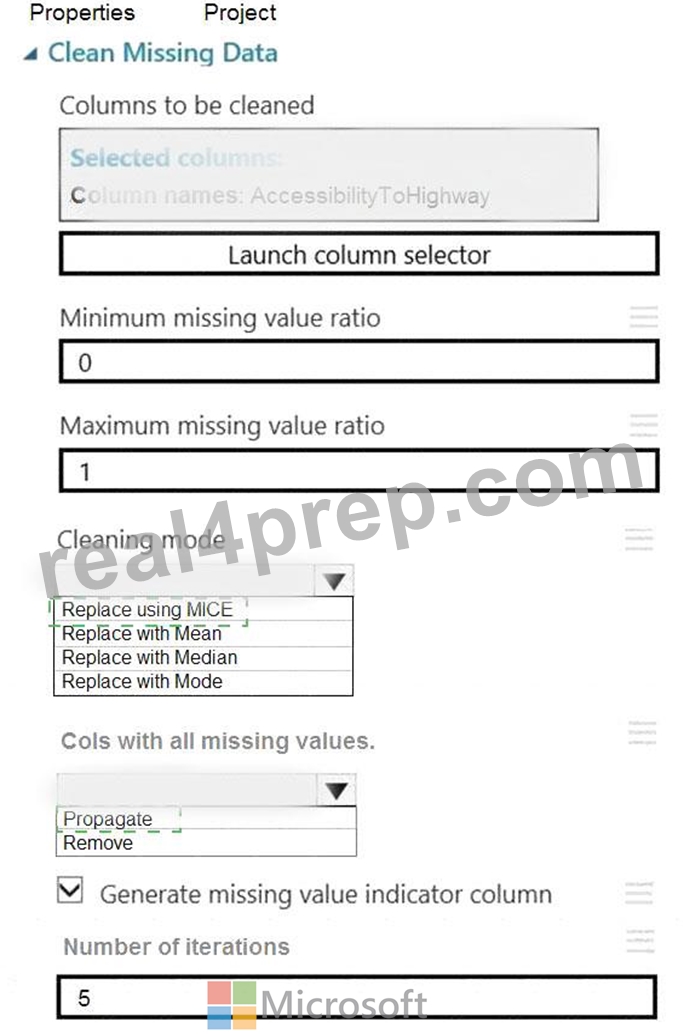
Explanation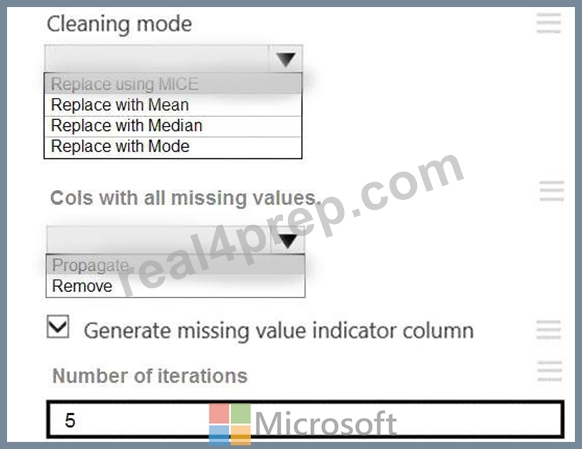
Box 1: Replace using MICE
Replace using MICE: For each missing value, this option assigns a new value, which is calculated by using a method described in the statistical literature as "Multivariate Imputation using Chained Equations" or
"Multiple Imputation by Chained Equations". With a multiple imputation method, each variable with missing data is modeled conditionally using the other variables in the data before filling in the missing values.
Scenario: The AccessibilityToHighway column in both datasets contains missing values. The missing data must be replaced with new data so that it is modeled conditionally using the other variables in the data before filling in the missing values.
Box 2: Propagate
Cols with all missing values indicate if columns of all missing values should be preserved in the output.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/clean-missing-data
NEW QUESTION # 373
You are creating a machine learning model that can predict the species of a penguin from its measurements.
You have a file that contains measurements for free species of penguin in comma delimited format.
The model must be optimized for area under the received operating characteristic curve performance metric averaged for each class.
You need to use the Automated Machine Learning user interface in Azure Machine Learning studio to run an experiment and find the best performing model.
Which five actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the collect order.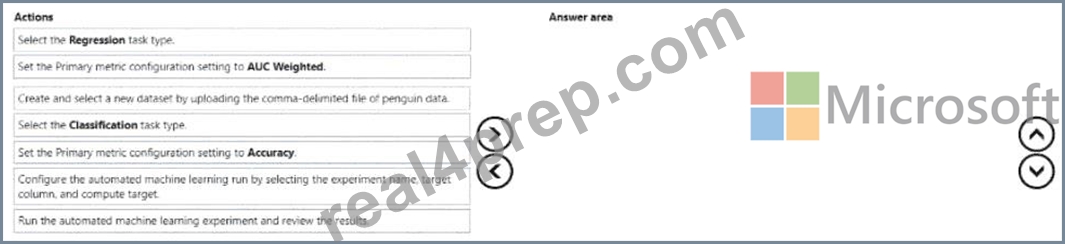
Answer:
Explanation: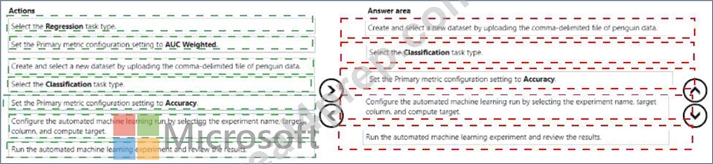
Explanation: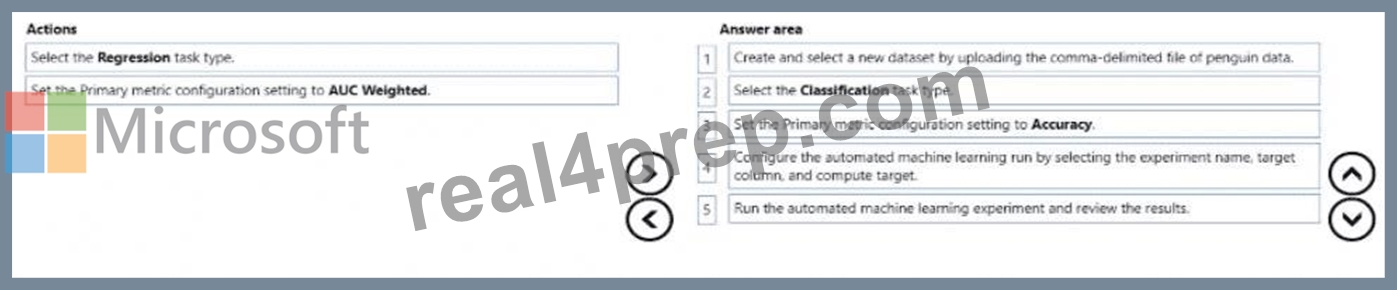
NEW QUESTION # 374
You plan to preprocess text from CSV files. You load the Azure Machine Learning Studio default stop words list.
You need to configure the Preprocess Text module to meet the following requirements:
* Ensure that multiple related words from a single canonical form.
* Remove pipe characters from text.
* Remove words to optimize information retrieval.
Which three options should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.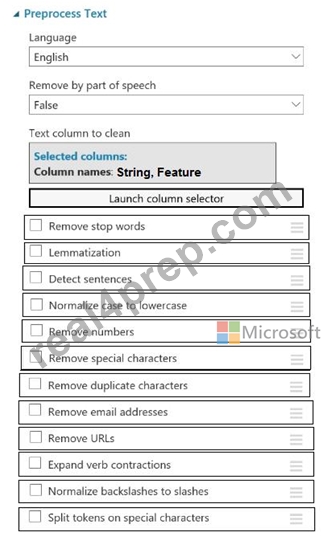
Answer:
Explanation: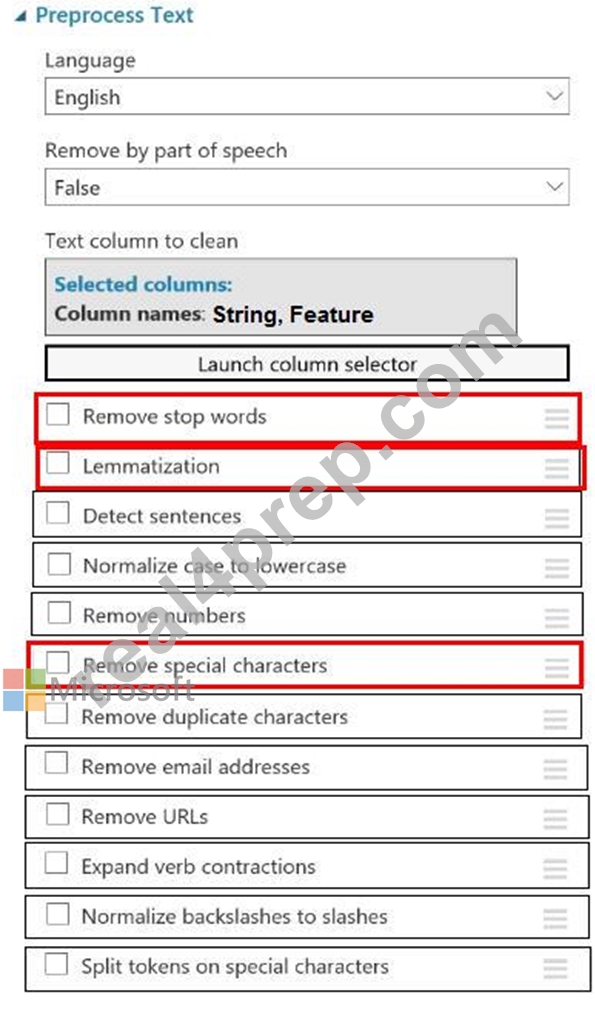
Explanation:
Box 1: Remove stop words
Remove words to optimize information retrieval.
Remove stop words: Select this option if you want to apply a predefined stopword list to the text column. Stop word removal is performed before any other processes.
Box 2: Lemmatization
Ensure that multiple related words from a single canonical form.
Lemmatization converts multiple related words to a single canonical form Box 3: Remove special characters Remove special characters: Use this option to replace any non-alphanumeric special characters with the pipe | character.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/preprocess-text
NEW QUESTION # 375
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You create an Azure Machine Learning service datastore in a workspace. The datastore contains the following files:
* /data/2018/Q1.csv
* /data/2018/Q2.csv
* /data/2018/Q3.csv
* /data/2018/Q4.csv
* /data/2019/Q1.csv
All files store data in the following format:
id,f1,f2,I
1,1,2,0
2,1,1,1
3,2,1,0
4,2,2,1
You run the following code: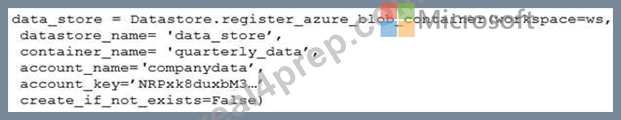
You need to create a dataset named training_data and load the data from all files into a single data frame by using the following code:
Solution: Run the following code:
Does the solution meet the goal?
Answer: A
Explanation:
Use two file paths.
Use Dataset.Tabular_from_delimeted, instead of Dataset.File.from_files as the data isn't cleansed.
Note:
A FileDataset references single or multiple files in your datastores or public URLs. If your data is already cleansed, and ready to use in training experiments, you can download or mount the files to your compute as a FileDataset object.
A TabularDataset represents data in a tabular format by parsing the provided file or list of files. This provides you with the ability to materialize the data into a pandas or Spark DataFrame so you can work with familiar data preparation and training libraries without having to leave your notebook. You can create a TabularDataset object from .csv, .tsv, .parquet, .jsonl files, and from SQL query results.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-create-register-datasets
NEW QUESTION # 376
......
DP-100 Relevant Exam Dumps: https://www.real4prep.com/DP-100-exam.html
BONUS!!! Download part of Real4Prep DP-100 dumps for free: https://drive.google.com/open?id=1MI65wUKObYtQBfq-OenOXJz8LAGZh-xm