BTW, DOWNLOAD part of Actualtests4sure ARA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1fgqTPmPnhlea9MH-aw6sPI8NaIh9aSdp
One of the major features provided by Snowflake is that it will provide you with free Snowflake ARA-C01 actual questions updates for 365 days after the purchase of our product. If you work hard with our Snowflake ARA-C01 Exam Practice material, nothing can stop you from cracking the test on the first endeavor.
| Section | Objectives |
|---|---|
| Topic 1: Performance and Optimization | - Query performance tuning
|
| Topic 2: Data Pipelines and Data Engineering | - Data ingestion and transformation
|
| Topic 3: Data Architecture and Design | - Data modeling and schema design
|
| Topic 4: Data Sharing and Collaboration | - Secure data sharing
|
| Topic 5: Security, Governance, and Compliance | - Data governance
|
>> ARA-C01 Reliable Practice Questions <<
Direct and dependable Snowflake ARA-C01 Exam Questions in three formats will surely help you pass the SnowPro Advanced Architect Certification ARA-C01 certification exam. Because this is a defining moment in your career, do not undervalue the importance of our SnowPro Advanced Architect Certification ARA-C01 Exam Dumps. Profit from the opportunity to get these top-notch exam questions for the Snowflake ARA-C01 certification test.
NEW QUESTION # 67
How can the Snowpipe REST API be used to keep a log of data load history?
Answer: B
Explanation:
* Snowpipe is a service that automates and optimizes the loading of data from external stages into Snowflake tables. Snowpipe uses a queue to ingest files as they become available in the stage. Snowpipe also provides REST endpoints to load data and retrieve load history reports1.
* The loadHistoryScan endpoint returns the history of files that have been ingested by Snowpipe within a specified time range. The endpoint accepts the following parameters2:
* pipe: The fully-qualified name of the pipe to query.
* startTimeInclusive: The start of the time range to query, in ISO 8601 format. The value must be within the past 14 days.
* endTimeExclusive: The end of the time range to query, in ISO 8601 format. The value must be later than the start time and within the past 14 days.
* recentFirst: A boolean flag that indicates whether to return the most recent files first or last. The default value is false, which means the oldest files are returned first.
* showSkippedFiles: A boolean flag that indicates whether to include files that were skipped by Snowpipe in the response. The default value is false, which means only files that were loaded are returned.
* The loadHistoryScan endpoint can be used to keep a log of data load history by calling it periodically with a suitable time range. The best option among the choices is D, which is to call loadHistoryScan every 10 minutes for a 15-minute time range. This option ensures that the endpoint is called frequently enough to capture the latest files that have been ingested, and that the time range is wide enough to avoid missing any files that may have been delayed or retried by Snowpipe. The other options are either too infrequent, too narrow, or use the wrong endpoint3.
1: Introduction to Snowpipe | Snowflake Documentation
2: loadHistoryScan | Snowflake Documentation
3: Monitoring Snowpipe Load History | Snowflake Documentation
NEW QUESTION # 68
A company's daily Snowflake workload consists of a huge number of concurrent queries triggered between
9pm and 11pm. At the individual level, these queries are smaller statements that get completed within a short time period.
What configuration can the company's Architect implement to enhance the performance of this workload?
(Choose two.)
Answer: A,C
Explanation:
These two configuration options can enhance the performance of the workload that consists of a huge number of concurrent queries that are smaller and faster.
* Enabling a multi-clustered virtual warehouse in maximized mode allows the warehouse to scale out automatically by adding more clusters as soon as the current cluster is fully loaded, regardless of the number of queries in the queue. This can improve the concurrency and throughput of the workload by minimizing or preventing queuing. The maximized mode is suitable for workloads that require high performance and low latency, and are less sensitive to credit consumption1.
* Setting the MAX_CONCURRENCY_LEVEL to a higher value than its default value of 8 at the virtual warehouse level allows the warehouse to run more queries concurrently on each cluster. This can
* improve the utilization and efficiency of the warehouse resources, especially for smaller and faster queries that do not require a lot of processing power. The MAX_CONCURRENCY_LEVEL parameter can be set when creating or modifying a warehouse, and it can be changed at any time2.
References:
* Snowflake Documentation: Scaling Policy for Multi-cluster Warehouses
* Snowflake Documentation: MAX_CONCURRENCY_LEVEL
NEW QUESTION # 69
What is a valid object hierarchy when building a Snowflake environment?
Answer: C
Explanation:
Explanation
This is the valid object hierarchy when building a Snowflake environment, according to the Snowflake documentation and the web search results. Snowflake is a cloud data platform that supports various types of objects, such as databases, schemas, tables, views, stages, warehouses, and more. These objects are organized in a hierarchical structure, as follows:
* Organization: An organization is the top-level entity that represents a group of Snowflake accounts that are related by business needs or ownership. An organization can have one or more accounts, and can enable features such as cross-account data sharing, billing and usage reporting, and single sign-on across accounts12.
* Account: An account is the primary entity that represents a Snowflake customer. An account can have one or more databases, schemas, stages, warehouses, and other objects. An account can also have one or more users, roles, and security integrations. An account is associated with a specific cloud platform, region, and Snowflake edition34.
* Database: A database is a logical grouping of schemas. A database can have one or more schemas, and can store structured, semi-structured, or unstructured data. A database can also have properties such as retention time, encryption, and ownership56.
* Schema: A schema is a logical grouping of tables, views, stages, and other objects. A schema can have one or more objects, and can define the namespace and access control for the objects. A schema can also have properties such as ownership and default warehouse .
* Stage: A stage is a named location that references the files in external or internal storage. A stage can be used to load data into Snowflake tables using the COPY INTO command, or to unload data from Snowflake tables using the COPY INTO LOCATION command. A stage can be created at the account, database, or schema level, and can have properties such as file format, encryption, and credentials .
The other options listed are not valid object hierarchies, because they either omit or misplace some objects in the structure. For example, option A omits the organization level and places the warehouse under the schema level, which is incorrect. Option C omits the organization, account, and stage levels, and places the table under the schema level, which is incorrect. Option D omits the database level and places the stage and table under the account level, which is incorrect.
References:
* Snowflake Documentation: Organizations
* Snowflake Blog: Introducing Organizations in Snowflake
* Snowflake Documentation: Accounts
* Snowflake Blog: Understanding Snowflake Account Structures
* Snowflake Documentation: Databases
* Snowflake Blog: How to Create a Database in Snowflake
* [Snowflake Documentation: Schemas]
* [Snowflake Blog: How to Create a Schema in Snowflake]
* [Snowflake Documentation: Stages]
* [Snowflake Blog: How to Use Stages in Snowflake]
NEW QUESTION # 70
Which query will identify the specific days and virtual warehouses that would benefit from a multi-cluster warehouse to improve the performance of a particular workload?
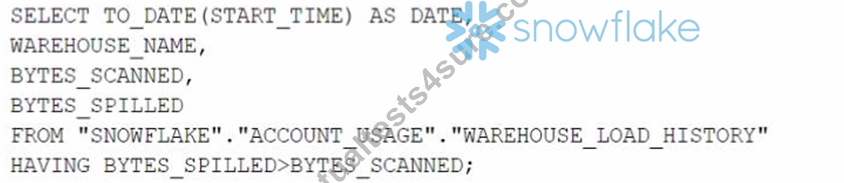
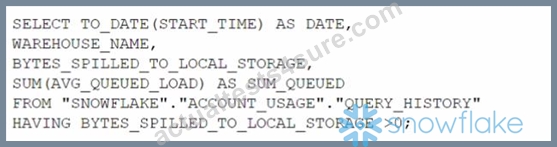
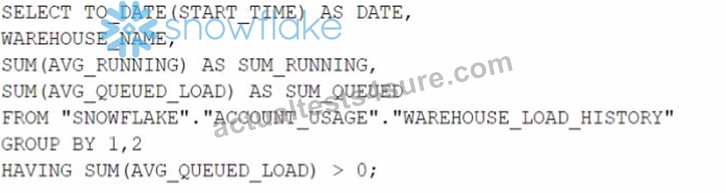
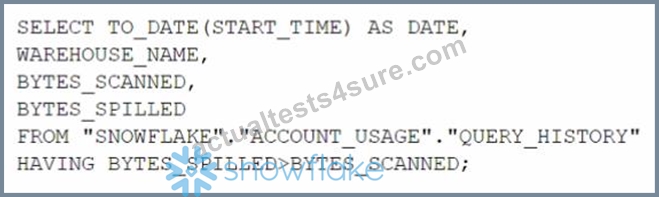
Answer: C
NEW QUESTION # 71
When using the copy into <table> command with the CSV file format, how does the match_by_column_name parameter behave?
Answer: B
Explanation:
Option B is the best design to meet the requirements because it uses Snowpipe to ingest the data continuously and efficiently as new records arrive in the object storage, leveraging event notifications. Snowpipe is a service that automates the loading of data from external sources into Snowflake tables1. It also uses streams and tasks to orchestrate transformations on the ingested data. Streams are objects that store the change history of a table, and tasks are objects that execute SQL statements on a schedule or when triggered by another task2.
Option B also uses an external function to do model inference with Amazon Comprehend and write the final records to a Snowflake table. An external function is a user-defined function that calls an external API, such as Amazon Comprehend, to perform computations that are not natively supported by Snowflake3. Finally, option B uses the Snowflake Marketplace to make the de-identified final data set available publicly for advertising companies who use different cloud providers in different regions. The Snowflake Marketplace is a platform that enables data providers to list and share their data sets with data consumers, regardless of the cloud platform or region they use4.
Option A is not the best design because it uses copy into to ingest the data, which is not as efficient and continuous as Snowpipe. Copy into is a SQL command that loads data from files into a table in a single transaction. It also exports the data into Amazon S3 to do model inference with Amazon Comprehend, which adds an extra step and increases the operational complexity and maintenance of the infrastructure.
Option C is not the best design because it uses Amazon EMR and PySpark to ingest and transform the data, which also increases the operational complexity and maintenance of the infrastructure. Amazon EMR is a cloud service that provides a managed Hadoop framework to process and analyze large-scale data sets.
PySpark is a Python API for Spark, a distributed computing framework that can run on Hadoop. Option C also develops a python program to do model inference by leveraging the Amazon Comprehend text analysis API, which increases the development effort.
Option D is not the best design because it is identical to option A, except for the ingestion method. It still exports the data into Amazon S3 to do model inference with Amazon Comprehend, which adds an extra step and increases the operational complexity and maintenance of the infrastructure.
References: 1: Snowpipe Overview 2: Using Streams and Tasks to Automate Data Pipelines 3: External Functions Overview 4: Snowflake Data Marketplace Overview : [Loading Data Using COPY INTO] : [What is Amazon EMR?] : [PySpark Overview]
* The copy into <table> command is used to load data from staged files into an existing table in Snowflake. The command supports various file formats, such as CSV, JSON, AVRO, ORC, PARQUET, and XML1.
* The match_by_column_name parameter is a copy option that enables loading semi-structured data into separate columns in the target table that match corresponding columns represented in the source data. The parameter can have one of the following values2:
* CASE_SENSITIVE: The column names in the source data must match the column names in the target table exactly, including the case. This is the default value.
* CASE_INSENSITIVE: The column names in the source data must match the column names in
* the target table, but the case is ignored.
* NONE: The column names in the source data are ignored, and the data is loaded based on the order of the columns in the target table.
* The match_by_column_name parameter only applies to semi-structured data, such as JSON, AVRO, ORC, PARQUET, and XML. It does not apply to CSV data, which is considered structured data2.
* When using the copy into <table> command with the CSV file format, the match_by_column_name parameter behaves as follows2:
* It expects a header to be present in the CSV file, which is matched to a case-sensitive table column name. This means that the first row of the CSV file must contain the column names, and they must match the column names in the target table exactly, including the case. If the header is missing or does not match, the command will return an error.
* The parameter will not be ignored, even if it is set to NONE. The command will still try to match the column names in the CSV file with the column names in the target table, and will return an error if they do not match.
* The command will not return a warning stating that the file has unmatched columns. It will either load the data successfully if the column names match, or return an error if they do not match.
References:
* 1: COPY INTO <table> | Snowflake Documentation
* 2: MATCH_BY_COLUMN_NAME | Snowflake Documentation
NEW QUESTION # 72
......
We are professional at providing best and valid ARA-C01 exam materials to help the candidates successfully pass their ARA-C01 exams with ease as well as establish their confidence. The precise and valid ARA-C01 exam torrent compiled by our experts is outstanding and tested by our clients all over the world. The numerous feedbacks from our clients proved our influence and charisma. We can provide you the fastest way to get your dreaming ARA-C01 Certification.
ARA-C01 New Test Bootcamp: https://www.actualtests4sure.com/ARA-C01-test-questions.html
DOWNLOAD the newest Actualtests4sure ARA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1fgqTPmPnhlea9MH-aw6sPI8NaIh9aSdp