Our AI-300 study question has high quality. So there is all effective and central practice for you to prepare for your test. With our professional ability, we can accord to the necessary testing points to edit AI-300 exam questions. It points to the exam heart to solve your difficulty. With a minimum number of questions and answers of AI-300 Test Guide to the most important message, to make every user can easily efficient learning, not to increase their extra burden, finally to let the AI-300 exam questions help users quickly to pass the exam.
| Section | Objectives |
|---|---|
| Topic 1: Optimize generative AI systems and model performance | - Fine-tune and distill models for specific use cases - Tune prompts, system messages, and grounding strategies - Implement cost management and scaling strategies for GenAI workloads - Optimize inference performance, caching, and throughput |
| Topic 2: Design and implement an MLOps infrastructure | - Set up Azure Machine Learning workspace and compute targets - Implement security, governance, and compliance for MLOps - Configure source control, CI/CD pipelines, and automation for ML workflows - Manage environments, data stores, and model registries |
| Topic 3: Implement generative AI quality assurance and observability | - Implement logging, tracing, and telemetry for GenAI applications - Evaluate generative AI outputs for quality, safety, and grounding - Monitor latency, token usage, cost, and error rates - Conduct red teaming, adversarial testing, and content filtering |
| Topic 4: Implement machine learning model lifecycle and operations | - Monitor model performance, data drift, and operational health - Train, register, and version models using Azure Machine Learning - Retrain, update, and manage model versions in production - Deploy models to real-time and batch endpoints |
| Topic 5: Design and implement a GenAIOps infrastructure | - Configure prompt orchestration, prompt flows, and agent frameworks - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Manage API keys, rate limits, and responsible AI guardrails - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search |
>> AI-300 Exam Registration <<
To clear the Operationalizing Machine Learning and Generative AI Solutions AI-300 exam questions in one go and not waste your time and money, follow these tips and see the result yourself. And when you know that you are ready with all the Operationalizing Machine Learning and Generative AI Solutions AI-300 Preparation, just relax, breathe and chill out. You have put your best efforts to mark your success and you shall get the best outcome out of it.
NEW QUESTION # 32
-
You have an Azure Machine Learning workspace and a collection of image files stored in two Azure Blob Storage accounts.
You need to configure data asset properties.
Which values should you use in your configuration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.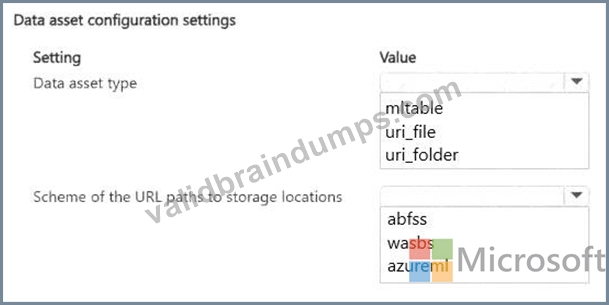
Answer:
Explanation: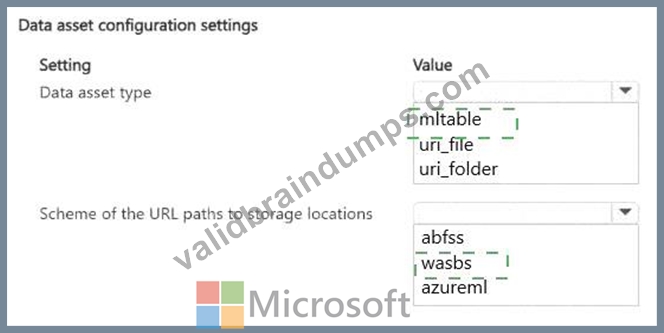
Explanation:
Data asset type: mltable
Scheme of the URL paths to storage locations: wasbs
The correct data asset type is mltable because the image collection is distributed across multiple storage locations . Microsoft identifies MLTable as the appropriate Azure Machine Learning data asset type when unstructured data such as images, text, or audio is spread across multiple storage locations. An MLTable definition can contain multiple file, folder, or pattern entries, allowing one logical data asset to reference image data residing in different storage accounts.
A uri_folder data asset is appropriate when the required unstructured files reside within a single folder path .
It represents one folder location and therefore does not provide the same multi-path abstraction required by this scenario. uri_file represents only an individual file and is clearly unsuitable for a collection of images.
For the path scheme, Azure Machine Learning uses wasbs:// for Azure Blob Storage. Microsoft documents the canonical format as:
wasbs:// < container > @ < account > .blob.core.windows.net/ < path >
By comparison, abfss:// is used for Azure Data Lake Storage Gen2, while azureml:// identifies Azure Machine Learning datastore paths rather than direct Azure Blob Storage URLs.
Therefore, an MLTable containing multiple wasbs:// paths correctly represents image files distributed across the two Azure Blob Storage accounts.
Study Guide Reference: Design and implement an MLOps infrastructure - Azure Machine Learning data assets, MLTable, multi-location datasets, storage URI schemes, and Blob Storage integration.
NEW QUESTION # 33
You have a deployment of an Azure OpenAI Service base model.
You plan to fine-tune the model.
You need to prepare a file that contains training data.
Which file format should you use?
Answer: B
Explanation:
To fine-tune a model in the Azure OpenAI Service, your training data must be in JSONL (JSON Lines) format.
File Requirements
Format: Each line of the file must be a single, valid JSON object.
Encoding: The file must be encoded in UTF-8.
Special Requirement: For some older tools or specific Azure OpenAI use cases, the file may need to include a byte-order mark (BOM).
Size Limits: Individual files typically have a maximum size (e.g., 100 MB per file in some contexts), but you can often upload multiple files.
Reference:
https://dev.to/icebeam7/fine-tuning-a-model-with-azure-open-ai-studio-39p7
NEW QUESTION # 34
You are authoring a notebook in Azure Machine Learning studio.
You must install packages from the notebook into the currently running kernel. The installation must be limited to the currently running kernel only.
You need to install the packages.
Which magic function should you use?
Answer: A
Explanation:
The correct choice is %pip . Azure Machine Learning compute instances can contain multiple Jupyter kernels, so package installation must target the interpreter associated with the notebook ' s currently active kernel . Microsoft explicitly recommends the %pip or %conda IPython magic commands for this purpose because these commands install packages into the environment associated with the running kernel.
For example, a notebook cell can contain:
%pip install scikit-learn
This ensures that the installed package becomes available to code executed by that notebook kernel.
By contrast, !pip invokes a shell command. Microsoft specifically warns against using !pip or !conda when the intention is to modify only the current notebook kernel, because shell-level package commands can reference environments or packages outside the active kernel.
%load has an entirely different purpose: it loads Python source code into a notebook cell and does not perform package installation.
Therefore, when package installation must be isolated to the active Azure Machine Learning notebook kernel,
%pip is the appropriate magic command .
Study Guide Reference: Design and implement an MLOps infrastructure - Azure Machine Learning development environments, notebook kernels, dependency management, and compute instances.
NEW QUESTION # 35
-
You use Azure Machine Learning to deploy a model as a real-time web service.
You need to create an entry script for the service that ensures that the model is loaded when the service starts and is used to score new data as it is received.
Which functions should you include in the script? To answer, drag the appropriate functions to the correct actions. Each function may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.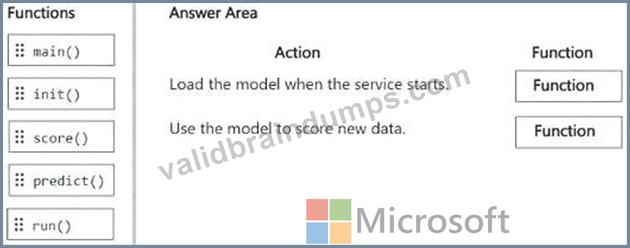
Answer:
Explanation: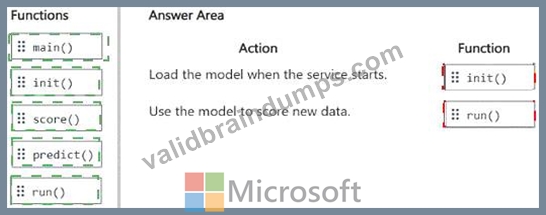
Explanation:
Load the model when the service starts: init()
Use the model to score new data: run()
Azure Machine Learning scoring scripts for online endpoints use two required entry-point functions: init() and run() . Microsoft explicitly states that the scoring script specified for an online deployment must contain both functions.
The init() function is invoked when the inference container is initialized or started, typically immediately after a deployment is created or updated. It is intended for one-time initialization tasks such as locating the registered model through AZUREML_MODEL_DIR, deserializing the model, and storing it in memory.
Loading the model once during initialization avoids repeatedly loading it for every inference request, which reduces latency and processing overhead.
The run() function is called each time the endpoint receives an inference request. It accepts the incoming request data, transforms or parses the input as required, invokes the loaded model ' s prediction logic, and returns the scoring result. Microsoft describes run() as the function that performs the actual scoring or prediction for each endpoint invocation.
main(), score(), and predict() may exist inside application code or model libraries, but they are not the required Azure Machine Learning scoring-script entry points.
NEW QUESTION # 36
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
An organization provisions Azure Machine Learning workspaces for development, test, and production environments.
Each environment must be deployed consistently and updated through source control. The deployment process must be automated, repeatable, and auditable.
You need to deploy Azure Machine Learning resources in a consistent and controlled manner.
Solution: Define Azure Machine Learning resources in a Bicep template and deploy them within a GitHub Action.
Does the solution meet the goal?
Answer: B
Explanation:
Correct:
* Define Azure Machine Learning resources in a Bicep template and deploy them within a GitHub Action.
This action is best because it fulfills all of your operational requirements:
Consistency & Controlled Manner:
Infrastructure as Code (IaC) via Bicep ensures that dev, test, and prod environments are configured identically, eliminating configuration drift.
Source Control: Storing the Bicep template in a Git repository satisfies the requirement that each environment must be updated through source control.
Automated & Repeatable: Orchestrating the deployment using GitHub Actions fully automates the workflow, allowing it to be executed reliably every time a change is merged.
Auditable: Git commit histories combined with GitHub deployment logs provide a comprehensive, compliant audit trail of exactly who modified the infrastructure and when.
Incorrect:
* Clone an existing Azure Machine Learning workspace to create additional environments.
* Create Azure Machine Learning workspaces manually in the Azure portal for each environment.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-github-actions-machine-learning
NEW QUESTION # 37
......
High efficiency service has won reputation for us among multitude of customers, so choosing our AI-300 real study dumps we guarantee that you won’t be regret of your decision. Helping our candidates to pass the AI-300 exam and achieve their dream has always been our common ideal. We believe that your satisfactory on our AI-300 Exam Questions is the drive force for our company. Meanwhile, we adopt a reasonable price for you, ensures people whoever is rich or poor would have the equal access to buy our useful AI-300 real study dumps.
Valid AI-300 Test Duration: https://www.validbraindumps.com/AI-300-exam-prep.html