2026 Latest Lead2Passed DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=1TOJZgL6DrPxURRHm4i3_nDi-ODuaAwT4
The high quality and high efficiency of DP-750 study guide make it stand out in the products of the same industry. Our study materials have always been considered for the users. If you choose our DP-750 exam questions, you will become a better self. DP-750 actual exam want to contribute to your brilliant future. Our study materials are constantly improving themselves. If you have any good ideas, our study materials are very happy to accept them. DP-750 Exam Materials are looking forward to having more partners to join this family. We will progress together and become better ourselves.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
>> Reliable DP-750 Exam Registration <<
As is known to us, if there are many people who are plugged into the internet, it will lead to unstable state of the whole network, and you will not use your study materials in your lunch time. If you choice our DP-750 exam question as your study tool, you will not meet the problem. Because the app of our DP-750 Exam Prep supports practice offline in anytime. If you buy our products, you can also continue your study when you are in an offline state. You will not be affected by the unable state of the whole network. You can choose to use our DP-750 exam prep in anytime and anywhere.
NEW QUESTION # 23
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 runs every hour.
Occasionally, Job1 takes longer than one hour to complete.
You need to configure the job scheduling behavior to meet the following requirements:
* Overlapping runs must be prevented to avoid data corruption.
* Scheduled runs must not be discarded when another run is already active.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Concurrency setting: Limit concurrent runs to one.
Execution behavior: Queue the new run.
Limiting concurrent runs to one ensures that only one instance of Job1 can execute at a time. This prevents two hourly runs from simultaneously modifying the same tables, files, checkpoints, or downstream systems, thereby reducing the risk of duplicate processing and data corruption. When a scheduled trigger occurs while an earlier execution is still active, queueing the new run preserves that execution and starts it after the active run finishes. Allowing concurrent runs would violate the non-overlap requirement. Restarting the job during an overlap could interrupt partially completed work. Canceling the new run or skipping it would avoid simultaneous execution, but the scheduled processing interval could be lost. Single-run concurrency combined with queueing therefore serializes the executions without discarding scheduled work.
NEW QUESTION # 24
You have an Azure Databticks workspace that contains an all-purpose compute cluster named Cluster1.
Cluser1 is used for
interactive development.
You need to configure Cluster1 to meet the following requirements:
* Automatically add and remove worker nodes based on workload demand
* Automatically shut down when the cluster has been idle for a specific period.
What should you configure for each requirement? To answer, drag the appropriate options to the correct requirements. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.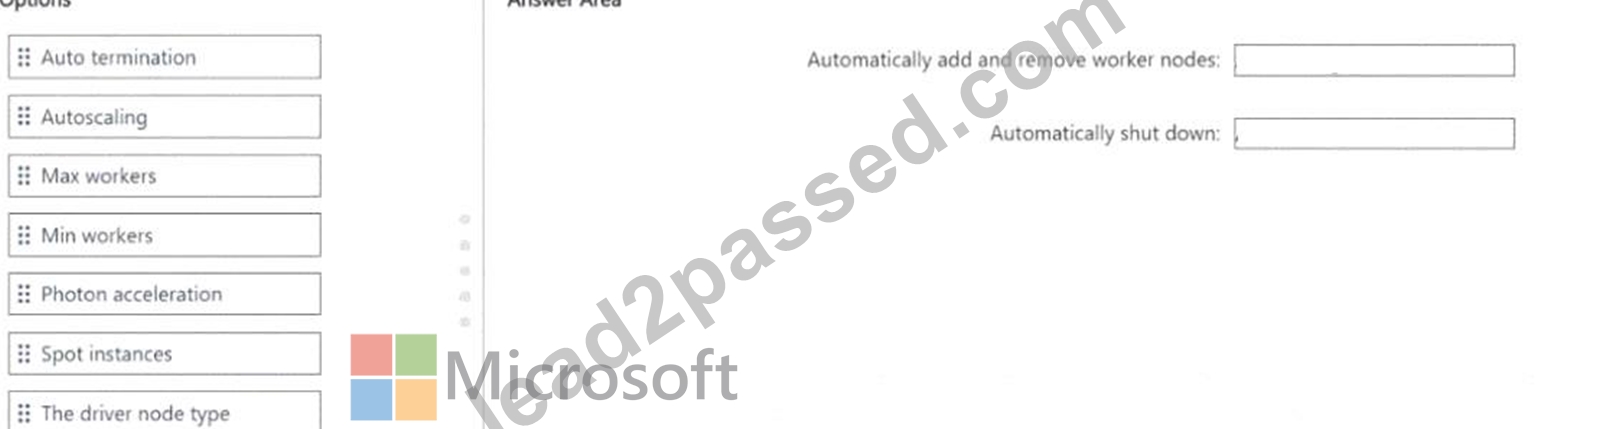
Answer:
Explanation:
Explanation:
Two separate cluster settings address the two requirements:
Autoscaling handles the first requirement - dynamically adding workers when the workload is heavy and removing them when it lightens. You set a minimum and maximum node count, and Databricks adjusts the cluster size between those bounds based on task queue depth.
Auto-termination handles the second - the cluster shuts itself down after a configurable idle period (e.g., 30 minutes with no active queries), preventing wasted spend on a development cluster left running overnight.
These two settings are independent and complementary: autoscaling manages horizontal elasticity during active use, while auto-termination manages complete shutdown during inactivity. Both are configured in the cluster creation UI under the Compute section.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/configure#autoscaling
NEW QUESTION # 25
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Payments.
Payments stores transaction data and contains a column named payment_amount of the Decimal data type.
You must enforce the following business rule:
payment_amount must be between 0 and 10,000, inclusive
You need to ensure that records that violate the rule are rejected when data is written to the Payments table.
What should you do?
Answer: D
Explanation:
A CHECK constraint enforces a Boolean condition whenever data is inserted or updated. The constraint can require payment_amount > = 0 AND payment_amount < = 10000, causing a transaction containing an invalid value to fail instead of allowing the record into Payments. This provides storage-level data-quality enforcement regardless of which pipeline, notebook, or SQL statement performs the write. Row-level security controls which existing records users can see; it does not reject invalid writes. SELECT statements filter results only when they are executed and therefore cannot protect the underlying table. Table update triggers are not the standard Delta Lake mechanism for this requirement. Azure Databricks classifies CHECK constraints as enforced constraints and rejects transactions when their conditions are violated. Microsoft Learn
NEW QUESTION # 26
You have an Azure Databticks workspace that is enabled for Unity Catalog and contains a catalog named catalog1.
You have a group named group!
You plan to create a schema named schema1 in catalog1.
You need to ensure that group1 meets the following requirements:
* Can create tables in schema1
* Can modify and query tables
* Cannot grant permissions for the schema and its objects
How should you complete the SQL statements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
The correct SQL grants group1 the ability to work within the schema without delegating that ability to anyone else:
GRANT USE SCHEMA ON schema1 TO group1 - required as a prerequisite to access any object inside the schema.
GRANT CREATE TABLE ON SCHEMA schema1 TO group1 - allows creating new tables.
GRANT SELECT, MODIFY ON SCHEMA schema1 TO group1 - SELECT for queries, MODIFY for INSERT/UPDATE/DELETE operations.
Crucially, MANAGE is NOT granted. In Unity Catalog, MANAGE is what allows a principal to grant and revoke privileges on the schema and its objects. Leaving it out means group1 can do all the data work but cannot redistribute those permissions - precisely what the requirement 'Cannot grant permissions for the schema and its objects' demands.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/manage- privileges/privileges
NEW QUESTION # 27
You use Databricks Asset Bundles to manage two jobs and an app.
You need to deploy the bundle to development and production environments. The solution must meet the following requirements
* Deploy the app to both environments.
* Deploy only one job to development.
* Minimize administrative effort.
What should you use?
Answer: A
Explanation:
The correct answer is D - a targets node in databricks.yml.
Databricks Asset Bundles use a single databricks.yml to define all resources (jobs, apps, pipelines) once, and a targets node to define per-environment overrides. Within the development target, you can use the include
/exclude mechanism or resource-level overrides to deploy only one of the two jobs. The app and the second job are deployed to both environments through the shared resource definition.
Option B (separate databricks.yml files per environment) works technically but means duplicating the shared resource definitions across files - any change to a shared resource requires edits in multiple places, which is exactly the administrative overhead the question wants to avoid.
Option A (resources node) defines resources globally across all targets - it doesn't provide environment- specific filtering. Option C (variables node) parameterises values like cluster sizes or paths but doesn't control which resources are deployed to which environment.
Reference: https://learn.microsoft.com/en-us/azure/databricks/dev-tools/bundles/deployment-modes
NEW QUESTION # 28
......
In order to help you control the DP-750 examination time, we have considerately designed a special timer to help your adjust the pace of answering the questions of the DP-750 study materials. Many people always are stopped by the difficult questions. Then they will fall into thoughts to try their best to answer the questions of the DP-750 Real Exam. But they forgot to answer the other questions, our DP-750 training guide can help you solve this problem and get used to the pace.
Test DP-750 Engine Version: https://www.lead2passed.com/Microsoft/DP-750-practice-exam-dumps.html
P.S. Free 2026 Microsoft DP-750 dumps are available on Google Drive shared by Lead2Passed: https://drive.google.com/open?id=1TOJZgL6DrPxURRHm4i3_nDi-ODuaAwT4