P.S. Free 2026 Anthropic CCAR-P dumps are available on Google Drive shared by PrepAwayETE: https://drive.google.com/open?id=1XqYch8lnhYnudzWsjiLfUYDGmW8x7L5q
The language of our CCAR-P study materials is simple. The learners may come from many social positions and their abilities to master our CCAR-P study materials are varied. Based on this consideration we apply the most simple and easy-to-be-understood language to help the learners no matter he or she is the students or the in-service staff, the novice or the experienced employee which have worked for many years. CCAR-P Study Material use the simple language to explain the answers and detailed knowledge points and the concise words to show the complicated information about the CCAR-P study material.
| Section | Objectives |
|---|---|
| Enterprise Integration and Production | - Enterprise integration architecture and production readiness - Cost, latency, reliability, and operational design |
| Solution Design | - Model, architecture, context, and deployment strategy selection - Claude platform and solution architecture |
| Governance, Safety, and Risk | - Safety controls and fail-closed system design - Security, compliance, risk management, and governance |
| Evaluation and Optimization | - Model and architecture optimization - Evaluation design and acceptance criteria |
| Stakeholder Engagement and Solution Lifecycle | - Solution lifecycle, handoff, adoption, and operational enablement - Stakeholder discovery and architectural trade-off communication |
>> New Anthropic CCAR-P Exam Camp <<
All praise and high values lead us to higher standard of CCAR-P practice engine. So our work ethic is strongly emphasized on your interests which profess high regard for interests of CCAR-P exam candidates. Our CCAR-P practice materials capture the essence of professional knowledge and lead you to desirable results effortlessly. Our CCAR-P Practice Engine has bountiful content that can fulfill your aims and our CCAR-P learning materials give you higher chance to pass your exam as the pass rate is as high as 99% to 100%.
NEW QUESTION # 91
You are identifying signals that a deployment should re-enter design rather than continue iterating in place.
Which signal most directly indicates the need for a new design cycle?
Answer: B
Explanation:
A new design cycle is warranted when the required change crosses an architectural boundary. Option D explicitly states that the existing architecture cannot satisfy the new requirements without redistributing component responsibilities or altering core contracts. Such changes may affect service ownership, orchestration, data flows, integration interfaces, security boundaries, failure handling, evaluation strategy, and operational accountability. They therefore require renewed discovery, impact analysis, design review, stakeholder approval, and regression planning.
Options A, B, and C are localized maintenance activities. Clarifying a runbook improves operational documentation but does not change the deployed system's structure. Adjusting an alert threshold is a controlled operational tuning activity, provided the change remains within established monitoring policy.
Editing customer-facing copy is similarly confined to the presentation or content layer. None of these changes inherently invalidates component contracts or architectural assumptions.
An architect should distinguish between iteration within an approved design and evidence that the design itself no longer supports the required outcome. Re-entering design for every minor adjustment creates unnecessary governance overhead; continuing local iteration after architectural assumptions have failed creates unmanaged technical and operational risk. Option D is the only signal that establishes a structural incompatibility.
Study Guide references/topics: Lifecycle feedback loops; design re-entry criteria; architectural significance; component responsibilities; interface contracts; controlled operational iteration.
NEW QUESTION # 92
You are reviewing a customer-support agent's configuration. Each candidate tool falls into one of four categories: (1) required to complete defined tasks, (2) frequently used and reduces hand-offs, (3) occasionally useful for unrelated work, (4) speculative future utility.
Which categories should typically remain in the agent configuration?
Answer: A
Explanation:
Category 1 tools are necessary for the agent to complete its approved responsibilities and must remain.
Category 2 tools are also justified when they are regularly used and eliminate predictable hand-offs without expanding the agent beyond its defined operating role.
Categories 3 and 4 create capability bloat. A tool that is occasionally useful only for unrelated work does not belong to this agent's responsibility boundary. A speculative tool has no validated requirement and adds attack surface, context consumption, authorization complexity, evaluation burden, and operational dependencies without demonstrated value.
Tool inclusion should be based on task traceability: every configured capability should map to a documented user journey, responsibility, permission scope, and evaluation case. Anthropic recommends least privilege so that a successful injection or model error can cause minimal damage. Mitigate Jailbreaks and Prompt Injections The architect should periodically review tool-call telemetry and remove unused capabilities. New tools can be added when a validated workflow requires them, after security review and evaluation. The objective is not the smallest possible catalog regardless of usefulness; it is the smallest catalog that reliably completes the agent's approved tasks.
Study Guide references/topics: Capability-bloat analysis; tool necessity; hand-off reduction; least privilege; attack-surface management; tool lifecycle review.
NEW QUESTION # 93
You are evaluating an evaluation set used to score a Claude-based hiring-support tool. The set is drawn from one geographic region and one tenure band.
Which response is most appropriate?
Answer: C
Explanation:
An evaluation set must represent the populations, operating conditions, and use cases that the deployed system will encounter. A dataset drawn from only one geographic region and one tenure band cannot reliably demonstrate that the hiring-support tool performs consistently across its intended users. Expanding the evaluation set enables architects to identify regional performance differences, tenure-related errors, unsupported generalizations, and potentially discriminatory outcomes before broader deployment. The system should then be rescored using the expanded dataset, with results examined across relevant population slices rather than relying only on an aggregate score. Options A and B preserve or worsen the representation gap.
Option D is also inappropriate because qualitative feedback can supplement structured evaluation but cannot replace measurable, repeatable testing of accuracy, fairness, and reliability across the intended deployment population.
NEW QUESTION # 94
You are evaluating prompting claims in a peer's design document.
For each claim, select yes if the claim reflects sound practice. Otherwise, select no.
Answer:
Explanation: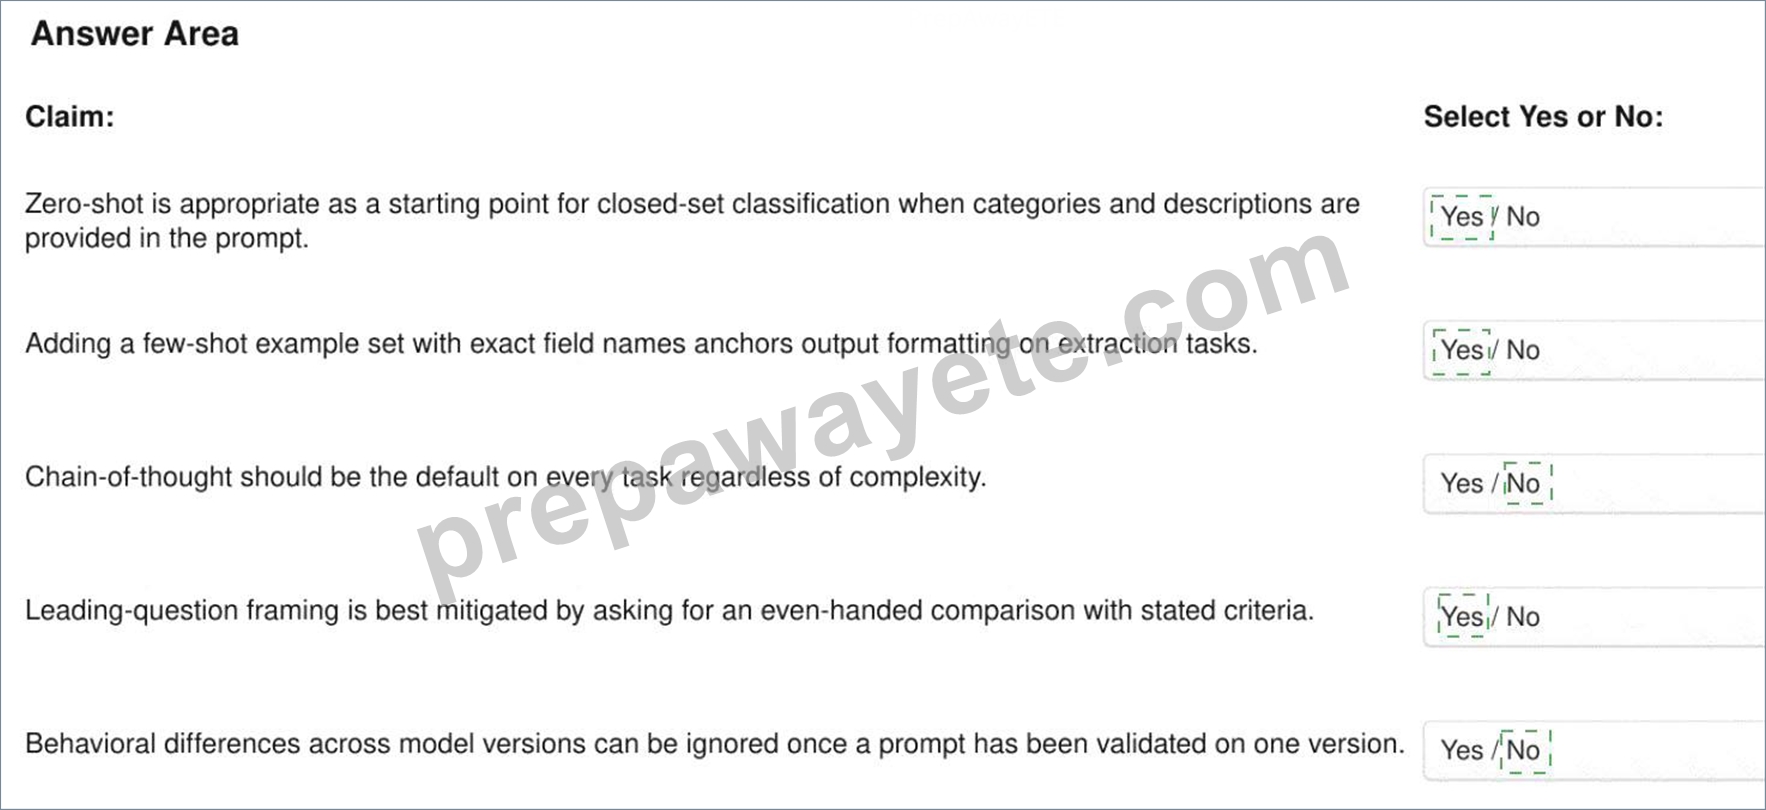
Explanation:
Yes, Yes, No, Yes, No
Zero-shot prompting is a reasonable baseline for a clearly defined closed-set classifier because the model receives both the permissible labels and their meanings. Performance should then be measured against an evaluation set before additional prompt complexity is introduced. Few-shot examples are also sound for extraction because examples containing the exact field names demonstrate the required schema and reduce formatting ambiguity. Anthropic identifies examples as one of the most reliable methods for steering output format, structure, and consistency. Prompting Best Practices Chain-of-thought is not an unconditional default. Additional reasoning is appropriate when the task requires substantive decomposition or complex judgment, but routine classification and extraction may gain little while consuming more tokens and increasing latency. The technique should be selected according to evaluated task requirements.
An even-handed comparison governed by explicit criteria mitigates leading-question bias by requiring symmetrical treatment of alternatives rather than presupposing a preferred conclusion. Finally, prompt validation is model-specific. New model versions may follow instructions differently, change formatting behavior, alter tool selection, or produce different latency and cost characteristics. Anthropic's migration guidance consequently recommends reevaluating prompts and workloads against the new baseline. Model Migration Guide Study Guide references/topics: Zero-shot prompting; few-shot examples; reasoning techniques; neutral framing; model migration and regression evaluation.
NEW QUESTION # 95
You are reviewing a peer's end-to-end design for a Claude-based platform expected to scale to thousands of concurrent users.
For each statement, indicate Yes if it reflects sound architectural practice. Otherwise, select No.
Answer:
Explanation: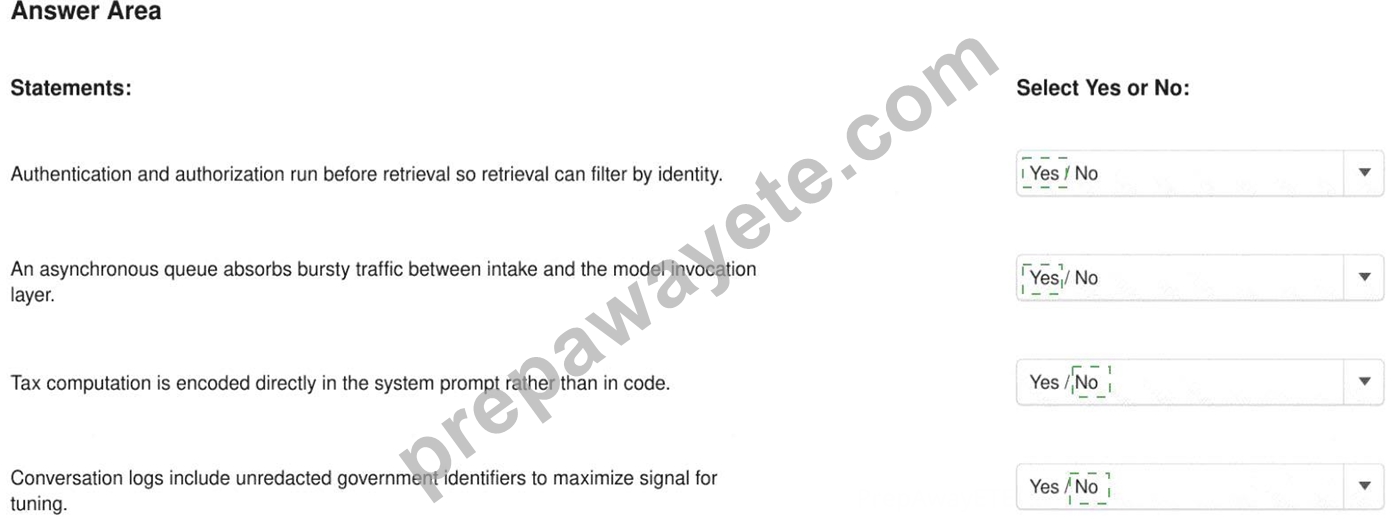
Explanation:
* Authentication and authorization run before retrieval so retrieval can filter by identity - Yes
* An asynchronous queue absorbs bursty traffic between intake and the model-invocation layer - Yes
* Tax computation is encoded directly in the system prompt rather than in code - No
* Conversation logs include unredacted government identifiers to maximize tuning signal - No Authentication and authorization must precede retrieval so unauthorized information never enters model context. An asynchronous queue is appropriate for burst absorption, backpressure, controlled concurrency, and retry management at scale. Deterministic tax computation should be implemented in validated code or a controlled calculation tool, not delegated to probabilistic prompt interpretation. Including unredacted government identifiers in conversation logs violates data-minimization principles and creates unnecessary privacy, security, and regulatory exposure. Sensitive fields should be removed, tokenized, or redacted before logging or model use unless specifically required and authorized. The resulting design separates deterministic computation, access control, scalable orchestration, and language reasoning into appropriate architectural layers.
NEW QUESTION # 96
......
If you want to finish it with minimum efforts, PrepAwayETE Anthropic CCAR-P test questions and answers is your best choice. PrepAwayETE Anthropic CCAR-P test contains high quality exam dumps. Like the actual test, PrepAwayETE test questions and test answers is of the same standard. Now, the best choice is to choose PrepAwayETE Anthropic CCAR-P Certification Training for exam preparation. You must pass at 100%. If you fail, FULL REFUND is allowed.
CCAR-P New Dumps Files: https://www.prepawayete.com/Anthropic/CCAR-P-practice-exam-dumps.html
BTW, DOWNLOAD part of PrepAwayETE CCAR-P dumps from Cloud Storage: https://drive.google.com/open?id=1XqYch8lnhYnudzWsjiLfUYDGmW8x7L5q