さらに、ShikenPASS DP-100ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1MVm1Xddqcb5nattD-dkv-0Ljgwhm4nxV
利用可能な時間、現在の知識レベルなどの状況に基づいて、DP-100学習教材は適切な計画と学習教材を作成します。利用可能な場合はDP-100テストの質問を使用して、各使用の効率を確認することができます。これは非常に良い効果があります。あなた自身や他の何かについて心配する必要はありません。 DP-100学習教材を使用すると、いつでも学習できます。また、DP-100ラーニングガイドを使用すると、最小限の時間と労力でDP-100試験に合格できます。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
Microsoft DP-100試験は、Microsoft Azureを使用してデータソリューションを設計および実装するデータプロフェッショナルがスキルを開発するための必須認定資格です。この認定資格は、データ探索、データ準備、データモデリング、機械学習、およびデータ可視化を含むデータサイエンスのさまざまな側面に関する候補者の知識を検証します。DP-100の認定資格は、グローバルに認められており、候補者がより良い就職機会とキャリア成長を実現するのに役立ちます。
Microsoft DP-100: Azure上でのデータサイエンスソリューションの設計と実装は、データプロフェッショナルがAzure上でデータサイエンスソリューションの設計と実装のスキルを証明するための認定試験です。これは、データエンジニア、データサイエンティスト、および組織内の他のステークホルダーと協力して、エンドツーエンドのデータサイエンスソリューションを作成し、展開する個人を対象としています。
Microsoft DP-100資格認定はIT技術領域に従事する人に必要があります。我々社のMicrosoft DP-100試験練習問題はあなたに試験うま合格できるのを支援します。あなたの取得したMicrosoft DP-100資格認定は、仕事中に核心技術知識を同僚に認可されるし、あなたの技術信頼度を増強できます。
質問 # 171
You manage an Azure Machine Learning workspace named workspace1.
You must register an Azure Blob storage datastore in workspace1 by using an access key. You develop Python SDK v2 code to import all modules required to register the datastore.
You need to complete the Python SDK v2 code to define the datastore.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.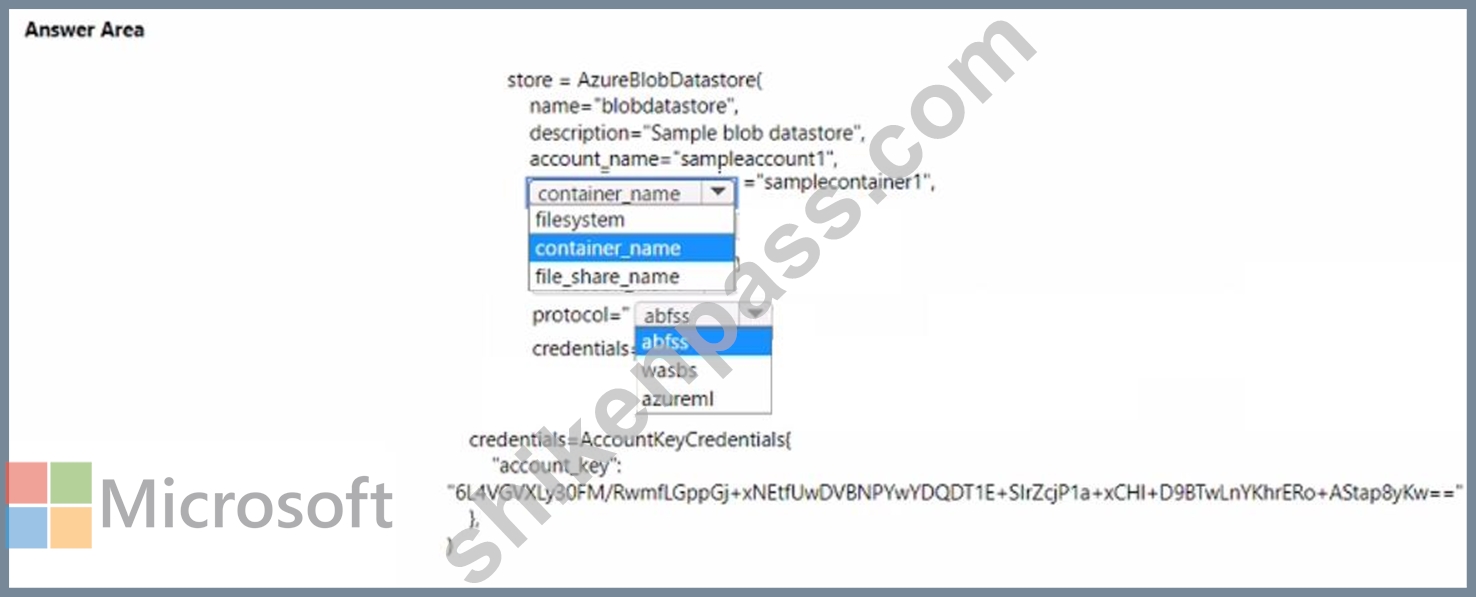
正解:
解説: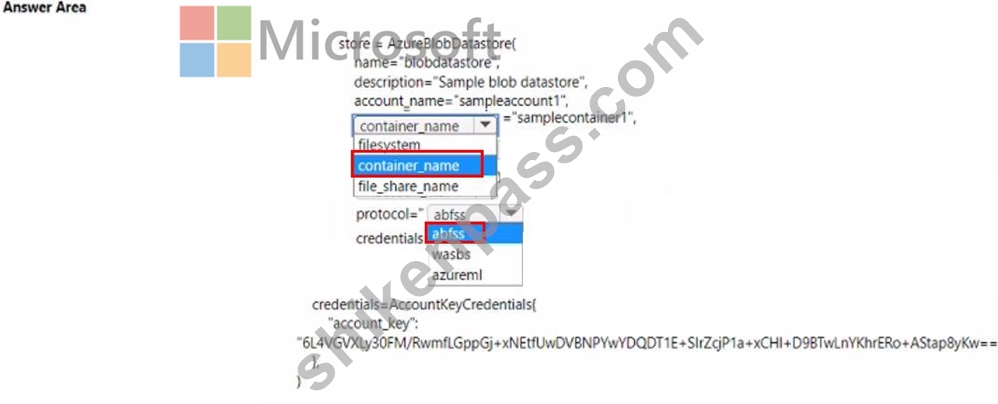
質問 # 172 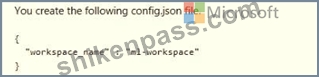
You must use the Azure Machine Learning SDK to interact with data and experiments in the workspace.
You need to configure the config.json file to connect to the workspace from the Python environment.
Which two additional parameters must you add to the config.json file in order to connect to the workspace?
Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
正解:C、E
解説:
To use the same workspace in multiple environments, create a JSON configuration file. The configuration file saves your subscription (subscription_id), resource (resource_group), and workspace name so that it can be easily loaded.
The following sample shows how to create a workspace.
from azureml.core import Workspace
ws = Workspace.create(name= ' myworkspace ' ,
subscription_id= ' < azure-subscription-id > ' ,
resource_group= ' myresourcegroup ' ,
create_resource_group=True,
location= ' eastus2 '
)
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-core/azureml.core.workspace.workspace
質問 # 173
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You create a model to forecast weather conditions based on historical data.
You need to create a pipeline that runs a processing script to load data from a datastore and pass the processed data to a machine learning model training script.
Solution: Run the following code: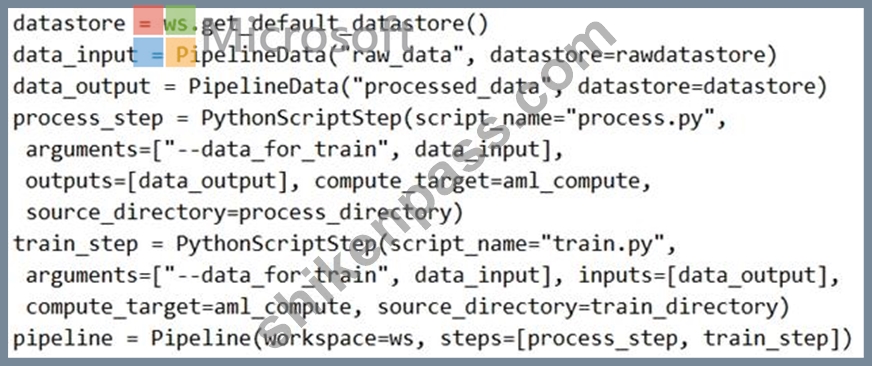
Does the solution meet the goal?
正解:B
解説:
Note: Data used in pipeline can be produced by one step and consumed in another step by providing a PipelineData object as an output of one step and an input of one or more subsequent steps.
Compare with this example, the pipeline train step depends on the process_step_output output of the pipeline process step:
from azureml.pipeline.core import Pipeline, PipelineData
from azureml.pipeline.steps import PythonScriptStep
datastore = ws.get_default_datastore()
process_step_output = PipelineData("processed_data", datastore=datastore) process_step = PythonScriptStep(script_name="process.py", arguments=["--data_for_train", process_step_output], outputs=[process_step_output], compute_target=aml_compute, source_directory=process_directory) train_step = PythonScriptStep(script_name="train.py", arguments=["--data_for_train", process_step_output], inputs=[process_step_output], compute_target=aml_compute, source_directory=train_directory) pipeline = Pipeline(workspace=ws, steps=[process_step, train_step]) Reference:
https://docs.microsoft.com/en-us/python/api/azureml-pipeline-core/azureml.pipeline.core.pipelinedata?view=azu
質問 # 174
You create a script for training a machine learning model in Azure Machine Learning service.
You create an estimator by running the following code: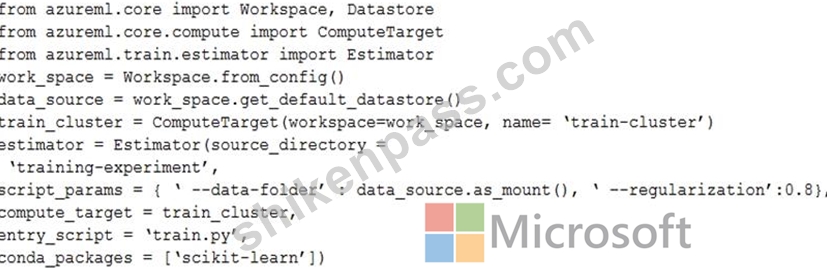
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.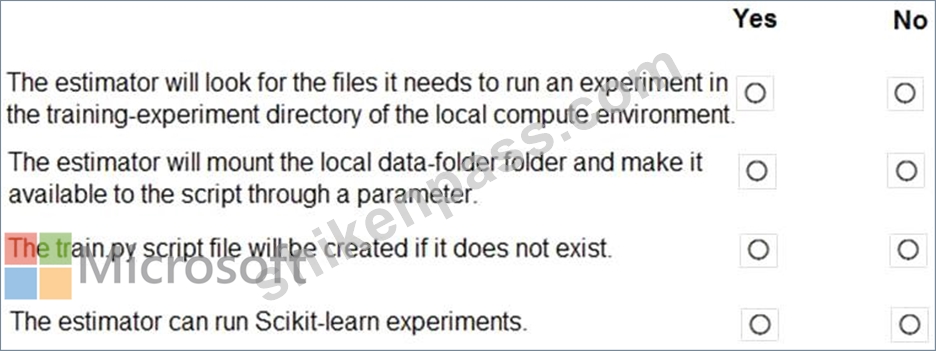
正解:
解説: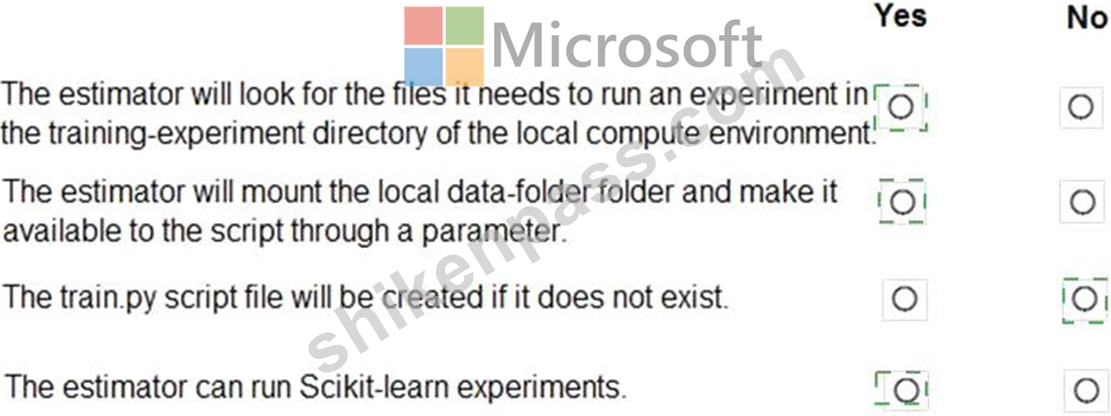
Explanation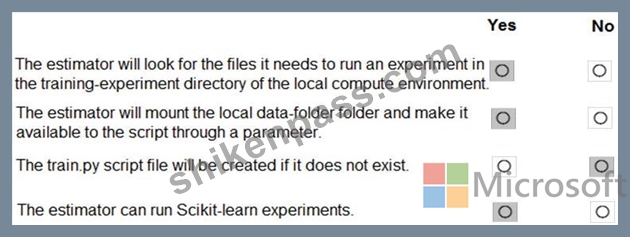
Box 1: Yes
Parameter source_directory is a local directory containing experiment configuration and code files needed for a training job.
Box 2: Yes
script_params is a dictionary of command-line arguments to pass to the training script specified in entry_script.
Box 3: No
Box 4: Yes
The conda_packages parameter is a list of strings representing conda packages to be added to the Python environment for the experiment.
質問 # 175
You deploy a model in Azure Container Instance.
You must use the Azure Machine Learning SDK to call the model API.
You need to invoke the deployed model using native SDK classes and methods.
How should you complete the command? To answer, select the appropriate options in the answer areas.
NOTE: Each correct selection is worth one point.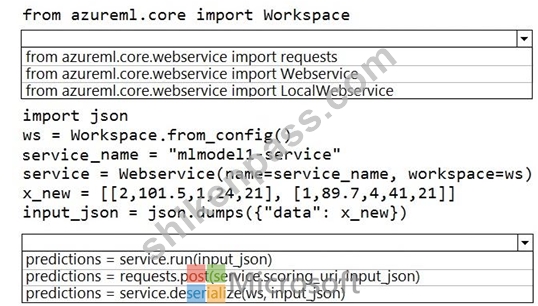
正解:
解説: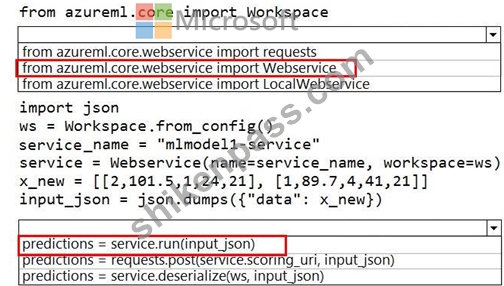
Reference:
https://docs.microsoft.com/bs-latn-ba/azure/machine-learning/how-to-deploy-azure-container-instance
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-troubleshoot-deployment
質問 # 176
......
DP-100試験に実際に参加して資料を選択する前に、このような証明書を保持することの重要性を思い出してください。このようなDP-100証明書を取得することで、昇給、昇進の機会、上司や同僚からの信頼など、将来の多くの同意結果を習得できます。これらすべての快い結果は、もはやあなたにとって夢ではありません。そして、DP-100試験準備により、成績を改善し、生活の状態を変え、キャリアの驚くべき変化を得ることができ、すべてが可能になります。それはすべて、DP-100学習の質問から始まります。
DP-100専門知識訓練: https://www.shikenpass.com/DP-100-shiken.html
P.S.ShikenPASSがGoogle Driveで共有している無料の2026 Microsoft DP-100ダンプ:https://drive.google.com/open?id=1MVm1Xddqcb5nattD-dkv-0Ljgwhm4nxV