Free PDF Databricks - Databricks-Certified-Data-Engineer-Professional Pass-Sure Useful Dumps
You must have felt the changes in the labor market. Today's businesses require us to have more skills and require us to do more in the shortest possible time. We are really burdened with too much pressure. Databricks-Certified-Data-Engineer-Professional simulating exam may give us some help. With our Databricks-Certified-Data-Engineer-Professional Study Materials, we can get the Databricks-Certified-Data-Engineer-Professional certificate in the shortest possible time. And our pass rate is high as 98% to 100% which is unbeatable in the market.
| Section | Weight | Objectives |
|---|
| Databricks Lakehouse Platform | 24% | - Lakehouse Architecture
- Delta Lake
- Unity Catalog
- Data Management
|
| Monitoring and Troubleshooting | 16% | - Performance Optimization
- Troubleshooting
- Monitoring
|
| Data Processing | 28% | - Structured Streaming
- Data Transformation
- Spark SQL
- ETL Pipelines
|
| Data Modeling and Storage | 20% | - Storage Optimization
- Data Modeling
- File Formats
|
| Data Quality and Governance | 12% | - Data Lineage
- Governance
- Data Quality
|
>> Useful Databricks-Certified-Data-Engineer-Professional Dumps <<
Databricks-Certified-Data-Engineer-Professional Exam Simulator Online & Exam Databricks-Certified-Data-Engineer-Professional Objectives
Studying from an updated practice material is necessary to get success in the Databricks Databricks-Certified-Data-Engineer-Professional certification test on the first try. If you don't adopt this strategy, you will not be able to clear the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) examination. Failure in the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) test will lead to loss of confidence, time, and money.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q69-Q74):
NEW QUESTION # 69
A data engineer is building a Lakeflow Declarative Pipelines pipeline to process healthcare claims data. A metadata JSON file defines data quality rules for multiple tables, including:
{
"claims": [
{"name": "valid_patient_id", "constraint": "patient_id IS NOT NULL"},
{"name": "non_negative_amount", "constraint": "claim_amount >= 0"}
]
}
The pipeline must dynamically apply these rules to the claims table without hardcoding the rules.
How should the data engineer achieve this?
- A. Invoke an external API to validate records against the metadata rules.
- B. Reference each expectation with @dlt.expect decorators in the table declaration.
- C. Load the JSON metadata, loop through its entries, and apply expectations using dlt.expect_all.
- D. Use a SQL CONSTRAINT block referencing the JSON file path.
Answer: C
Explanation:
Lakeflow Declarative Pipelines provide the expect_all method for programmatically applying multiple data quality expectations at once. The documentation explains that @dlt.expect_all accepts a dictionary of expectation names mapped to SQL constraints, allowing rules to be dynamically loaded from metadata such as JSON files. This ensures that pipelines remain maintainable and scalable without needing to hardcode individual @dlt.expect decorators. The event logs will track each expectation's pass and fail counts individually, making it auditable.
NEW QUESTION # 70
The data governance team is reviewing user for deleting records for compliance with GDPR. The following logic has been implemented to propagate deleted requests from the user_lookup table to the user aggregate table.
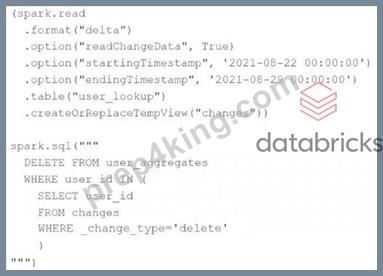
Assuming that user_id is a unique identifying key and that all users have requested deletion have been removed from the user_lookup table, which statement describes whether successfully executing the above logic guarantees that the records to be deleted from the user_aggregates table are no longer accessible and why?
- A. No; the Delta Lake DELETE command only provides ACID guarantees when combined with the MERGE INTO command
- B. Yes; the change data feed uses foreign keys to ensure delete consistency throughout the Lakehouse.
- C. Yes; Delta Lake ACID guarantees provide assurance that the DELETE command successed fully and permanently purged these records.
- D. No; files containing deleted records may still be accessible with time travel until a BACUM command is used to remove invalidated data files.
- E. No; the change data feed only tracks inserts and updates not deleted records.
Answer: D
Explanation:
The DELETE operation in Delta Lake is ACID compliant, which means that once the operation is successful, the records are logically removed from the table. However, the underlying files that contained these records may still exist and be accessible via time travel to older versions of the table. To ensure that these records are physically removed and compliance with GDPR is maintained, a VACUUM command should be used to clean up these data files after a certain retention period. The VACUUM command will remove the files from the storage layer, and after this, the records will no longer be accessible.
NEW QUESTION # 71
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream to power several production monitoring dashboards and a production model. At present, 45 of the 100 fields are being used in at least one of these applications.
The data engineer is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields.
Which of the following accurately presents information about Delta Lake and Databricks that may impact their decision-making process?
- A. Because Delta Lake uses Parquet for data storage, data types can be easily evolved by just modifying file footer information in place.
- B. Schema inference and evolution on .Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
- C. Human labor in writing code is the largest cost associated with data engineering workloads; as such, automating table declaration logic should be a priority in all migration workloads.
- D. The Tungsten encoding used by Databricks is optimized for storing string data; newly-added native support for querying JSON strings means that string types are always most efficient.
- E. Because Databricks will infer schema using types that allow all observed data to be processed, setting types manually provides greater assurance of data quality enforcement.
Answer: E
Explanation:
This is the correct answer because it accurately presents information about Delta Lake and Databricks that may impact the decision-making process of a junior data engineer who is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields. Delta Lake and Databricks support schema inference and evolution, which means that they can automatically infer the schema of a table from the source data and allow adding new columns or changing column types without affecting existing queries or pipelines. However, schema inference and evolution may not always be desirable or reliable, especially when dealing with complex or nested data structures or when enforcing data quality and consistency across different systems. Therefore, setting types manually can provide greater assurance of data quality enforcement and avoid potential errors or conflicts due to incompatible or unexpected data types.
NEW QUESTION # 72
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed:

Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system.
If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
- A. Duplicate records arriving more than 2 hours apart will be dropped, but duplicates that arrive in the same batch may both be written to the orders table.
- B. All records will be held in the state store for 2 hours before being deduplicated and committed to the orders table.
- C. The orders table will contain only the most recent 2 hours of records and no duplicates will be present.
- D. Duplicate records enqueued more than 2 hours apart may be retained and the orders table may contain duplicate records with the same customer_id and order_id.
- E. The orders table will not contain duplicates, but records arriving more than 2 hours late will be ignored and missing from the table.
Answer: D
NEW QUESTION # 73
What statement is true regarding the retention of job run history?
- A. It is retained for 90 days or until the run-id is re-used through custom run configuration
- B. It is retained for 30 days, during which time you can deliver job run logs to DBFS or S3
- C. t is retained for 60 days, during which you can export notebook run results to HTML
- D. It is retained until you export or delete job run logs
- E. It is retained for 60 days, after which logs are archived
Answer: C
Explanation:
https://docs.databricks.com/en/workflows/jobs/monitor-job-runs.html
NEW QUESTION # 74
......
The PDF version of our Databricks-Certified-Data-Engineer-Professional study tool is very practical, which is mainly reflected on the special function. As I mentioned above, our company are willing to provide all people with the demo for free. You must want to know how to get the trial demo of our Databricks-Certified-Data-Engineer-Professional question torrent; the answer is the PDF version. You can download the free demo form the PDF version of our Databricks-Certified-Data-Engineer-Professional Exam Torrent. If you download our study materials successfully, you can print our study materials on pages by the PDF version of our Databricks-Certified-Data-Engineer-Professional exam torrent.
Databricks-Certified-Data-Engineer-Professional Exam Simulator Online: https://www.prep4king.com/Databricks-Certified-Data-Engineer-Professional-exam-prep-material.html
- Reliable Databricks-Certified-Data-Engineer-Professional Test Syllabus 😳 Real Databricks-Certified-Data-Engineer-Professional Exams 📄 Databricks-Certified-Data-Engineer-Professional Practice Questions 🐊 Search on ➤ www.dumpsquestion.com ⮘ for [ Databricks-Certified-Data-Engineer-Professional ] to obtain exam materials for free download ⏫Databricks-Certified-Data-Engineer-Professional Reliable Test Test
- 100% Pass 2026 Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Fantastic Useful Dumps 🧡 Go to website ▷ www.pdfvce.com ◁ open and search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ to download for free 💏Latest Databricks-Certified-Data-Engineer-Professional Questions
- Exam Databricks-Certified-Data-Engineer-Professional Dumps 🔚 New Databricks-Certified-Data-Engineer-Professional Test Simulator 👵 Databricks-Certified-Data-Engineer-Professional Reliable Test Test 🍈 Search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ and download it for free on { www.prepawaypdf.com } website 🐄Real Databricks-Certified-Data-Engineer-Professional Exams
- Useful Databricks-Certified-Data-Engineer-Professional Dumps - Databricks Databricks-Certified-Data-Engineer-Professional Exam Simulator Online: Databricks Certified Data Engineer Professional Exam Pass Success 🤟 Immediately open { www.pdfvce.com } and search for 「 Databricks-Certified-Data-Engineer-Professional 」 to obtain a free download 👉Exam Databricks-Certified-Data-Engineer-Professional Quick Prep
- Useful Databricks-Certified-Data-Engineer-Professional Dumps - Updated Databricks-Certified-Data-Engineer-Professional Exam Simulator Online Supply you the Best Materials for Databricks Certified Data Engineer Professional Exam 🐼 Copy URL ( www.testkingpass.com ) open and search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ to download for free 📐Test Databricks-Certified-Data-Engineer-Professional King
- Real Databricks-Certified-Data-Engineer-Professional Exams 🏌 Databricks-Certified-Data-Engineer-Professional Valid Exam Preparation 🌕 Databricks-Certified-Data-Engineer-Professional Guide 👪 Immediately open ➠ www.pdfvce.com 🠰 and search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ to obtain a free download 👷Databricks-Certified-Data-Engineer-Professional Latest Test Braindumps
- Exam Databricks-Certified-Data-Engineer-Professional Overviews 😺 Actual Databricks-Certified-Data-Engineer-Professional Test 🕎 Exam Databricks-Certified-Data-Engineer-Professional Quick Prep 🔘 Search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ and easily obtain a free download on ( www.examcollectionpass.com ) ⚾Test Databricks-Certified-Data-Engineer-Professional King
- Databricks - Updated Useful Databricks-Certified-Data-Engineer-Professional Dumps 🙁 Search for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ on ➠ www.pdfvce.com 🠰 immediately to obtain a free download 🕦Test Databricks-Certified-Data-Engineer-Professional King
- 100% Pass 2026 Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Fantastic Useful Dumps ⏏ Search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ and obtain a free download on ▶ www.examdiscuss.com ◀ 🦄Actual Databricks-Certified-Data-Engineer-Professional Test
- Databricks Useful Databricks-Certified-Data-Engineer-Professional Dumps: Databricks Certified Data Engineer Professional Exam - Pdfvce Ensures you a Easy Studying Experience 🥦 Open ➡ www.pdfvce.com ️⬅️ enter ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ and obtain a free download 🙌Reliable Databricks-Certified-Data-Engineer-Professional Test Syllabus
- 100% Pass 2026 Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Fantastic Useful Dumps 🏎 Search for 【 Databricks-Certified-Data-Engineer-Professional 】 and download it for free immediately on ➥ www.easy4engine.com 🡄 ⏬Exam Databricks-Certified-Data-Engineer-Professional Quick Prep
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes