Exams4Collection provides a clear and superior solutions for each Microsoft AI-200 Exam candidates. We provide you with the Microsoft AI-200 exam questions and answers. Our team of IT experts is the most experienced and qualified. Our test questions and the answer is almost like the real exam. This is really amazing. More importantly, the examination pass rate of Exams4Collection is highest in the worldwide.
| Section | Objectives |
|---|---|
| Connect to and consume Azure services | - Integrate Azure services
|
| Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Develop containerized solutions on Azure | - Implement containerized applications
|
| Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
>> Reliable AI-200 Exam Guide <<
Exams4Collection are supposed to help you pass the exam smoothly. Don't worry about channels to the best AI-200 study materials because we are the exactly best vendor in this field for more than ten years. And so many exam candidates admire our generosity of the AI-200 Practice Questions offering help for them. Up to now, no one has ever challenged our leading position of this area. With our AI-200 training guide, you will be doomed to pass the exam successfully.
NEW QUESTION # 50
You need to deploy a batch embedding workload according to the planned application architecture.
What should you use?
Answer: D
Explanation:
The batch embedding workload is planned to run in Azure Kubernetes Service (AKS) , and Kubernetes workloads should be defined declaratively by using YAML manifest files . Microsoft states that a Kubernetes manifest defines the desired state of cluster resources, including Deployments, Jobs, Services, ConfigMaps, and other Kubernetes objects. These manifests can then be deployed by using kubectl apply -f < manifest > .
yaml.
For this case, YAML is particularly appropriate because the technical requirements emphasize repeatable, version-controlled, automated deployments . A batch vector embedding regeneration process would typically be represented as a Kubernetes workload such as a Job or another batch-oriented resource, with its configuration committed to Git alongside the rest of the deployment definitions.
kubectl run and kubectl create are imperative commands and are less appropriate for a controlled Git-based deployment model because they do not inherently preserve the complete desired-state definition as source- controlled configuration. XML is not the standard Kubernetes manifest format. az aks commands are primarily used to provision and manage the AKS cluster itself rather than declaratively define application workloads running inside the cluster.
Therefore, the correct choice is YAML-formatted Kubernetes manifest files .
Study Guide references: Azure Kubernetes Service # Kubernetes manifests; declarative deployments; kubectl apply; Git-based workload configuration.
NEW QUESTION # 51
You have an Event Grid subscription that triggers an Azure Function.
You need to prevent loss of events in case the endpoint returns an HTTP 400 response.
Which action should you perform?
Answer: A
Explanation:
Configuring a dead-letter destination is exactly the right step to take.
By default, when an endpoint returns an HTTP 400 (Bad Request) or HTTP 413 (Payload Too Large) response, Azure Event Grid immediately stops delivery attempts and drops the message.
It treats these specific errors as non-transient, client-side issues, meaning it skips its standard 24- hour retry policy.
Configuring a dead-letter destination ensures that these dropped events are safely preserved for future troubleshooting and reprocessing.
Reference:
https://turbo360.com/blog/azure-event-grid-dead-letter-monitoring
NEW QUESTION # 52
You have two Azure Container Registry (ACR) instances: ACR01 and ACR02.
You plan to implement a containerized application named APP1 that will use a base image named BASE1.
The image for APP1 will be stored in ACR01. The image BASE1 will be stored in ACR02.
You need to automate the planned implementation by using a sequence of five Azure command-line interface (Azure CLI) commands. Your solution must ensure that the APP1 image stored in ACR01 will be automatically updated when the BASE1 image is updated.
In which order should you arrange the commands to develop the solution? To answer, move all commands from the list of commands to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.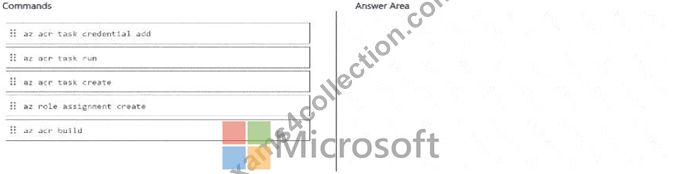
Answer:
Explanation: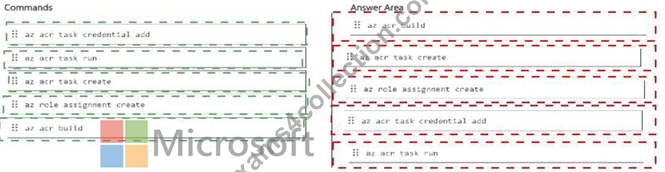
Explanation: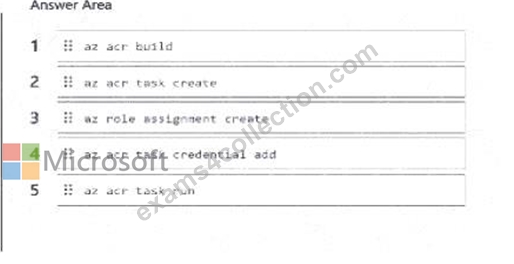
NEW QUESTION # 53
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
Hotspot Question
You need to configure vector embedding updates according to the business and technical requirements.
Which configurations should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.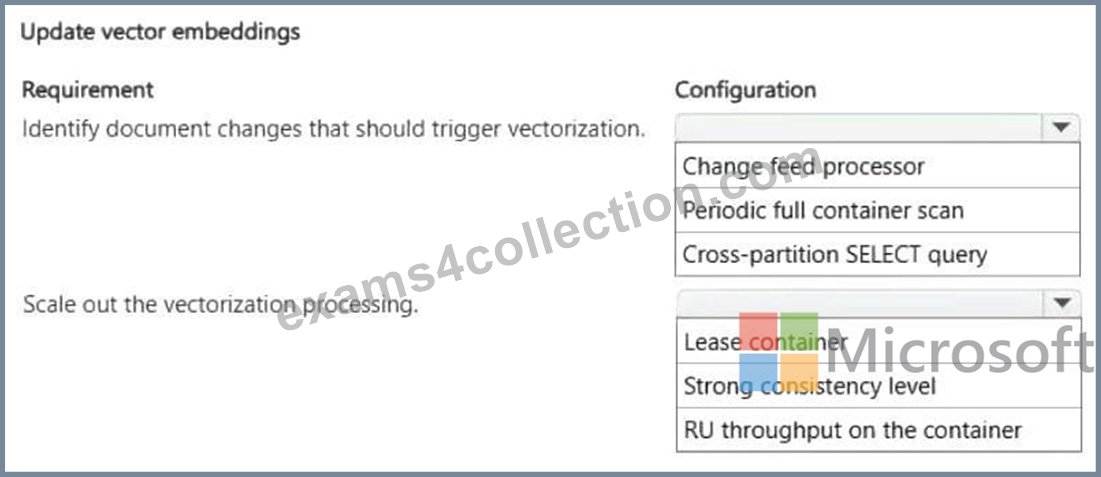
Answer:
Explanation: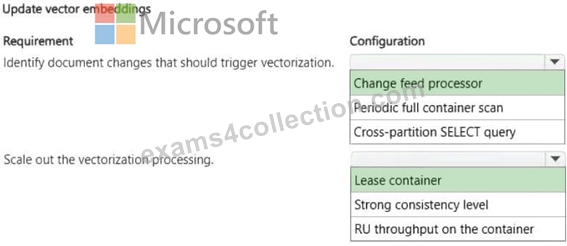
Explanation:
Business Requirements: Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Technical Requirements: Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
Box 1: Change feed processor
The Change feed processor is the correct component to configure for identifying document changes that should trigger vectorization.
This feature in Azure Cosmos DB provides a reliable, distributed, and scalable way to listen to a constant stream of changes (inserts and updates) within a container. It allows you to process these modifications in real-time, making it the perfect trigger for automated workflows like sending new text to an embedding model.
Box 2: Lease Container
The lease container is the component you configure to coordinate and horizontally scale out the change feed-driven vectorization processing across multiple workers or compute instances.
The Lease Container acts as state storage, tracks checkpoints, and distributes partition keys across parallel compute workers (such as Azure Functions or custom change feed processors) to scale out throughput processing safely without duplicate work.
Incorrect:
RU Throughput: Dictates the maximum performance limit, but provisioning RUs alone does not orchestrate or scale out multiple processing workers.
Consistency Level: Affects data replication guarantees and read/write ordering, not parallel processing distribution.
Reference:
https://blog.nashtechglobal.com/managing-record-changes-with-change-feed-in-azure-cosmos-db/
NEW QUESTION # 54
Drag and Drop Question
You are developing a serverless Java application on Azure. You create a new Azure Key Vault to work with secrets from a new Azure Functions application.
The application must meet the following requirements:
- Reference the Azure Key Vault without requiring any changes to the
Java code.
- Dynamically add and remove instances of the Azure Functions host
based on the number of incoming application events.
- Ensure that instances are perpetually warm to avoid any cold starts.
- Connect to a VNet.
- Authentication to the Azure Key Vault instance must be removed if the Azure Functions application is deleted.
You need to grant the Azure Functions application access to the Azure Key Vault.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.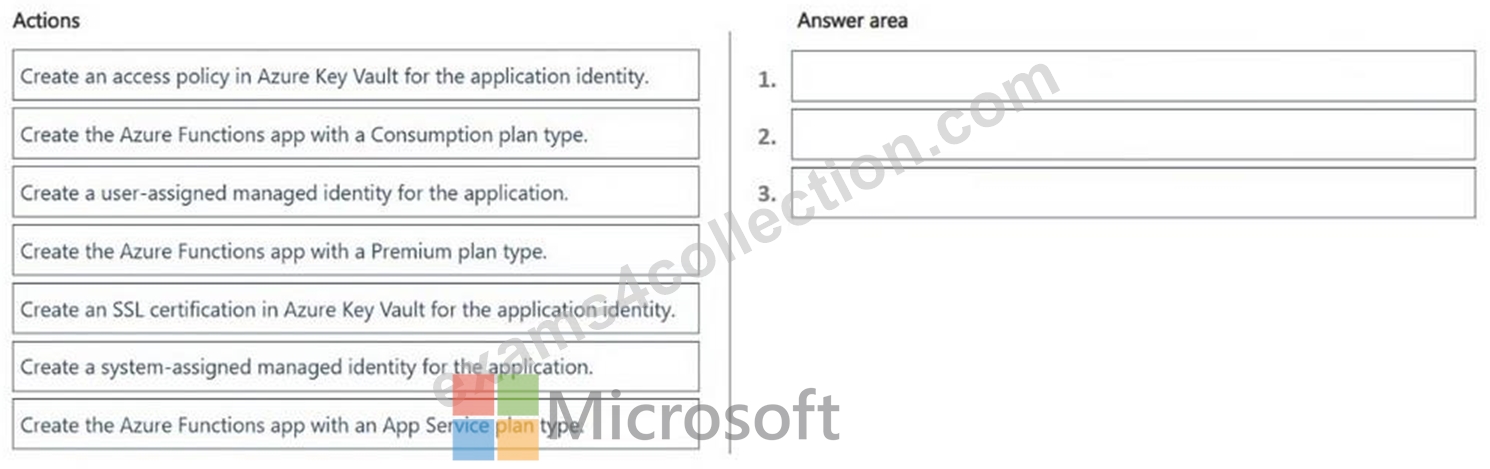
Answer:
Explanation: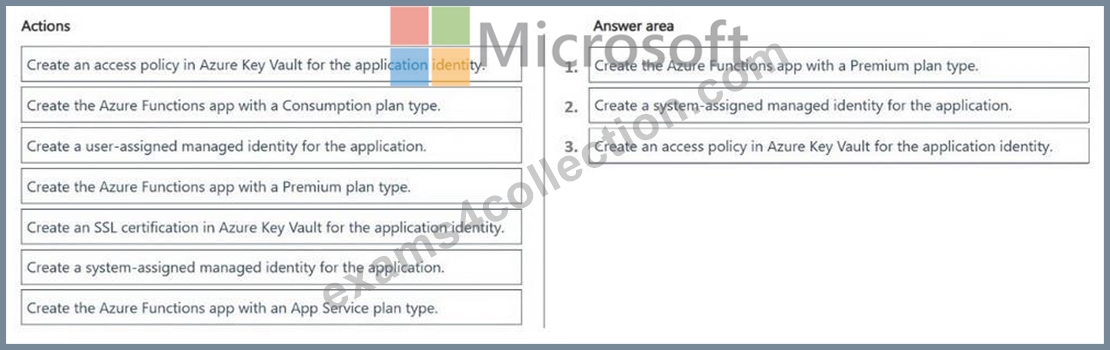
Explanation:
Step 1: Create the Azure Functions app with a Premium plan type
Perpetually Warm & VNet: The Premium plan type is the only serverless-scale hosting option that satisfies requirement 3 (keeping instances warm to eliminate cold starts) and requirement 4 (native regional VNet integration). The Consumption plan type does not keep instances warm and does not support VNet injection.
Event-Driven Scaling: It fulfills requirement 2 by dynamically adding and removing host instances using the event-driven scale controller.
Step 2: Create a system-assigned managed identity for the application
Lifecycle Coupling: It directly satisfies requirement 5. A system-assigned managed identity is tied strictly to the lifecycle of the Azure Functions resource. If the Functions application is deleted, Azure automatically removes the identity and its authentication token, ensuring that access to the Key Vault is immediately revoked. A user-assigned identity exists as an independent resource and would persist after the application's deletion.
Step 3: Create an access policy in Azure Key Vault for the application identity Granting Permissions: This step completes the access requirements. By adding an access policy (or an Azure RBAC role assignment) in Azure Key Vault specifically for the created system- assigned managed identity, you grant the runtime environment the necessary permissions to retrieve secrets.
No Code Changes: Combining the managed identity with an App Setting configured as an Azure Key Vault Reference allows the Functions platform to fetch secrets automatically at runtime, keeping your Java source code unchanged Reference:
https://learn.microsoft.com/en-us/azure/azure-functions/functions-best-practices
NEW QUESTION # 55
......
Certification has become a prerequisite for employment and career growth in the Microsoft industry for reputable companies. To advance comfortably in your career, passing the AI-200 exam is a valuable validation of your expertise. However, many test takers struggle to find updated Developing AI Cloud Solutions on Azure (AI-200) dumps and fail to prepare effectively in a short period, resulting in a loss of time, money, and motivation.
AI-200 Latest Test Testking: https://www.exams4collection.com/AI-200-latest-braindumps.html