Databricks-Certified-Data-Engineer-Professional인기덤프문제 & Databricks-Certified-Data-Engineer-Professional시험대비최신덤프문제

그 외, Fast2test Databricks-Certified-Data-Engineer-Professional 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=19LcXwQ1ok9zApEnxyP1l4AsJ5lPXzY9J
Databricks Databricks-Certified-Data-Engineer-Professional인증시험도 어려울 뿐만 아니라 신청 또한 어렵습니다.Databricks Databricks-Certified-Data-Engineer-Professional시험은 IT업계에서도 권위가 있고 직위가 있으신 분들이 응시할 수 있는 시험이라고 알고 있습니다. 우리 Fast2test에서는Databricks Databricks-Certified-Data-Engineer-Professional관련 학습가이드를 제동합니다. Fast2test 는 우리만의IT전문가들이 만들어낸Databricks Databricks-Certified-Data-Engineer-Professional관련 최신, 최고의 자료와 학습가이드를 준비하고 있습니다. 여러분의 편리하게Databricks Databricks-Certified-Data-Engineer-Professional응시하는데 많은 도움이 될 것입니다.
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Debugging and Deploying | 10% | - Troubleshoot and debug pipelines
- Deploy using Asset Bundles, CLI, and APIs
- Implement CI/CD and DevOps practices
|
| Data Modelling | 6% | - Implement dimensional and relational models
- Optimize table design and partitioning
- Design Medallion Architecture
|
| Data Ingestion & Acquisition | 7% | - Ingest data from diverse sources
- Handle incremental and batch data loads
- Use Auto Loader and structured streaming
|
| Ensuring Data Security and Compliance | 10% | - Ensure data privacy and compliance
- Implement access control and permissions
- Secure data at rest and in transit
|
| Data Transformation, Cleansing, and Quality | 10% | - Enforce data quality standards
- Implement schema evolution and management
- Apply data cleansing and validation rules
|
| Developing Code for Data Processing using Python and SQL | 22% | - Use Databricks-specific libraries and APIs
- Implement complex data processing logic
- Write efficient and maintainable code
|
| Data Governance | 7% | - Manage data assets and metadata
- Enforce data policies and standards
- Use Unity Catalog for governance
|
| Monitoring and Alerting | 10% | - Monitor pipeline performance and health
- Set up alerts and notifications
- Track data lineage and metrics
|
| Cost & Performance Optimisation | 13% | - Apply cost management best practices
- Improve query and pipeline performance
- Optimize compute and storage resources
|
| Data Sharing and Federation | 5% | - Implement Lakehouse Federation
- Use Delta Sharing for secure data sharing
- Manage cross-platform data access
|
>> Databricks-Certified-Data-Engineer-Professional인기덤프문제 <<
Databricks-Certified-Data-Engineer-Professional인기덤프문제 시험대비 덤프공부
Databricks Databricks-Certified-Data-Engineer-Professional인증시험은 전문적인 관련지식을 테스트하는 인증시험입니다. Fast2test는 여러분이Databricks Databricks-Certified-Data-Engineer-Professional인증시험을 통과할 수 잇도록 도와주는 사이트입니다. 여러분은 응시 전 저희의 문제와 답만 잘 장악한다면 빠른 시일 내에 많은 성과 가 있을 것입니다.
최신 Databricks Certification Databricks-Certified-Data-Engineer-Professional 무료샘플문제 (Q88-Q93):
질문 # 88
A data engineer is performing a join operating to combine values from a static userlookup table with a streaming DataFrame streamingDF.
Which code block attempts to perform an invalid stream-static join?
- A. streamingDF.join(userLookup, ["user_id"], how="outer")
- B. streamingDF.join(userLookup, ["userid"], how="inner")
- C. userLookup.join(streamingDF, ["user_id"], how="right")
- D. userLookup.join(streamingDF, ["userid"], how="inner")
- E. streamingDF.join(userLookup, ["user_id"], how="left")
정답:A
설명:
https://spark.apache.org/docs/latest/structured-streaming-programming-guide.html#support- matrix-for-joins-in-streaming-queries
질문 # 89
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
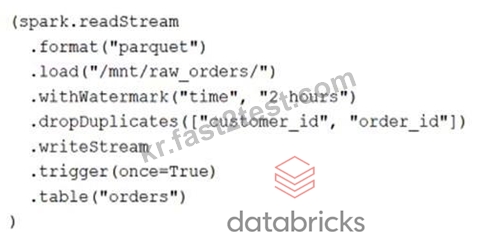
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system.
If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
- A. Duplicate records enqueued more than 2 hours apart may be retained and the orders table may contain duplicate records with the same customer_id and order_id.
- B. The orders table will not contain duplicates, but records arriving more than 2 hours late will be ignored and missing from the table.
- C. Duplicate records arriving more than 2 hours apart will be dropped, but duplicates that arrive in the same batch may both be written to the orders table.
- D. All records will be held in the state store for 2 hours before being deduplicated and committed to the orders table.
- E. The orders table will contain only the most recent 2 hours of records and no duplicates will be present.
정답:A
질문 # 90
Although the Databricks Utilities Secrets module provides tools to store sensitive credentials and avoid accidentally displaying them in plain text users should still be careful with which credentials are stored here and which users have access to using these secrets.
Which statement describes a limitation of Databricks Secrets?
- A. The Databricks REST API can be used to list secrets in plain text if the personal access token has proper credentials.
- B. Iterating through a stored secret and printing each character will display secret contents in plain text.
- C. Secrets are stored in an administrators-only table within the Hive Metastore; database administrators have permission to query this table by default.
- D. Because the SHA256 hash is used to obfuscate stored secrets, reversing this hash will display the value in plain text.
- E. Account administrators can see all secrets in plain text by logging on to the Databricks Accounts console.
정답:A
설명:
This is the correct answer because it describes a limitation of Databricks Secrets. Databricks Secrets is a module that provides tools to store sensitive credentials and avoid accidentally displaying them in plain text. Databricks Secrets allows creating secret scopes, which are collections of secrets that can be accessed by users or groups. Databricks Secrets also allows creating and managing secrets using the Databricks CLI or the Databricks REST API. However, a limitation of Databricks Secrets is that the Databricks REST API can be used to list secrets in plain text if the personal access token has proper credentials. Therefore, users should still be careful with which credentials are stored in Databricks Secrets and which users have access to using these secrets.
질문 # 91
A job runs four independent tasks (X, Y, Z, W) in parallel to process regional sales data. The Data Engineering team recently updated its cluster policy to ban cost-prohibitive instance types. Task Y now fails due to the newly enforced cluster policy restricting the use of a specific instance type.
A data engineer needs to resolve the failure quickly without disrupting the other tasks. How should the data engineer resolve the failure of tasks?
- A. Edit the global cluster policy to allow the restricted instance type, then re-run the entire job.
- B. Manually create a new cluster for Task Y, update the job configuration, and trigger a full re-run.
- C. Use "Repair run", override the cluster configuration for Task Y to use a permitted instance type, and let Databricks re-run only Task Y.
- D. Delete the failed run, disable the cluster policy, and re-execute all tasks.
정답:C
설명:
Repair run allows re-running only the failed task without affecting successfully completed tasks.
Overriding the cluster configuration for the specific task resolves the policy violation quickly while keeping the rest of the job intact and minimizing disruption.
질문 # 92
Which statement describes the correct use of pyspark.sql.functions.broadcast?
- A. It marks a column as small enough to store in memory on all executors, allowing a broadcast join.
- B. It marks a column as having low enough cardinality to properly map distinct values to available partitions, allowing a broadcast join.
- C. It marks a DataFrame as small enough to store in memory on all executors, allowing a broadcast join.
- D. It caches a copy of the indicated table on all nodes in the cluster for use in all future queries during the cluster lifetime.
- E. It caches a copy of the indicated table on attached storage volumes for all active clusters within a Databricks workspace.
정답:C
설명:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
질문 # 93
......
Fast2test는 저희 제품을 구매한 분들이 100%통과율을 보장해드리도록 최선을 다하고 있습니다. Fast2test를 선택한것은 시험패스와 자격증취득을 예약한것과 같습니다. Fast2test의 믿음직한 Databricks인증 Databricks-Certified-Data-Engineer-Professional덤프를 공부해보세요.
Databricks-Certified-Data-Engineer-Professional시험대비 최신 덤프문제: https://kr.fast2test.com/Databricks-Certified-Data-Engineer-Professional-premium-file.html
- Databricks-Certified-Data-Engineer-Professional인기덤프문제 덤프 ----- IT전문가의 노하우로 만들어진 시험자료 🎣 { www.dumptop.com }의 무료 다운로드➥ Databricks-Certified-Data-Engineer-Professional 🡄페이지가 지금 열립니다Databricks-Certified-Data-Engineer-Professional퍼펙트 최신 공부자료
- Databricks-Certified-Data-Engineer-Professional최고품질 인증시험공부자료 🍭 Databricks-Certified-Data-Engineer-Professional시험대비 인증공부자료 ⚫ Databricks-Certified-Data-Engineer-Professional최고품질 인증시험공부자료 🍼 ✔ Databricks-Certified-Data-Engineer-Professional ️✔️를 무료로 다운로드하려면➡ www.itdumpskr.com ️⬅️웹사이트를 입력하세요Databricks-Certified-Data-Engineer-Professional덤프공부문제
- Databricks-Certified-Data-Engineer-Professional최신버전 덤프공부문제 🎓 Databricks-Certified-Data-Engineer-Professional인기자격증 시험대비 덤프문제 👎 Databricks-Certified-Data-Engineer-Professional최신버전 덤프공부문제 💼 오픈 웹 사이트▶ www.dumptop.com ◀검색✔ Databricks-Certified-Data-Engineer-Professional ️✔️무료 다운로드Databricks-Certified-Data-Engineer-Professional시험대비 덤프데모문제
- Databricks-Certified-Data-Engineer-Professional인기덤프문제 100% 합격 보장 가능한 덤프문제 🥗 검색만 하면▶ www.itdumpskr.com ◀에서《 Databricks-Certified-Data-Engineer-Professional 》무료 다운로드Databricks-Certified-Data-Engineer-Professional합격보장 가능 시험대비자료
- Databricks-Certified-Data-Engineer-Professional퍼펙트 최신 공부자료 🙊 Databricks-Certified-Data-Engineer-Professional인기시험자료 🏀 Databricks-Certified-Data-Engineer-Professional높은 통과율 시험공부 🥟 무료 다운로드를 위해{ Databricks-Certified-Data-Engineer-Professional }를 검색하려면{ www.dumptop.com }을(를) 입력하십시오Databricks-Certified-Data-Engineer-Professional시험대비 덤프데모문제
- 시험준비에 가장 좋은 Databricks-Certified-Data-Engineer-Professional인기덤프문제 최신버전 덤프데모문제 다운받기 ⛅ ( www.itdumpskr.com )의 무료 다운로드“ Databricks-Certified-Data-Engineer-Professional ”페이지가 지금 열립니다Databricks-Certified-Data-Engineer-Professional최신 덤프샘플문제 다운
- Databricks-Certified-Data-Engineer-Professional퍼펙트 덤프샘플 다운로드 😦 Databricks-Certified-Data-Engineer-Professional시험 ⬅️ Databricks-Certified-Data-Engineer-Professional시험대비 인증공부자료 🏄 지금「 kr.fast2test.com 」을(를) 열고 무료 다운로드를 위해✔ Databricks-Certified-Data-Engineer-Professional ️✔️를 검색하십시오Databricks-Certified-Data-Engineer-Professional높은 통과율 시험대비 공부문제
- Databricks-Certified-Data-Engineer-Professional인기덤프문제 100% 합격 보장 가능한 덤프문제 🦀 ⮆ www.itdumpskr.com ⮄을(를) 열고✔ Databricks-Certified-Data-Engineer-Professional ️✔️를 검색하여 시험 자료를 무료로 다운로드하십시오Databricks-Certified-Data-Engineer-Professional인기자격증 시험대비 덤프문제
- Databricks-Certified-Data-Engineer-Professional인기덤프문제 100% 합격 보장 가능한 덤프문제 👋 무료 다운로드를 위해 지금【 www.itdumpskr.com 】에서▛ Databricks-Certified-Data-Engineer-Professional ▟검색Databricks-Certified-Data-Engineer-Professional퍼펙트 인증덤프자료
- 시험패스 가능한 Databricks-Certified-Data-Engineer-Professional인기덤프문제 최신버전 덤프데모문제 다운로드 ➖ ➥ www.itdumpskr.com 🡄의 무료 다운로드➥ Databricks-Certified-Data-Engineer-Professional 🡄페이지가 지금 열립니다Databricks-Certified-Data-Engineer-Professional높은 통과율 시험공부
- Databricks-Certified-Data-Engineer-Professional인기시험자료 😸 Databricks-Certified-Data-Engineer-Professional높은 통과율 시험공부 💧 Databricks-Certified-Data-Engineer-Professional인기자격증 시험대비 덤프문제 🛫 ➠ www.exampassdump.com 🠰에서➠ Databricks-Certified-Data-Engineer-Professional 🠰를 검색하고 무료 다운로드 받기Databricks-Certified-Data-Engineer-Professional덤프공부문제
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
참고: Fast2test에서 Google Drive로 공유하는 무료, 최신 Databricks-Certified-Data-Engineer-Professional 시험 문제집이 있습니다: https://drive.google.com/open?id=19LcXwQ1ok9zApEnxyP1l4AsJ5lPXzY9J