If you plan to apply for the Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 (NCP-BC-7.5) certification exam, you need the best NCP-BC-7.5 practice test material that can help you maximize your chances of success. You cannot rely on invalid NCP-BC-7.5 Materials and then expect the results to be great. So, you must prepare from the updated Nutanix NCP-BC-7.5 Exam Dumps to crack the NCP-BC-7.5 exam.
| Section | Objectives |
|---|---|
| Topic 1: Security and Hardening | - Designing secure BCDR environments - Security best practices for replication - RBAC implementation for disaster recovery - Approval policies configuration |
| Topic 2: Replication and Failover Architecture | - Synchronous replication across sites - Failover readiness validation - Recovery site capacity management - Network segmentation for BCDR environments - Asynchronous replication planning |
| Topic 3: BCDR Fundamentals and Requirements Interpretation | - Defining recovery strategies aligned to business requirements and risk tolerance - Availability metrics and SLA definitions - Translating business requirements into resilient recovery architectures - Understanding RTO and RPO concepts and business impact analysis - Selecting appropriate replication types (async, near-sync, synchronous, metro) |
| Topic 4: Monitoring, Testing and Troubleshooting | - Troubleshooting permission issues and misconfigured DR environments - Non-disruptive recovery testing - Setting up alerts for replication lag - Diagnosing network, storage and replication failures - Documenting runbooks for incident response - Resolving third-party backup integration problems |
| Topic 5: Nutanix Disaster Recovery Solutions | - Recovery workflows using Nutanix native tools - Configuring and managing replication policies - Integration with third-party backup solutions - Failover procedures and execution - Metro Availability configuration and management |
| Topic 6: Data Protection and Snapshots | - Snapshot scheduling and management - Snapshot retention policies design - Storage configuration for BCDR - Incremental backup implementation - Data restoration at VM and application level |
>> NCP-BC-7.5 Exam Tutorial <<
For the convenience of the users, the NCP-BC-7.5 test materials will be updated on the homepage and timely update the information related to the qualification examination. Annual qualification examination, although content broadly may be the same, but as the policy of each year, the corresponding examination pattern grading standards and hot spots will be changed, as a result, the NCP-BC-7.5 Test Prep can help users to spend the least time, you can know the test information directly what you care about on the learning platform that provided by us, let users save time and used their time in learning the new hot spot concerning about the knowledge content.
NEW QUESTION # 26
An administrator has been tasked with configuring a Nutanix replication solution that provides an RPO of zero. Which solution should the administrator choose?
Answer: A
Explanation:
The Recovery Point Objective (RPO) is a measure of how much data an organization can afford to lose during an outage. An RPO of zero means that absolutely no data loss is tolerated; every write performed at the primary site must be safely committed to the recovery site before the application receives a confirmation. In the Nutanix portfolio, Synchronous Replication (Option A) is the only technology that guarantees this level of data protection. It mirrors every write in real-time between two clusters, ensuring they are always in perfect synchronization. In contrast, Nearsync Replication (Option B) allows for very low RPOs (as low as 20 seconds to 1 minute), but it is still fundamentally an asynchronous process using lightweight snapshots, meaning some " data-in-flight " could be lost. Async Replication (Option C) typically involves RPOs of one hour or more and is used for less critical workloads. Cloud Connect (Option D) is a legacy feature for off-site backup and does not support zero-RPO requirements. Synchronous Replication is the " gold standard " for Tier-1, mission-critical applications where data integrity and zero loss are the primary business requirements, provided the network latency between sites is 5ms or less.
NEW QUESTION # 27
An administrator is troubleshooting a hung replication. When checking the replication status, the complete percent and bytes completed do not increase. The administrator checks the Stargate logs on the destination cluster and confirms the writes are failing with " nfs status 28 " . Checking the container info on the destination cluster, free space on the container is 0. The administrator confirms that there is sufficient space available in the storage pool. What could be the reason for free space on the container to be 0?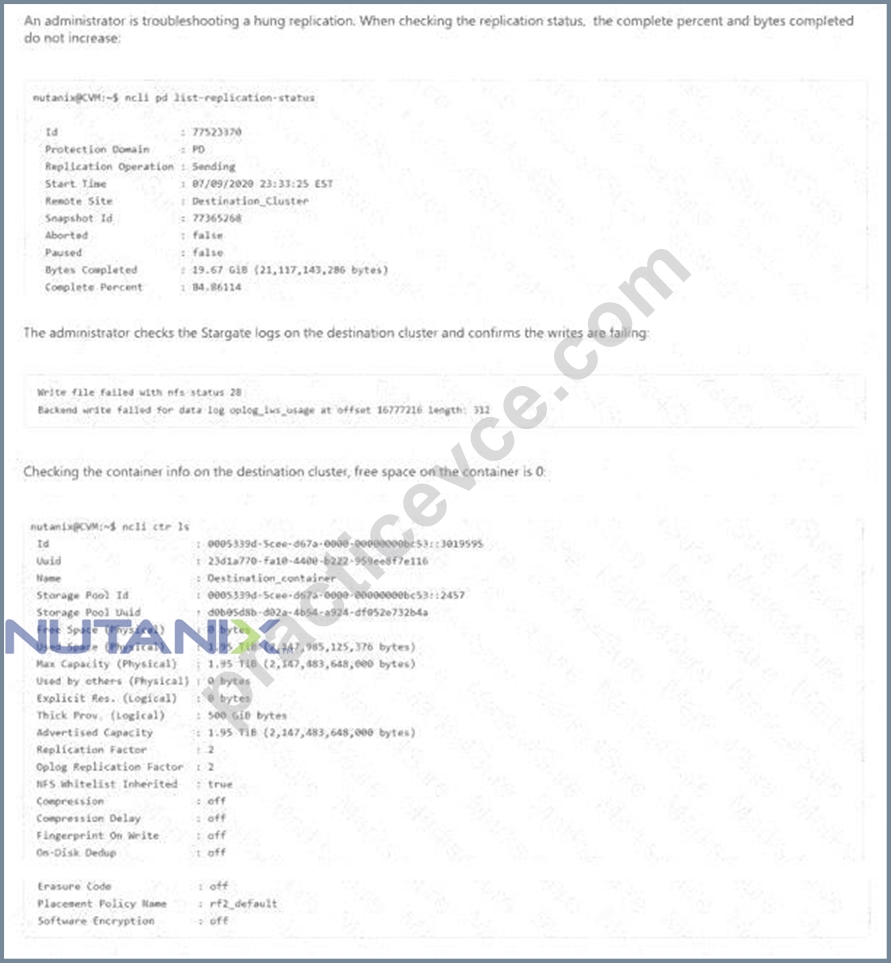
Answer: B
Explanation:
In a Nutanix environment, " Advertised Capacity " is a logical limit (a quota) that an administrator can set on a specific storage container. Even if the physical storage pool has terabytes of free space, if a container ' s advertised capacity is reached, the hypervisor and the Nutanix services will perceive the container as being
100% full.
In this troubleshooting scenario, the " nfs status 28 " error code is a standard indicator for " No space left on device " . Since the administrator confirmed the pool is healthy, the logical limit on the container is the only remaining bottleneck. Replication jobs will " hang " because the destination Stargate service cannot write the incoming data blocks to a container that reports zero free space. To resolve this, the administrator must either increase the advertised capacity value in Prism or remove the limit entirely to allow the container to consume the available physical space in the pool. This highlights a common configuration " trap " where logical quotas-intended for multi-tenant management-can inadvertently block critical BCDR processes like replication if not monitored or sized correctly according to the protected VM growth.
NEW QUESTION # 28
An administrator is planning to deploy some 2-node clusters and is reviewing data protection strategies for some of the critical VMs.
What can be the minimum RPO for these VMs?
Answer: B
Explanation:
Nutanix 2-node clusters are often used in small remote office (ROBO) environments to provide high availability with a smaller hardware footprint. However, the reduced node count introduces specific limitations on advanced data protection features compared to standard 3-node or larger clusters.
One of the key limitations of a 2-node cluster is the support for high-frequency replication. Technologies like NearSync (which provides RPOs from 1 to 15 minutes) and Synchronous replication (0 RPO) require a minimum of three nodes to manage the necessary metadata overhead, storage consistency, and lightweight snapshot (LWS) engine requirements. In a 2-node cluster, the system is restricted to using standard Asynchronous replication. The minimum RPO supported for standard Asynchronous replication in these small cluster configurations is typically 1 hour (60 minutes). An administrator attempting to set a more aggressive RPO will find that the system does not support the necessary lightweight snapshot infrastructure.
Therefore, while a 2-node cluster provides excellent local availability, its off-site disaster recovery capability is limited to a 1-hour RPO, which should be considered during the initial architectural design and risk assessment phase for critical workloads.
NEW QUESTION # 29
After an unplanned outage, all VMs were successfully failed over to the recovery site, and users are now accessing workloads from there. The DR dashboard shows the failover is complete and replication from the original primary site has stopped. As part of post-failover cleanup, what is the most appropriate next action to ensure the DR configuration reflects the current production state and is ready for future protection?
Answer: C
Explanation:
Following a successful unplanned failover, the " Recovery Site " has technically become the new " Production Site " . However, the data protection relationship is now one-sided; while the VMs are running at the recovery site, they are likely no longer being replicated anywhere because the original protection policy was designed to move data from the (now failed) primary site to the recovery site.
The most critical post-failover task is to " re-protect " the workloads. This involves updating the Protection Policies in Prism Central to establish a new replication direction, typically from the current active site (the old recovery site) back to the original primary site (once it is restored) or to a third availability zone. Without re- protection, the business is running its production workloads without a safety net, leaving them vulnerable to a second failure. Deleting recovery points (Option A) is dangerous as it removes the only historical data available. Leaving the environment as-is (Option B) ignores the lack of ongoing protection. Initiating an immediate failback (Option D) is often impossible or unwise until the original site is fully stabilized and the data has been synchronized back. Therefore, establishing a new protection stream is the mandatory next step for operational resilience.
NEW QUESTION # 30
A VM is configured with a 5-minute Nearsync RPO. After several hours, replication transitions back to hourly RPO. Alerts indicate the minute schedule cannot be maintained. What is the most likely root cause?
Answer: D
Explanation:
Nutanix NearSync replication uses Lightweight Snapshots (LWS) to achieve RPOs as low as 1 minute. To maintain this aggressive schedule, the system must be able to replicate all the " delta " changes (the data that has changed since the last snapshot) within the RPO window. If the data change rate (churn) of the VM increases, or if the available network bandwidth decreases, the system may find that it cannot complete the replication of one LWS before the next one is due.
When the Nutanix Cerebro service detects that it is consistently missing its NearSync target, it will automatically " downshift " the replication to a standard Asynchronous schedule (typically hourly) to ensure that the VM remains protected at a manageable frequency. This is a self-healing mechanism designed to prevent replication jobs from stacking up and causing cluster instability. Insufficient bandwidth (Option D) is the most common cause for this downshift, as the " Snapshot-on-wire " cannot be moved fast enough to satisfy the 5-minute requirement. While high RTT (Option A) is a requirement for Synchronous replication, NearSync is designed to handle higher latencies (up to 80ms or more), making bandwidth the primary bottleneck in these troubleshooting scenarios.
NEW QUESTION # 31
......
Are you tired of feeling overwhelmed and unsure about how to prepare for the NCP-BC-7.5 exam? Are you ready to take control of your future and get the NCP-BC-7.5 certification you need to accelerate your career? If so, it's time to visit PracticeVCE and download real NCP-BC-7.5 Exam Dumps. Our team of experts has designed a Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 (NCP-BC-7.5) exam study material that has already helped thousands of students just like you achieve their goals. We offer a comprehensive NCP-BC-7.5 practice exam material that is according to the content of the Nutanix NCP-BC-7.5 test.
Cert NCP-BC-7.5 Exam: https://www.practicevce.com/Nutanix/NCP-BC-7.5-practice-exam-dumps.html