BTW, DOWNLOAD part of ActualPDF Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=17awqUoZLhYJj6XmPb3W74iKOGDCCLvzu
Regularly updated material content to ensure you are always practicing with the most up-to-date preparation material which covers all the changes that are made to the Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam questions from ActualPDF. Our preparation material is built in such a way that it will help everyone even a beginner to reach his goal of clearing the Google Professional-Machine-Learning-Engineer Exam Dumps from ActualPDF just in one attempt.
Google Professional Machine Learning Engineer Exam is a certification program that focuses on the skills and knowledge required to design, build, and deploy machine learning models on the Google Cloud Platform. Google Professional Machine Learning Engineer certification is awarded to individuals who have demonstrated their proficiency in developing and implementing machine learning solutions on the Google Cloud Platform.
Google Professional Machine Learning Engineer certification is highly valued by employers, as it demonstrates the candidate's ability to design, build, and deploy machine learning models using the Google Cloud Platform. Google Professional Machine Learning Engineer certification is also a testament to the candidate's commitment to staying up-to-date with the latest advancements in the field of machine learning.
>> Professional-Machine-Learning-Engineer Valid Real Exam <<
We offer you free update for one year if you buy Professional-Machine-Learning-Engineer training materials from us. That is to say, in the following year, you will get the latest version once the Professional-Machine-Learning-Engineer exam dumps update. It can save your money for buying new version. In addition, the Professional-Machine-Learning-Engineer learning materials of us is compiled by experienced experts, and the quality can be guaranteed, you can pass your exam just one time by using ourProfessional-Machine-Learning-Engineer Exam Dumps. We also have online and offline service stuff, if you have any question, you can consult us.
Google Professional Machine Learning Engineer Exam is a certification exam designed to validate an individual's expertise in machine learning engineering. Professional-Machine-Learning-Engineer exam aims to assess the candidate's ability to create and deploy highly scalable, robust, and maintainable machine learning models using Google Cloud Platform technologies. Professional-Machine-Learning-Engineer Exam also tests the candidate's proficiency in designing and implementing machine learning architectures, solving business problems using machine learning, and optimizing machine learning workflows.
NEW QUESTION # 170
You are training an object detection model using a Cloud TPU v2. Training time is taking longer than expected. Based on this simplified trace obtained with a Cloud TPU profile, what action should you take to decrease training time in a cost-efficient way?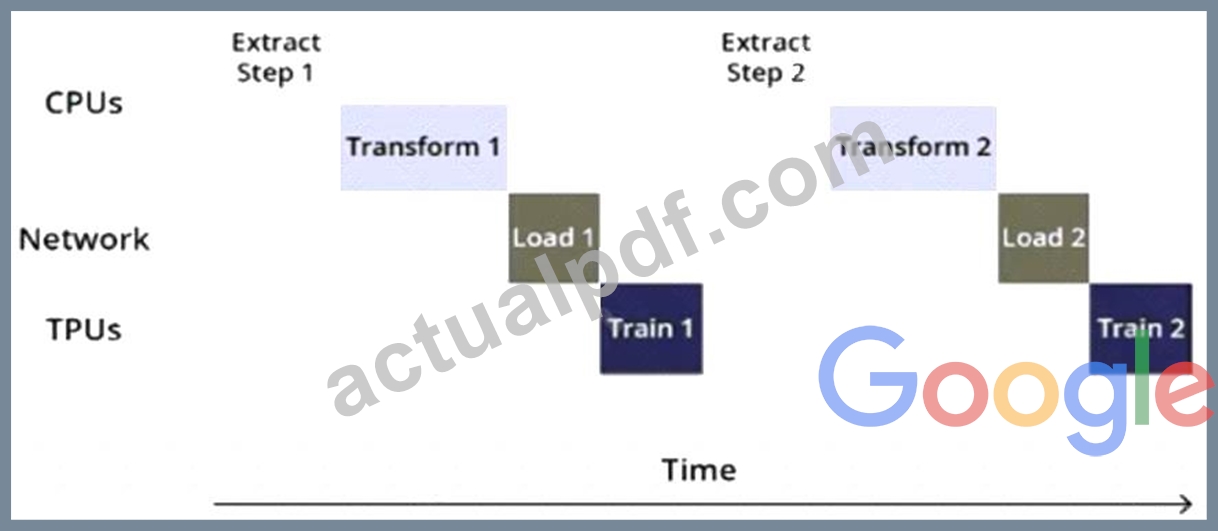
Answer: C
Explanation:
The trace in the question shows that the training time is taking longer than expected. This is likely due to the input function not being optimized. To decrease training time in a cost-efficient way, the best option is to rewrite the input function using parallel reads, parallel processing, and prefetch. This will allow the model to process the data more efficiently and decrease training time. References:
* [Cloud TPU Performance Guide]
* [Data input pipeline performance guide]
NEW QUESTION # 171
You are developing a custom TensorFlow classification model based on tabular data. Your raw data is stored in BigQuery. contains hundreds of millions of rows, and includes both categorical and numerical features. You need to use a MaxMin scaler on some numerical features, and apply a one-hot encoding to some categorical features such as SKU names. Your model will be trained over multiple epochs. You want to minimize the effort and cost of your solution. What should you do?
Answer: D
NEW QUESTION # 172
You need to design an architecture that serves asynchronous predictions to determine whether a particular mission-critical machine part will fail. Your system collects data from multiple sensors from the machine. You want to build a model that will predict a failure in the next N minutes, given the average of each sensor's data from the past 12 hours. How should you design the architecture?
Answer: C
Explanation:
* Reasoning: The question asks for a design that serves asynchronous predictions to determine whether a machine part will fail. This means that the predictions do not need to be returned immediately to the sensors, but can be processed in batches and sent to a downstream system for monitoring. Option B is the only one that uses a streaming data pipeline with Pub/Sub and Dataflow, which can handle real-time data ingestion, processing, and prediction. Option B also invokes the model for prediction, which is required by the question. The other options either use synchronous predictions (option A), batch predictions (options C and D), or do not invoke the model for prediction (option D).
* References: You can learn more about the differences between synchronous, asynchronous, and batch predictions in Vertex AI from this document. You can also find examples of how to use Pub/Sub and Dataflow for streaming data pipelines from this tutorial and this codelab.
NEW QUESTION # 173
You need to train a computer vision model that predicts the type of government ID present in a given image using a GPU-powered virtual machine on Compute Engine. You use the following parameters:
* Optimizer: SGD
* Image shape = 224x224
* Batch size = 64
* Epochs = 10
* Verbose = 2
During training you encounter the following error: ResourceExhaustedError: out of Memory (oom) when allocating tensor. What should you do?
Answer: B
Explanation:
A ResourceExhaustedError: out of memory (OOM) when allocating tensor is an error that occurs when the GPU runs out of memory while trying to allocate memory for a tensor. A tensor is a multi-dimensional array of numbers that represents the data or the parameters of a machine learning model. The size and shape of a tensor depend on various factors, such as the input data, the model architecture, the batch size, and the optimization algorithm 1 .
For the use case of training a computer vision model that predicts the type of government ID present in a given image using a GPU-powered virtual machine on Compute Engine, the best option to resolve the error is to reduce the batch size. The batch size is a parameter that determines how many input examples are processed at a time by the model. A larger batch size can improve the model's accuracy and stability, but it also requires more memory and computation. A smaller batch size can reduce the memory and computation requirements, but it may also affect the model's performance and convergence 2 .
By reducing the batch size, the GPU can allocate less memory for each tensor, and avoid running out of memory. Reducing the batch size can also speed up the training process, as the GPU can process more batches in parallel. However, reducing the batch size too much may also have some drawbacks, such as increasing the noise and variance of the gradient updates, and slowing down the convergence of the model. Therefore, the optimal batch size should be chosen based on the trade-off between memory, computation, and performance 3
.
The other options are not as effective as option B, because they are not directly related to the memory allocation of the GPU. Option A, changing the optimizer, may affect the speed and quality of the optimization process, but it may not reduce the memory usage of the model. Option C, changing the learning rate, may affect the convergence and stability of the model, but it may not reduce the memory usage of the model.
Option D, reducing the image shape, may reduce the size of the input tensor, but it may also reduce the quality and resolution of the image, and affect the model's accuracy. Therefore, option B, reducing the batch size, is the best answer for this question.
References:
ResourceExhaustedError: OOM when allocating tensor with shape - Stack Overflow How does batch size affect model performance and training time? - Stack Overflow How to choose an optimal batch size for training a neural network? - Stack Overflow
NEW QUESTION # 174
You have deployed a model on Vertex AI for real-time inference. During an online prediction request, you get an "Out of Memory" error. What should you do?
Answer: C
Explanation:
* Option A is incorrect because using batch prediction mode instead of online mode does not solve the
"Out of Memory" error, but rather changes the latency and throughput of the prediction service. Batch prediction mode is suitable for large-scale, asynchronous, and non-urgent predictions, while online prediction mode is suitable for low-latency, synchronous, and real-time predictions1.
* Option B is correct because sending the request again with a smaller batch of instances can reduce the memory consumption of the prediction service and avoid the "Out of Memory" error. The batch size is the number of instances that are processed together in one request. A smaller batch size means less data to load into memory at once2.
* Option C is incorrect because using base64 to encode your data before using it for prediction does not reduce the memory consumption of the prediction service, but rather increases it. Base64 encoding is a way of representing binary data as ASCII characters, which increases the size of the data by about
33%3. Base64 encoding is only required for certain data types, such as images and audio, that cannot be represented as JSON or CSV4.
* Option D is incorrect because applying for a quota increase for the number of prediction requests does not solve the "Out of Memory" error, but rather increases the number of requests that can be sent to the
* prediction service per day. Quotas are limits on the usage of Google Cloud resources, such as CPU, memory, disk, and network5. Quotas do not affect the performance of the prediction service, but rather the availability and cost of the service.
References:
* Choosing between online and batch prediction
* Online prediction input data
* Base64 encoding
* Preparing data for prediction
* Quotas and limits
NEW QUESTION # 175
......
Dumps Professional-Machine-Learning-Engineer Vce: https://www.actualpdf.com/Professional-Machine-Learning-Engineer_exam-dumps.html
BTW, DOWNLOAD part of ActualPDF Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=17awqUoZLhYJj6XmPb3W74iKOGDCCLvzu