Therefore, you must stay informed as per these changes to save time, money, and mental peace. As was already discussed, Itcertmaster satisfies the needs of Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam candidates. The customer will receive updates of Operationalizing Machine Learning and Generative AI Solutions (AI-300) real dumps for up to 365 days after buying the product. Our offers don't stop here. If our customers want to evaluate the Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam dumps before paying us, they can download a free demo as well.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Topic 2: Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Topic 3: Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
| Topic 4: Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Topic 5: Implement machine learning model lifecycle and operations | 25–30% | - Monitor and maintain models in production
|
>> Reliable AI-300 Practice Materials <<
The high quality and high efficiency of our AI-300 exam materials has helped many people pass exams quickly. And we can proudly claim that if you study with our AI-300 study questions for 20 to 30 hours, then you can confidently pass the exam for sure. After our worthy customers get a AI-300 certificate, they now have more job opportunities. The current situation is very serious. Selecting AI-300 training guide is your best decision.
NEW QUESTION # 44
A team deploys a model to a real-time endpoint in Azure Machine Learning. You deploy some updates to the endpoint.
The endpoint returns errors after the new deployment is released.
You need to restore the service as quickly as possible.
What should you do first?
Answer: C
Explanation:
To restore the service as quickly as possible, you can roll back traffic to the previous deployment by updating the traffic allocation settings of your Azure Machine Learning online endpoint.
Azure Machine Learning managed online endpoints support multiple deployments under a single endpoint, allowing for blue-green deployment strategies where you can shift traffic between versions instantly.
Key Benefits of This Approach
Instant Recovery: Traffic shifting is a routing change and does not require redeploying the previous model's code or environment, making it the fastest recovery method.
No Downtime: Because the previous deployment remains "warm" (active but receiving no traffic), the switch happens without interrupting the service.
Isolation for Debugging: You can keep the failing deployment at 0% traffic to inspect its logs using az ml online-deployment get-logs without affecting end users How to Roll Back Traffic If your new deployment (e.g., "green") is returning errors, you can reallocate 100% of the traffic back to the known stable deployment (e.g., "blue") using the following methods:
* Azure CLI: Use the az ml online-endpoint update command to set the traffic percentage:
az ml online-endpoint update --name <your-endpoint-name> --traffic "blue=100 green=0"
* Azure Machine Learning Studio:
Navigate to Endpoints in the left menu.
Select your specific real-time endpoint.
Go to the Details or Live Traffic tab.
Adjust the traffic percentages so the previous deployment receives 100% and the failing deployment receives 0%.
Select Update or Save to apply the changes immediately
Reference:
https://learn.microsoft.com/en-us/answers/questions/1275110/azure-ml-v2-yaml-code-for-live- traffic-allocation
NEW QUESTION # 45
You create an Azure Machine Learning workspace.
You must use the Python SDK v2 to implement an experiment from a Jupyter notebook in the workspace. The experiment must log a list of numerical metrics.
You need to implement a method to log a list of numerical metrics.
Which method should you use?
Answer: A
Explanation:
To log a list of numerical metrics using the Azure Machine Learning Python SDK v2, you should use the mlflow.log_metric() method within a loop, or mlflow.log_metrics() to log them simultaneously as a dictionary.
Reference:
https://learn.microsoft.com/en-us/answers/questions/1456554/downloading-azureml-experiment-metrics-logged-with
NEW QUESTION # 46
You are preparing training data for a fine-tuning job in Microsoft Foundry.
Real production conversations cannot be used due to compliance requirements.
You need to generate synthetic interaction data that can be used for fine-tuning a generative model.
What should you do?
Answer: D
Explanation:
The correct approach is to generate synthetic prompt-response interactions that reproduce the structure and behavioral patterns of the target task. Microsoft Foundry supports synthetic data generation specifically for cases where real production data is unavailable, scarce, sensitive, or subject to privacy and compliance restrictions. Generated examples can be converted into the structured conversational format required for fine- tuning, such as JSONL containing messages with system, user, and assistant roles.
A simulator or synthetic-data generator can construct representative conversations without exposing genuine customer interactions. This allows the team to create sufficient task-specific examples, review their quality, remove unsuitable samples, and then use the resulting dataset for supervised fine-tuning. Microsoft notes that synthetic data can preserve useful task structure while avoiding reliance on proprietary or sensitive production datasets.
Option A is incorrect because evaluation logs are primarily intended for assessment and observability and are not automatically suitable as training examples. Option C directly violates the requirement because it captures real production traffic. Option D confuses training data with observability artifacts: telemetry logs and traces describe execution behavior and diagnostics rather than producing the prompt-response examples required for fine-tuning.
Study Guide Reference: Optimize generative AI systems and model performance - synthetic data generation, supervised fine-tuning datasets, simulator-based interaction generation, privacy-preserving model customization, and training-data preparation.
NEW QUESTION # 47
You manage an Azure Machine Learning workspace by using the Python SDK v2.
You must create a compute cluster in the workspace. The compute cluster must run workloads and properly handle interruptions. You start by calculating the maximum amount of compute resources required by the workloads and size the cluster to match the calculations.
The cluster definition includes the following properties and values:
* name= " mlcluster1''
* size= " STANDARD.DS3.v2 "
* min_instances=1
* maxjnstances=4
* tier= " dedicated "
The cost of the compute resources must be minimized when a workload is active Of idle. Cluster property changes must not affect the maximum amount of compute resources available to the workloads run on the cluster.
You need to modify the cluster properties to minimize the cost of compute resources.
Which properties should you modify? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.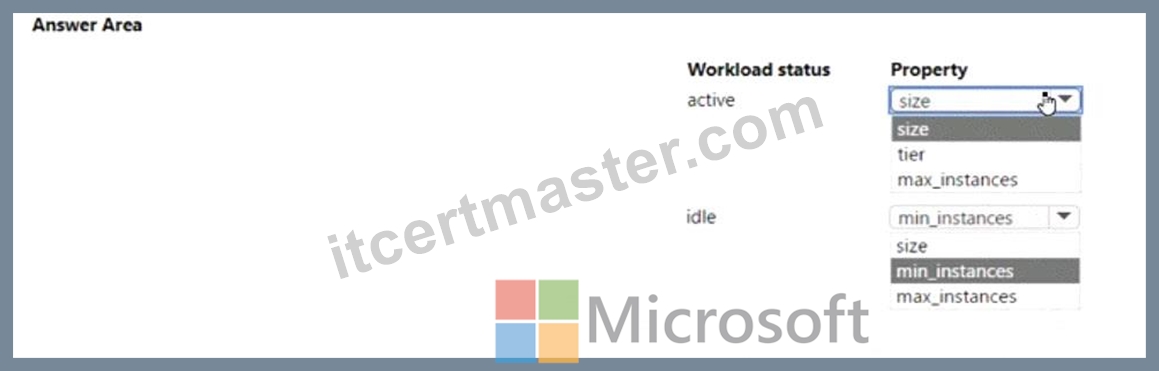
Answer:
Explanation: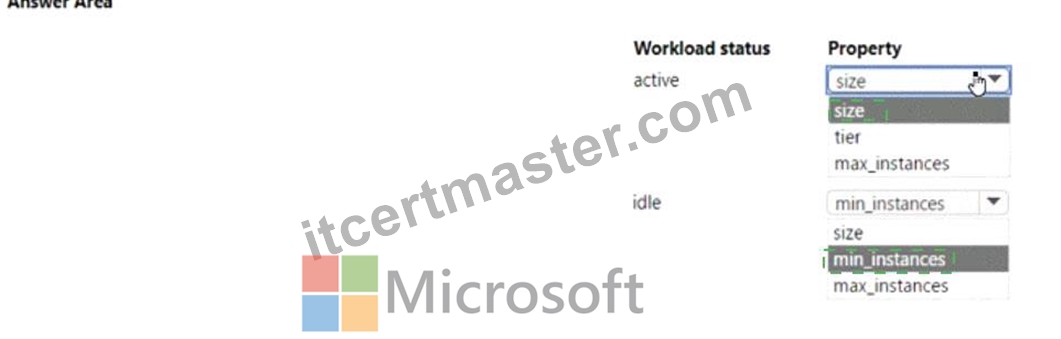
Explanation: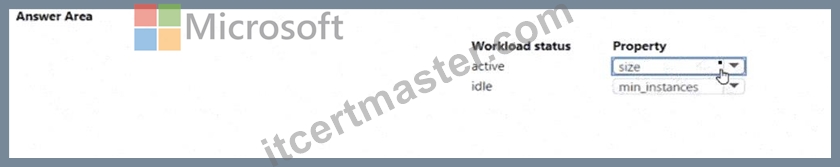
NEW QUESTION # 48
Hotspot Question
A team retrains a machine learning model on a weekly basis by using updated training data.
The team must be able to rerun any previous experiment by using the exact data that was available at the time it was originally run. The solution must preserve historical versions of the data without duplicating training scripts.
You need to manage the data so that experiments can be reproduced reliably.
Which workspace actions should you perform? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.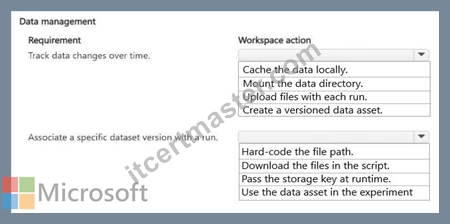
Answer:
Explanation:
Explanation:
Box 1: Create a versioned dataset
Track data changes over time.
Creating a versioned dataset in your machine learning workspace configuration is the correct and industry-standard way to solve this.
Versioned datasets allow you to decouple your training scripts from your data state. This approach satisfies all your constraints without duplicating code or creating messy infrastructure.
Enables Reproducibility: Every time you run a training job, you log the specific dataset version used (e.g., v1, v2, v3). To rerun a historical experiment, you simply call that specific version identifier.
Prevents Code Duplication: Your training scripts remain identical. They accept a dataset version as an input parameter rather than pointing to hardcoded file paths.
Tracks Weekly Updates: When the weekly data refresh occurs, you register the new data as v+1 in the workspace registry, keeping a clean chronological ledger.
Box 2: Use the data asset in the experiment
Associate a specific dataset version with a run.
To best associate a specific dataset version with a run in the workspace, you should use the data asset in the experiment.
Automatic Lineage: Registering data as a versioned data asset automatically tracks which exact version was used in which specific run.
Exact Reproducibility: You can look back at any historical run and instantly identify or retrieve the precise data state used at that moment.
No Script Duplication: Your training scripts remain decoupled from the data, satisfying your requirement to preserve history without changing code.
Incorrect:
[Pass the storage key at runtime]
Passing a storage key at runtime only connects the run to a storage location, not a specific, immutable version of the data at a frozen point in time.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-version-track-datasets
NEW QUESTION # 49
......
We are pleased to inform you that we have engaged in this business for over ten years with our Operationalizing Machine Learning and Generative AI Solutions AI-300 exam questions. Because of our experience, we are well qualified to take care of your worried about the AI-300 Preparation exam and smooth your process with successful passing results.
Latest AI-300 Exam Papers: https://www.itcertmaster.com/AI-300.html