Valid SPS-C01 Test Discount | Hot SPS-C01 Questions
Passing a SPS-C01 certification exam is very hard. It gives the exam candidates a tough time as it requires the most updated information and hands-on experience on the contents of the syllabus. UpdateDumps's SPS-C01 brain dumps make your preparation easier. They provide you authentic and verified information and the most relevant set of questions and answers that will help you attain success in your SPS-C01 Exam.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Transformations and Operations | 35% | - User-defined logic
- 1. UDFs, UDAFs, UDTFs
- 2. Stored procedures with Snowpark
- DataFrame manipulation
- 1. Selection, projection, renaming, casting
- 2. Filtering, sorting, grouping, aggregation
- 3. Joins, unions, set operations
- Advanced operations
- 1. Window functions and analytics
- 2. Semi-structured data processing
- 3. Pivot and unpivot transformations
|
| Topic 2: Snowpark Concepts and Architecture | 25% | - Session management and connection
- 1. Create and configure Snowpark sessions
- 2. Authentication and connection settings
- Snowpark architecture and execution model
- 1. Client-side vs server-side processing
- 2. Transformations vs actions
- 3. Lazy evaluation and DAG execution
|
| Topic 3: Performance and Best Practices | 10% | - Optimization techniques
- 1. Caching and warehouse sizing
- 2. Query pushdown and execution plans
- 3. Minimizing data movement
- Security and governance
- 1. Data protection and compliance
- 2. Access control and permissions
|
| Topic 4: Snowpark API and Development | 30% | - Python API fundamentals
- 1. Data persistence and writing results
- 2. Column operations and functions
- 3. DataFrame creation from tables, views, SQL
- Multi-language support
- 1. Environment setup and dependencies
- 2. Java and Scala API basics
|
>> Valid SPS-C01 Test Discount <<
Hot SPS-C01 Questions, SPS-C01 Reliable Dump
We know that the standard for most workers become higher and higher; so we also set higher goal on our SPS-C01 guide questions. Our training materials put customers' interests in front of other points, committing us to the advanced SPS-C01 learning materials all along. Until now, we have simplified the most complicated SPS-C01 Guide questions and designed a straightforward operation system, with the natural and seamless user interfaces of SPS-C01 exam question grown to be more fluent, we assure that our practice materials provide you a total ease of use.
Snowflake Certified SnowPro Specialty - Snowpark Sample Questions (Q287-Q292):
NEW QUESTION # 287
You are developing a Snowpark application to analyze website traffic data'. You have a DataFrame named 'website_logs' with columns 'user_id', 'page_url', and 'timestamp'. You need to create a new DataFrame that contains the count of distinct users who visited each page within a specific time window Consider the following (incomplete) Snowpark Python code:
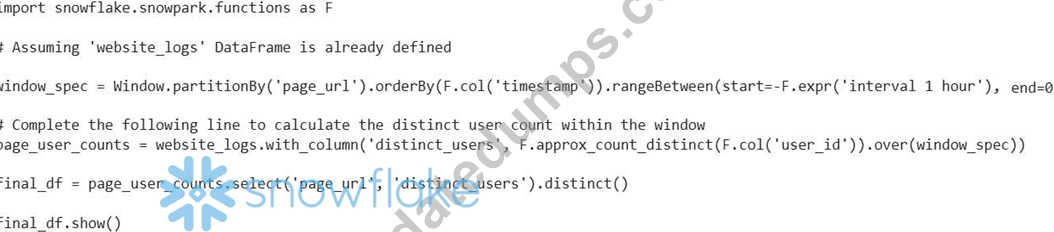
Which of the following code lines, when inserted into the Complete the following line...' comment, will correctly calculate the approximate distinct user count for each page within the specified time window?
- A. website_logs.groupBy('page_url').agg(F.countDistinct('user_id').alias('distinct_users'))
- B. _logs.with_column('distinct_users', F.countDistinct('user_id').over(window_spec)) website
- C. website_logs.groupBy('page_url', F.window('timestamp', '1 hour')).agg(F.countDistinct('user_id').alias('distinct_users'))
- D. website_logs.with_column('distinct_users', F.count('user_id').over(window_spec))
- E. website_logs.with_column('distinct_users', F.approx_count_distinct('user_id').over(window_spec))
Answer: E
Explanation:
The correct code line is 'website_logs.with_column('distinct_users', F.approx_count_distinct('user_id').over(window_spec))'. This uses the function to calculate the approximate distinct count of user IDs within the window defined by 'window_spec' . Option B uses exact count which is less performant. Option A performs an aggregation, which will give a different type of result. Option D uses F.window' which is used for tumbling windows, not sliding windows as requested by the problem.
NEW QUESTION # 288
You have a Snowpark Python stored procedure that reads data from a Snowflake table, performs a complex calculation using Pandas, and then writes the results back to another Snowflake table. You are experiencing performance issues, and you suspect the data transfer between Snowpark and Pandas is a bottleneck. Which of the following techniques could significantly improve the performance of this stored procedure? (Select two)
- A. Use the 'TABLE function in Snowpark to directly access the source table instead of reading the entire table into a Snowpark DataFrame at once.
- B. Increase the warehouse size to the largest possible value before executing the stored procedure.
- C. Utilize vectorized operations within Pandas to minimize explicit looping and improve calculation speed.
- D. Convert the Pandas DataFrame to a Dask DataFrame for distributed computation.
- E. Leverage Snowpark's optimized functions and UDFs wherever possible to perform transformations within Snowflake's engine instead of transferring data to Pandas.
Answer: C,E
Explanation:
Options B and D are the most effective. Vectorized operations (B) significantly speed up Pandas calculations. Performing transformations within Snowflake (D) avoids unnecessary data transfer between Snowpark and Pandas, reducing the bottleneck. A is useful, but secondary. C only affects Snowflake side processing, but it may help. E would be useful, but not as helpful as pushing as much as possible down to Snowflake processing.
NEW QUESTION # 289
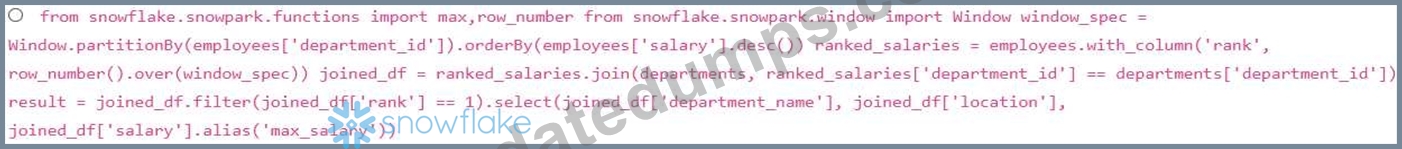
Consider two Snowpark DataFrames, 'employees' and 'departments' , with the following schemas: 'employees': (employee_id: Integer Type, employee_name: StringType, department_id: Integer Type, salary: IntegerType) 'departments': (department_id: Integer Type, department_name: StringType, location: StringType) You want to find the highest salary within each department, along with the department name and location, and display the results in a Snowpark DataFrame. Which of the following Snowpark Python code snippets correctly achieves this?
Answer: C
Explanation:
Option A correctly groups the 'employees' DataFrame by 'department_id' , calculates the maximum salary for each department using and then joins the resulting DataFrame with the 'departments' DataFrame on Finally, it selects the required columns: department name, location, and the calculated maximum salary. Option B is not correct as it calculates the rank of all salaries within each department but it does not aggregate on 'department_id'. Option C incorrectly attempts to group by columns from both tables before joining. Option D incorrectly uses the un-joined employees table where rank_salaries are from department_id. Option E will not work due to table names during select. It tries to use 'joined_df table for columns which doesn't have it.
NEW QUESTION # 290
You are developing a Snowpark application to process large datasets. You want to leverage asynchronous jobs to improve performance and prevent blocking the main thread. You have the following code snippet:
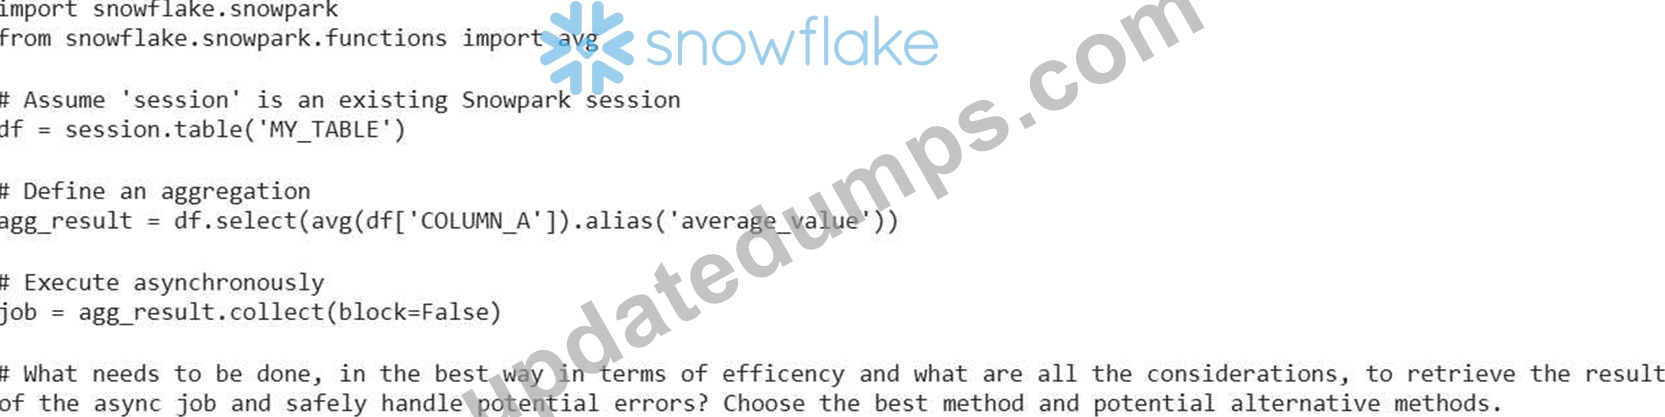
- A. Call 'job.result(Y without any error handling. Snowflake will automatically handle any errors and return a null result.
- B. Implement a callback function using 'job.on_success(callback_function)' and 'job.on_error(error_function)' to handle the result or any errors asynchronously.
- C. Continuously check 'job.status' in a loop until it returns 'SUCCESS', then retrieve the result using 'job.result()'. This is less efficient due to polling.
- D. Use to retrieve the result with a timeout of 30 seconds, catching 'TimeoutError' if the job takes too long. This is the only way to get the result safely.
- E. Use 'job.getQueryld(Y to fetch the query ID and query the execution status directly from Snowflake using SQL. This is inefficient and bypasses the Snowpark API.
Answer: B
Explanation:
Option D is the most robust and recommended approach for handling asynchronous Snowpark jobs. Using callback functions allows for non-blocking execution and proper error handling. ensures that the main thread doesn't proceed until the asynchronous job has completed. Option B, while functionally correct, introduces inefficient polling. Options A and C lack comprehensive error handling or assume error handling behavior that Snowflake doesn't provide directly. Option E bypasses the Snowpark API and introduces unnecessary complexity.
NEW QUESTION # 291
You are working with a Snowpark DataFrame representing sensor data. The DataFrame contains columns like 'timestamp', 'sensor id' , and 'value'. You need to perform a complex windowing operation to calculate the moving average of the 'value' for each 'sensor id' over a 5-minute window, but only for data points where the 'value' is greater than a threshold. The window should be defined based on the 'timestamp' column. What is the most efficient and correct approach to implement this using Snowpark DataFrames?
- A. First, collect the entire DataFrame into a Pandas DataFrame, then use Pandas windowing functions to calculate the moving average.
- B. Use a loop to iterate over each 'sensor_id' , filter the DataFrame for that sensor, calculate the moving average using Pandas windowing functions, and then combine the results.
- C. Create a UDF that takes a list of timestamps and values as input and returns the moving average. Apply this UDF to the entire DataFrame.
- D. First apply the moving average calculation to the DataFrame and then filter for rows with values exceeding the threshold, since calculations are performed in order.
- E. Use a combination of 'filter' to apply the threshold condition, 'Window.partitionBy' and 'Window.orderBy' to define the window, and 'avg' window function to calculate the moving average.
Answer: E
Explanation:
The most efficient and correct approach is to use Snowpark's built-in windowing functions. Applying the threshold using 'filter' before the windowing operation reduces the amount of data processed by the window function, improving performance. Using 'Window.partitionBy' and 'Window.orderBy' correctly defines the window based on 'sensor_id' and 'timestamp', respectively. Using 'avg' window function calculates the moving average within the defined window. Options B, C, and D are less efficient because they involve transferring data to the client side (Pandas) or using UDFs, which can introduce overhead. Option E reverses the correct process.
NEW QUESTION # 292
......
Our SPS-C01 study materials have plenty of advantages. For example, in order to meet the needs of different groups of people, we provide customers with three different versions of SPS-C01 study materials, which contain the same questions and answers. You can choose the one that best suits you according to your study habits. Secondly, the passing rate of our SPS-C01 Study Materials is very high. Generally speaking, 98 % - 99 % of the users can successfully pass the exam, obtaining the corresponding certificate.
Hot SPS-C01 Questions: https://www.updatedumps.com/Snowflake/SPS-C01-updated-exam-dumps.html
- Exam SPS-C01 Torrent 👈 SPS-C01 Exam Study Solutions 🥌 SPS-C01 Exam Dump 🤛 Search for ☀ SPS-C01 ️☀️ and download it for free on 「 www.troytecdumps.com 」 website 🎠SPS-C01 Dumps Cost
- Quiz Marvelous Snowflake Valid SPS-C01 Test Discount 🕣 Open ▛ www.pdfvce.com ▟ and search for “ SPS-C01 ” to download exam materials for free 🐘SPS-C01 Valid Exam Review
- SPS-C01 Latest Dumps 🐊 SPS-C01 Official Practice Test 📥 Certification SPS-C01 Exam Dumps 📴 《 www.vce4dumps.com 》 is best website to obtain 《 SPS-C01 》 for free download 💃SPS-C01 Exam Dump
- SPS-C01 Exam Dump 🥢 SPS-C01 Official Practice Test 🍧 SPS-C01 Exam Study Solutions ✏ Open ⇛ www.pdfvce.com ⇚ and search for 【 SPS-C01 】 to download exam materials for free ⏰SPS-C01 Test Price
- Test SPS-C01 Quiz 🙄 SPS-C01 Test Price 🧞 SPS-C01 Latest Dumps 🍆 Open “ www.vceengine.com ” and search for ⮆ SPS-C01 ⮄ to download exam materials for free ▶SPS-C01 Exam Study Solutions
- Latest SPS-C01 Test Voucher 🏘 SPS-C01 Reliable Exam Papers 👟 SPS-C01 Exam Dump 🏜 Enter ➽ www.pdfvce.com 🢪 and search for ▷ SPS-C01 ◁ to download for free 👉Exam SPS-C01 Torrent
- HOT Valid SPS-C01 Test Discount - High-quality Snowflake Hot SPS-C01 Questions: Snowflake Certified SnowPro Specialty - Snowpark 🥼 The page for free download of ➠ SPS-C01 🠰 on ➡ www.troytecdumps.com ️⬅️ will open immediately 🍢Reliable SPS-C01 Dumps Files
- SPS-C01 Exam Syllabus 🏜 New SPS-C01 Real Exam 🐬 SPS-C01 Latest Dumps 🍫 Search for ➡ SPS-C01 ️⬅️ and obtain a free download on ➽ www.pdfvce.com 🢪 🐒SPS-C01 Exam Dump
- Trustworthy SPS-C01 Exam Torrent ⛴ SPS-C01 Pdf Pass Leader ⬛ Exam SPS-C01 Torrent 💃 Go to website ➤ www.testkingpass.com ⮘ open and search for { SPS-C01 } to download for free ⬅️SPS-C01 Exam Study Solutions
- SPS-C01 Dumps Cost 🌲 SPS-C01 Latest Dumps 🍉 SPS-C01 Lead2pass Review 💖 Open website ✔ www.pdfvce.com ️✔️ and search for ➤ SPS-C01 ⮘ for free download 😯SPS-C01 Latest Dumps
- Trustworthy SPS-C01 Exam Torrent 🥼 Test SPS-C01 Quiz 🐵 SPS-C01 Lead2pass Review 🧴 Search for “ SPS-C01 ” and download it for free immediately on 《 www.vce4dumps.com 》 🍗SPS-C01 Reliable Test Camp
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes