P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by Pass4sures: https://drive.google.com/open?id=1CUBy051imvIkvPqUBIGVRcHj3CWT7s3l
Sometimes choice is greater than important. Good choice may do more with less. If you still worry about your exam, our Amazon MLA-C01 braindump materials will be your right choice. Our exam braindumps materials have high pass rate. Most candidates purchase our products and will pass exam certainly. If you want to fail exam and feel depressed, our Amazon MLA-C01 braindump materials can help you pass exam one-shot.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> MLA-C01 Reliable Test Camp <<
If you study with our MLA-C01 exam questions, then you will be surprised to find that our MLA-C01 training material is well-written and excellently-organised. That is because our experts fully considered the differences in learning methods and MLA-C01 examination models between different majors and eventually formed a complete review system. It will help you to Pass MLA-C01 Exam successfully after a series of exercises, correction of errors, and self-improvement. Our MLA-C01 exam questions contain everything you need to pass the exam.
NEW QUESTION # 215
An ML engineer at a credit card company built and deployed an ML model by using Amazon SageMaker AI.
The model was trained on transaction data that contained very few fraudulent transactions. After deployment, the model is underperforming.
What should the ML engineer do to improve the model's performance?
Answer: D
Explanation:
This is a classic class imbalance problem, where fraudulent transactions (minority class) are severely underrepresented. AWS documentation for SageMaker Data Wrangler recommends SMOTE (Synthetic Minority Oversampling Technique) as an effective approach for improving model performance in such scenarios.
SMOTE generates synthetic minority samples by interpolating between existing minority class examples.
This improves the model's ability to learn decision boundaries without simply duplicating data, which can cause overfitting.
Random undersampling removes valuable majority class data, reducing overall model robustness. Random oversampling duplicates data and increases overfitting risk. Changing algorithms does not address the root cause.
AWS best practices highlight SMOTE as the preferred technique for fraud detection and other highly imbalanced datasets.
Therefore, Option C is the correct and AWS-verified answer.
NEW QUESTION # 216
A company has significantly increased the amount of data that is stored as .csv files in an Amazon S3 bucket.
Data transformation scripts and queries are now taking much longer than they used to take.
An ML engineer must implement a solution to optimize the data for query performance.
Which solution will meet this requirement with the LEAST operational overhead?
Answer: A
Explanation:
AWS documentation strongly recommends using columnar storage formats to optimize analytical query performance on large datasets stored in Amazon S3. Apache Parquet is a columnar, compressed, and splittable file format that significantly improves query speed and reduces I/O compared to row-based formats such as CSV.
By using AWS Glue to convert CSV files into Parquet format, the company can achieve faster query execution with minimal operational overhead. Glue is fully managed, serverless, and integrates natively with S3, Amazon Athena, and Amazon Redshift Spectrum.
Option A does not improve query efficiency; splitting files still leaves the data in an inefficient row-based format. Option B may reduce data size but does not address the fundamental inefficiency of CSV for analytics. Option D introduces significant operational overhead because Amazon EMR requires cluster provisioning, scaling, and maintenance.
Therefore, converting CSV files to Apache Parquet using AWS Glue ETL is the most efficient and low- maintenance solution.
NEW QUESTION # 217
A company uses Amazon SageMaker for its ML workloads. The company's ML engineer receives a 50 MB Apache Parquet data file to build a fraud detection model. The file includes several correlated columns that are not required.
What should the ML engineer do to drop the unnecessary columns in the file with the LEAST effort?
Answer: C
Explanation:
SageMaker Data Wrangler provides a no-code/low-code interface for preparing and transforming data, including dropping unnecessary columns. By creating a data flow and configuring a transform step, the ML engineer can easily remove correlated or unneeded columns from the Parquet file with minimal effort. This approach avoids the need for custom coding or managing additional infrastructure.
NEW QUESTION # 218
A recommendation model uses ML and calls an Amazon SageMaker AI endpoint to get recommendations. An ML engineer must ensure that the model stays available during an expected increase in user traffic.
Which solution will meet these requirements?
Answer: C
Explanation:
Option A is correct because Amazon SageMaker AI supports automatic scaling for hosted models , and AWS documentation states that auto scaling dynamically adjusts the number of instances provisioned for a model in response to workload changes. When traffic increases, auto scaling brings more instances online; when traffic decreases, it removes unneeded capacity. This directly matches the requirement to keep the recommendation endpoint available during an expected increase in user traffic.
AWS also documents that SageMaker integrates with Application Auto Scaling , and you can scale SageMaker endpoint variants by using target tracking , step scaling , and scheduled scaling policies. That means the service is purpose-built for this scenario: maintaining availability and capacity as inference demand changes over time. Since the model is already being served from a SageMaker endpoint, the most direct and AWS-recommended solution is to configure endpoint auto scaling rather than redesigning the deployment.
The other options do not address the requirement as effectively. Creating a new endpoint does not automatically handle fluctuating traffic and adds unnecessary operational complexity. SageMaker Neo optimizes models for inference performance on supported hardware, but it does not provide elastic capacity management. Attaching an Auto Scaling group to a SageMaker endpoint is incorrect because SageMaker endpoints do not use EC2 Auto Scaling groups directly; scaling is handled through SageMaker's integration with Application Auto Scaling. Therefore, to maintain availability during traffic spikes, the best AWS- documented answer is A: configure auto scaling on the SageMaker AI endpoint .
NEW QUESTION # 219
A company has deployed a model to predict the churn rate for its games by using Amazon SageMaker Studio.
After the model is deployed, the company must monitor the model performance for data drift and inspect the report. Select and order the correct steps from the following list to model monitor actions. Select each step one time. (Select and order THREE.) .
Check the analysis results on the SageMaker Studio console. .
Create a Shapley Additive Explanations (SHAP) baseline for the model by using Amazon SageMaker Clarify.
Schedule an hourly model explainability monitor.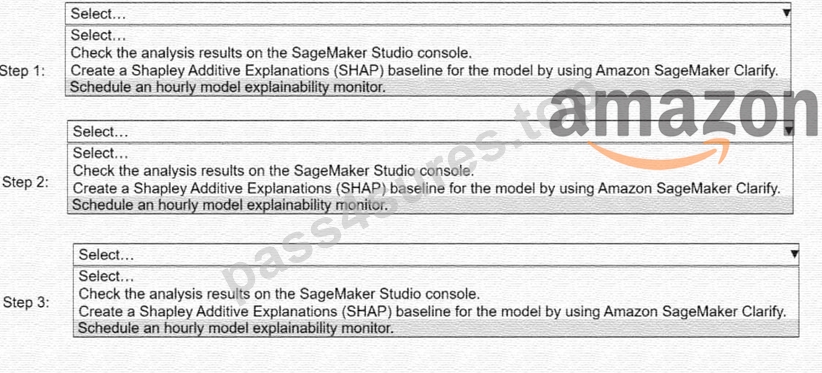
Answer:
Explanation: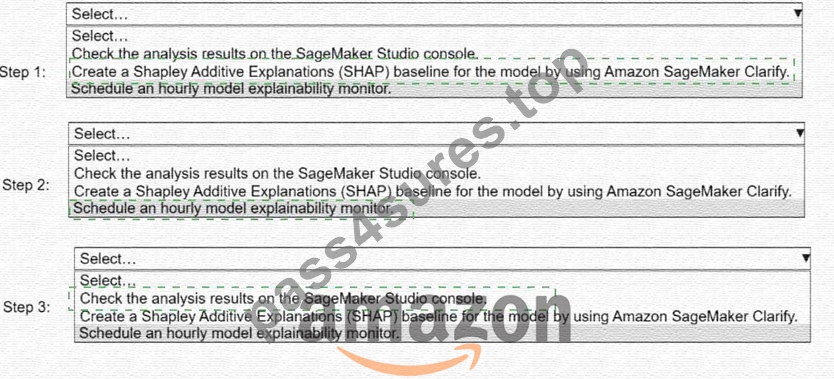
Explanation:
Step 1:
Create a Shapley Additive Explanations (SHAP) baseline for the model by using Amazon SageMaker Clarify.
Step 2:
Schedule an hourly model explainability monitor.
Step 3:
Check the analysis results on the SageMaker Studio console.
When monitoring a deployed model for data drift and explainability, AWS prescribes a specific workflow using SageMaker Clarify and SageMaker Model Monitor:
* Create a SHAP baseline (Step 1)Before any monitoring can occur, SageMaker Clarify must establish a baseline explainability configuration. This baseline captures the reference SHAP values for feature importance using training or baseline data. Model Monitor uses this baseline to compare future inferences and detect drift in feature attributions.
* Schedule the model explainability monitor (Step 2)After the baseline is created, an explainability monitoring schedule must be configured (hourly in this case). The monitor periodically analyzes inference data, compares it against the SHAP baseline, and generates reports that highlight drift or anomalies in feature contributions.
* Inspect results in SageMaker Studio (Step 3)Once monitoring jobs run, SageMaker stores the analysis results in Amazon S3 and surfaces them in the SageMaker Studio console, where engineers can review metrics, violations, and visual reports.
This sequence is mandatory because:
* A monitor cannot run without a baseline
* Results cannot be reviewed until the monitor executes
NEW QUESTION # 220
......
These Amazon MLA-C01 exam questions give you an idea about the final Amazon MLA-C01 exam questions formats, exam question structures, and best possible answers, and you will also enhance your exam time management skills. Finally, at the end of Amazon MLA-C01 Exam Practice test you will be ready to pass the final Amazon MLA-C01 exam easily. Best of luck in Amazon Amazon exam and professional career!!!
Formal MLA-C01 Test: https://www.pass4sures.top/AWS-Certified-Associate/MLA-C01-testking-braindumps.html
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by Pass4sures: https://drive.google.com/open?id=1CUBy051imvIkvPqUBIGVRcHj3CWT7s3l