What's more, part of that PracticeTorrent DP-750 dumps now are free: https://drive.google.com/open?id=1W-b8QyjInySOX5AHEBL_hE4YzfM6j2Hw
Top Rated Features of Microsoft DP-750 Practice Test Questions. The PracticeTorrent is committed to making the Microsoft DP-750 exam preparation journey simple, smart, and swift. To meet this objective the PracticeTorrent is offering DP-750 practice test questions with top-rated features. These features are updated and real Microsoft DP-750 Exam Questions, availability of Implementing Data Engineering Solutions Using Azure Databricks DP-750 exam real questions in three easy-to-use and compatible formats, three months free updated Microsoft DP-750 exam questions download facility, affordable price and 100 percent Implementing Data Engineering Solutions Using Azure Databricks DP-750 exam passing money back guarantee.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Prepare and process data | 30-35% | - Data quality and validation
|
>> DP-750 Intereactive Testing Engine <<
The web-based Microsoft DP-750 practice exam is compatible with all browsers like Chrome, Mozilla Firefox, MS Edge, Internet Explorer, Safari, Opera, and more. Unlike the desktop version, it requires an internet connection. The Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice exam will ask real Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam questions. Consistent practice with it relieves exam stress and boosts self-confidence. The web-based Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice exam does not require additional software installation. All operating systems also support this Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice test.
NEW QUESTION # 48
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
You need to modify rule1 to meet the following requirements:
Ensure that amount is always greater than 0.
Prevent an update to Table1 from being committed when data that violates rule1 is detected.
Which statement should you execute?
Answer: D
Explanation:
The correct answer is C - @dlt.expect_or_fail.
Lakeflow Spark Declarative Pipelines (SDP) offers three expectation decorators, each with a different violation response:
@dlt.expect - logs the violation as a metric but writes all records, including bad ones, to the table. Suitable for monitoring only.
@dlt.expect_or_drop - drops violating records and continues the pipeline. The table receives only clean rows, but the pipeline update commits successfully.
@dlt.expect_or_fail - fails the entire pipeline update when a violation is detected. The table update is never committed. This is the correct choice when data integrity is non-negotiable: 'Prevent an update to Table1 from being committed when data that violates rule1 is detected.'
@dlt.expect_all_or_drop takes a dictionary of rules and drops violating rows but still commits - it doesn't halt the pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 49
You have an Azure Databricks account that contains a single workspace named Workspace1. Workspace1 is enabled for Unity Catalog.
You discover that data access events for Unity Catalog tables fail to appear in the logs.
You need to ensure that all the data access events are captured centrally for auditing purposes. The log data must be available for analysis as quickly as possible.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.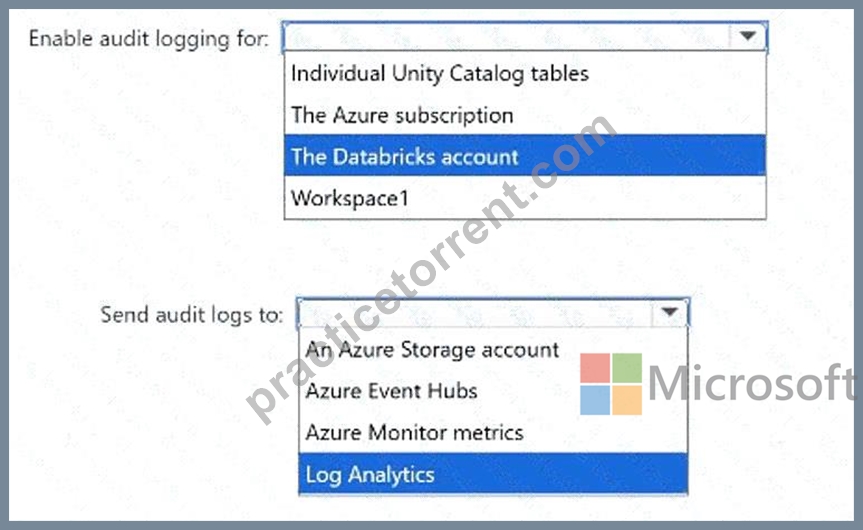
Answer:
Explanation: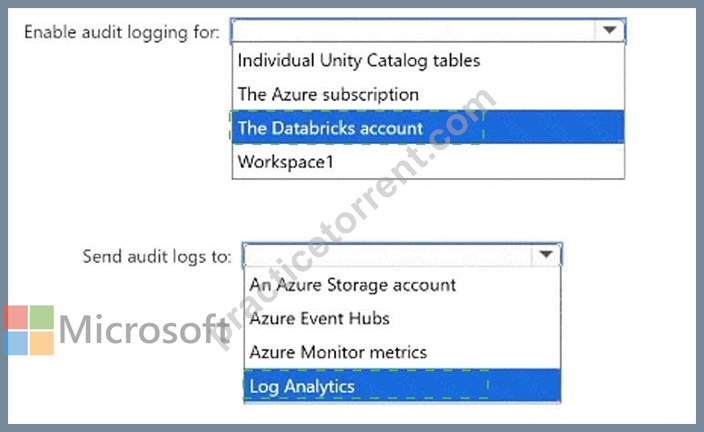
Explanation:
Enable audit logging for: The Databricks account
Send audit logs to: Log Analytics
Enabling audit logging at the Databricks account level provides centralized coverage of account and workspace activities, including Unity Catalog data-access events. Enabling logging only for Workspace1 would provide a narrower configuration and would not offer the same centralized account-level auditing model. Individual Unity Catalog tables and the Azure subscription are not the appropriate Databricks audit- log scope selections. Log Analytics is the suitable destination because it supports rapid ingestion and immediate querying of log records through Azure Monitor Logs. Auditors can search, filter, correlate, and analyze the captured events without first developing a separate data-processing solution. An Azure Storage account is more suitable for inexpensive archival, while Event Hubs is primarily a streaming transport that normally requires an additional consumer before investigators can analyze the records.
NEW QUESTION # 50
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.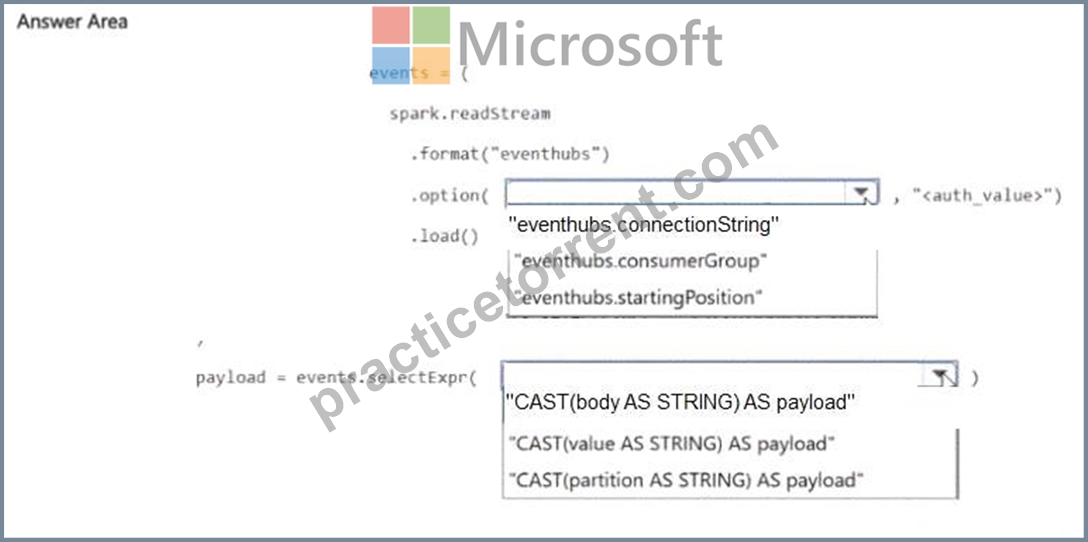
Answer:
Explanation: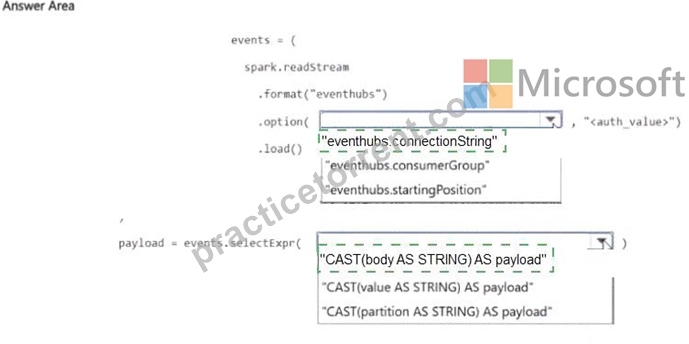
Explanation:
Reading from Azure Event Hubs in Spark Structured Streaming requires three things:
An EventHubsConf object built with the Event Hubs connection string (eventhubs.connectionString). This object is then converted to a map with .toMap before being passed to Spark.
spark.readStream.format( ' eventhubs ' ).options(**ehConf).load() to create the streaming DataFrame. The ' eventhubs ' format is provided by the azure-eventhubs-spark connector library.
A cast( ' string ' ) on the body column to decode the binary payload. Event Hubs delivers messages with the raw event bytes in a column called body - without the cast, you get binary data rather than the readable JSON or text payload.
This is the standard, documented integration pattern for connecting Azure Databricks to Event Hubs with Structured Streaming, providing the checkpoint-based exactly-once semantics required by the Contoso telemetry pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/storage/events/eventhubs
NEW QUESTION # 51
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.dropna(subset=["order_amount"])
Does this meet the goal?
Answer: A
Explanation:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
NEW QUESTION # 52
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out of- memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior. What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.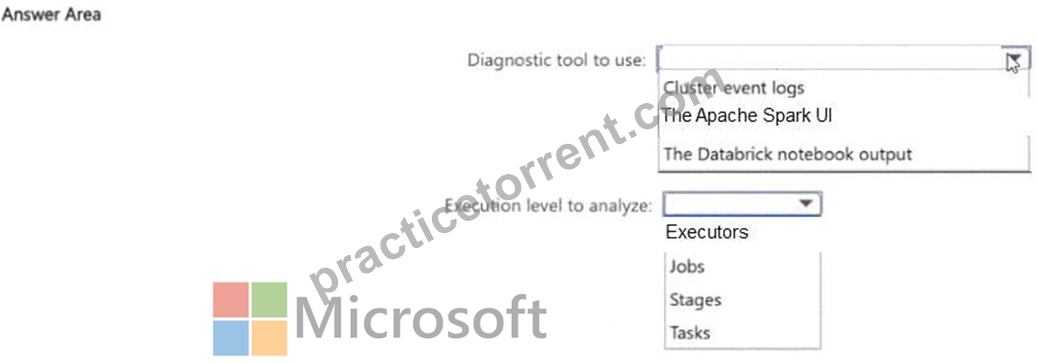
Answer:
Explanation: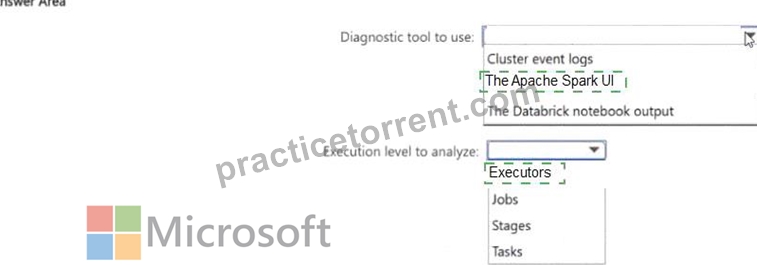
Explanation:
Diagnosing OOM errors requires analysing actual runtime execution behaviour. The Spark UI is the primary tool - it ' s accessible from the cluster detail page and captures rich per-stage and per-task metrics without any extra setup.
In the Executors tab, look at storage memory used, execution memory used, memory spill to disk, and GC time per executor. An executor showing high memory spill is a strong indicator that it ' s processing more data than it can hold in memory - often caused by data skew, where one partition is far larger than the others.
The Stages tab shows task distribution - if one task in a stage is processing 10x more data than its peers, that
' s data skew causing memory pressure on that specific executor. Ganglia (available on older runtimes) provides node-level OS metrics like heap usage over time, which can confirm whether memory pressure is sustained or spiky.
These built-in tools give a complete picture of the root cause before making any configuration changes.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/monitor-cluster
NEW QUESTION # 53
......
If you follow the steps of our DP-750 exam questions, you can easily and happily learn and ultimately succeed in the ocean of learning. And our DP-750 exam questions can help you pass the DP-750 exam for sure. Choosing our DP-750 exam questions actually means that you will have more opportunities to be promoted in the near future. We are confident that in the future, our DP-750 Study Tool will be more attractive and the pass rate will be further enhanced. For now, the high pass rate of our DP-750 exam questions is more than 98%.
DP-750 Latest Exam Experience: https://www.practicetorrent.com/DP-750-practice-exam-torrent.html
2026 Latest PracticeTorrent DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=1W-b8QyjInySOX5AHEBL_hE4YzfM6j2Hw