Certified-Data-Engineer-Professional Real Dump & Exam Certified-Data-Engineer-Professional Passing Score

With Certified-Data-Engineer-Professional guide torrent, you may only need to spend half of your time that you will need if you didn’t use our products successfully passing a professional qualification exam. In this way, you will have more time to travel, go to parties and even prepare for another exam. The benefits of Certified-Data-Engineer-Professional Study Guide for you are far from being measured by money. Certified-Data-Engineer-Professional guide torrent has a first-rate team of experts, advanced learning concepts and a complete learning model. You give us a trust and we reward you for a better future.
| Section | Objectives |
|---|
| Topic 1: Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Understand Liquid Clustering versus partitioning and Z-Ordering
- 2. Design and implement scalable data models using Delta Lake
- 3. Optimize data layout using Liquid Clustering
|
| Topic 2: Monitoring and Alerting | - Monitoring
- 1. Use system tables for resource, cost, audit, and workload monitoring
- 2. Use Query Profiler and Spark UI to monitor workloads
- 3. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 4. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
|
| Topic 3: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Use control flow operators in pipeline components
- 2. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 3. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 4. Configure environments, dependencies, memory, and retry behavior
- 5. Compare streaming tables and materialized views
- 6. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 7. Develop unit and integration tests for data processing code
- 8. Use APPLY CHANGES APIs for change data capture
- Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Develop User-Defined Functions using Pandas/Python UDFs
|
| Topic 4: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
|
| Topic 5: Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Topic 6: Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Use Change Data Feed to address streaming table limitations and improve latency
- 3. Understand deletion vectors and liquid clustering
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
|
| Topic 7: Data Sharing and Federation | - Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Configure Databricks-to-Databricks Sharing
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Topic 8: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest data from message buses and cloud storage
|
| Topic 9: Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Use row filters and column masks for sensitive data
|
| Topic 10: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 2. Analyze errors and remediate failed job runs
- 3. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
|
>> Certified-Data-Engineer-Professional Real Dump <<
Exam Certified-Data-Engineer-Professional Passing Score, Certified-Data-Engineer-Professional Exam Assessment
We have thousands of satisfied customers around the globe so you can freely join your journey for the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) certification exam with us. Prep4sures also guarantees that it will provide your money back if in any case, you are unable to pass the Databricks Certified-Data-Engineer-Professional Exam but the terms and conditions are there that you must have to follow.
Databricks Certified Data Engineer Professional Sample Questions (Q197-Q202):
NEW QUESTION # 197
A data engineer is brining an existing production Databricks job under asset bundle management and wants to ensure that:
- The job's current configuration is captured as YAML, and all
referenced files are included in their bundle project.
- Future changes to the bundle's YAML will update the existing job in-
place (not create a new job)
How should the data engineer successfully move the production job under asset bundle management?
- A. Manually create the YAML configuration for the job in your bundle project, ensuring all settings match the existing job. Then, run Databricks bundle deploy the bundle, which will update the existing job in your workspace.
- B. Export the job definition as JSON, convert it to YAML, and place it in your bundle. Then, run Databricks bundle deploy to update the existing job.
- C. Run Databricks bundle generate job --existing-job-id to generate the YAML and download referenced files. Then, run Databricks bundle deploy to deploy the bundle, which will always update the existing job automatically.
- D. Run databricks bundle generate job --existing-job-id to generate the YAML and download referenced files. Then, run Databricks bundle deployment, bind to link the bundle's job resource to the existing job in Databricks.
Answer: D
Explanation:
Generating the bundle from the existing job captures the full job configuration as YAML and pulls in all referenced files into the bundle project. Binding the generated job resource to the existing Databricks job establishes a persistent link, ensuring that future bundle deployments update the same production job in place rather than creating a new one.
NEW QUESTION # 198
A data engineer is configuring a pipeline that will potentially see late-arriving, duplicate records.
In addition to de-duplicating records within the batch, which of the following approaches allows the data engineer to deduplicate data against previously processed records as it is inserted into a Delta table?
- A. VACUUM the Delta table after each batch completes.
- B. Rely on Delta Lake schema enforcement to prevent duplicate records.
- C. Perform an insert-only merge with a matching condition on a unique key.
- D. Set the configuration delta.deduplicate = true.
- E. Perform a full outer join on a unique key and overwrite existing data.
Answer: C
Explanation:
To deduplicate data against previously processed records as it is inserted into a Delta table, you can use the merge operation with an insert-only clause. This allows you to insert new records that do not match any existing records based on a unique key, while ignoring duplicate records that match existing records. For example, you can use the following syntax:
MERGE INTO target_table USING source_table ON target_table.unique_key = source_table.unique_key WHEN NOT MATCHED THEN INSERT * This will insert only the records from the source table that have a unique key that is not present in the target table, and skip the records that have a matching key. This way, you can avoid inserting duplicate records into the Delta table.
NEW QUESTION # 199
A data engineer needs to productionize a new Spark application written by teammate. This application has numerous external dependencies, including libraries, and requires custom environment variables and Spark configuration parameters to be set. Which two methods will help the data engineer accomplish the task? (Choose two.)
- A. Create init scripts on DBFS.
- B. Install libraries on DBFS
- C. Use compute policies to set system properties, environment variables, and Spark configuration parameters.
- D. Use secrets in init scripts to store configuration data
- E. Add libraries to compute policies
Answer: A,C
Explanation:
Compute policies allow centrally defining and enforcing Spark configuration parameters, system properties, and environment variables required by the application, ensuring consistent production settings. Init scripts enable installing external dependencies and performing custom environment setup at cluster startup, making them essential for productionizing Spark applications with complex dependency and configuration requirements.
NEW QUESTION # 200
A data engineer wants to refactor the following DLT code, which includes multiple table definitions with very similar code.
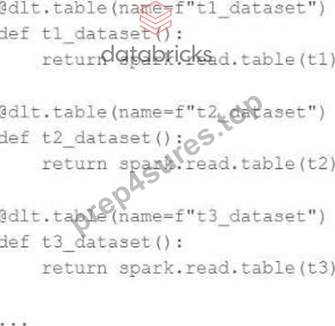
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.
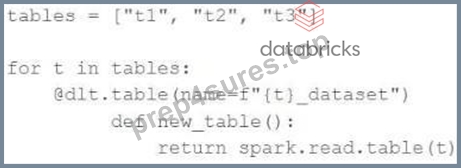
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for these tables.
How can the data engineer fix this?
- A. Load the configuration values for these tables from a separate file, located at a path provided by a pipeline parameter.
- B. Convert the list of configuration values to a dictionary of table settings, using different input the for loop.
- C. Convert the list of configuration values to a dictionary of table settings, using table names as keys.
- D. Wrap the loop inside another table definition, using generalized names and properties to replace with those from the inner table
Answer: C
Explanation:
The issue with the refactored code is that it tries to use string interpolation to dynamically create table names within the dlc.table decorator, which will not correctly interpret the table names.
Instead, by using a dictionary with table names as keys and their configurations as values, the data engineer can iterate over the dictionary items and use the keys (table names) to properly configure the table settings. This way, the decorator can correctly recognize each table name, and the corresponding configuration settings can be applied appropriately.
NEW QUESTION # 201
A data engineer is building a Lakeflow Declarative Pipelines pipeline to process healthcare claims data. A metadata JSON file defines data quality rules for multiple tables, including:
{
"claims": [
{"name": "valid_patient_id", "constraint": "patient_id IS NOT NULL"},
{"name": "non_negative_amount", "constraint": "claim_amount >= 0"}
]
}
The pipeline must dynamically apply these rules to the claims table without hardcoding the rules.
How should the data engineer achieve this?
- A. Invoke an external API to validate records against the metadata rules.
- B. Reference each expectation with @dlt.expect decorators in the table declaration.
- C. Use a SQL CONSTRAINT block referencing the JSON file path.
- D. Load the JSON metadata, loop through its entries, and apply expectations using dlt.expect_all.
Answer: D
Explanation:
Lakeflow Declarative Pipelines provide the expect_all method for programmatically applying multiple data quality expectations at once. The documentation explains that @dlt.expect_all accepts a dictionary of expectation names mapped to SQL constraints, allowing rules to be dynamically loaded from metadata such as JSON files. This ensures that pipelines remain maintainable and scalable without needing to hardcode individual @dlt.expect decorators. The event logs will track each expectation's pass and fail counts individually, making it auditable.
NEW QUESTION # 202
......
Our Certified-Data-Engineer-Professional training braindump is elaborately composed with major questions and answers. We are choosing the key from past materials to finish our Certified-Data-Engineer-Professional guide question. It only takes you 20 hours to 30 hours to do the practice. After your effective practice, you can master the examination point from the Certified-Data-Engineer-Professional Test Question. Then, you will have enough confidence to pass the Certified-Data-Engineer-Professional exam. What are you waiting for? Just come and buy our Certified-Data-Engineer-Professional exam questions!
Exam Certified-Data-Engineer-Professional Passing Score: https://www.prep4sures.top/Certified-Data-Engineer-Professional-exam-dumps-torrent.html
- Pass Guaranteed Quiz 2026 Databricks Trustable Certified-Data-Engineer-Professional Real Dump 🔆 Easily obtain free download of ☀ Certified-Data-Engineer-Professional ️☀️ by searching on ☀ www.prep4sures.top ️☀️ 😢Certified-Data-Engineer-Professional Valid Test Voucher
- Current Certified-Data-Engineer-Professional Exam Content 🥉 Certified-Data-Engineer-Professional Free Dumps 🏃 Certified-Data-Engineer-Professional Braindump Pdf 🏪 Immediately open ▶ www.pdfvce.com ◀ and search for ⮆ Certified-Data-Engineer-Professional ⮄ to obtain a free download 🌇Certified-Data-Engineer-Professional Valid Exam Cram
- Certified-Data-Engineer-Professional Pass4sure ☕ Certified-Data-Engineer-Professional Pass4sure 🏅 Certified-Data-Engineer-Professional Free Dumps 🌕 Easily obtain ➥ Certified-Data-Engineer-Professional 🡄 for free download through { www.practicevce.com } 🙉Certified-Data-Engineer-Professional Valid Exam Cram
- Certified-Data-Engineer-Professional Valid Test Online 📺 Certified-Data-Engineer-Professional Latest Braindumps Free ⚡ Certified-Data-Engineer-Professional Valid Test Online 🐫 Search for ➤ Certified-Data-Engineer-Professional ⮘ and download it for free on ▛ www.pdfvce.com ▟ website 🎷Current Certified-Data-Engineer-Professional Exam Content
- Certified-Data-Engineer-Professional Detailed Study Plan 🦠 Certified-Data-Engineer-Professional Pass4sure ❤ Certified-Data-Engineer-Professional Braindump Pdf 🍆 Open 「 www.practicevce.com 」 and search for “ Certified-Data-Engineer-Professional ” to download exam materials for free 🥏Certified-Data-Engineer-Professional Valid Exam Cram
- Certified-Data-Engineer-Professional Valid Test Online ☎ Certified-Data-Engineer-Professional Formal Test 🍏 New Certified-Data-Engineer-Professional Exam Topics 🆔 Search for ▛ Certified-Data-Engineer-Professional ▟ and download exam materials for free through 【 www.pdfvce.com 】 🏡Online Certified-Data-Engineer-Professional Tests
- Databricks Certified-Data-Engineer-Professional Exam Questions are Real and Recommended By Experts 🌄 ➽ www.vceengine.com 🢪 is best website to obtain “ Certified-Data-Engineer-Professional ” for free download 🏺New Certified-Data-Engineer-Professional Exam Topics
- Unparalleled Certified-Data-Engineer-Professional Real Dump - Win Your Databricks Certificate with Top Score 🍡 Download ➡ Certified-Data-Engineer-Professional ️⬅️ for free by simply searching on ➡ www.pdfvce.com ️⬅️ 🕖Online Certified-Data-Engineer-Professional Tests
- Free 1 year Databricks Certified-Data-Engineer-Professional Dumps Updates: a Full Refund Guarantee By www.practicevce.com 🏊 Search for ☀ Certified-Data-Engineer-Professional ️☀️ and download it for free immediately on “ www.practicevce.com ” 🛐Current Certified-Data-Engineer-Professional Exam Content
- Certified-Data-Engineer-Professional Pass4sure 💏 Certified-Data-Engineer-Professional Latest Braindumps Free 📦 Latest Certified-Data-Engineer-Professional Exam Fee 📴 Search for 【 Certified-Data-Engineer-Professional 】 on ⇛ www.pdfvce.com ⇚ immediately to obtain a free download ↩Online Certified-Data-Engineer-Professional Tests
- 2026 Certified-Data-Engineer-Professional Real Dump | Perfect Databricks Certified Data Engineer Professional 100% Free Exam Passing Score 🌞 Easily obtain free download of 「 Certified-Data-Engineer-Professional 」 by searching on { www.vce4dumps.com } ⏰Latest Certified-Data-Engineer-Professional Exam Fee
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes