Our Certified-Data-Engineer-Professional free demo provides you with the free renewal in one year so that you can keep track of the latest points happening in the world. As the questions of exams of our Certified-Data-Engineer-Professional exam torrent are more or less involved with heated issues and customers who prepare for the exams must haven’t enough time to keep trace of exams all day long, our Certified-Data-Engineer-Professional Practice Test can serve as a conducive tool for you make up for those hot points you have ignored. Therefore, you will have more confidence in passing the exam, which will certainly increase your rate to pass the Certified-Data-Engineer-Professional exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data - Apply advanced Spark transformations |
| Topic 2: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Topic 3: CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines - Deploy with Declarative Automation Bundles, CLI, and REST API |
| Topic 4: Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
| Topic 5: Security and Governance | ~10% | - Implement row-level security, column masking, and compliance - Manage Unity Catalog permissions and ACLs |
| Topic 6: Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables - Diagnose common pipeline and job failures |
| Topic 7: Developing Code for Data Processing using Python and SQL | ~22% | - Manage dependencies, libraries, and UDFs - Implement scalable Python/SQL code and project structures - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader |
| Topic 8: Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines - Apply AUTO CDC APIs and exactly-once semantics |
| Topic 9: Data Modeling | ~10% | - Apply dimensional modeling techniques - Design scalable Delta Lake schemas and clustering |
>> Free Sample Certified-Data-Engineer-Professional Questions <<
Our Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam questions are being offered in three easy-to-use and compatible formats. This Certified-Data-Engineer-Professional exam dumps formats offer a user-friendly interface and are compatible with all devices, operating systems, and browsers. The VerifiedDumps Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) PDF questions file contains real and valid Databricks Certified-Data-Engineer-Professional exam questions that assist you in Certified-Data-Engineer-Professional exam dumps preparation and boost the candidate's confidence to pass the challenging Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam easily.
NEW QUESTION # 191
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block: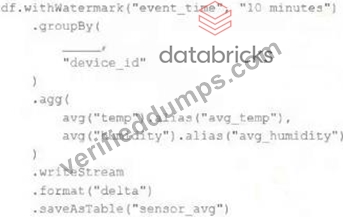
Choose the response that correctly fills in the blank within the code block to complete this task.
Answer: B
Explanation:
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1 second. In this case, the window duration is "5 minutes", which means each window will cover a non-overlapping five- minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window. The alias function is used to rename the struct column as "time".
NEW QUESTION # 192
Which statement regarding spark configuration on the Databricks platform is true?
Answer: B
Explanation:
When Spark configuration properties are set for an interactive cluster using the Clusters UI in Databricks, those configurations are applied at the cluster level. This means that all notebooks attached to that cluster will inherit and be affected by these configurations. This approach ensures consistency across all executions within that cluster, as the Spark configuration properties dictate aspects such as memory allocation, number of executors, and other vital execution parameters. This centralized configuration management helps maintain standardized execution environments across different notebooks, aiding in debugging and performance optimization.
NEW QUESTION # 193
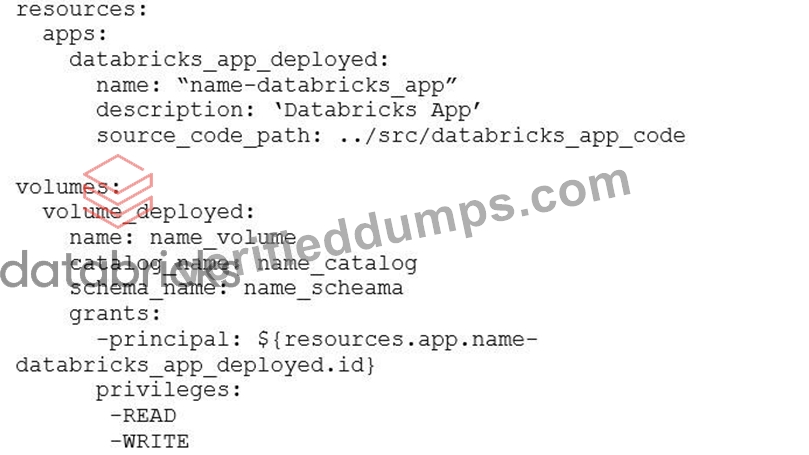
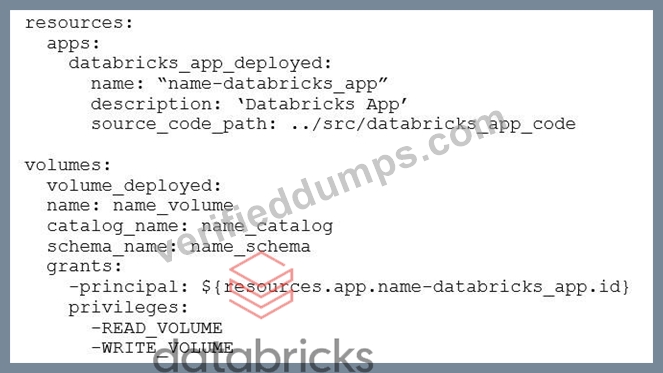
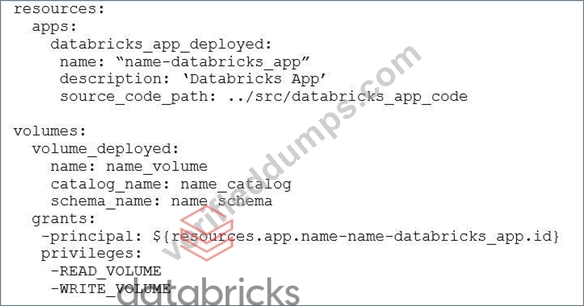
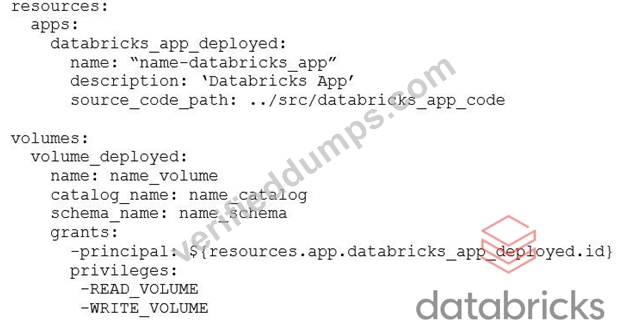
In a Databricks Asset Bundle project, in the file resources/app.yml, the data engineer would like to deploy a Databricks Apps databricks_app_deployed and Volume volume_deployed and grant the Service Principal behind Databricks Apps permissions to READ and WRITE to the Volume.
How should the data engineer achieve the deployment?
Answer: D
Explanation:
This configuration correctly references the service principal created for the Databricks App using the deployed app resource identifier, and it grants the required READ and WRITE privileges at the Volume level. The privileges are specified using the correct Volume-specific permissions, ensuring the Databricks App can securely access the Volume after deployment.
NEW QUESTION # 194
A data engineer needs to design an efficient pipeline that automatically processes new CSV files as they arrive in S3 storage. Which Databricks feature should the data engineer use to meet these requirements?
Answer: C
Explanation:
Auto Loader is designed to efficiently and incrementally process new files as they arrive in cloud object storage. It provides scalable file discovery, supports schema inference and evolution, and minimizes overhead compared to traditional batch or manual streaming approaches.
NEW QUESTION # 195
The data engineer team is configuring environment for development testing, and production before beginning migration on a new data pipeline. The team requires extensive testing on both the code and data resulting from code execution, and the team want to develop and test against similar production data as possible.
A junior data engineer suggests that production data can be mounted to the development testing environments, allowing pre production code to execute against production data. Because all users have Admin privileges in the development environment, the junior data engineer has offered to configure permissions and mount this data for the team.
Which statement captures best practices for this situation?
Answer: A
Explanation:
The best practice in such scenarios is to ensure that production data is handled securely and with proper access controls. By granting only read access to production data in development and testing environments, it mitigates the risk of unintended data modification. Additionally, maintaining isolated databases for different environments helps to avoid accidental impacts on production data and systems.
NEW QUESTION # 196
......
One of the biggest challenges of preparing for a Databricks Certified-Data-Engineer-Professional certification exam is staying motivated. It is easy to get bogged down by all the material you need to learn and lose sight of your goal. That is why our Databricks Certified-Data-Engineer-Professional PDF and practice tests are designed to be engaging and easy to understand.
100% Certified-Data-Engineer-Professional Exam Coverage: https://www.verifieddumps.com/Certified-Data-Engineer-Professional-valid-exam-braindumps.html