We cannot overlook the importance of efficiency because we live in a society emphasize on it. So to get our latest Databricks-Certified-Professional-Data-Engineer exam torrent, just enter the purchasing website, and select your favorite version with convenient payment and you can download our latest Databricks-Certified-Professional-Data-Engineer exam torrent immediately within 5 minutes. This way you can avoid the problems in waiting for arrival of products and you can learn about the knowledge of Databricks-Certified-Professional-Data-Engineer Quiz guides in a short time. Latest Databricks-Certified-Professional-Data-Engineer exam torrent can vividly embody the spirits and effort we have put into them. And the power of our Databricks-Certified-Professional-Data-Engineer test prep permit you to apprehend the essence of the exam. All elites in this area vindicate the accuracy and efficiency of our Databricks-Certified-Professional-Data-Engineer quiz guides.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Certificate Validity Period: | 2 years |
| Passing Score: | 70% |
| Exam Format: | Multiple choice, Scenario-based questions, Multiple select |
| Related Certifications: | Databricks Certified Data Engineer Associate |
| Exam Price: | USD 200 |
| Real Exam Qty: | 60-70 |
| Available Languages: | English |
| Exam Duration: | 120 minutes |
| Recommended Training: | Databricks Academy |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored exam |
| Pre Condition: | Recommended: Databricks Certified Data Engineer Associate or equivalent experience with Spark and Databricks platform. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
>> Databricks-Certified-Professional-Data-Engineer Free Exam <<
However, when asked whether the Databricks-Certified-Professional-Data-Engineer latest dumps are reliable, costumers may be confused. For us, we strongly recommend the Databricks-Certified-Professional-Data-Engineer exam questions compiled by our company, here goes the reason. On one hand, our Databricks-Certified-Professional-Data-Engineer test material owns the best quality. When it comes to the study materials selling in the market, qualities are patchy. But our Databricks test material has been recognized by multitude of customers, which possess of the top-class quality, can help you pass exam successfully. On the other hand, our Databricks-Certified-Professional-Data-Engineer Latest Dumps are designed by the most experienced experts, thus it can not only teach you knowledge, but also show you the method of learning in the most brief and efficient ways.
Databricks Certified Professional Data Engineer exam consists of multiple-choice questions and is conducted online. Databricks-Certified-Professional-Data-Engineer exam is intended to measure the candidate's proficiency in various areas, such as Spark architecture, Spark programming, data processing, data analysis, and data modeling. Databricks-Certified-Professional-Data-Engineer Exam also tests the candidate's ability to optimize Spark performance and troubleshoot Spark applications. It is recommended that individuals who plan to take Databricks-Certified-Professional-Data-Engineer exam have at least two years of hands-on experience in big data technologies and Apache Spark.
NEW QUESTION # 50
The business reporting team requires that data for their dashboards be updated every hour. The total processing time for the pipeline that extracts, transforms, and loads the data for their pipeline runs in 10 minutes. Assuming normal operating conditions, which configuration will meet their service-level agreement requirements with the lowest cost?
Answer: B
Explanation:
* Exact extract: "Job clusters are created for a job run and terminate when the job completes." References: Cluster types (job vs all-purpose); Databricks Jobs scheduling.
NEW QUESTION # 51
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schem a. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below: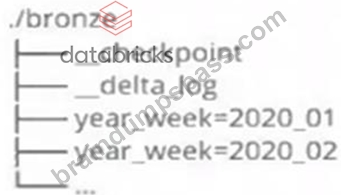
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
Answer: B
Explanation:
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss. Verified Reference: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "Checkpointing" section.
NEW QUESTION # 52
A data engineer needs to provide access to a group named manufacturing-team. The team needs privileges to create tables in the quality schema.
Which set of SQL commands will grant a group named manufacturing-team to create tables in a schema named production with the parent catalog named manufacturing with the least privileges?
Answer: C
Explanation:
To create a table within a schema, a principal must have CREATE TABLE on the schema, USE SCHEMA on that schema, and USE CATALOG on the parent catalog. This combination ensures the group has just enough privileges to create objects in that schema without excessive permissions like CREATE SCHEMA or CREATE CATALOG.
Reference Source: Databricks Unity Catalog Privilege Model - "Privileges Required to Create a Table."
NEW QUESTION # 53
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below:
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
Answer: B
Explanation:
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss. Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation , under "Checkpointing" section.
NEW QUESTION # 54
To identify the top users consuming compute resources, a data engineering team needs to monitor usage within their Databricks workspace for better resource utilization and cost control. The team decided to use Databricks system tables, available under the System catalog in Unity Catalog, to gain detailed visibility into workspace activity.
Which SQL query should the team run from the System catalog to achieve this?
A)
SELECT sku_name,
identity_metadata.created_by AS user_email,
COUNT(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10
B)
SELECT identity_metadata.run_as AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email
ORDER BY total_dbus DESC
LIMIT 10
C)
SELECT sku_name,
identity_metadata.created_by AS user_email,
SUM(usage_quantity * usage_unit) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10
D)
SELECT sku_name,
usage_metadata.run_name AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The system.billing.usage table in the Unity Catalog System schema provides detailed usage metrics for each workload in the workspace. The field identity_metadata.run_as identifies the user or service principal under which the job or query executed. Summing usage_quantity provides total DBU (Databricks Unit) consumption per user. According to Databricks documentation, this table is the authoritative source for monitoring workspace cost drivers, showing compute SKU, user, and DBU consumption over time. Grouping by identity_metadata.run_as and summing usage_quantity produces the correct aggregation to determine top users. Other queries use non-existent or incorrect fields (created_by, run_name, or multiplied usage quantities), which do not reflect actual billing metrics.
NEW QUESTION # 55
......
Exam Databricks-Certified-Professional-Data-Engineer Cram: https://www.braindumpspass.com/Databricks/Databricks-Certified-Professional-Data-Engineer-practice-exam-dumps.html