現在の仕事にまだ満足していますか?あなたはまだあなたの仕事にうまく対処する能力を持っていますか?同じ分野で働いている人々と比較したときに、競争上の優位性があるかどうかを考えますか?あなたの答えがいいえなら、あなたは今正しい場所です。私たちのAI-300試験トレントはあなたの良いパートナーであり、あなたは満足していない仕事を変更する機会があり、私たちのAI-300ガイド質問であなたの能力を高めることができるので、あなたはAI-300試験に合格します目標を達成します。 AI-300試験問題のデモを無料でダウンロードしてください!
| Section | Weight | Objectives |
|---|---|---|
| Implement machine learning model lifecycle and operations | 25–30% | - Register, version, and package models
|
| Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
| Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
近年、IT技術の急速な発展に伴って、IT技術を勉強し始める人がますます多くなっています。そこで、IT業界で働く人も多くなっています。このように、IT業界の競争が一層激しくなります。同様にIT業界で働いていて、IT夢を持っているあなたは、きっと他の人にキャッチアップされ、追い抜かれることを望まないでしょう。それでは、ずっと自分自身のスキルをアップグレードすることが必要になり、他の人に自分の強さを証明する必要があります。では、どうやって自分の能力を証明するのですか。多くの人々はIT認定試験を受験して認証資格を取ることを通して彼らの強さを証明します。あなたもIT認証資格を取りたいですか。まずMicrosoftのAI-300認定試験に合格しましょう。これはMicrosoftの最も重要な試験の一つで、業界全体に認証された資格です。
質問 # 114
A team is deploying machine learning models to a production inference endpoint in Azure Machine Learning.
The team requires a safe way to validate a new model version without disrupting existing users.
You need to recommend a deployment strategy for controlled testing of a new model version.
What should you configure?
正解:D
解説:
The best strategy for controlled testing of a new model version in Azure Machine Learning is Blue-Green Deployment, often referred to as a safe rollout.
This approach allows you to deploy a new model version alongside the current one within the same Managed Online Endpoint without disrupting existing users.
Key Features of Blue-Green Deployment in Azure ML
Simultaneous Versions: Both the current "Blue" and new "Green" models run concurrently on the same endpoint.
*-> Traffic Shifting: You can use the endpoint's load balancer to allocate a specific percentage (e.g., 10%) of live production traffic to the new version.
Mirrored Traffic: For even lower risk, you can test the new model with mirrored traffic, where production requests are copied to the new model for validation without using its responses for the end user.
Instant Rollback: If the new model performs poorly, you can instantly shift 100% of traffic back to the original version.
Deployment Headers: You can bypass general traffic splitting to test the "Green" deployment specifically by adding an azureml-model-deployment header to your HTTP requests.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-safely-rollout-online-endpoints
質問 # 115
A team deploys a machine learning model to a managed online endpoint. The team monitors model performance and data quality metrics in production.
When monitoring thresholds are exceeded, the team requires an automated operational response that notifies downstream systems.
You need to configure the monitoring solution to meet the requirements.
Which configuration should you associate with each requirement as a first step? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content . NOTE: Each correct selection is worth one point.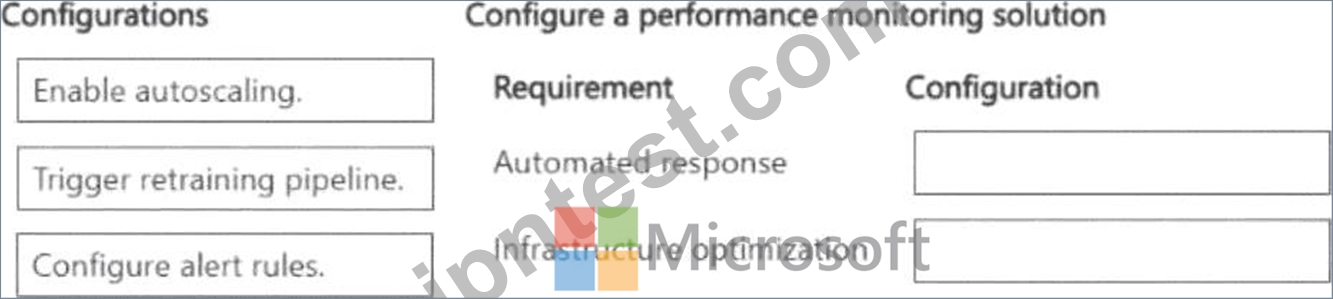
正解:
解説: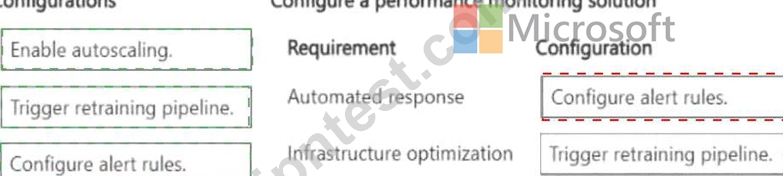
Explanation:
Microsoft ' s documentation on Azure Machine Learning model monitoring describes a layered alerting architecture. At the base layer, Azure ML model monitors compute drift, prediction, and data quality metrics on a scheduled basis and publish results as Azure Monitor metrics. To notify stakeholders, you create an Azure Monitor alert rule that watches these metrics and fires an action group when a threshold is breached.
Action groups support email, SMS, push notifications, and webhook calls. To initiate automated retraining, the webhook call in the action group targets an Azure ML pipeline ' s REST endpoint, triggering a retraining run. Alternatively, Azure Event Grid subscriptions on AML workspace events can route model-quality events to Azure Functions that start pipelines. The separation of monitoring, alerting, notification, and remediation is intentional, allowing each component to be updated independently.
Microsoft Learn Reference Topic: Set up model monitoring for data and model quality - Azure Machine Learning model monitoring
質問 # 116
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
An organization provisions Azure Machine Learning workspaces for development, test, and production environments.
Each environment must be deployed consistently and updated through source control. The deployment process must be automated, repeatable, and auditable.
You need to deploy Azure Machine Learning resources in a consistent and controlled manner.
Solution: Define Azure Machine Learning resources in a Bicep template and deploy them within a GitHub Action.
Does the solution meet the goal?
正解:A
解説:
Correct:
* Define Azure Machine Learning resources in a Bicep template and deploy them within a GitHub Action.
This action is best because it fulfills all of your operational requirements:
Consistency & Controlled Manner:
Infrastructure as Code (IaC) via Bicep ensures that dev, test, and prod environments are configured identically, eliminating configuration drift.
Source Control: Storing the Bicep template in a Git repository satisfies the requirement that each environment must be updated through source control.
Automated & Repeatable: Orchestrating the deployment using GitHub Actions fully automates the workflow, allowing it to be executed reliably every time a change is merged.
Auditable: Git commit histories combined with GitHub deployment logs provide a comprehensive, compliant audit trail of exactly who modified the infrastructure and when.
Incorrect:
* Clone an existing Azure Machine Learning workspace to create additional environments.
* Create Azure Machine Learning workspaces manually in the Azure portal for each environment.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-github-actions-machine-learning
質問 # 117
An Azure Machine Learning workspace contains multiple registered versions of a model that is used in production.
An older model version must no longer be deployable, but it must remain available for compliance review and potential rollback.
You need to change the state of the model version to meet the requirements.
What should you do?
正解:C
質問 # 118
You are training machine learning models in Azure Machine Learning. You use Hyperdrive to tune the hyperparameters.
In previous model training and tuning runs, many models showed similar performance.
You need to select an early termination policy that meets the following requirements:
* Accounts for the performance of all previous runs when evaluating the current run.
* Avoids comparing the current run with only the best performing run to date.
Which two early termination policies should you use? Each correct answer presents part of the solution.
正解:A、C
解説:
Median stopping and Truncation selection both evaluate a run relative to the broader population of training runs rather than comparing it only against the single best run.
The Median Stopping Policy calculates running averages of the primary metric across all runs . At an evaluation interval, a run can be terminated when its best primary-metric performance is worse than the median of the running averages across the population. Microsoft explicitly defines this policy as being based on running averages of the primary metric of all runs.
The Truncation Selection Policy periodically ranks runs by their primary metric and terminates a configured percentage of the lowest-performing runs . For example, a 20-percent truncation policy terminates runs falling within the lowest 20 percent at the applicable evaluation interval. It therefore compares each candidate with the population of comparable runs rather than only the current leader.
Bandit is specifically unsuitable because it uses an allowable slack relative to the best-performing run , which directly violates the requirement. The Default behavior applies no early termination policy and allows runs to execute to completion.
Study Guide Reference: Implement machine learning model lifecycle and operations - automated hyperparameter tuning, early termination policies, Median Stopping Policy, Truncation Selection Policy, and efficient experiment execution.
質問 # 119
......
弊社のMicrosoft AI-300問題集を使用した後、AI-300試験に合格するのはあまりに難しくないことだと知られます。我々JPNTest提供するAI-300問題集を通して、試験に迅速的にパースする技をファンドできます。あなたのご遠慮なく購買するために、弊社は提供する無料のMicrosoft AI-300問題集デーモをダウンロードします。
AI-300科目対策: https://www.jpntest.com/shiken/AI-300-mondaishu