Certified-Data-Engineer-Professional Pass-Sure Torrent - Certified-Data-Engineer-Professional Actual Braindumps & Certified-Data-Engineer-Professional Test Cram

By unremitting effort and studious research of the Certified-Data-Engineer-Professional practice materials, they devised our high quality and high effective Certified-Data-Engineer-Professional practice materials which win consensus acceptance around the world. They are meritorious experts with a professional background in this line and remain unpretentious attitude towards our Certified-Data-Engineer-Professional practice materials all the time. They are unsuspecting experts who you can count on.
| Section | Objectives |
|---|
| Topic 1: Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Topic 2: Debugging and Deploying | - Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
|
| Topic 3: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Compare streaming tables and materialized views
- 2. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 3. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 4. Configure environments, dependencies, memory, and retry behavior
- 5. Use control flow operators in pipeline components
- 6. Develop unit and integration tests for data processing code
- 7. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 8. Use APPLY CHANGES APIs for change data capture
- Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Develop User-Defined Functions using Pandas/Python UDFs
|
| Topic 4: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Topic 5: Ensuring Data Security and Compliance | - Data Security
- 1. Use ACLs to secure workspace objects and enforce least privilege
- 2. Apply anonymization and pseudonymization techniques
- 3. Use row filters and column masks for sensitive data
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Topic 6: Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Understand deletion vectors and liquid clustering
- 3. Apply data skipping and file pruning techniques
|
| Topic 7: Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
- Monitoring
- 1. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 2. Use system tables for resource, cost, audit, and workload monitoring
- 3. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 4. Use Query Profiler and Spark UI to monitor workloads
|
| Topic 8: Data Sharing and Federation | - Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Configure Databricks-to-Databricks Sharing
- 3. Share live Lakehouse data with external computing platforms
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Topic 9: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest data from message buses and cloud storage
|
| Topic 10: Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Optimize data layout using Liquid Clustering
|
>> Free Certified-Data-Engineer-Professional Study Material <<
Pass Guaranteed Quiz Databricks - Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Newest Free Study Material
Do you want to pass your exam by using the least time? Certified-Data-Engineer-Professional exam braindumps of us can do that for you. With skilled professionals to compile and verify, Certified-Data-Engineer-Professional exam dumps of us is high quality and accuracy. You just need to spend 48 to 72 hours on practicing, and you can pass your exam. We are pass guaranteed and money back guaranteed. If you fail to pass the exam, we will give you full refund. Besides, we offer you free demo to have a try before buying Certified-Data-Engineer-Professional Exam Dumps. We also have free update for one year after purchasing.
Databricks Certified Data Engineer Professional Sample Questions (Q32-Q37):
NEW QUESTION # 32
A data engineer is troubleshooting a slow-running Delta Lake query on Databricks SQL involves complex joins and large datasets. They need to identify whether the root cause is related to poor data skipping, inefficient join strategies, or excessive data shuffling. Which approach should identify the specific bottlenecks using native Databricks tools?
- A. Use the LIMIT clause to run a subset of the query and compare execution times with the full dataset.
- B. Check the query's execution time in the Jobs UI and correlate it with cluster resource utilization metrics.
- C. Enable the EXPLAIN command to review the parsed logical plan and manually estimate shuffle sizes.
- D. Analyze the Top Operators panel in the Query Profile to identify high-cost operations like BroadcastNestedLoopJoin
Answer: D
Explanation:
The Query Profile's Top Operators panel surfaces the most expensive operators in the query execution, making it possible to directly identify bottlenecks such as inefficient join strategies, poor data skipping, or excessive shuffling. This native visualization highlights where time and resources are spent, enabling precise root-cause analysis for slow-running queries.
NEW QUESTION # 33
A CHECK constraint has been successfully added to the Delta table named activity_details using the following logic:
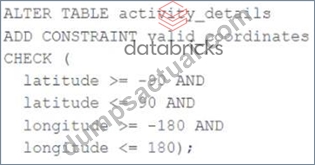
A batch job is attempting to insert new records to the table, including a record where latitude =
45.50 and longitude = 212.67.
Which statement describes the outcome of this batch insert?
- A. The write will insert all records except those that violate the table constraints; the violating records will be recorded to a quarantine table.
- B. The write will insert all records except those that violate the table constraints; the violating records will be reported in a warning log.
- C. The write will fail when the violating record is reached; any records previously processed will be recorded to the target table.
- D. The write will include all records in the target table; any violations will be indicated in the boolean column named valid_coordinates.
- E. The write will fail completely because of the constraint violation and no records will be inserted into the target table.
Answer: E
Explanation:
The CHECK constraint is used to ensure that the data inserted into the table meets the specified conditions. In this case, the CHECK constraint is used to ensure that the latitude and longitude values are within the specified range. If the data does not meet the specified conditions, the write operation will fail completely and no records will be inserted into the target table. This is because Delta Lake supports ACID transactions, which means that either all the data is written or none of it is written. Therefore, the batch insert will fail when it encounters a record that violates the constraint, and the target table will not be updated.
NEW QUESTION # 34
A junior data engineer seeks to leverage Delta Lake's Change Data Feed functionality to create a Type 1 table representing all of the values that have ever been valid for all rows in a bronze table created with the property delta.enableChangeDataFeed = true. They plan to execute the following code as a daily job:
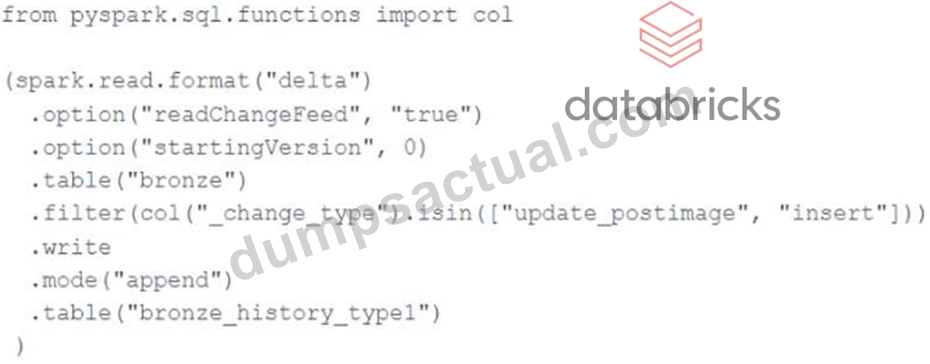
Which statement describes the execution and results of running the above query multiple times?
- A. Each time the job is executed, the entire available history of inserted or updated records will be appended to the target table, resulting in many duplicate entries.
- B. Each time the job is executed, only those records that have been inserted or updated since the last execution will be appended to the target table giving the desired result.
- C. Each time the job is executed, the differences between the original and current versions are calculated; this may result in duplicate entries for some records.
- D. Each time the job is executed, newly updated records will be merged into the target table, overwriting previous values with the same primary keys.
- E. Each time the job is executed, the target table will be overwritten using the entire history of inserted or updated records, giving the desired result.
Answer: A
Explanation:
Reading table's changes, captured by CDF, using spark.read means that you are reading them as a static source. So, each time you run the query, all table's changes (starting from the specified startingVersion) will be read.
NEW QUESTION # 35
A data engineer created a daily batch ingestion pipeline using a cluster with the latest DBR version to store banking transaction data, and persisted it in a MANAGED DELTA table called prod.gold.all_banking_transactions_daily. The data engineer is constantly receiving complaints from business users who query this table ad hoc through a SQL Serverless Warehouse about poor query performance. Upon analysis, the data engineer identified that these users frequently use high- cardinality columns as filters. The engineer now seeks to implement a data layout optimization technique that is incremental, easy to maintain, and can evolve over time. Which command should the data engineer implement?
- A. Alter the table to use Liquid Clustering and implement a periodic OPTIMIZE command.
- B. Alter the table to use Hive-Style Partitions and implement a periodic OPTIMIZE command.
- C. Alter the table to use Z-ORDER and implement a periodic OPTIMIZE command.
- D. Alter the table to use Hive-Style Partitions + Z-ORDER and implement a periodic OPTIMIZE command.
Answer: A
Explanation:
Databricks recommends Liquid Clustering for optimizing data layout in large Delta tables where query filters involve high-cardinality columns. Liquid Clustering automatically manages file organization and supports incremental maintenance without the need to rewrite data when clustering keys evolve. This is a key advantage over static partitioning or Z-ordering, which require costly file rewrites whenever optimization keys change. By combining Liquid Clustering with a periodic OPTIMIZE command, Databricks automatically compacts small files and maintains efficient data skipping performance. As stated in the Delta Lake optimization guide, Liquid Clustering is designed for scalability, minimal maintenance, and adaptability for analytical workloads with evolving query patterns--making B the correct answer.
NEW QUESTION # 36
A data engineering team is setting up deployment automation. To deploy workspace assets remotely using the Databricks CLI command, they must configure it with proper authentication.
Which authentication approach will provide the highest level of security?
- A. Use a shared user account and its OAuth client secret.
- B. Use a service principal with OAuth token federation.
- C. Use a service principal ID and its OAuth client secret.
- D. Use a service principal and its Personal Access Token.
Answer: B
Explanation:
The most secure and enterprise-recommended authentication method for Databricks automation is OAuth token federation with service principals.
This configuration allows service principals (non-human identities) to authenticate using temporary OAuth access tokens from a trusted identity provider (such as Azure AD or AWS IAM federation). These tokens are short-lived and scoped, significantly reducing credential exposure risks.
By contrast, static client secrets (B) or PATs (C) are long-lived and require periodic manual rotation, increasing security vulnerability. Shared user accounts (D) violate least-privilege and auditability principles. Therefore, A provides the strongest, most compliant authentication model for automated CLI and CI/CD workflows.
NEW QUESTION # 37
......
Before you choose to end your practices of the Certified-Data-Engineer-Professional study materials, the screen will display the questions you have done, which help you check again to ensure all questions of Certified-Data-Engineer-Professional practice prep are well finished. The report includes your scores of the Certified-Data-Engineer-Professional learning guide. Also, it will display how many questions of the Certified-Data-Engineer-Professional exam questions you do correctly and mistakenly. In a word, you can compensate for your weakness and change a correct review plan of the study materials.
Certified-Data-Engineer-Professional Exam Actual Tests: https://www.dumpsactual.com/Certified-Data-Engineer-Professional-actualtests-dumps.html
- Certified-Data-Engineer-Professional Valid Exam Cost 🏔 Certified-Data-Engineer-Professional Exam Labs 🔯 Certified-Data-Engineer-Professional New Braindumps Free 🔍 Copy URL [ www.troytecdumps.com ] open and search for 「 Certified-Data-Engineer-Professional 」 to download for free 🐹Certified-Data-Engineer-Professional Exams Training
- Marvelous Free Certified-Data-Engineer-Professional Study Material – Pass Certified-Data-Engineer-Professional First Attempt 📙 Copy URL ✔ www.pdfvce.com ️✔️ open and search for ⏩ Certified-Data-Engineer-Professional ⏪ to download for free 🟣Certified-Data-Engineer-Professional Exam Labs
- Free Certified-Data-Engineer-Professional Study Material Exam Instant Download | Updated Certified-Data-Engineer-Professional Exam Actual Tests 📁 Go to website ▶ www.dumpsquestion.com ◀ open and search for ▷ Certified-Data-Engineer-Professional ◁ to download for free ⚓Certified-Data-Engineer-Professional Flexible Learning Mode
- Perfect 100% Free Certified-Data-Engineer-Professional – 100% Free Free Study Material | Certified-Data-Engineer-Professional Exam Actual Tests 🦨 Search for [ Certified-Data-Engineer-Professional ] and download exam materials for free through ➤ www.pdfvce.com ⮘ 🔼New Certified-Data-Engineer-Professional Dumps Questions
- Valid Certified-Data-Engineer-Professional Exam Question 🍝 Certified-Data-Engineer-Professional Practice Test 🚡 New Certified-Data-Engineer-Professional Exam Format ❗ Search for ⏩ Certified-Data-Engineer-Professional ⏪ on ✔ www.prep4sures.top ️✔️ immediately to obtain a free download 🐙Certified-Data-Engineer-Professional Test Registration
- Certified-Data-Engineer-Professional Valid Test Simulator 🍚 New Certified-Data-Engineer-Professional Dumps Questions ⏲ New Certified-Data-Engineer-Professional Test Sample 🏺 Search for ⏩ Certified-Data-Engineer-Professional ⏪ and download it for free on “ www.pdfvce.com ” website 🍄New Certified-Data-Engineer-Professional Exam Format
- 100% Pass Quiz Reliable Databricks - Free Certified-Data-Engineer-Professional Study Material 🌄 Search for ⏩ Certified-Data-Engineer-Professional ⏪ and easily obtain a free download on ✔ www.troytecdumps.com ️✔️ 💔Certified-Data-Engineer-Professional Test Registration
- Certified-Data-Engineer-Professional Valid Test Simulator 🥝 Certified-Data-Engineer-Professional Flexible Learning Mode 🔑 Certified-Data-Engineer-Professional Flexible Learning Mode 😥 Immediately open [ www.pdfvce.com ] and search for ➤ Certified-Data-Engineer-Professional ⮘ to obtain a free download ⏺Certified-Data-Engineer-Professional Valid Exam Cost
- 100% Pass Quiz Reliable Databricks - Free Certified-Data-Engineer-Professional Study Material 🥽 Search on ( www.troytecdumps.com ) for ➽ Certified-Data-Engineer-Professional 🢪 to obtain exam materials for free download 📔Customizable Certified-Data-Engineer-Professional Exam Mode
- Certified-Data-Engineer-Professional Exam Labs 🥑 Certified-Data-Engineer-Professional Exam Labs 🎯 New Certified-Data-Engineer-Professional Test Sample 💒 Go to website { www.pdfvce.com } open and search for ➽ Certified-Data-Engineer-Professional 🢪 to download for free 👗Certified-Data-Engineer-Professional Exam Labs
- Try www.pdfdumps.com Databricks Certified-Data-Engineer-Professional Practice Test Software 🍇 Easily obtain free download of ➽ Certified-Data-Engineer-Professional 🢪 by searching on ☀ www.pdfdumps.com ️☀️ 🍞Certified-Data-Engineer-Professional Flexible Learning Mode
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, justpaste.me, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes