Pdf Certified-Data-Engineer-Professional Files, Practice Certified-Data-Engineer-Professional Exam

The free demos do honor to the perfection of our latest Certified-Data-Engineer-Professional exam torrent, and also a performance of our considerate after sales services. Those demos serve as epitomes of real Certified-Data-Engineer-Professional quiz guides for your reference. In our demos, some examples or question points were enumerated as some representatives of our Certified-Data-Engineer-Professional Test Prep. How convenient and awesome of it! By the free trial services you can get close realization with our Certified-Data-Engineer-Professional quiz guides, and know how to choose the perfect versions before your purchase.
| Section | Objectives |
|---|
| Topic 1: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Topic 2: Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Query Profile and Spark UI to monitor workloads
- Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
|
| Topic 3: Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Use row filters and column masks to protect sensitive table data
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
|
| Topic 4: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Topic 5: Data Modeling | - Design and optimize data models
- 1. Design dimensional models for analytical workloads with efficient querying and aggregation
- 2. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 3. Simplify data layout decisions and optimize query performance using liquid clustering
- 4. Design and implement scalable data models using Delta Lake to manage large datasets
|
| Topic 6: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 2. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 3. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 4. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 5. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 6. Create pipeline components using control flow operators such as if/else and foreach
- 7. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 8. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
|
| Topic 7: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 2. Apply Change Data Feed to address streaming table limitations and improve latency
- 3. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 4. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
| Topic 8: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
|
| Topic 9: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 10: Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
>> Pdf Certified-Data-Engineer-Professional Files <<
Practice Certified-Data-Engineer-Professional Exam & Certified-Data-Engineer-Professional Study Plan
TestPassed deeply hope our Certified-Data-Engineer-Professional study materials can bring benefits and profits for our customers. So we have been persisting in updating our Certified-Data-Engineer-Professional test torrent and trying our best to provide customers with the latest study materials. More importantly, the updating system we provide is free for all customers. If you decide to buy our Certified-Data-Engineer-Professional Study Materials, we can guarantee that you will have the opportunity to use the updating system for free.
Databricks Certified Data Engineer Professional Sample Questions (Q213-Q218):
NEW QUESTION # 213
A developer has successfully configured their credentials for Databricks Repos and cloned a remote Git repository. They do not have privileges to make changes to the main branch, which is the only branch currently visible in their workspace. Which approach allows this user to share their code updates without the risk of overwriting the work of their teammates?
- A. Use Repos to pull changes from the remote Git repository; commit and push changes to a branch that appeared as changes were pulled.
- B. Use Repos to merge all differences and make a pull request back to the remote repository.
- C. Use repos to create a fork of the remote repository commit all changes and make a pull request on the source repository
- D. Use repos to merge all difference and make a pull request back to the remote repository.
- E. Use Repos to create a new branch commit all changes and push changes to the remote Git repertory.
Answer: E
Explanation:
In Databricks Repos, when a user does not have privileges to make changes directly to the main branch of a cloned remote Git repository, the recommended approach is to create a new branch within the Databricks workspace. The developer can then make changes in this new branch, commit those changes, and push the new branch to the remote Git repository. This workflow allows for isolated development without affecting the main branch, enabling the developer to propose changes via a pull request from the new branch to the main branch in the remote repository. This method adheres to common Git collaboration workflows, fostering code review and collaboration while ensuring the integrity of the main branch.
NEW QUESTION # 214
All records from an Apache Kafka producer are being ingested into a single Delta Lake table with the following schema:
key BINARY, value BINARY, topic STRING, partition LONG, offset LONG, timestamp LONG There are 5 unique topics being ingested. Only the "registration" topic contains Personal Identifiable Information (PII). The company wishes to restrict access to PII. The company also wishes to only retain records containing PII in this table for 14 days after initial ingestion.
However, for non-PII information, it would like to retain these records indefinitely.
Which of the following solutions meets the requirements?
- A. Data should be partitioned by the registration field, allowing ACLs and delete statements to be set for the PII directory.
- B. All data should be deleted biweekly; Delta Lake's time travel functionality should be leveraged to maintain a history of non-PII information.
- C. Separate object storage containers should be specified based on the partition field, allowing isolation at the storage level.
- D. Data should be partitioned by the topic field, allowing ACLs and delete statements to leverage partition boundaries.
- E. Because the value field is stored as binary data, this information is not considered PII and no special precautions should be taken.
Answer: D
Explanation:
By default partitionning by a column will create a separate folder for each subset data linked to the partition.
NEW QUESTION # 215
A data engineer wants to enforce the principle of least privilege when configuring ACLs for Databricks jobs in a collaborative workspace. Which approach should the data engineer use?
- A. Grant CAN RUN permission to everyone and CAN MANAGE to a single admin group.
- B. Use only folder-level permissions and avoid setting permissions on individual jobs.
- C. Assign users only the minimum permission level (e.g., CAN RUN or CAN VIEW) required for their role on each job.
- D. Grant all users CAN MANAGE permission on all jobs to avoid access issues.
Answer: C
Explanation:
Assigning the minimum required permission level on each job ensures users can perform only the actions necessary for their role. This directly enforces the principle of least privilege while maintaining secure and controlled access in a collaborative workspace.
NEW QUESTION # 216
The following table consists of items found in user carts within an e-commerce website.
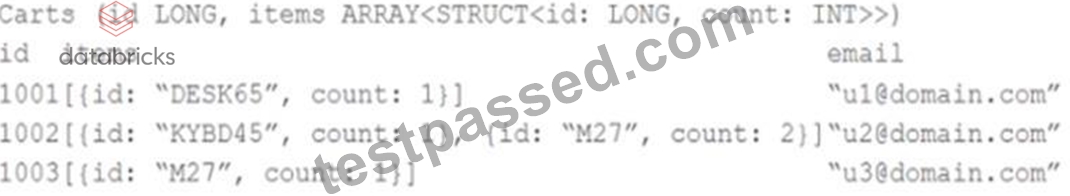
The following MERGE statement is used to update this table using an updates view, with schema evolution enabled on this table.
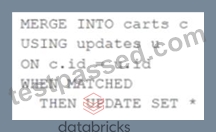
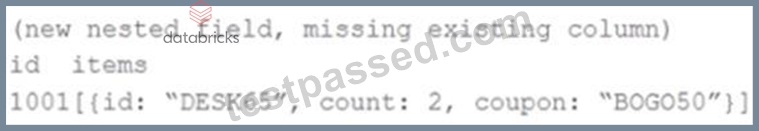
How would the following update be handled?
- A. The update throws an error because changes to existing columns in the target schema are not supported.
- B. The new restored field is added to the target schema, and dynamically read as NULL for existing unmatched records.
- C. The new nested field is added to the target schema, and files underlying existing records are updated to include NULL values for the new field.
- D. The update is moved to separate ''restored'' column because it is missing a column expected in the target schema.
Answer: C
Explanation:
With schema evolution enabled in Databricks Delta tables, when a new field is added to a record through a MERGE operation, Databricks automatically modifies the table schema to include the new field. In existing records where this new field is not present, Databricks will insert NULL values for that field. This ensures that the schema remains consistent across all records in the table, with the new field being present in every record, even if it is NULL for records that did not originally include it.
NEW QUESTION # 217
A user new to Databricks is trying to troubleshoot long execution times for some pipeline logic they are working on. Presently, the user is executing code cell-by-cell, using display() calls to confirm code is producing the logically correct results as new transformations are added to an operation. To get a measure of average time to execute, the user is running each cell multiple times interactively.
Which of the following adjustments will get a more accurate measure of how code is likely to perform in production?
- A. Scala is the only language that can be accurately tested using interactive notebooks; because the best performance is achieved by using Scala code compiled to JARs. all PySpark and Spark SQL logic should be refactored.
- B. The Jobs Ul should be leveraged to occasionally run the notebook as a job and track execution time during incremental code development because Photon can only be enabled on clusters launched for scheduled jobs.
- C. The only way to meaningfully troubleshoot code execution times in development notebooks Is to use production-sized data and production-sized clusters with Run All execution.
- D. Calling display () forces a job to trigger, while many transformations will only add to the logical query plan; because of caching, repeated execution of the same logic does not provide meaningful results.
- E. Production code development should only be done using an IDE; executing code against a local build of open source Spark and Delta Lake will provide the most accurate benchmarks for how code will perform in production.
Answer: C
NEW QUESTION # 218
......
TestPassed will provide exam prep and Databricks Certified-Data-Engineer-Professional Exam Simulations you will need to take a certification examination. About Databricks Certified-Data-Engineer-Professional test, you can find related dumps from different websites or books, however, TestPassed has the advantage of perfect contents, strong logicality and complete supporting facilities. TestPassed original questions and test answers can not only help you to pass an exam, can also save you valuable time.
Practice Certified-Data-Engineer-Professional Exam: https://www.testpassed.com/Certified-Data-Engineer-Professional-still-valid-exam.html
- 100% Pass 2026 High Hit-Rate Databricks Certified-Data-Engineer-Professional: Pdf Databricks Certified Data Engineer Professional Files 🧼 Search on 《 www.prep4sures.top 》 for { Certified-Data-Engineer-Professional } to obtain exam materials for free download 🧷Pdf Certified-Data-Engineer-Professional Exam Dump
- Certified-Data-Engineer-Professional Exam Testking 🦛 Certified-Data-Engineer-Professional Exam Syllabus 🛺 Valid Certified-Data-Engineer-Professional Exam Guide 🚢 Search for 「 Certified-Data-Engineer-Professional 」 on ➡ www.pdfvce.com ️⬅️ immediately to obtain a free download 👡Interactive Certified-Data-Engineer-Professional EBook
- Certification Certified-Data-Engineer-Professional Test Questions 😸 New Certified-Data-Engineer-Professional Braindumps Files 📭 New Certified-Data-Engineer-Professional Braindumps Files 🐃 Open website ☀ www.practicevce.com ️☀️ and search for ( Certified-Data-Engineer-Professional ) for free download 💻Interactive Certified-Data-Engineer-Professional EBook
- Overcome Exam Challenges with Certified-Data-Engineer-Professional Databricks Certified-Data-Engineer-Professional Exam Questions ⚾ Open ⮆ www.pdfvce.com ⮄ and search for 【 Certified-Data-Engineer-Professional 】 to download exam materials for free 🎰Interactive Certified-Data-Engineer-Professional EBook
- 100% Pass 2026 High Hit-Rate Databricks Certified-Data-Engineer-Professional: Pdf Databricks Certified Data Engineer Professional Files 🧘 Search for 《 Certified-Data-Engineer-Professional 》 and download it for free on [ www.troytecdumps.com ] website 😄Certified-Data-Engineer-Professional Reliable Braindumps Free
- Certified-Data-Engineer-Professional Reliable Braindumps Free 🖋 Certification Certified-Data-Engineer-Professional Test Questions 🦦 New Certified-Data-Engineer-Professional Braindumps Files 📊 Simply search for ➽ Certified-Data-Engineer-Professional 🢪 for free download on ➠ www.pdfvce.com 🠰 🦝PDF Certified-Data-Engineer-Professional Cram Exam
- Get Ready For Your Exam Quickly With Certified-Data-Engineer-Professional PDF Dumps Format ♿ Enter 「 www.examcollectionpass.com 」 and search for ✔ Certified-Data-Engineer-Professional ️✔️ to download for free 📳Valid Certified-Data-Engineer-Professional Exam Guide
- Actual Databricks Certified-Data-Engineer-Professional Practice Test - Quick Test Preparation Tips 🕴 Open ➽ www.pdfvce.com 🢪 enter ➤ Certified-Data-Engineer-Professional ⮘ and obtain a free download 😏Certified-Data-Engineer-Professional Reliable Braindumps Free
- First-grade Pdf Certified-Data-Engineer-Professional Files, Practice Certified-Data-Engineer-Professional Exam 🐀 Search for 《 Certified-Data-Engineer-Professional 》 and download it for free on ☀ www.dumpsmaterials.com ️☀️ website 😑Valid Certified-Data-Engineer-Professional Test Materials
- Using Pdf Certified-Data-Engineer-Professional Files, Pass The Databricks Certified Data Engineer Professional 👰 The page for free download of 【 Certified-Data-Engineer-Professional 】 on ➤ www.pdfvce.com ⮘ will open immediately 🥊Valid Certified-Data-Engineer-Professional Test Materials
- Overcome Exam Challenges with Certified-Data-Engineer-Professional Databricks Certified-Data-Engineer-Professional Exam Questions 🧛 Easily obtain free download of ➠ Certified-Data-Engineer-Professional 🠰 by searching on ⇛ www.testkingpass.com ⇚ 🕍New Certified-Data-Engineer-Professional Braindumps Files
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, swipy.ru, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes