無料PDFDY0-001対応受験 |最初の試行で簡単に勉強して試験に合格する &更新のDY0-001: CompTIA DataAI Certification Exam

BONUS!!! Jpexam DY0-001ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=16PNNkIm2JUs25mNJFSRTuKv-6J-J8A5f
ほかの人はあちこちCompTIAのDY0-001試験の資料を探しているとき、あなたは問題集の勉強を始めました。準備の段階であなたはリーダーしています。我々Jpexamの提供するCompTIAのDY0-001試験のソフトは豊富な試験に関する資源を含めてあなたに最も真実のCompTIAのDY0-001試験環境で体験させます。
CompTIA DY0-001 Exam Overview:
| Certification Vendor: | CompTIA |
|---|
| Exam Name: | CompTIA DataAI Certification Exam |
|---|
| Exam Number: | DY0-001 |
|---|
| Real Exam Qty: | Up to 90 |
|---|
| Certificate Validity Period: | Usually 3 years |
|---|
| Available Languages: | Japanese, English |
|---|
| Passing Score: | Pass/Fail (No scaled score) |
|---|
| Exam Price: | $529 USD |
|---|
| Exam Format: | Multiple Choice, Performance-Based |
|---|
| Exam Duration: | 165 minutes |
|---|
| Related Certifications: | CompTIA DataAI (formerly DataX) |
|---|
| Sample Questions: | CompTIA DY0-001 Sample Questions |
|---|
| Exam Way: | Available at Pearson VUE testing centers or via online proctoring (OnVUE). |
|---|
| Pre Condition: | 5+ years of experience in data science or a similar role recommended. |
|---|
| Official Syllabus URL: | https://www.comptia.org/en-us/certifications/dataai |
|---|
>> DY0-001対応受験 <<
DY0-001対策学習、DY0-001日本語版と英語版
あなたに相応しいJpexam問題集を探していますか。DY0-001試験備考資料の整理を悩んでいますか。専業化のIT認定試験資料提供者Jpexamとして、かねてより全面的の資料を準備します。あなたの資料を探す時間を節約し、CompTIA DY0-001試験の復習をやっています。
CompTIA DY0-001 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - Machine Learning: This section of the exam measures skills of a Machine Learning Engineer and covers foundational ML concepts such as overfitting, feature selection, and ensemble models. It includes supervised learning algorithms, tree-based methods, and regression techniques. The domain introduces deep learning frameworks and architectures like CNNs, RNNs, and transformers, along with optimization methods. It also addresses unsupervised learning, dimensionality reduction, and clustering models, helping candidates understand the wide range of ML applications and techniques used in modern analytics.
|
| トピック 2 | - Mathematics and Statistics: This section of the exam measures skills of a Data Scientist and covers the application of various statistical techniques used in data science, such as hypothesis testing, regression metrics, and probability functions. It also evaluates understanding of statistical distributions, types of data missingness, and probability models. Candidates are expected to understand essential linear algebra and calculus concepts relevant to data manipulation and analysis, as well as compare time-based models like ARIMA and longitudinal studies used for forecasting and causal inference.
|
| トピック 3 | - Operations and Processes: This section of the exam measures skills of an AI
- ML Operations Specialist and evaluates understanding of data ingestion methods, pipeline orchestration, data cleaning, and version control in the data science workflow. Candidates are expected to understand infrastructure needs for various data types and formats, manage clean code practices, and follow documentation standards. The section also explores DevOps and MLOps concepts, including continuous deployment, model performance monitoring, and deployment across environments like cloud, containers, and edge systems.
|
| トピック 4 | - Modeling, Analysis, and Outcomes: This section of the exam measures skills of a Data Science Consultant and focuses on exploratory data analysis, feature identification, and visualization techniques to interpret object behavior and relationships. It explores data quality issues, data enrichment practices like feature engineering and transformation, and model design processes including iterations and performance assessments. Candidates are also evaluated on their ability to justify model selections through experiment outcomes and communicate insights effectively to diverse business audiences using appropriate visualization tools.
|
| トピック 5 | - Specialized Applications of Data Science: This section of the exam measures skills of a Senior Data Analyst and introduces advanced topics like constrained optimization, reinforcement learning, and edge computing. It covers natural language processing fundamentals such as text tokenization, embeddings, sentiment analysis, and LLMs. Candidates also explore computer vision tasks like object detection and segmentation, and are assessed on their understanding of graph theory, anomaly detection, heuristics, and multimodal machine learning, showing how data science extends across multiple domains and applications.
|
CompTIA DataAI Certification Exam 認定 DY0-001 試験問題 (Q68-Q73):
質問 # 68
A data scientist is developing a model to predict the outcome of a vote for a national mascot. The choice is between tigers and lions. The full data set represents feedback from individuals representing 17 professions and 12 different locations. The following rank aggregation represents 80% of the data set:
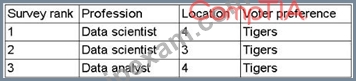
Which of the following is the most likely concern about the model's ability to predict the outcome of the vote?
- A. In-sample data
- B. Out-of-sample data
- C. Extrapolated data
- D. Interpolated data
正解:B
解説:
The aggregated feedback covers only 80% of respondents, mostly from a few professions and locations, so the model hasn't "seen" the remaining 20% (and those underrepresented groups). Its performance on those unseen subsets (out-of-sample data) is therefore the primary concern for how well it will predict the actual vote.
質問 # 69
Which of the following describes the appropriate use case for PCA?
- A. Dimensionality reduction
- B. Regression
- C. Classification
- D. Recommendation
正解:A
解説:
Principal Component Analysis transforms correlated features into a smaller set of uncorrelated components that capture most of the variance, making it ideal for reducing dimensionality before modeling or visualization.
質問 # 70
A data scientist is building a proof of concept for a commercialized machine-learning model. Which of the following is the best starting point?
- A. Model selection
- B. Hyperparameter tuning
- C. Literature review
- D. Model performance evaluation
正解:A
解説:
# In the proof-of-concept phase, the first practical step is model selection - identifying which modeling technique is most appropriate based on the nature of the problem, data, and business goal. Literature reviews are helpful but usually precede model experimentation.
Why the other options are incorrect:
* A: Literature review informs planning but isn't the first hands-on step.
* B: Performance evaluation comes after models are built.
* C: Hyperparameter tuning applies after a model is chosen.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 5.1:"Model selection is a critical step during early prototyping when evaluating different algorithms for feasibility."
* CRISP-DM Framework - Modeling Phase:"Selecting candidate models is the first step in model development after understanding the data."
質問 # 71
Which of the following distribution methods or models can most effectively represent the actual arrival times of a bus that runs on an hourly schedule?
- A. Normal
- B. Binomial
- C. Poisson
- D. Exponential
正解:A
解説:
Scheduled buses tend to arrive around a fixed time with random delays that cluster symmetrically around the hour. A normal distribution effectively models those continuous, bell-shaped deviations from the exact schedule.
質問 # 72
Which of the following explains back propagation?
- A. The passage of accuracy backward through a neural network to update weights and biases
- B. The passage of errors backward through a neural network to update weights and biases
- C. The passage of nodes backward through a neural network to update weights and biases
- D. The passage of convolutions backward through a neural network to update weights and biases
正解:B
解説:
Back propagation computes the gradient of the loss (error) with respect to each weight by propagating the error signal backward through the network, then uses those gradients to adjust weights and biases.
質問 # 73
......
DY0-001対策学習: https://www.jpexam.com/DY0-001_exam.html
- www.passtest.jp CompTIAのDY0-001問題集 😦 ( www.passtest.jp )で[ DY0-001 ]を検索して、無料で簡単にダウンロードできますDY0-001模試エンジン
- 試験の準備方法-認定するDY0-001対応受験試験-実際的なDY0-001対策学習 🚹 【 www.goshiken.com 】を開き、⮆ DY0-001 ⮄を入力して、無料でダウンロードしてくださいDY0-001試験参考書
- DY0-001最新関連参考書 ⏺ DY0-001試験問題集 🎉 DY0-001最新関連参考書 🐩 ➽ www.shikenpass.com 🢪には無料の▶ DY0-001 ◀問題集がありますDY0-001日本語版と英語版
- 有効的なCompTIA DY0-001対応受験 - 合格スムーズDY0-001対策学習 | 実際的なDY0-001日本語版と英語版 🦞 Open Webサイト➽ www.goshiken.com 🢪検索( DY0-001 )無料ダウンロードDY0-001日本語参考
- 効果的なDY0-001対応受験 - 合格スムーズDY0-001対策学習 | 一番優秀なDY0-001日本語版と英語版 CompTIA DataAI Certification Exam 🥵 ▶ www.mogiexam.com ◀から簡単に“ DY0-001 ”を無料でダウンロードできますDY0-001トレーニング資料
- DY0-001試験問題集 ☃ DY0-001資格問題対応 ⚖ DY0-001試験勉強過去問 🥒 ➠ www.goshiken.com 🠰で{ DY0-001 }を検索して、無料で簡単にダウンロードできますDY0-001試験準備
- DY0-001試験の準備方法|ハイパスレートのDY0-001対応受験試験|素敵なCompTIA DataAI Certification Exam対策学習 ➕ 今すぐ☀ www.xhs1991.com ️☀️で▛ DY0-001 ▟を検索し、無料でダウンロードしてくださいDY0-001リンクグローバル
- 高品質なDY0-001対応受験 - 合格スムーズDY0-001対策学習 | 100%合格率のDY0-001日本語版と英語版 📑 ⮆ www.goshiken.com ⮄で⇛ DY0-001 ⇚を検索し、無料でダウンロードしてくださいDY0-001資格問題対応
- DY0-001日本語参考 🧕 DY0-001資料的中率 🍴 DY0-001関連資格試験対応 🔢 { www.goshiken.com }の無料ダウンロード▛ DY0-001 ▟ページが開きますDY0-001無料試験
- 効果的なDY0-001対応受験 - 合格スムーズDY0-001対策学習 | 一番優秀なDY0-001日本語版と英語版 CompTIA DataAI Certification Exam 🗳 《 www.goshiken.com 》は、[ DY0-001 ]を無料でダウンロードするのに最適なサイトですDY0-001模試エンジン
- DY0-001リンクグローバル 🕝 DY0-001試験参考書 🌎 DY0-001関連資格試験対応 🟫 [ www.xhs1991.com ]を入力して【 DY0-001 】を検索し、無料でダウンロードしてくださいDY0-001資料的中率
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
2026年Jpexamの最新DY0-001 PDFダンプおよびDY0-001試験エンジンの無料共有:https://drive.google.com/open?id=16PNNkIm2JUs25mNJFSRTuKv-6J-J8A5f