Reliable Databricks-Certified-Professional-Data-Engineer Test Vce & Valid Databricks-Certified-Professional-Data-Engineer Braindumps

Customizable Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) practice tests (desktop and web-based) of Free4Torrent are made to ensure excellent practice of applicants. Users can take multiple Databricks-Certified-Professional-Data-Engineer practice exams. And the previous exam progress can be saved, so candidates can track it easily whenever they want to see the mistakes. The exam is tough to pass, and that's why Databricks-Certified-Professional-Data-Engineer provides our customers with all the best Databricks Databricks-Certified-Professional-Data-Engineer exam dumps to pass the exam on the first try.
| Section | Weight | Objectives |
|---|
| Data Ingestion | 15-20% | - Batch ingestion methods
- 1. Spark APIs for ingestion
- 2. Integration with external systems
- 3. DBR autoloader
- Streaming ingestion
- 1. Structured streaming fundamentals
- 2. Kafka integration
|
| Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
- 1. Spark SQL queries and functions
- 2. Window functions
- 3. DataFrame operations and transformations
- Python and SQL for data engineering
- 1. Performance optimization techniques
- 2. Spark APIs in Python
- 3. Built-in and user-defined functions
|
| Delta Lake | 20-25% | - Delta Lake fundamentals
- 1. ACID transactions
- 2. Time travel and data versioning
- 3. Optimize and Z-order
- Delta Lake operations
- 1. Delta Live Tables
- 2. Merge, update, delete operations
- 3. Schema evolution and enforcement
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Data governance fundamentals
- 2. Bronze, silver, gold data layers
- 3. Differences between data lake, data warehouse, and lakehouse
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Task dependencies and orchestration
- 2. Monitoring and alerting
- 3. Jobs and job scheduling
|
>> Reliable Databricks-Certified-Professional-Data-Engineer Test Vce <<
Quiz Marvelous Databricks-Certified-Professional-Data-Engineer - Reliable Databricks Certified Professional Data Engineer Exam Test Vce
As we will find that, get the test Databricks-Certified-Professional-Data-Engineer certification, acquire the qualification of as much as possible to our employment effect is significant. But how to get the test Databricks-Certified-Professional-Data-Engineer certification didn't own a set of methods, and cost a lot of time to do something that has no value. With our Databricks-Certified-Professional-Data-Engineer Exam Practice, you will feel much relax for the advantages of high-efficiency and accurate positioning on the content and formats according to the candidates’ interests and hobbies.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q207-Q212):
NEW QUESTION # 207
A data engineering team uses Databricks Lakehouse Monitoring to track the percent_null metric for a critical column in their Delta table.
The profile metrics table (prod_catalog.prod_schema.customer_data_profile_metrics) stores hourly percent_null values.
The team wants to:
Trigger an alert when the daily average of percent_null exceeds 5% for three consecutive days.
Ensure that notifications are not spammed during sustained issues.
Options:
- A. SELECT percent_null
FROM prod_catalog.prod_schema.customer_data_profile_metrics
WHERE window.end >= CURRENT_TIMESTAMP - INTERVAL '1' DAY
Alert Condition: percent_null > 5
Notification Frequency: At most every 24 hours - B. WITH daily_avg AS (
SELECT DATE_TRUNC('DAY', window.end) AS day,
AVG(percent_null) AS avg_null
FROM prod_catalog.prod_schema.customer_data_profile_metrics
GROUP BY DATE_TRUNC('DAY', window.end)
)
SELECT day, avg_null
FROM daily_avg
ORDER BY day DESC
LIMIT 3
Alert Condition: ALL avg_null > 5 for the latest 3 rows
Notification Frequency: Just once - C. SELECT AVG(percent_null) AS daily_avg
FROM prod_catalog.prod_schema.customer_data_profile_metrics
WHERE window.end >= CURRENT_TIMESTAMP - INTERVAL '3' DAY
Alert Condition: daily_avg > 5
Notification Frequency: Each time alert is evaluated - D. SELECT SUM(CASE WHEN percent_null > 5 THEN 1 ELSE 0 END) AS violation_days FROM prod_catalog.prod_schema.customer_data_profile_metrics WHERE window.end >= CURRENT_TIMESTAMP - INTERVAL '3' DAY Alert Condition: violation_days >= 3 Notification Frequency: Just once
Answer: B
Explanation:
The key requirement is to detect when the daily average of percent_null is greater than 5% for three consecutive days.
Option A only checks the last 24 hours, not consecutive days. It would trigger too frequently and cause spam.
Option C calculates an average across all records in the last 3 days, but this could be skewed by one high or low day - it does not ensure consecutive daily violations.
Option D simply counts days where the threshold was exceeded, but it does not guarantee that those days were consecutive. This could incorrectly trigger on non-adjacent violations.
Option B is correct:
It aggregates hourly values into daily averages.
It checks that the last 3 consecutive days all had averages above 5%.
It avoids redundant alerts by using Notification Frequency: Just once.
This matches Databricks Lakehouse Monitoring best practices, where SQL alerts should be designed to aggregate metrics to the correct granularity (daily here) and ensure consecutive threshold violations before triggering.
Reference (Databricks Lakehouse Monitoring, SQL Alerts Best Practices):
Use DATE_TRUNC to compute metrics at the correct time granularity.
To detect consecutive-day issues, filter the last N daily aggregates and check conditions across all rows.
Always configure alerts with controlled notification frequency to prevent alert fatigue.
NEW QUESTION # 208
A CHECK constraint has been successfully added to the Delta table named activity_details using the following logic:
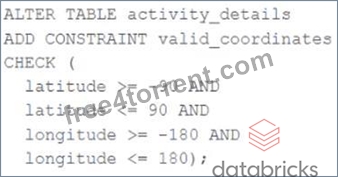
A batch job is attempting to insert new records to the table, including a record where latitude = 45.50 and longitude = 212.67.
Which statement describes the outcome of this batch insert?
- A. The write will insert all records except those that violate the table constraints; the violating records will be reported in a warning log.
- B. The write will include all records in the target table; any violations will be indicated in the boolean column named valid_coordinates.
- C. The write will fail completely because of the constraint violation and no records will be inserted into the target table.
- D. The write will insert all records except those that violate the table constraints; the violating records will be recorded to a quarantine table.
- E. The write will fail when the violating record is reached; any records previously processed will be recorded to the target table.
Answer: C
Explanation:
The CHECK constraint is used to ensure that the data inserted into the table meets the specified conditions. In this case, the CHECK constraint is used to ensure that the latitude and longitude values are within the specified range. If the data does not meet the specified conditions, the write operation will fail completely and no records will be inserted into the target table. This is because Delta Lake supports ACID transactions, which means that either all the data is written or none of it is written. Therefore, the batch insert will fail when it encounters a record that violates the constraint, and the target table will not be updated. References:
* Constraints : https://docs.delta.io/latest/delta-constraints.html
* ACID Transactions : https://docs.delta.io/latest/delta-intro.html#acid-transactions
NEW QUESTION # 209
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df . The pipeline needs to calculate the average humidity and average temperature for each non- overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFrame df has the following schema:
" device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT "
Code block:
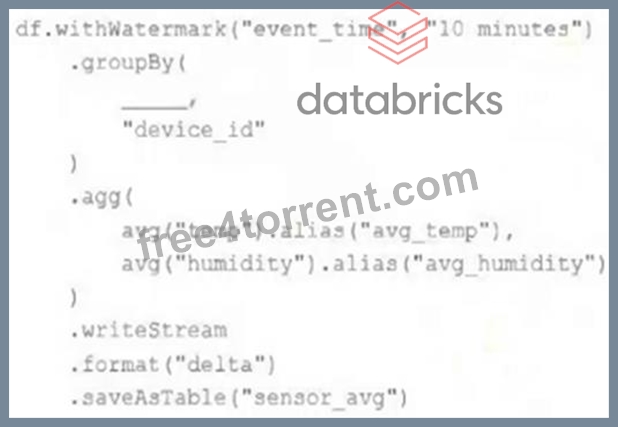
Choose the response that correctly fills in the blank within the code block to complete this task.
- A. window( " event_time " , " 10 minutes " ).alias( " time " )
- B. " event_time "
- C. lag( " event_time " , " 10 minutes " ).alias( " time " )
- D. window( " event_time " , " 5 minutes " ).alias( " time " )
- E. to_interval( " event_time " , " 5 minutes " ).alias( " time " )
Answer: D
Explanation:
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1 second. In this case, the window duration is "5 minutes", which means each window will cover a non-overlapping five-minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window. The alias function is used to rename the struct column as "time". Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation , under "WINDOW" section. https://www.databricks.com/blog/2017/05/08/event-time-aggregation- watermarking-apache-sparks-structured-streaming.html
NEW QUESTION # 210
A user wants to use DLT expectations to validate that a derived table report contains all records from the source, included in the table validation_copy.
The user attempts and fails to accomplish this by adding an expectation to the report table definition.
Which approach would allow using DLT expectations to validate all expected records are present in this table?
- A. Define a SQL UDF that performs a left outer join on two tables, and check if this returns null values for report key values in a DLT expectation for the report table.
- B. Define a function that performs a left outer join on validation_copy and report and report, and check against the result in a DLT expectation for the report table
- C. Define a temporary table that perform a left outer join on validation_copy and report, and define an expectation that no report key values are null
- D. Define a view that performs a left outer join on validation_copy and report, and reference this view in DLT expectations for the report table
Answer: D
Explanation:
To validate that all records from the source are included in the derived table, creating a view that performs a left outer join between the validation_copy table and the report table is effective. The view can highlight any discrepancies, such as null values in the report table's key columns, indicating missing records. This view can then be referenced in DLT (Delta Live Tables) expectations for the report table to ensure data integrity. This approach allows for a comprehensive comparison between the source and the derived table.
References:
* Databricks Documentation on Delta Live Tables and Expectations: Delta Live Tables Expectations
NEW QUESTION # 211
Which statement characterizes the general programming model used by Spark Structured Streaming?
- A. Structured Streaming models new data arriving in a data stream as new rows appended to an unbounded table.
- B. Structured Streaming is implemented as a messaging bus and is derived from Apache Kafka.
- C. Structured Streaming relies on a distributed network of nodes that hold incremental state values for cached stages.
- D. Structured Streaming leverages the parallel processing of GPUs to achieve highly parallel data throughput.
- E. Structured Streaming uses specialized hardware and I/O streams to achieve sub-second latency for data transfer.
Answer: B
Explanation:
This is the correct answer because it characterizes the general programming model used by Spark Structured Streaming, which is to treat a live data stream as a table that is being continuously appended. This leads to a new stream processing model that is very similar to a batch processing model, where users can express their streaming computation using the same Dataset/DataFrame API as they would use for static data. The Spark SQL engine will take care of running the streaming query incrementally and continuously and updating the final result as streaming data continues to arrive. Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "Overview" section.
NEW QUESTION # 212
......
Databricks-Certified-Professional-Data-Engineer preparation materials will be the good helper for your qualification certification. We are concentrating on providing high-quality authorized Databricks-Certified-Professional-Data-Engineer study guide all over the world so that you can clear exam one time. Databricks-Certified-Professional-Data-Engineer reliable exam bootcamp materials contain three formats: PDF version, Soft test engine and APP test engine so that our products are enough to satisfy different candidates' habits and cover nearly full questions & answers of the real Databricks-Certified-Professional-Data-Engineer test.
Valid Databricks-Certified-Professional-Data-Engineer Braindumps: https://www.free4torrent.com/Databricks-Certified-Professional-Data-Engineer-braindumps-torrent.html
- Exam Databricks-Certified-Professional-Data-Engineer Assessment 🐂 New Databricks-Certified-Professional-Data-Engineer Study Plan 🎇 Databricks-Certified-Professional-Data-Engineer Exam Cram Pdf 🔲 Search for 《 Databricks-Certified-Professional-Data-Engineer 》 and easily obtain a free download on 《 www.torrentvce.com 》 🏈Databricks-Certified-Professional-Data-Engineer Top Questions
- Databricks-Certified-Professional-Data-Engineer Exam Cram Pdf 🗳 Exam Databricks-Certified-Professional-Data-Engineer Topics 📢 New Databricks-Certified-Professional-Data-Engineer Test Objectives 🥩 Copy URL 「 www.pdfvce.com 」 open and search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ to download for free 🌐Databricks-Certified-Professional-Data-Engineer Latest Exam Fee
- Complete Reliable Databricks-Certified-Professional-Data-Engineer Test Vce | Easy To Study and Pass Exam at first attempt - 100% Pass-Rate Databricks Databricks Certified Professional Data Engineer Exam 🏔 Open ▛ www.prepawayexam.com ▟ and search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ to download exam materials for free ‼Databricks-Certified-Professional-Data-Engineer Exam Cram Pdf
- Databricks-Certified-Professional-Data-Engineer Latest Exam Fee 🤓 Reliable Databricks-Certified-Professional-Data-Engineer Exam Pattern 👊 Databricks-Certified-Professional-Data-Engineer Exam Cram Pdf 👽 Easily obtain ▷ Databricks-Certified-Professional-Data-Engineer ◁ for free download through ☀ www.pdfvce.com ️☀️ 🏣Databricks-Certified-Professional-Data-Engineer Latest Exam Fee
- Free PDF Quiz Databricks - Newest Databricks-Certified-Professional-Data-Engineer - Reliable Databricks Certified Professional Data Engineer Exam Test Vce 🍢 Search for 【 Databricks-Certified-Professional-Data-Engineer 】 and obtain a free download on 【 www.examcollectionpass.com 】 🐪Practice Databricks-Certified-Professional-Data-Engineer Test
- Valid Databricks-Certified-Professional-Data-Engineer Exam Papers 🥕 Databricks-Certified-Professional-Data-Engineer Trustworthy Dumps 🔣 Databricks-Certified-Professional-Data-Engineer Exam Cram Questions 🍺 ⇛ www.pdfvce.com ⇚ is best website to obtain ▛ Databricks-Certified-Professional-Data-Engineer ▟ for free download 🔜Reliable Databricks-Certified-Professional-Data-Engineer Exam Pattern
- Reliable Databricks-Certified-Professional-Data-Engineer Exam Pattern ❤ Reliable Databricks-Certified-Professional-Data-Engineer Guide Files 🕉 Databricks-Certified-Professional-Data-Engineer Top Questions 🕠 Enter ⇛ www.prepawayexam.com ⇚ and search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ to download for free ☑New Databricks-Certified-Professional-Data-Engineer Study Notes
- Fast Download Reliable Databricks-Certified-Professional-Data-Engineer Test Vce - Authoritative Valid Databricks-Certified-Professional-Data-Engineer Braindumps - Accurate Databricks Databricks Certified Professional Data Engineer Exam 🛴 Go to website ( www.pdfvce.com ) open and search for ( Databricks-Certified-Professional-Data-Engineer ) to download for free 🌼Databricks-Certified-Professional-Data-Engineer Exam Cram Pdf
- Databricks-Certified-Professional-Data-Engineer Trustworthy Dumps 😥 Practice Databricks-Certified-Professional-Data-Engineer Test 😗 New Databricks-Certified-Professional-Data-Engineer Study Notes 🌕 Go to website ☀ www.testkingpass.com ️☀️ open and search for [ Databricks-Certified-Professional-Data-Engineer ] to download for free ❤Exam Databricks-Certified-Professional-Data-Engineer Assessment
- Fast Download Reliable Databricks-Certified-Professional-Data-Engineer Test Vce - Authoritative Valid Databricks-Certified-Professional-Data-Engineer Braindumps - Accurate Databricks Databricks Certified Professional Data Engineer Exam 😀 Search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ and download it for free immediately on { www.pdfvce.com } 🛤Exam Databricks-Certified-Professional-Data-Engineer Assessment
- Databricks-Certified-Professional-Data-Engineer Latest Exam Fee 🧍 New Databricks-Certified-Professional-Data-Engineer Study Notes 🍃 Online Databricks-Certified-Professional-Data-Engineer Training 🔯 Open ⇛ www.prep4away.com ⇚ and search for 「 Databricks-Certified-Professional-Data-Engineer 」 to download exam materials for free 🍑Databricks-Certified-Professional-Data-Engineer Exam Guide
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, camp-fire.jp, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes