2026 Latest Lead2Passed Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1etw0emeCVcNaDxwMwTJqAc2jxCmc6C2d
Our Professional-Machine-Learning-Engineer exam materials allows you to have a 98% to 100% pass rate; allows you takes only 20 to 30 hours to practice before you take the exam; provide you with 24 free online customer service; provide professional personnel remote assistance; give you full refund if you fail to pass the Professional-Machine-Learning-Engineer Exam. Our Professional-Machine-Learning-Engineer real test serve you with the greatest sincerity. Face to such an excellent product which has so much advantages, do you fall in love with our Professional-Machine-Learning-Engineer study materials now? If your answer is yes, then come and buy our Professional-Machine-Learning-Engineer exam questions now.
| Certification Vendor: | Google Cloud |
|---|---|
| Exam Name: | Google Cloud Professional Machine Learning Engineer Certification Exam |
| Exam Number: | Professional-Machine-Learning-Engineer |
| Exam Price: | $200 USD |
| Certificate Validity Period: | 2 years |
| Real Exam Qty: | Approximately 50–60 questions |
| Available Languages: | Japanese, English |
| Exam Format: | Multiple choice, Case study, Multiple select |
| Exam Duration: | 120 minutes |
| Related Certifications: | Google Cloud Professional Cloud Architect Google Cloud Associate Cloud Engineer Google Cloud Professional Data Engineer |
| Recommended Training: | Vertex AI Documentation Google Cloud Skills Boost - Machine Learning Engineer Path |
| Exam Registration: | Google Cloud Certification Portal Kryterion Webassessor |
| Sample Questions: | Google Professional-Machine-Learning-Engineer Sample Questions |
| Exam Way: | Online proctored exam or in-person testing via Kryterion test centers. |
| Pre Condition: | No formal prerequisites required, but 3+ years of industry experience in ML/AI and familiarity with Google Cloud Platform are strongly recommended. |
| Official Syllabus URL: | https://cloud.google.com/certification/machine-learning-engineer |
>> Latest Test Google Professional-Machine-Learning-Engineer Experience <<
We are dedicated to providing an updated Professional-Machine-Learning-Engineer practice test material with these three formats: PDF, Web-Based practice exam, and Desktop practice test software. With our Professional-Machine-Learning-Engineer practice exam (desktop and web-based), you can evaluate and enhance your knowledge essential to crack the test. This step is critical to the success of your Google Professional-Machine-Learning-Engineer Exam Preparation, as these practice tests help you identify your strengths and weaknesses.
Achieving the Google Professional Machine Learning Engineer certification is a significant accomplishment for any individual seeking to validate their expertise in machine learning. Google Professional Machine Learning Engineer certification demonstrates that an individual has the skills and knowledge required to design, build, and deploy machine learning models on Google Cloud Platform. It also enables individuals to differentiate themselves in the job market and opens up new career opportunities.
The estimated average salary of Professional Machine Learning Engineer - Google is listed below:
NEW QUESTION # 235
You work for a large hotel chain and have been asked to assist the marketing team in gathering predictions for a targeted marketing strategy. You need to make predictions about user lifetime value (LTV) over the next 30 days so that marketing can be adjusted accordingly. The customer dataset is in BigQuery, and you are preparing the tabular data for training with AutoML Tables. This data has a time signal that is spread across multiple columns. How should you ensure that AutoML fits the best model to your data?
Answer: D
NEW QUESTION # 236
Your organization ' s call center has asked you to develop a model that analyzes customer sentiments in each call. The call center receives over one million calls daily, and data is stored in Cloud Storage. The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. You need to select components for data processing and for analytics. How should the data pipeline be designed?
Answer: A
Explanation:
A data pipeline is a set of steps or processes that move data from one or more sources to one or more destinations, usually for the purpose of analysis, transformation, or storage. A data pipeline can be designed using various components, such as data sources, data processing tools, data storage systems, and data analytics tools 1 To design a data pipeline for analyzing customer sentiments in each call, one should consider the following requirements and constraints:
* The call center receives over one million calls daily, and data is stored in Cloud Storage. This implies that the data is large, unstructured, and distributed, and requires a scalable and efficient data processing tool that can handle various types of data formats, such as audio, text, or image.
* The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. This implies that the data is sensitive and subject to data privacy and compliance regulations, and requires a secure and reliable data storage system that can enforce data encryption, access control, and regional policies.
* The data science team has a third-party tool for visualization and access which requires a SQL ANSI-
2011 compliant interface. This implies that the data analytics tool is external and independent of the data pipeline, and requires a standard and compatible data interface that can support SQL queries and operations.
One of the best options for selecting components for data processing and for analytics is to use Dataflow for data processing and BigQuery for analytics. Dataflow is a fully managed service for executing Apache Beam pipelines for data processing, such as batch or stream processing, extract-transform-load (ETL), or data integration. BigQuery is a serverless, scalable, and cost-effective data warehouse that allows you to run fast and complex queries on large-sca le data 2 3 Using Dataflow and BigQuery has several advantages for this use case:
* Dataflow can process large and unstructured data from Cloud Storage in a parallel and distributed manner, and apply various transformations, such as converting audio to text, extracting sentiment scores, or anonymizing PII. Dataflow can also handle both batch and stream processing, which can enable real-time or near-real-time analysis of the call data.
* BigQuery can store and analyze the processed data from Dataflow in a secure and reliable way, and enforce data encryption, access control, and regional policies. BigQuery can also support SQL ANSI-
2011 compliant interface, which can enable the data science team to use their third-party tool for visualization and access. BigQuery can also integrate with various Google Cloud services and tools, such as AI Platform, Data Studio, or Looker.
* Dataflow and BigQuery can work seamlessly together, as they are both part of the Google Cloud ecosystem, and support various data formats, such as CSV, JSON, Avro, or Parquet. Dataflow and BigQuery can also leverage the benefits of Google Cloud infrastructure, such as scalability, performance, and cost-effectiveness.
The other options are not as suitable or feasible. Using Pub/Sub for data processing and Datastore for analytics is not ideal, as Pub/Sub is mainly designed for event-driven and asynchronous messaging, not data processing, and Datastore is mainly designed for low-latency and high-throughput key-value operations, not analytics. Using Cloud Function for data processing and Cloud SQL for analytics is not optimal, as Cloud Function has limitations on the memory, CPU, and execution time, and does not support complex data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data. Using Cloud Composer for data processing and Cloud SQL for analytics is not relevant, as Cloud Composer is mainly designed for orchestrating complex workflows across multiple systems, not data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data.
References: 1 : Data pipeline 2 : Dataflow overview 3 : BigQuery overview : [Dataflow documentation] : [BigQuery documentation]
NEW QUESTION # 237
You deployed an ML model into production a year ago. Every month, you collect all raw requests that were sent to your model prediction service during the previous month. You send a subset of these requests to a human labeling service to evaluate your model's performance. After a year, you notice that your model's performance sometimes degrades significantly after a month, while other times it takes several months to notice any decrease in performance. The labeling service is costly, but you also need to avoid large performance degradations. You want to determine how often you should retrain your model to maintain a high level of performance while minimizing cost. What should you do?
Answer: C
Explanation:
The best option for determining how often to retrain your model to maintain a high level of performance while minimizing cost is to run training-serving skew detection batch jobs every few days. Training-serving skew refers to the discrepancy between the distributions of the features in the training dataset and the serving data. This can cause the model to perform poorly on the new data, as it is not representative of the data that the model was trained on. By running training-serving skew detection batch jobs, you can monitor the changes in the feature distributions over time, and identify when the skew becomes significant enough to affect the model performance. If skew is detected, you can send the most recent serving data to the labeling service, and use the labeled data to retrain your model. This option has the following benefits:
* It allows you to retrain your model only when necessary, based on the actual data changes, rather than on a fixed schedule or a heuristic. This can save you the cost of the labeling service and the retraining process, and also avoid overfitting or underfitting your model.
* It leverages the existing tools and frameworks for training-serving skew detection, such as TensorFlow Data Validation (TFDV) and Vertex Data Labeling. TFDV is a library that can compute and visualize descriptive statistics for your datasets, and compare the statistics across different datasets. Vertex Data Labeling is a service that can label your data with high quality and low latency, using either human labelers or automated labelers.
* It integrates well with the MLOps practices, such as continuous integration and continuous delivery (CI/CD), which can automate the workflow of running the skew detection jobs, sending the data to the labeling service, retraining the model, and deploying the new model version.
The other options are less optimal for the following reasons:
* Option A: Training an anomaly detection model on the training dataset, and running all incoming requests through this model, introduces additional complexity and overhead. This option requires building and maintaining a separate model for anomaly detection, which can be challenging and time-consuming. Moreover, this option requires running the anomaly detection model on every request, which can increase the latency and resource consumption of the prediction service. Additionally, this option may not capture the subtle changes in the feature distributions that can affect the model performance, as anomalies are usually defined as rare or extreme events.
* Option B: Identifying temporal patterns in your model's performance over the previous year, and creating a schedule for sending serving data to the labeling service for the next year, introduces
* additional assumptions and risks. This option requires analyzing the historical data and model performance, and finding the patterns that can explain the variations in the model performance over time. However, this can be difficult and unreliable, as the patterns may not be consistent or predictable, and may depend on various factors that are not captured by the data. Moreover, this option requires creating a schedule based on the past patterns, which may not reflect the future changes in the data or the environment. This can lead to either sending too much or too little data to the labeling service, resulting in either wasted cost or degraded performance.
* Option C: Comparing the cost of the labeling service with the lost revenue due to model performance degradation over the past year, and adjusting the frequency of model retraining accordingly, introduces additional challenges and trade-offs. This option requires estimating the cost of the labeling service and the lost revenue due to model performance degradation, which can be difficult and inaccurate, as they may depend on various factors that are not easily quantifiable or measurable. Moreover, this option requires finding the optimal balance between the cost and the performance, which can be subjective and variable, as different stakeholders may have different preferences and expectations. Furthermore, this option may not account for the potential impact of the model performance degradation on other aspects of the business, such as customer satisfaction, retention, or loyalty.
NEW QUESTION # 238
You trained a text classification model. You have the following SignatureDefs: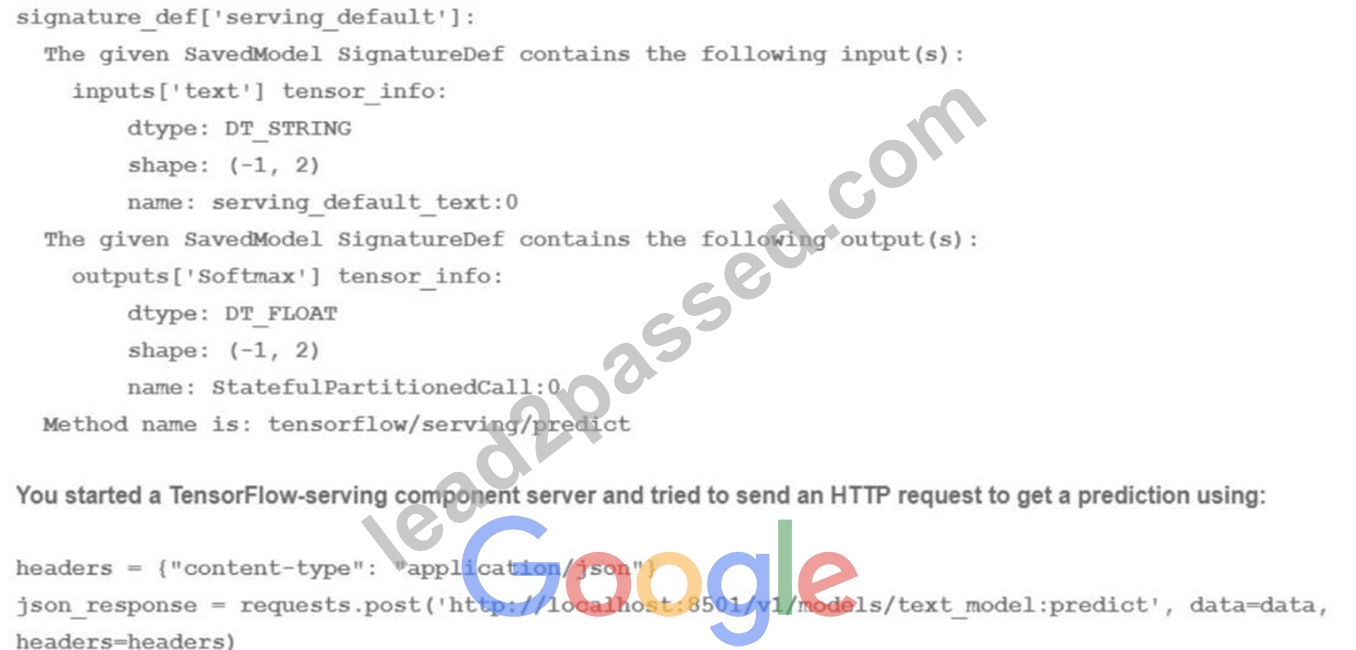
What is the correct way to write the predict request?
Answer: B
Explanation:
A predict request is a way to send data to a trained model and get predictions in return. A predict request can be written in different formats, such as JSON, protobuf, or gRPC, depending on the service and the platform that are used to host and serve the model. A predict request usually contains the following information:
* The signature name: This is the name of the signature that defines the inputs and outputs of the model.
A signature is a way to specify the expected format, type, and shape of the data that the model can accept and produce. A signature can be specified when exporting or saving the model, or it can be automatically inferred by the service or the platform. A model can have multiple signatures, but only one can be used for each predict request.
* The instances: This is the data that is sent to the model for prediction. The instances can be a single instance or a batch of instances, depending on the size and shape of the data. The instances should match the input specification of the signature, such as the number, name, and type of the input tensors.
For the use case of training a text classification model, the correct way to write the predict request is D. data = json.dumps({"signature_name": "serving_default", "instances": [['a', 'b'], ['c', 'd'], ['e', 'f']]}) This option involves writing the predict request in JSON format, which is a common and convenient format for sending and receiving data over the web. JSON stands for JavaScript Object Notation, and it is a way to represent data as a collection of name-value pairs or an ordered list of values. JSON can be easily converted to and from Python objects using the json module.
This option also involves using the signature name "serving_default", which is the default signature name that is assigned to the model when it is saved or exported without specifying a custom signature name. The serving_default signature defines the input and output tensors of the model based on the SignatureDef that is shown in the image. According to the SignatureDef, the model expects an input tensor called "text" that has a shape of (-1, 2) and a type of DT_STRING, and produces an output tensor called "softmax" that has a shape of (-1, 2) and a type of DT_FLOAT. The -1 in the shape indicates that the dimension can vary depending on the number of instances, and the 2 indicates that the dimension is fixed at 2. The DT_STRING and DT_FLOAT indicate that the data type is string and float, respectively.
This option also involves sending a batch of three instances to the model for prediction. Each instance is a list of two strings, such as ['a', 'b'], ['c', 'd'], or ['e', 'f']. These instances match the input specification of the signature, as they have a shape of (3, 2) and a type of string. The model will process these instances and produce a batch of three predictions, each with a softmax output that has a shape of (1, 2) and a type of float.
The softmax output is a probability distribution over the two possible classes that the model can predict, such as positive or negative sentiment.
Therefore, writing the predict request as data = json.dumps({"signature_name": "serving_default",
"instances": [['a', 'b'], ['c', 'd'], ['e', 'f']]}) is the correct and valid way to send data to the text classification model and get predictions in return.
References:
* [json - JSON encoder and decoder]
NEW QUESTION # 239
You recently developed a wide and deep model in TensorFlow. You generated training datasets using a SQL script that preprocessed raw data in BigQuery by performing instance-level transformations of the data. You need to create a training pipeline to retrain the model on a weekly basis. The trained model will be used to generate daily recommendations. You want to minimize model development and training time. How should you develop the training pipeline?
Answer: B
NEW QUESTION # 240
......
Professional-Machine-Learning-Engineer Reliable Exam Bootcamp: https://www.lead2passed.com/Google/Professional-Machine-Learning-Engineer-practice-exam-dumps.html
BTW, DOWNLOAD part of Lead2Passed Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1etw0emeCVcNaDxwMwTJqAc2jxCmc6C2d