Free Demo: 100% Databricks Databricks-Certified-Data-Engineer-Professional Exam Questions
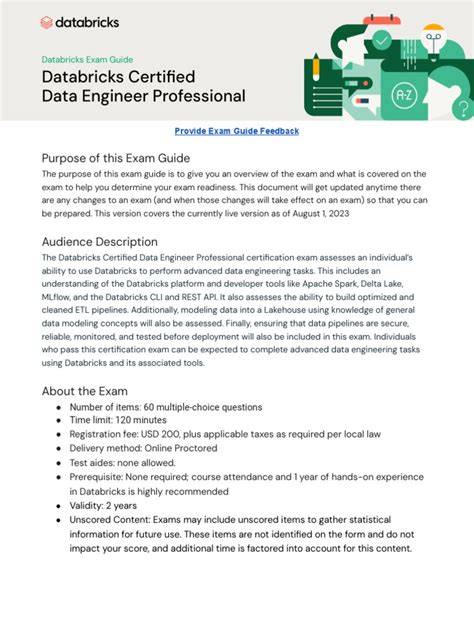
All contents of Databricks-Certified-Data-Engineer-Professional training guide are being explicit to make you have explicit understanding of this exam. Their contribution is praised for their purview is unlimited. None cryptic contents in Databricks-Certified-Data-Engineer-Professional learning materials you may encounter. And our Databricks-Certified-Data-Engineer-Professional Exam Questions are easy to understand and they are popular to be sold to all over the world. Just look at the comments on the website, then you will know that we have a lot of loyal customers.
| Section | Objectives |
|---|
| Production Pipelines and Orchestration | - Job scheduling and monitoring
- Error handling and recovery strategies
- Databricks Workflows
|
| Data Ingestion and Processing | - Structured Streaming fundamentals
- Batch and streaming ingestion with Auto Loader
- ETL pipeline design patterns
|
| Delta Lake and Data Management | - Schema evolution and enforcement
- Delta Lake transactions and ACID properties
- Time travel and versioning
|
| Databricks Lakehouse Platform Architecture | - Medallion architecture (Bronze, Silver, Gold)
- Data governance concepts (Unity Catalog basics)
- Workspace and cluster architecture
|
| Data Modeling and Transformation | - Dimensional modeling concepts
- Spark SQL transformations
- Performance optimization techniques
|
>> Databricks-Certified-Data-Engineer-Professional Valid Exam Voucher <<
Get Special 30% EXTRA Discount on Databricks-Certified-Data-Engineer-Professional Dumps By Dumpcollection
This Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) software has a simple-to-use interface. By using the Databricks-Certified-Data-Engineer-Professional practice exam software, you can evaluate your mistakes at the end of every take and overcome them. Our software helps you to get familiar with the format of the original Databricks-Certified-Data-Engineer-Professional test. Software lets you customize your Databricks Databricks-Certified-Data-Engineer-Professional Practice Exam's duration and question numbers as per your practice needs. You just need an active internet connection to confirm the license of your product. All Windows-based computers support this Databricks-Certified-Data-Engineer-Professional practice exam software.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q245-Q250):
NEW QUESTION # 245
A Structured Streaming job deployed to production has been resulting in higher than expected cloud storage costs. At present, during normal execution, each microbatch of data is processed in less than 3s; at least 12 times per minute, a microbatch is processed that contains 0 records. The streaming write was configured using the default trigger settings. The production job is currently scheduled alongside many other Databricks jobs in a workspace with instance pools provisioned to reduce start-up time for jobs with batch execution.
Holding all other variables constant and assuming records need to be processed in less than 10 minutes, which adjustment will meet the requirement?
- A. Use the trigger once option and configure a Databricks job to execute the query every 10 minutes; this approach minimizes costs for both compute and storage.
- B. Increase the number of shuffle partitions to maximize parallelism, since the trigger interval cannot be modified without modifying the checkpoint directory.
- C. Set the trigger interval to 500 milliseconds; setting a small but non-zero trigger interval ensures that the source is not queried too frequently.
- D. Set the trigger interval to 10 minutes; each batch calls APIs in the source storage account, so decreasing trigger frequency to maximum allowable threshold should minimize this cost.
- E. Set the trigger interval to 3 seconds; the default trigger interval is consuming too many records per batch, resulting in spill to disk that can increase volume costs.
Answer: D
NEW QUESTION # 246
An hourly batch job is configured to ingest data files from a cloud object storage container where each batch represent all records produced by the source system in a given hour. The batch job to process these records into the Lakehouse is sufficiently delayed to ensure no late-arriving data is missed. The user_id field represents a unique key for the data, which has the following schema:
user_id BIGINT, username STRING, user_utc STRING, user_region STRING, last_login BIGINT, auto_pay BOOLEAN, last_updated BIGINT New records are all ingested into a table named account_history which maintains a full record of all data in the same schema as the source. The next table in the system is named account_current and is implemented as a Type 1 table representing the most recent value for each unique user_id.
Assuming there are millions of user accounts and tens of thousands of records processed hourly, which implementation can be used to efficiently update the described account_current table as part of each hourly batch job?
- A. Use Auto Loader to subscribe to new files in the account history directory; configure a Structured Streaminq trigger once job to batch update newly detected files into the account current table.
- B. Overwrite the account current table with each batch using the results of a query against the account history table grouping by user id and filtering for the max value of last updated.
- C. Filter records in account history using the last updated field and the most recent hour processed, making sure to deduplicate on username; write a merge statement to update or insert the most recent value for each username.
- D. Use Delta Lake version history to get the difference between the latest version of account history and one version prior, then write these records to account current.
- E. Filter records in account history using the last updated field and the most recent hour processed, as well as the max last iogin by user id write a merge statement to update or insert the most recent value for each user id.
Answer: E
Explanation:
This is the correct answer because it efficiently updates the account current table with only the most recent value for each user id. The code filters records in account history using the last updated field and the most recent hour processed, which means it will only process the latest batch of data. It also filters by the max last login by user id, which means it will only keep the most Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from recent record for each user id within that batch. Then, it writes a merge statement to update or insert the most recent value for each user id into account current, which means it will perform an upsert operation based on the user id column.
NEW QUESTION # 247
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).

Which statement describes what will happen when the above code is executed?
- A. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the password will be printed in plain text.
- B. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the encoded password will be saved to DBFS.
- C. The connection to the external table will succeed; the string "redacted" will be printed.
- D. The connection to the external table will fail; the string "redacted" will be printed.
- E. The connection to the external table will succeed; the string value of password will be printed in plain text.
Answer: C
Explanation:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks.
NEW QUESTION # 248
A data engineer is using Lakeflow Declarative Pipeline to propagate row deletions from a source bronze table (user_bronze) to a target silver table (user_silver). The engineer wants deletions in user_bronze to automatically delete corresponding rows in user_silver during pipeline execution.
Which configuration ensures deletions in the bronze table are propagated to the silver table?
- A. Enable Change Data Feed (CDF) on user_bronze, read its CDF stream, and use apply_changes() with apply_as_deletes=True for user_silver.
- B. Use apply_changes without CDF and filter rows where _soft_deleted is true.
- C. Enable CDF on user_silver, read its transaction log, and use MERGE to sync deletions.
- D. Configure VACUUM on user_bronze to delete files, then rebuild user_silver from scratch.
Answer: A
Explanation:
According to Databricks documentation, Change Data Feed (CDF) allows pipelines to read incremental data changes, including inserts, updates, and deletes, from a Delta table. When deletions occur in the source table, reading the CDF stream ensures downstream consumers receive the deletion records. The Lakeflow Declarative Pipelines API provides the apply_changes() function (or auto-CDC pipelines) with the apply_as_deletes parameter to correctly apply those deletions to the target table. This enables automatic synchronization between bronze and silver layers. Options A and D either require manual handling or complete rebuilds, and C incorrectly applies CDF to the target rather than the source. Therefore, enabling CDF on the bronze table and using apply_as_deletes=True is the correct, Databricks-supported configuration.
NEW QUESTION # 249
The data engineering team is migrating an enterprise system with thousands of tables and views into the Lakehouse. They plan to implement the target architecture using a series of bronze, silver, and gold tables. Bronze tables will almost exclusively be used by production data engineering workloads, while silver tables will be used to support both data engineering and machine learning workloads. Gold tables will largely serve business intelligence and reporting purposes. While personal identifying information (PII) exists in all tiers of data, pseudonymization and anonymization rules are in place for all data at the silver and gold levels.
The organization is interested in reducing security concerns while maximizing the ability to collaborate across diverse teams.
Which statement exemplifies best practices for implementing this system?
- A. Isolating tables in separate databases based on data quality tiers allows for easy permissions management through database ACLs and allows physical separation of default storage locations for managed tables.
- B. Because all tables must live in the same storage containers used for the database they're created in, organizations should be prepared to create between dozens and thousands of databases depending on their data isolation requirements.
- C. Working in the default Databricks database provides the greatest security when working with managed tables, as these will be created in the DBFS root.
- D. Because databases on Databricks are merely a logical construct, choices around database organization do not impact security or discoverability in the Lakehouse.
- E. Storinq all production tables in a single database provides a unified view of all data assets available throughout the Lakehouse, simplifying discoverability by granting all users view privileges on this database.
Answer: A
Explanation:
This is the correct answer because it exemplifies best practices for implementing this system. By isolating tables in separate databases based on data quality tiers, such as bronze, silver, and gold, the data engineering team can achieve several benefits. First, they can easily manage permissions for different users and groups through database ACLs, which allow granting or revoking access to databases, tables, or views. Second, they can physically separate the default storage locations for managed tables in each database, which can improve performance and reduce costs. Third, they can provide a clear and consistent naming convention for the tables in each database, which can improve discoverability and usability.
NEW QUESTION # 250
......
Because the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) test has a restricted time constraint, time management must be exercised to get success. Only with enough practice one can answer real Databricks Databricks-Certified-Data-Engineer-Professional Exam Questions in a given amount of time. It has created three formats to aid Databricks Databricks-Certified-Data-Engineer-Professional applicants in practicing and organizing their time for this aim.
Databricks-Certified-Data-Engineer-Professional New Study Plan: https://www.dumpcollection.com/Databricks-Certified-Data-Engineer-Professional_braindumps.html
- Free PDF Quiz 2026 Databricks Marvelous Databricks-Certified-Data-Engineer-Professional Valid Exam Voucher 🍉 Copy URL ✔ www.testkingpass.com ️✔️ open and search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ to download for free 🚺Databricks-Certified-Data-Engineer-Professional Exam Experience
- Databricks Databricks-Certified-Data-Engineer-Professional Valid Exam Voucher: Databricks Certified Data Engineer Professional Exam - Pdfvce Gives Warm Service - Excellent New Study Plan 🦇 Search for 【 Databricks-Certified-Data-Engineer-Professional 】 and download it for free on 《 www.pdfvce.com 》 website 🎄Authorized Databricks-Certified-Data-Engineer-Professional Test Dumps
- 2026 Databricks-Certified-Data-Engineer-Professional Valid Exam Voucher | Latest Databricks Certified Data Engineer Professional Exam 100% Free New Study Plan 💸 Open website “ www.prepawaypdf.com ” and search for ➠ Databricks-Certified-Data-Engineer-Professional 🠰 for free download 📬Databricks-Certified-Data-Engineer-Professional Certification Materials
- Pass Guaranteed Quiz 2026 Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam – Trustable Valid Exam Voucher ⛑ Search for { Databricks-Certified-Data-Engineer-Professional } on [ www.pdfvce.com ] immediately to obtain a free download 🖤Free Databricks-Certified-Data-Engineer-Professional Download Pdf
- Free PDF Quiz 2026 Databricks Reliable Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Valid Exam Voucher 🏳 Enter ⮆ www.vce4dumps.com ⮄ and search for 【 Databricks-Certified-Data-Engineer-Professional 】 to download for free ⬛Databricks-Certified-Data-Engineer-Professional Study Guide
- Databricks Databricks-Certified-Data-Engineer-Professional Valid Exam Voucher: Databricks Certified Data Engineer Professional Exam - Pdfvce Gives Warm Service - Excellent New Study Plan 💧 Simply search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ for free download on { www.pdfvce.com } 📣Databricks-Certified-Data-Engineer-Professional Reliable Exam Voucher
- Databricks-Certified-Data-Engineer-Professional Certification Materials 🍱 Authorized Databricks-Certified-Data-Engineer-Professional Test Dumps 🥃 Databricks-Certified-Data-Engineer-Professional Practice Guide 📐 Search for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 and easily obtain a free download on ⏩ www.examdiscuss.com ⏪ 👾Databricks-Certified-Data-Engineer-Professional Valid Exam Notes
- Fast Download Databricks-Certified-Data-Engineer-Professional Valid Exam Voucher - Correct Databricks Certification Training - Marvelous Databricks Databricks Certified Data Engineer Professional Exam 💦 Download 「 Databricks-Certified-Data-Engineer-Professional 」 for free by simply entering { www.pdfvce.com } website ⌛Databricks-Certified-Data-Engineer-Professional Prepaway Dumps
- Databricks-Certified-Data-Engineer-Professional Exam Experience 🛐 Databricks-Certified-Data-Engineer-Professional Latest Test Vce 🛣 Latest Databricks-Certified-Data-Engineer-Professional Exam Bootcamp 🚡 Search for [ Databricks-Certified-Data-Engineer-Professional ] and download it for free on ☀ www.prepawayete.com ️☀️ website 📋Databricks-Certified-Data-Engineer-Professional Dumps Vce
- Databricks-Certified-Data-Engineer-Professional Reliable Learning Materials 🔟 Databricks-Certified-Data-Engineer-Professional Exams Training 🗻 Latest Databricks-Certified-Data-Engineer-Professional Exam Bootcamp 🎻 Search for ➠ Databricks-Certified-Data-Engineer-Professional 🠰 and obtain a free download on ➡ www.pdfvce.com ️⬅️ 🍱Databricks-Certified-Data-Engineer-Professional Study Guide
- Databricks-Certified-Data-Engineer-Professional Reliable Learning Materials 💞 Authorized Databricks-Certified-Data-Engineer-Professional Test Dumps 🧾 Databricks-Certified-Data-Engineer-Professional Practice Guide 😕 Search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ and easily obtain a free download on 「 www.testkingpass.com 」 😃Databricks-Certified-Data-Engineer-Professional Practice Guide
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, app.parler.com, oazwvun.mataroa.blog, issuu.com, scalar.usc.edu, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, blogfreely.net, www.intensedebate.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes