우리ITDumpsKR 사이트에서Anthropic CCAR-P관련자료의 일부 문제와 답 등 샘플을 제공함으로 여러분은 무료로 다운받아 체험해보실 수 있습니다.체험 후 우리의ITDumpsKR에 신뢰감을 느끼게 됩니다.빨리 우리 ITDumpsKR의 덤프를 만나보세요.
| Section | Weight | Objectives |
|---|---|---|
| Solution Design & Architecture | 17% | - Align solutions to business value pillars - Design multi-agent systems and orchestration strategies - Select architectural patterns: workflow, agentic, augmented LLM - Design end-to-end architectures and feedback loops - Translate business problems into Claude-based AI solutions |
| Evaluation, Testing & Optimization | 16% | - Optimize performance, prompting, and model selection - Define evaluation metrics and success criteria - Implement iterative improvement pipelines - Test accuracy, reliability, latency, and cost |
| Developer Productivity & Operational Enablement | 7% | - Configure Claude tools and environments for teams - Improve developer workflows with AI-assisted tooling - Support debugging, monitoring, and operational resolution |
| Stakeholder Communication & Lifecycle Management | 14% | - Conduct structured discovery and requirement gathering - Document architectures and support full lifecycle phases - Manage stakeholder feedback and expectation alignment - Communicate architectural decisions and trade-offs |
| Governance, Safety & Risk Management | 14% | - Manage data privacy and security compliance - Ensure regulatory compliance (GDPR, HIPAA, etc.) - Implement guardrails and safety controls - Address ethical AI considerations and bias mitigation |
| Claude Models, Prompting & Context Engineering | 13% | - Mitigate prompt injection, leaks, and jailbreak risks - Select appropriate Claude models based on trade-offs - Design system prompts, templates, and guardrails - Apply context engineering and context management techniques |
| Integration | 19% | - Integrate Claude with enterprise systems, APIs, and tools - Implement Model Context Protocol (MCP) integrations - Design authentication, authorization, and observability - Integrate with data pipelines and RAG systems |
ITDumpsKR 에서 제공해드리는 Anthropic인증CCAR-P시험덤프자료를 구입하시면 퍼펙트한 구매후 서비스를 약속드립니다. ITDumpsKR에서 제공해드리는 덤프는 IT업계 유명인사들이 자신들의 노하우와 경험을 토대로 하여 실제 출제되는 시험문제를 연구하여 제작한 최고품질의 덤프자료입니다. Anthropic인증CCAR-P시험은ITDumpsKR 표Anthropic인증CCAR-P덤프자료로 시험준비를 하시면 시험패스는 아주 간단하게 할수 있습니다. 구매하기전 PDF버전 무료샘플을 다운받아 공부하세요.
질문 # 129
A business sponsor has requested an AI solution to "improve customer experience." The sponsor cannot articulate which customer journey is failing, which metric reflects the failure, or which decisions the AI should support. The sponsor is asking you to begin design work next week.
Which delegation-competency action should you take first?
정답:D
설명:
The request is not yet design-ready because it lacks a defined failure, affected user journey, supported decision, target population, and measurable outcome. The architect should therefore facilitate structured discovery rather than prematurely selecting an AI pattern or model.
Discovery should identify where the current customer journey breaks down, who experiences the problem, what decision or task requires assistance, what data is available, and which metric would demonstrate improvement. The team can then establish baseline performance, target thresholds, operational constraints, risks, and explicit non-goals. Anthropic's evaluation guidance states that an LLM application should begin with clearly defined success criteria and a method for measuring them. Define Success Criteria and Build Evaluations Option A abandons the sponsor instead of helping translate a business concern into an actionable problem.
Option B risks producing a generic demonstration unrelated to a validated customer need. Option C substitutes the architect's assumptions for stakeholder evidence and may commit the organization to the wrong scope.
Competent delegation begins by defining the decision, intended outcome, authority boundaries, and target metric before determining which responsibilities should be assigned to Claude, conventional software, or human reviewers.
Study Guide references/topics: Structured discovery; delegation competency; problem definition; target metrics; decision support; measurable business outcomes.
질문 # 130
You are sequencing decomposed components in an invoice-processing pipeline.
For each of the decomposed components, select the execution layer it belongs to: "Pre-Processing," "Model Stage," or "Post-Processing."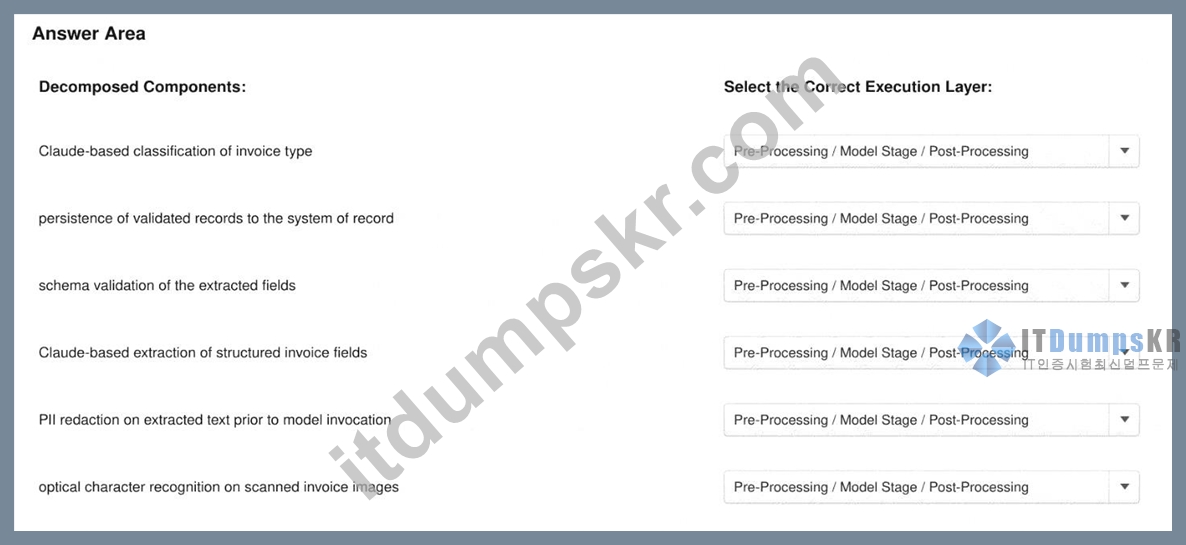
정답:
설명: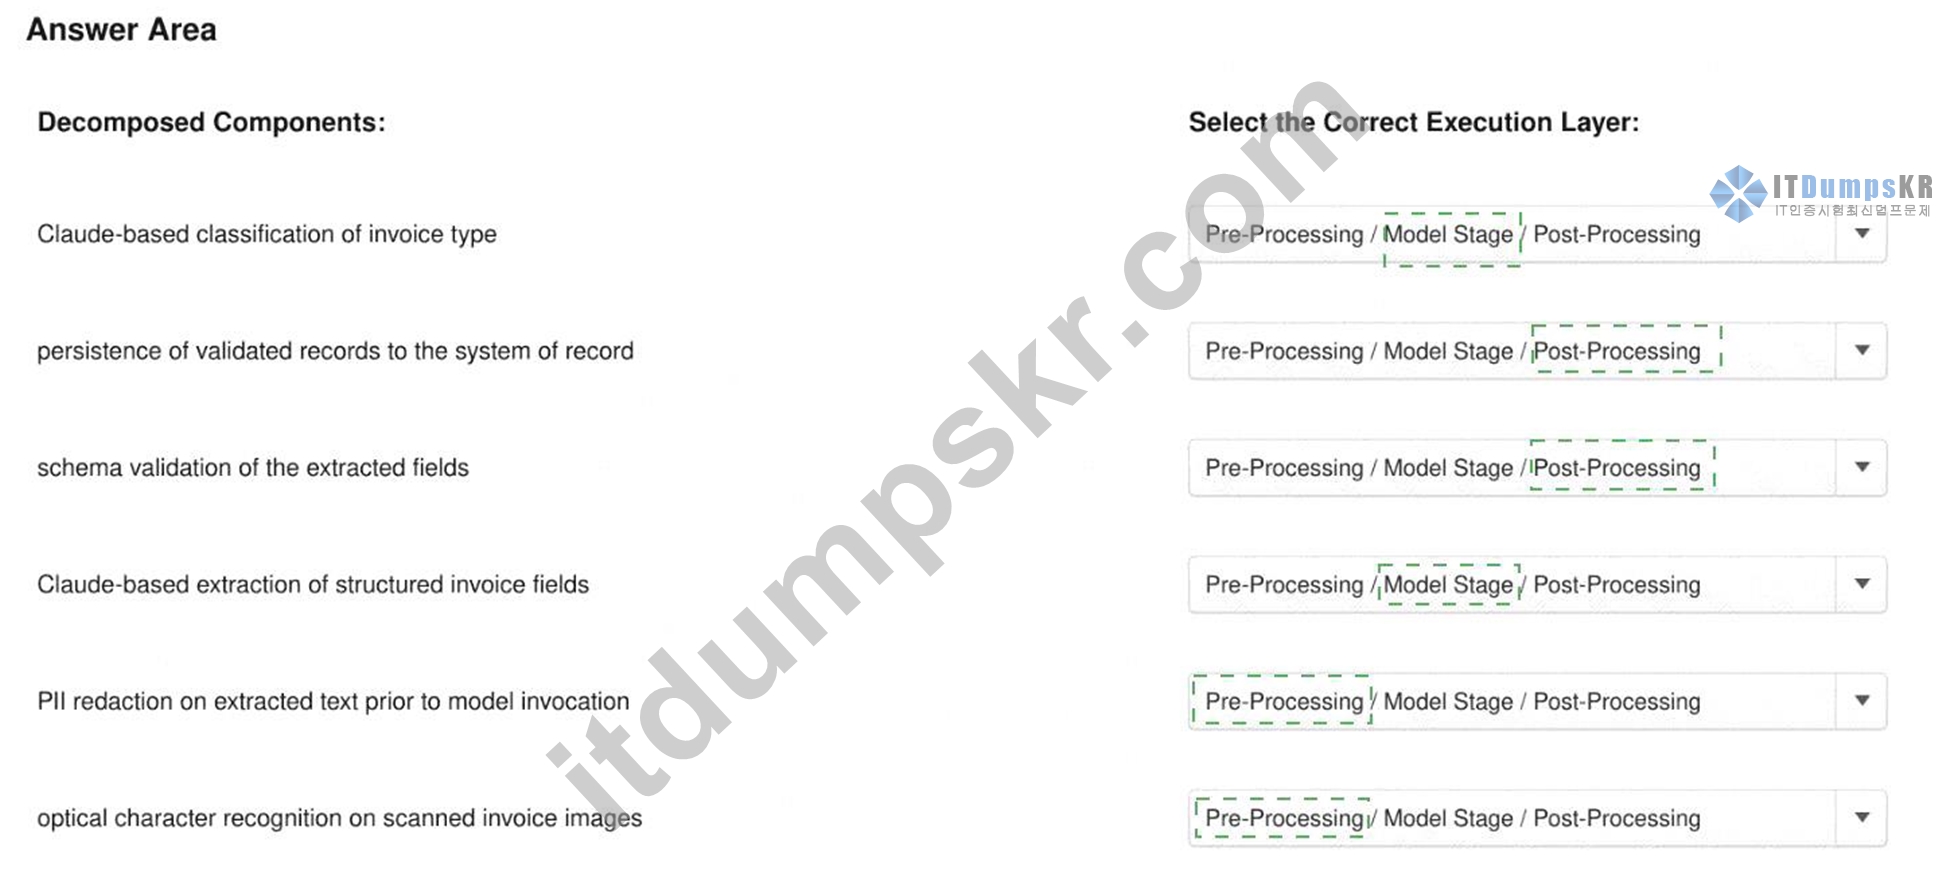
Explanation:
Model Stage, Post-Processing, Post-Processing, Model Stage, Pre-Processing, Pre-Processing Pre-processing prepares source material before Claude receives it. Optical character recognition converts scanned invoice images into machine-readable text. Because PII redaction is explicitly performed before model invocation, it also belongs in pre-processing. Additional activities at this layer can include file validation, malware scanning, normalization, page separation, and metadata extraction.
The model stage contains tasks requiring Claude's language-understanding capability. Classifying the invoice type involves interpreting textual and contextual features, while extracting structured invoice fields requires mapping unstructured content into defined business attributes.
Post-processing verifies and commits the model's result. Schema validation confirms that required fields exist, data types are correct, enumerated values are permitted, and structural constraints are satisfied.
Persistence must occur only after validation and any required human review because the system of record should not receive malformed or unapproved model output.
This decomposition separates probabilistic inference from deterministic processing. OCR, redaction, validation, and persistence do not need to be delegated to Claude when conventional components can execute them more predictably. The resulting architecture reduces model workload, strengthens privacy controls, improves auditability, and prevents unvalidated output from directly changing authoritative records.
Study Guide references/topics: Task decomposition; pre-processing; model inference; post-processing; deterministic validation; privacy-by-design; system-of-record protection.
질문 # 131
A Claude Architect is reviewing a post-deployment performance report for an AI-assisted legal-document summarization system. The report includes these observations:
* Average summarization time decreased from 47 minutes to 6 minutes per document.
* Associates spend less time on summaries, but overall billable output has not measurably changed.
* Infrastructure costs increased by 22% because redundant retry logic generated additional API calls.
* Some summaries require attorney correction, adding an average of 8 minutes of review per document.
Which analysis correctly attributes each observation to the appropriate business-value pillar?
정답:A
설명:
Observation 1 is a direct efficiency improvement because the time required for one summarization task fell substantially. Observation 2 shows that local time savings have not yet translated into higher organizational productivity or billable output. Observation 3 is explicitly a solution-cost problem caused by unnecessary API calls. Observation 4 introduces additional human correction time and therefore partially offsets the gross efficiency gain reported in Observation 1. Option D is the only answer that keeps these value dimensions distinct. Measuring only generation speed would overstate realized value because review effort, retry costs, and downstream output must also be included. A valid post-deployment assessment should calculate net cycle time, cost per accepted summary, correction rate, and resulting business output.
질문 # 132
You are evaluating model-selection claims used by a peer team.
For each statement, select yes if the statement is generally true. Otherwise, select no.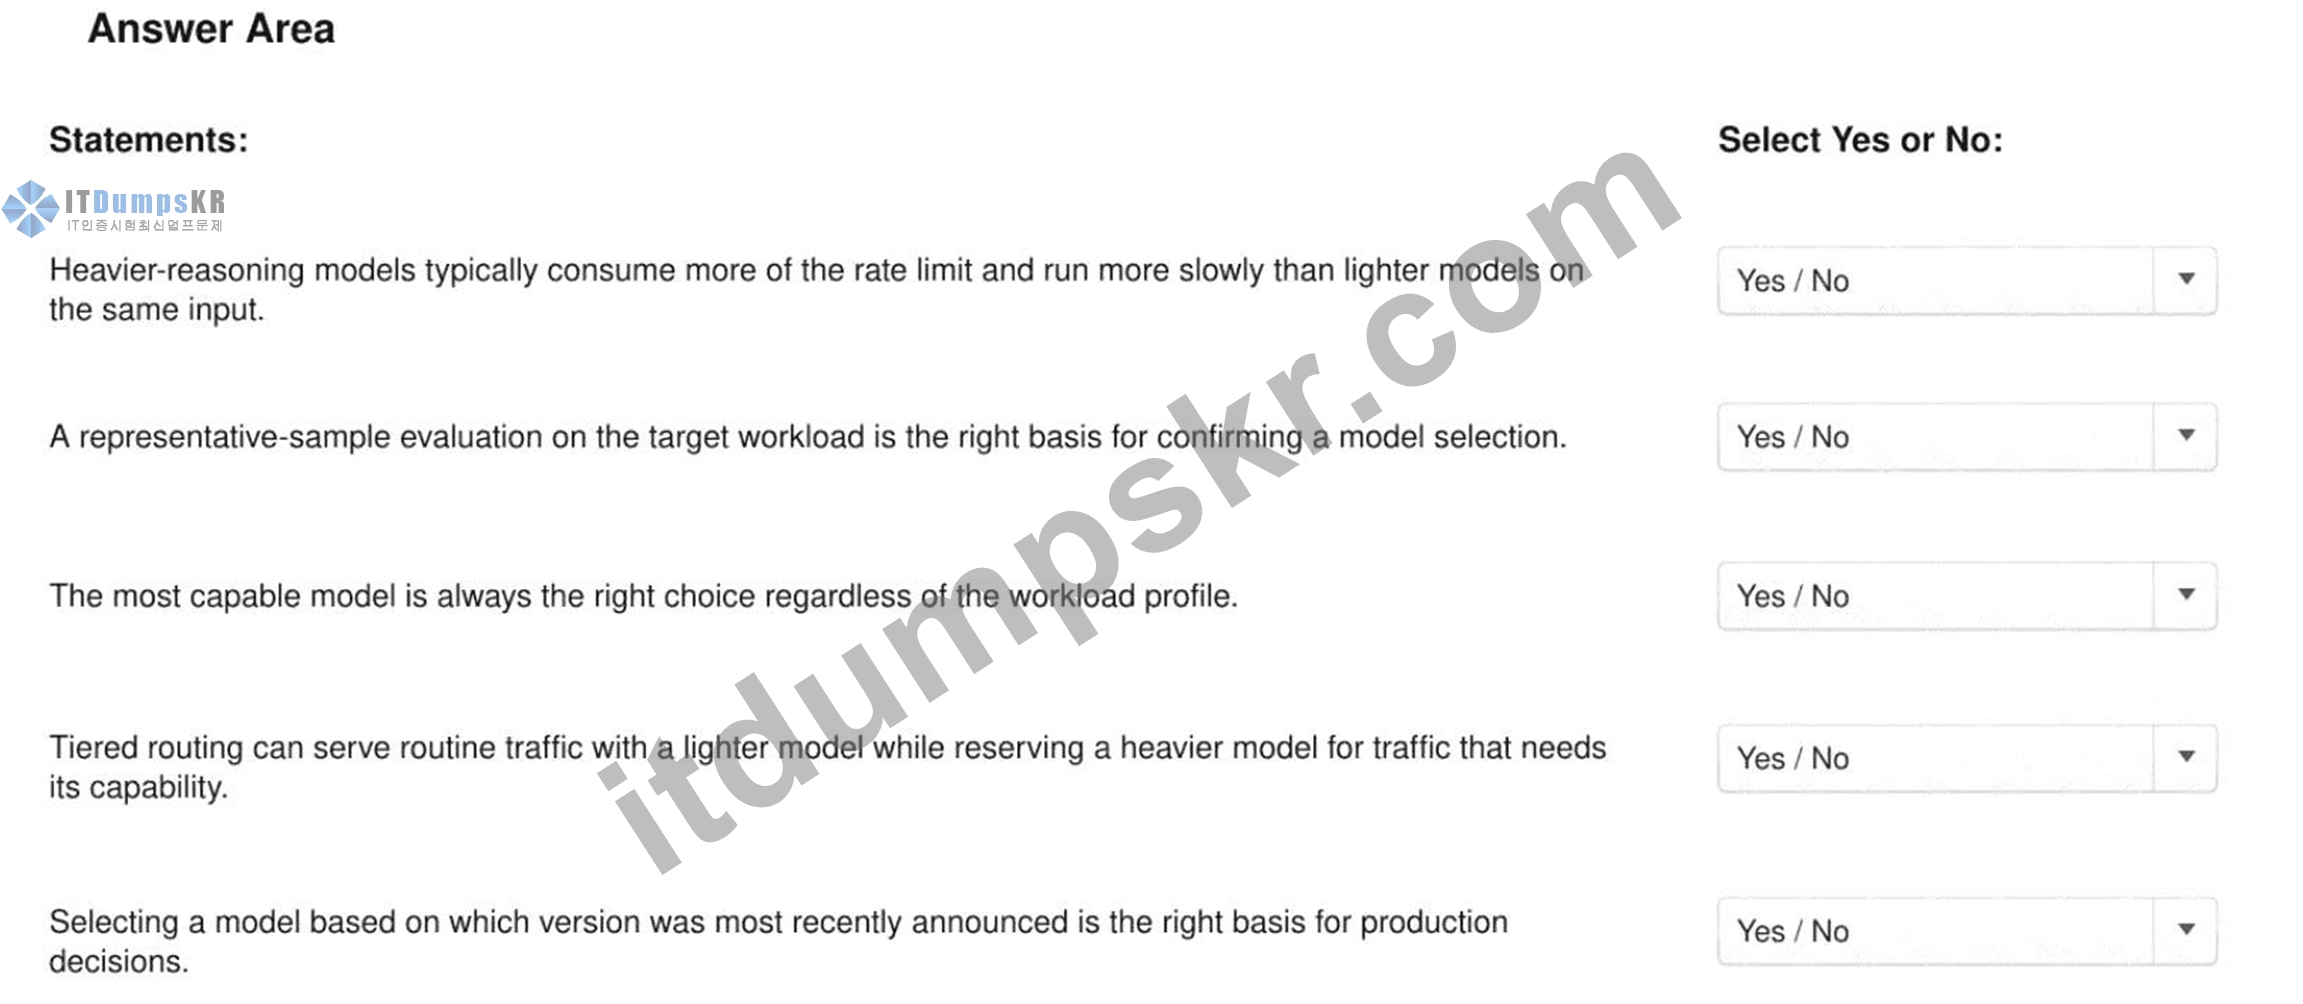
정답:
설명: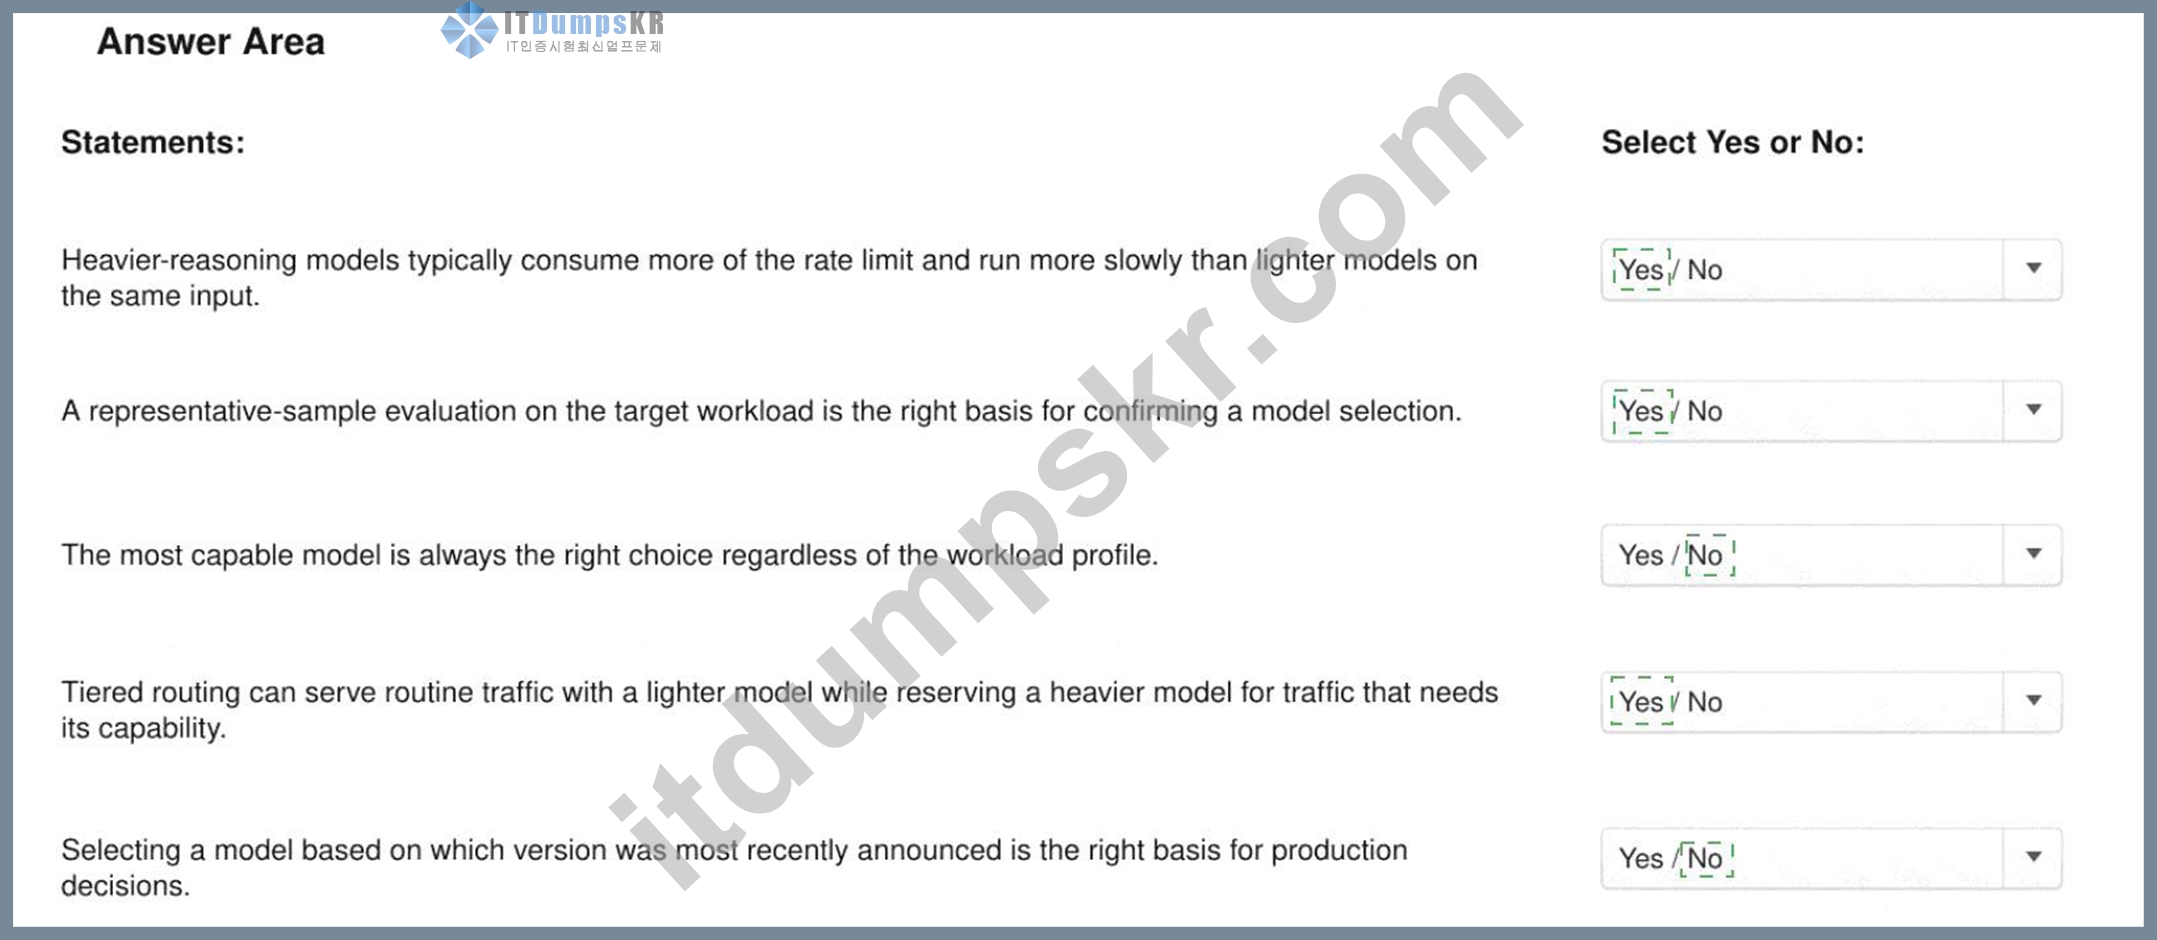
Explanation:
Yes, Yes, No, Yes, No
More capable reasoning configurations generally require greater computation, produce higher latency, and may consume larger token or rate-limit allocations than lighter alternatives. This makes the first statement generally accurate, although actual performance must be measured under the organization's specific provider and service tier.
Representative workload testing is essential because generic benchmark rankings do not establish performance on the organization's prompts, data, edge cases, tools, or required output format. Anthropic recommends benchmark tests specific to the use case, using actual prompts and data, followed by comparison of accuracy, quality, edge-case behavior, and cost. Choosing the Right Model The strongest model is not automatically the correct production choice. Model selection must balance capability, speed, cost, throughput, and operational constraints. Tiered routing implements this principle by serving predictable requests with an efficient model and escalating difficult cases to a more capable model.
Anthropic documents multi-model strategies in which lower-cost workers handle most traffic while harder decisions are escalated.
Recency is also not a valid selection criterion. A newly announced model must pass the workload's existing evaluation, security, latency, and cost gates before replacing a validated production model.
Study Guide references/topics: Model trade-offs; representative evaluations; tiered routing; escalation architectures; cost-capability optimization; model migration validation.
질문 # 133
A security audit uncovers two issues: (1) all end users share a single API key, and (2) tool calls are executed without logging the initiating user.
Which two mitigations directly address these specific findings? (Select two.)
정답:B,C
설명:
Per-user, scope-restricted OAuth tokens directly eliminate the shared-credential weakness. Each token represents a distinct user or delegated identity, carries only the permissions required for that user's role, and can be revoked independently. This supports least privilege, limits the blast radius of credential compromise, and enables authorization decisions to be tied to a specific principal instead of an undifferentiated shared API key.
Actor attribution in tool-call logs directly resolves the second finding. Each audit event should record the authenticated user, delegated service identity, session or request identifier, tool name, authorization decision, relevant resource, timestamp, and outcome. This establishes accountability and permits incident investigators to reconstruct who initiated a consequential action.
Moving credentials into a server-side secret store is sound secret-management practice, but it does not by itself correct the shared-identity problem: a centrally stored key can still represent every user as the same principal. Schema validation protects downstream processing, while retrieval-layer RBAC protects information access; neither addresses the two specific audit findings.
These controls should be reinforced by short-lived tokens, server-side authorization enforcement, sensitive- field redaction, and tamper-resistant audit-log retention.
Study Guide references/topics: [Claude Code security](https://docs.anthropic.com/en/docs/claude-code
/security); [MCP authentication and OAuth] (https://docs.anthropic.com/en/docs/claude-code/mcp); least privilege; identity propagation; auditable tool execution.
질문 # 134
......
우리 ITDumpsKR 에는 최신의Anthropic CCAR-P학습가이드가 있습니다. ITDumpsKR의 부지런한 IT전문가들이 자기만의 지식과 끊임없는 노력과 경험으로 최고의Anthropic CCAR-P합습자료로Anthropic CCAR-P인증시험을 응시하실 수 있습니다.Anthropic CCAR-P인증시험은 IT업계에서의 비중은 아주 큽니다. 시험신청하시는분들도 많아지고 또 많은 분들이 우리ITDumpsKR의Anthropic CCAR-P자료로 시험을 패스했습니다. 이미 패스한 분들의 리뷰로 우리ITDumpsKR의 제품의 중요함과 정확함을 증명하였습니다.
CCAR-P합격보장 가능 시험: https://www.itdumpskr.com/CCAR-P-exam.html