BTW, DOWNLOAD part of CertkingdomPDF AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1W9dPfIFo2zM9MxaEBZsbypcGGoytqkpI
As we all know, time for preparing a exam is quite tight. Once you have signed up for the exam, you need to prepare. Therefore improving the efficiency is quite necessary. Our AI-300 training materials include the main knowledge point of the exam, which will help you to know the main knowledge. Besides the professionals check the AI-300 at time, it can ensure the accuracy of the answers. Therefore, please make it easy to use the AI-300 training materials freely.
| Section | Objectives |
|---|---|
| Topic 1: Implement generative AI quality assurance and observability | - Monitor latency, token usage, cost, and error rates - Conduct red teaming, adversarial testing, and content filtering - Evaluate generative AI outputs for quality, safety, and grounding - Implement logging, tracing, and telemetry for GenAI applications |
| Topic 2: Optimize generative AI systems and model performance | - Tune prompts, system messages, and grounding strategies - Implement cost management and scaling strategies for GenAI workloads - Fine-tune and distill models for specific use cases - Optimize inference performance, caching, and throughput |
| Topic 3: Implement machine learning model lifecycle and operations | - Retrain, update, and manage model versions in production - Train, register, and version models using Azure Machine Learning - Deploy models to real-time and batch endpoints - Monitor model performance, data drift, and operational health |
| Topic 4: Design and implement an MLOps infrastructure | - Manage environments, data stores, and model registries - Configure source control, CI/CD pipelines, and automation for ML workflows - Implement security, governance, and compliance for MLOps - Set up Azure Machine Learning workspace and compute targets |
| Topic 5: Design and implement a GenAIOps infrastructure | - Configure prompt orchestration, prompt flows, and agent frameworks - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search - Manage API keys, rate limits, and responsible AI guardrails - Set up Microsoft Foundry and Azure AI services for generative AI workloads |
It is our biggest goal to try to get every candidate through the exam. Although the passing rate of our AI-300 study materials is nearly 100%, we can refund money in full if you are still worried that you may not pass. You don't need to worry about the complexity of the refund process at all, we've made it quite simple. As long as you provide us with proof that you failed the exam after using our AI-300 Study Materials, we can refund immediately.
NEW QUESTION # 180
You are monitoring a fine-tuned large language model deployed in Microsoft Foundry.
You evaluate the model before and after fine-tuning by using the same evaluation dataset.
You review the following evaluation results: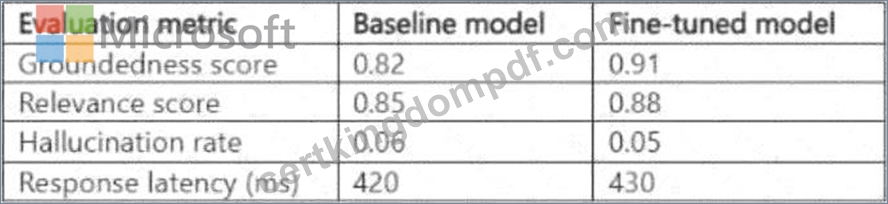
You need to determine whether the fine-tuned model shows improved performance without introducing regression.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.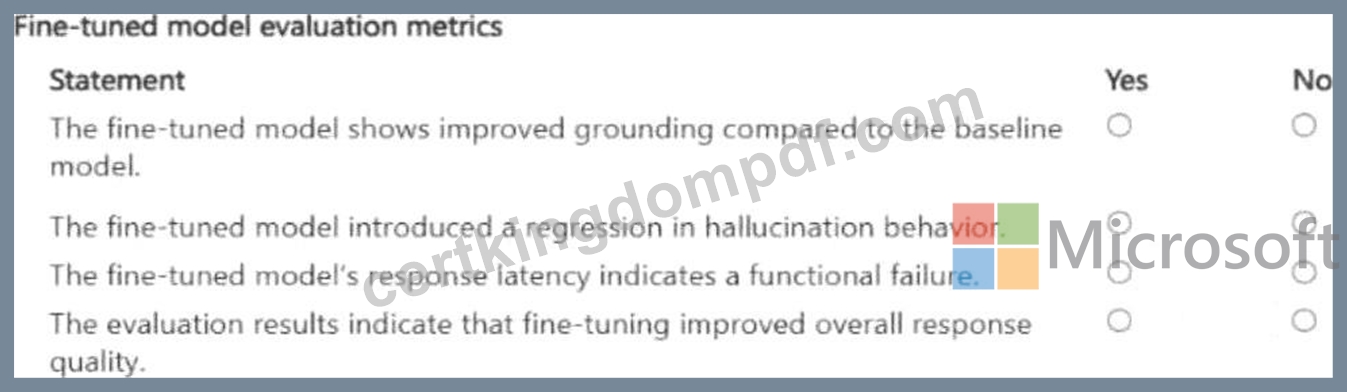
Answer:
Explanation: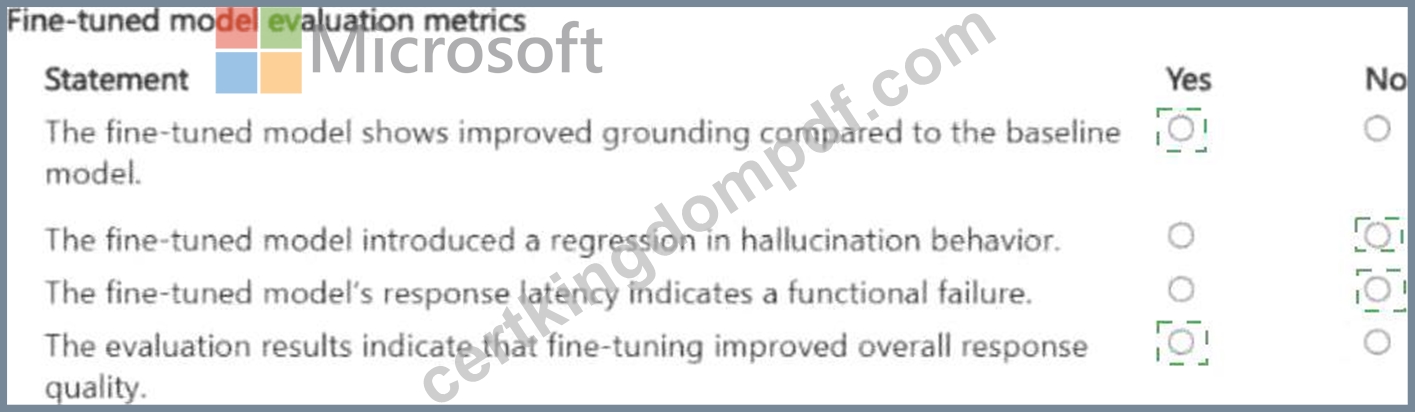
Explanation:
When evaluating a fine-tuned model against the base model using the same evaluation dataset, the interpretation of each metric requires careful analysis. A statement that the fine-tuned model improves on the target task is True if and only if the target metric such as task-specific accuracy, F1 score, or ROUGE score shows a statistically meaningful improvement. A statement about regression on a complementary metric is True if the fine-tuned model ' s score on that metric is meaningfully lower than the base model ' s. In Microsoft Foundry ' s evaluation framework, both pre-fine-tuning and post-fine-tuning results are stored against the same experiment, enabling direct side-by-side comparison. The core principle is that improvement on the primary task is not sufficient if fine-tuning causes degradation on safety or coherence - this is called catastrophic forgetting, and the evaluation dataset is designed to detect it.
Microsoft Learn Reference Topic: Evaluate fine-tuned models in Microsoft Foundry - Compare base and fine-tuned model metrics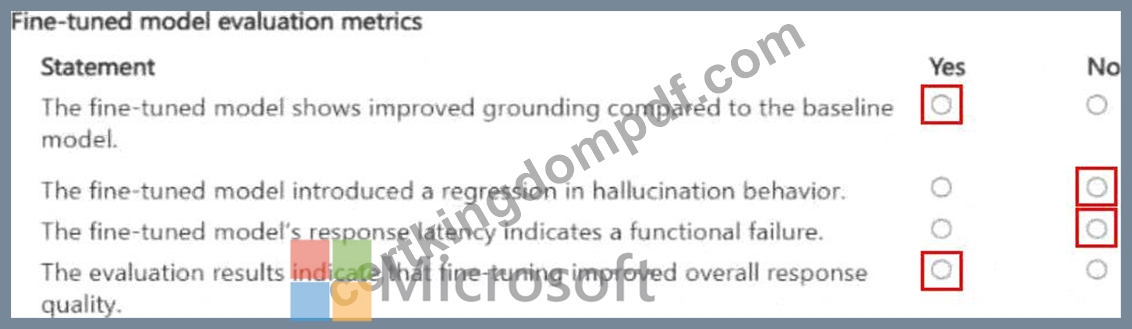
NEW QUESTION # 181
Drag and Drop Question
An organization uses Microsoft Foundry to develop generative AI projects that access shared Azure resources such as storage accounts and vector databases.
The organization s security policy requires eliminating secret key-based authentication and enforcing least-privilege access.
You must configure identity and access so that:
Services authenticate without stored credentials.
Permissions are scoped appropriately across projects and shared resources.
You need to configure the appropriate identity or access mechanism for each requirement.
What should you configure in Microsoft Foundry to meet each requirement? To answer, move the appropriate configuration mechanisms to the correct requirements. You may use each configuration mechanism once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.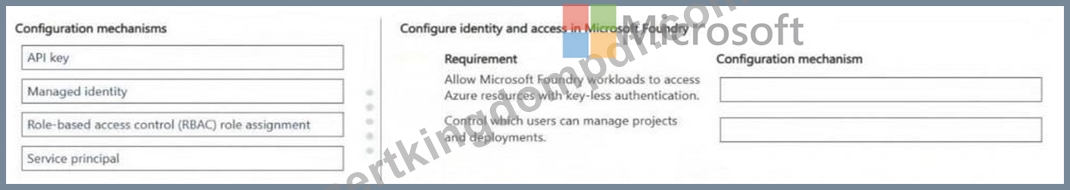
Answer:
Explanation: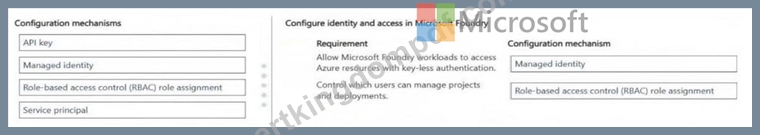
NEW QUESTION # 182
Hotspot Question
You manage an Azure Machine Learning workspace. You configure an automated machine learning regression training job by using the Azure Machine Learning Python SDK v2.
You configure the regression job by using the following script: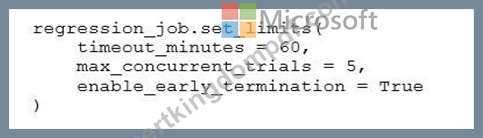
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.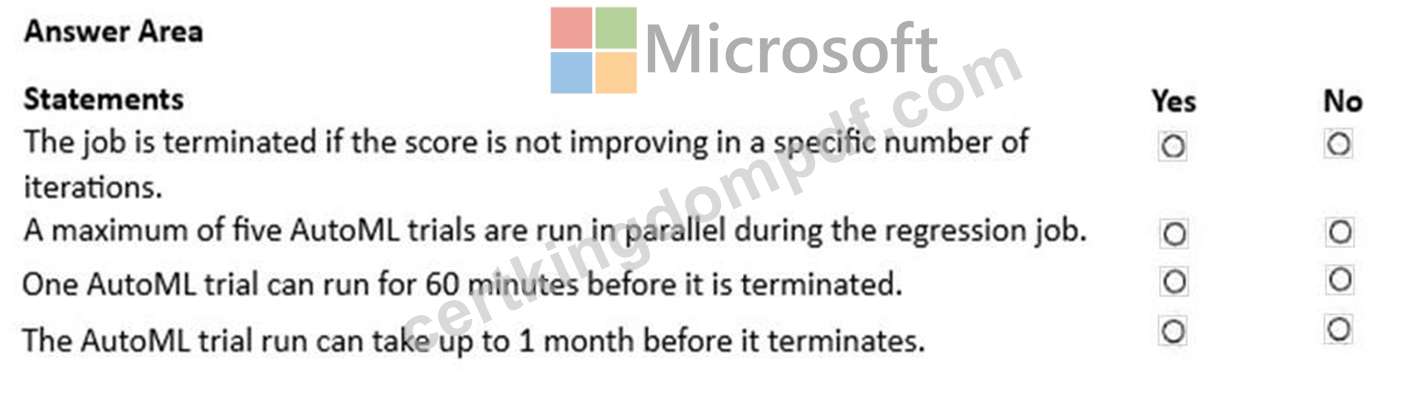
Answer:
Explanation: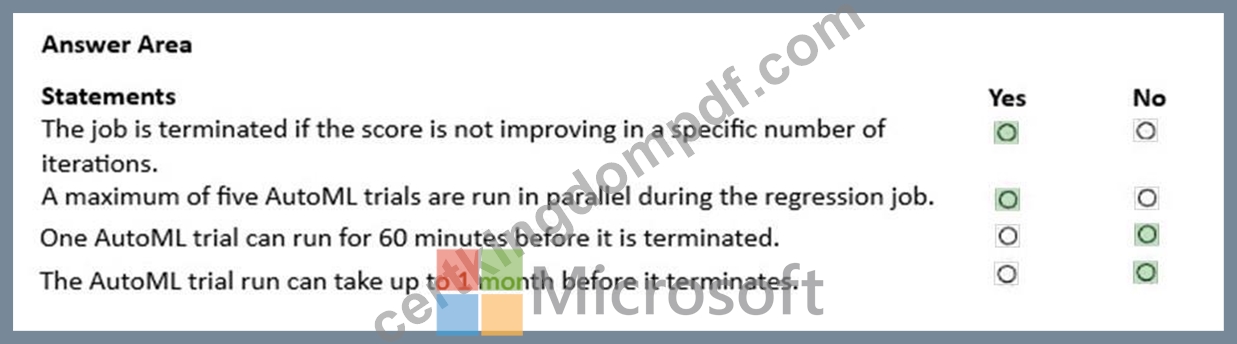
Explanation:
Box 1: Yes
Yes, the automated machine learning (AutoML) training job will terminate early if the primary metric score stops improving after a specific number of iterations.
According to the official Microsoft Azure Machine Learning SDK v2 documentation, setting enable_early_termination = True activates the early stopping policy for the overall experiment.
How Early Termination Works in AutoML v2
The internal early stopping logic operates on a built-in schedule to avoid premature termination:
First 20 iterations: No early stopping takes place (these serve as landmarks).
From the 21st iteration onward: The early stopping window activates.
Termination trigger: The job will automatically stop if the primary evaluation score fails to improve across 10 consecutive iterations.
Box 2: Yes
Yes, a maximum of five trials can run at the same time.
The limit comes from the code settings.
The max_concurrent_trials = 5 line tells Azure to run up to five trials at once.
Box 3: No
No, a single AutoML trial cannot run for 60 minutes before it is terminated.
Parameter Breakdown
In the Azure Machine Learning Python SDK v2, the set_limits() method handles timeouts via two distinct parameters:timeout_minutes = 60: This sets the maximum duration for the entire AutoML job (the experiment as a whole), including data preparation, featurization, and all training trials combined.
trial_timeout_minutes: This parameter governs the maximum time allowed for an individual trial (a single model training run) before termination.
Conclusion
Because trial_timeout_minutes is omitted from your script, it defaults to its standard system value (which is typically 20 minutes for tabular datasets). Therefore, an individual trial will time out much earlier than 60 minutes. Additionally, since the entire job terminates at 60 minutes, it is physically impossible for a single trial to consume the full 60 minutes without forcing the termination of the remaining concurrent runs.
Box 4: No
No, the AutoML trial cannot take up to 1 month before it terminates.
Based on the script parameters, the job will terminate after a maximum of 60 minutes.
Reference:
https://learn.microsoft.com/en-us/python/api/azure-ai-ml/azure.ai.ml.automl.regressionjob?view=azure-python
NEW QUESTION # 183
You use Azure Machine Learning to train models across multiple experiments by using the same workspace.
You must record training runs in a centralized location to compare results from different jobs.
During training, performance values must be captured so they appear in the experiment run history.
You need to configure experiment tracking.
What should you configure for each requirement? To answer, select the appropriate options in the answer area
. NOTE: Each correct selection is worth one point.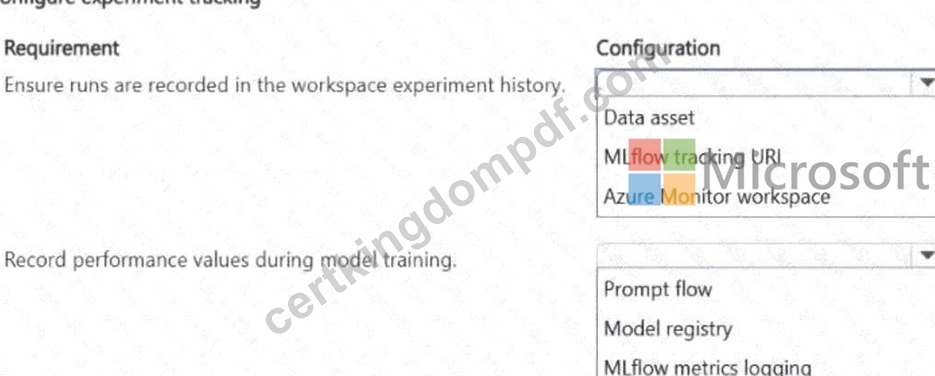
Answer:
Explanation: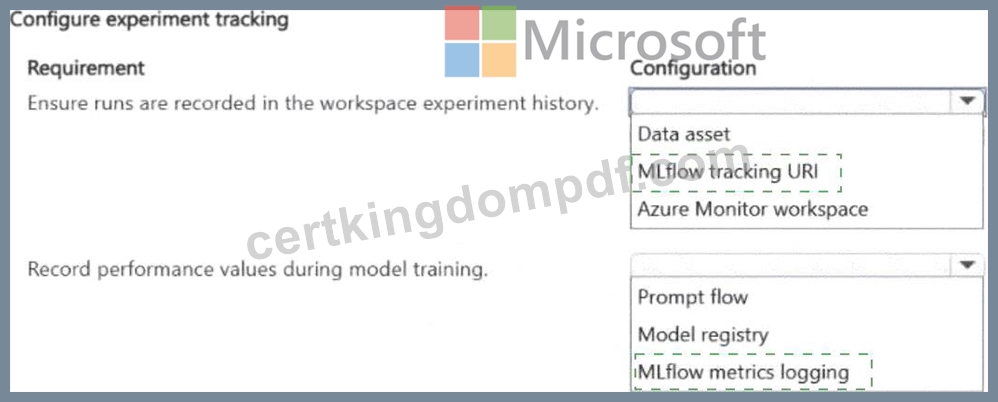
Explanation:
Azure Machine Learning ' s experiment tracking is built around two complementary concepts. First, experiments are named containers that group related runs. By calling mlflow.set_experiment with an experiment name at the start of your training code, all subsequent runs are grouped under that experiment name in the AML workspace, creating the centralized record required. Second, metrics are scalar values such as accuracy, loss, or AUC that represent model performance. Calling mlflow.log_metric with a metric name and value during training persists these values to the run ' s record in the experiment history. These values appear on the Azure ML Studio run detail page and can be compared across runs using the experiment comparison view. Without set_experiment, runs fall into a default experiment. Without log_metric, the run history has no performance data to display or compare.
Microsoft Learn Reference Topic: Track machine learning experiments with MLflow in Azure Machine Learning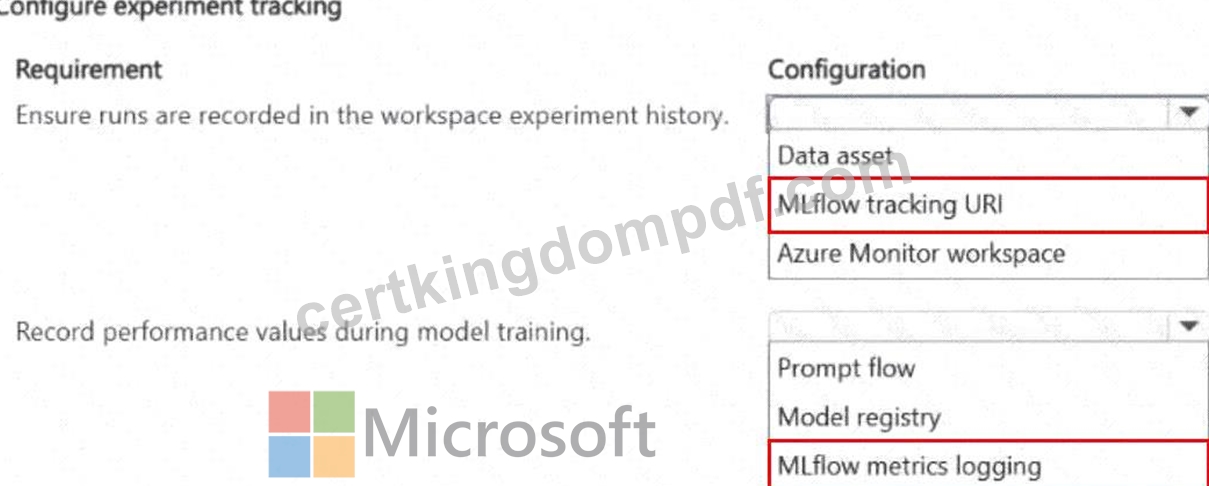
NEW QUESTION # 184
You need to run large-scale inference jobs on millions of records periodically. Jobs are not latency-sensitive but must be cost-efficient and scalable. Which deployment option is MOST appropriate?
Answer: B
Explanation:
Batch endpoints are optimized for large-scale, asynchronous inference workloads. They efficiently process large datasets and scale based on demand, making them cost-effective for non-real-time scenarios. Online endpoints are designed for low-latency use cases and are more expensive for batch processing.
NEW QUESTION # 185
......
The real and updated CertkingdomPDF Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam dumps file, desktop practice test software, and web-based practice test software are ready for download. Take the best decision of your professional career and enroll in the Operationalizing Machine Learning and Generative AI Solutions (AI-300) certification exam and download CertkingdomPDF Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam questions and starts preparing today.
Test AI-300 Engine Version: https://www.certkingdompdf.com/AI-300-latest-certkingdom-dumps.html
2026 Latest CertkingdomPDF AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=1W9dPfIFo2zM9MxaEBZsbypcGGoytqkpI