What's more, part of that ExamDiscuss AI-103 dumps now are free: https://drive.google.com/open?id=1XmCJODzf_x6CMI11Uvk3Sgw4F35pJIP_
It is universally accepted that in this competitive society in order to get a good job we have no choice but to improve our own capacity and explore our potential constantly, and try our best to get the related AI-103 certification is the best way to show our professional ability, however, the AI-103 Exam is hard nut to crack but our AI-103 preparation questions are closely related to the exam, it is designed for you to systematize all of the key points needed for the AI-103 exam.
| Section | Objectives |
|---|---|
| Plan and Manage Azure AI Solutions | - Azure AI resource provisioning and configuration - Responsible AI principles and governance - Model selection and lifecycle management |
| Implement Computer Vision Solutions | - Image classification and object detection - OCR and document intelligence |
| Develop Generative AI Applications and Agents | - AI agents architecture
|
| Implement Natural Language Processing Solutions | - Text analytics and summarization - Language understanding and intent recognition - Translation and multilingual support |
| Knowledge Mining and Information Retrieval | - RAG (Retrieval Augmented Generation) patterns - Azure AI Search configuration - Indexing and semantic search |
>> New AI-103 Exam Objectives <<
Perhaps you still have doubts about our AI-103 study tool. You can contact other buyers to confirm. Our company always regards quality as the most important things. The pursuit of quantity is meaningless. Our company positively accepts annual official quality inspection. All of our AI-103 real exam dumps have passed the official inspection every year. Our study materials are completely reliable and responsible for all customers. The development process of our study materials is strict. We will never carry out the AI-103 Real Exam dumps that are under researching. All AI-103 study tool that can be sold to customers are mature products. We are not chasing for enormous economic benefits. As for a company, we are willing to assume more social responsibility.
NEW QUESTION # 81
You have a chat app in a Microsoft Foundry project and an Azure AI Search vectorized index.
You need to connect to the index to meet the following requirements:
- Complex questions must retrieve information from multiple chunks.
- Multi-turn conversations must influence retrieval planning.
- Retrievals must run in parallel to reduce latency.
Which retrieval approach should you use?
Answer: A
Explanation:
An agentic Retrieval-Augmented Generation (RAG) architecture is the best fit for your requirements. Traditional, linear RAG pipelines struggle with complex, multi-turn dependencies, whereas an agentic approach natively solves them through iterative reasoning and tool orchestration.
Here is how an agentic RAG pattern specifically satisfies each the three technical requirements:
1. Complex Questions & Multi-Chunk Retrieval
The Challenge: Complex questions often require aggregating distinct pieces of information scattered across different documents or sections.
The Agentic Solution: An agent uses a Reasoning and Acting (ReAct) loop. It evaluates the user's query, breaks it down into sub-questions, and executes multiple distinct search queries. It then synthesizes the information from these diverse chunks before generating a final response.
2. Multi-Turn Conversations & Retrieval Planning
The Challenge: Standard RAG often just passes the latest user message or a simple chat history summary to the search index, which can lose context or misinterpret the user's true intent in long conversations.
The Agentic Solution: The agent acts as a query planner. It maintains the state of the conversation and dynamically decides if a retrieval is needed, what specific keywords or vectors to target based on past turns, and how to reformulate the query to bridge context gaps.
3. Parallel Retrievals for Low Latency
The Challenge: Sequential lookups drastically increase time-to-first-token (TTFT), harming the chat user experience.
The Agentic Solution: Modern AI agent frameworks allow the LLM to emit multiple tool calls simultaneously. The application layer can intercept these calls and execute parallel asynchronous queries against your Azure AI Search vectorized index, drastically minimizing latency.
Reference:
https://arxiv.org/html/2501.09136v1
NEW QUESTION # 82
Hotspot Question
You have a Python application collects customer comments before posting them to a public forum.
You need to send a text comment to Azure AI Content Safety and return the self-harm severity from the response.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.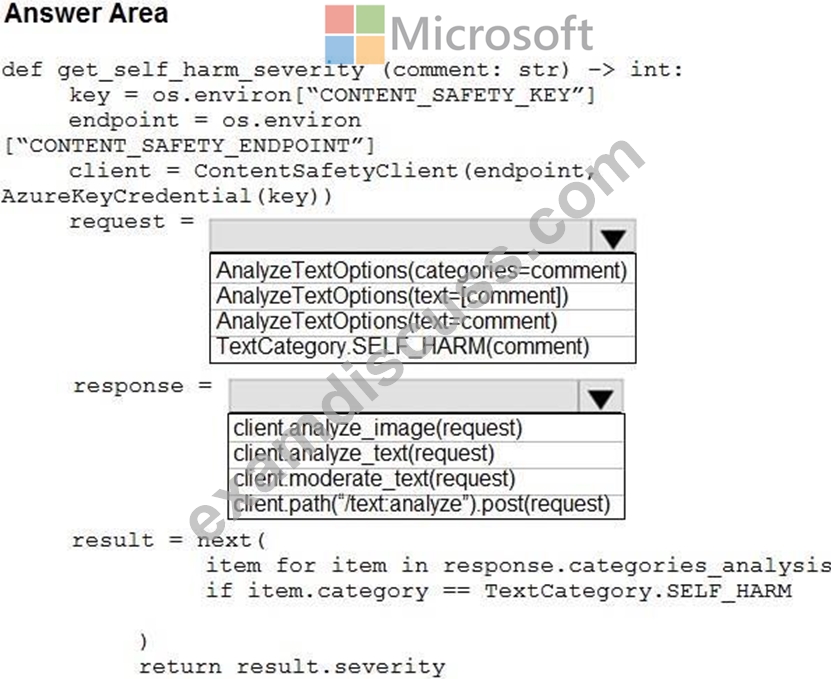
Answer:
Explanation: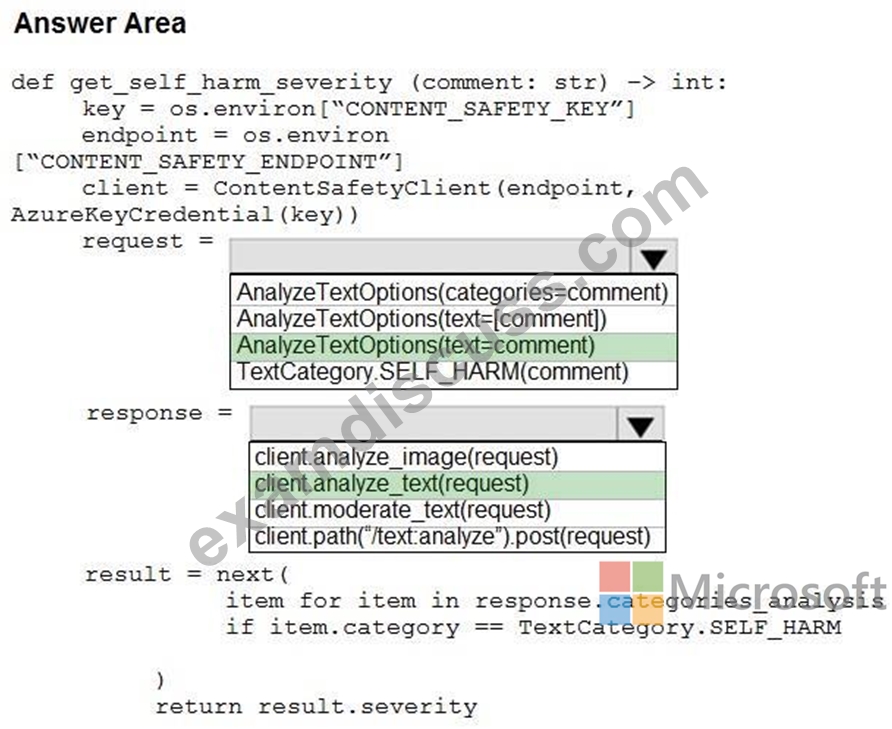
Explanation:
Box 1: AnalyzeTextOptions(text=comment)
To set up the request in your Python script, you must use AnalyzeTextOptions(text=comment), passing the text as a single string rather than a list.
Example:
Build the request options focusing on Text analysis
# You can optionally restrict analysis to specific categories
request_options = AnalyzeTextOptions(
text=user_comment,
categories=[TextCategory.SELF_HARM]
Box 2: client.analyze_text(request)
You must use client.analyze_text(request)
1. Send the request: Call client.analyze_text(request) to retrieve the multi-severity results.
2. Extract the self-harm result: Locate the self-harm categories from the response list.
3. Return the severity: Access the .severity attribute
Reference:
https://learn.microsoft.com/en-us/python/api/overview/azure/ai-contentsafety-readme
NEW QUESTION # 83
You have a Microsoft Foundry project that contains an agent.
The agent accepts user-uploaded screenshots and uses a multimodal chat model.
Some screenshots contain potentially malicious embedded text.
You need to prevent a prompt injection attack and ensure that third-party content is treated as lower trust.
How should you configure prompt shields for document attacks? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.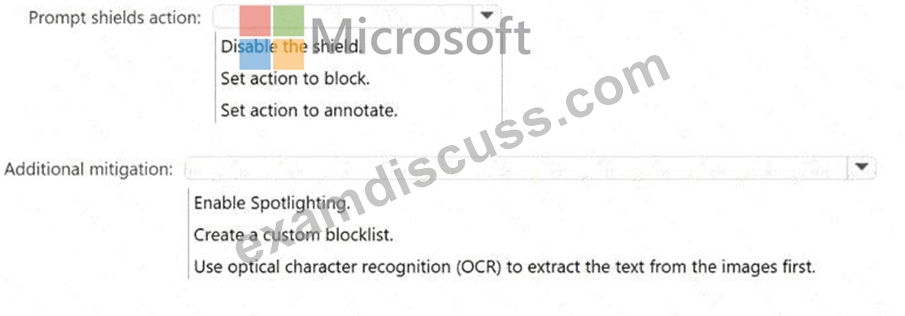
Answer:
Explanation: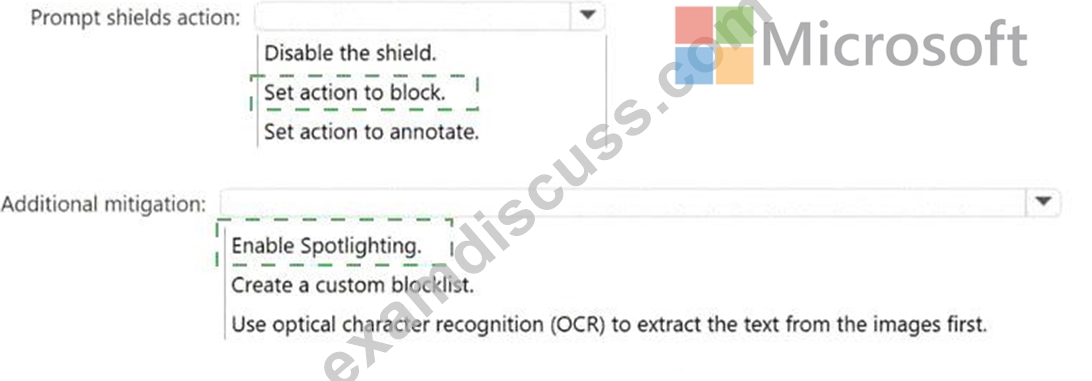
Explanation:
Prompt shields action: Set action to block.
Additional mitigation: Enable Spotlighting.
The correct configuration is to set the Prompt Shields document attack action to block and enable Spotlighting . Prompt Shields in Microsoft Foundry are designed to detect attempts to manipulate model behavior through adversarial input. Microsoft distinguishes document attacks from direct user prompt attacks:
document attacks are malicious instructions embedded in third-party content such as documents, webpages, emails, or other externally supplied material. In this scenario, the embedded text inside uploaded screenshots is third-party content and can attempt to override the agent's instructions. Setting the action to block prevents detected document-attack content from being processed normally, which is required because the goal is prevention rather than passive logging or annotation.
Spotlighting is the additional mitigation because it marks or transforms document content so the model treats it as lower trust than system and user instructions. Microsoft's Foundry guidance describes Spotlighting as a Prompt Shields subfeature that helps protect against indirect or embedded document attacks by tagging input documents with special formatting to indicate lower trust. A custom blocklist is insufficient for unknown attacks, and OCR alone only extracts the malicious text; it does not mitigate prompt injection. Reference topics: Prompt Shields, document attacks, guardrails, Spotlighting, multimodal safety, and prompt injection defense.
NEW QUESTION # 84
Hotspot Question
You have a Microsoft Foundry project.
- You need to create a customer support agent that meets the following
requirements:
- Grounds responses only in company policy documents stored in curated
repositories
- Retains customer preferences across separate chat sessions
How should you configure the agent? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.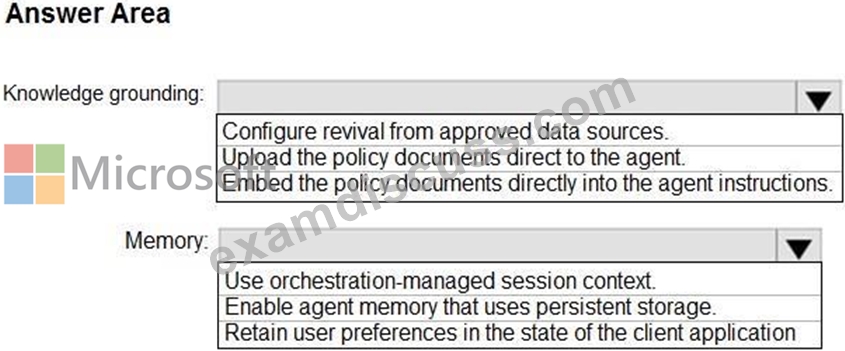
Answer:
Explanation: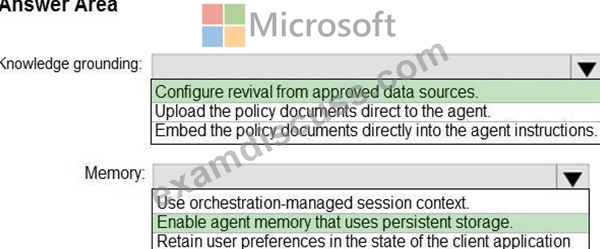
Explanation:
Box 1: Configure retrieval from approved data sources
You should configure retrieval from approved data sources to meet this requirement.
In Microsoft Foundry (and broader Azure AI Foundry / Azure OpenAI architectures), grounding an agent exclusively in company policy documents requires implementing a Retrieval-Augmented Generation (RAG) pattern. This ensures the AI model only answers using the provided context and does not hallucinate or rely on its public training data.
Box 2: Enable agent memory that uses persistent storage
To retain user preferences across completely separate chat sessions or conversations, you must use persistent agent memory. Traditional chat history only tracks messages within a single active thread or session. By contrast, the Memory Store feature provides a managed, long-term memory system that structurally indexes user preferences and facts across different devices and separate sessions.
Reference:
https://techcommunity.microsoft.com/blog/azure-ai-foundry-blog/announcing-new-capabilities-for-azure-openai-on-your-data/4144636
NEW QUESTION # 85
You have an Azure Speech in Foundry Tools resource that hosts a custom speech to text model deployed to a custom endpoint. An agent uses the endpoint to perform real-time speech recognition.
You are approaching the expiration date of the custom speech to text model.
What is the expected behavior when the model expires?
Answer: D
Explanation:
The correct answer is A. Speech recognition requests will fall back to the most recent base model for the same locale . Microsoft's custom speech model lifecycle guidance states that when a model expires, it is no longer available for transcription. For the custom endpoint route, speech recognition requests fall back to the most recent base model for the same locale. The documentation also warns that recognition results might still be returned, but the transcription may no longer reflect the domain-specific adaptation of the custom model.
This distinguishes real-time custom endpoint behavior from batch transcription behavior. Batch transcription requests that specify an expired model fail with a 4xx error, but that is not the route described in this question.
The agent is using a custom endpoint for real-time recognition, so fallback to the latest base model is the expected behavior. The model is not automatically deleted merely because it expires, and it does not continue to use the expired custom model indefinitely. The operational recommendation is to update the endpoint's model before expiration by redeploying the endpoint with a newer custom model. Reference topics: Azure Speech custom speech model lifecycle, custom endpoints, model expiration, real-time speech recognition, and endpoint redeployment.
NEW QUESTION # 86
......
The "ExamDiscuss" is committed to making the entire Microsoft AI-103 exam preparation process instant and successful. To achieve these objectives the "ExamDiscuss" is offering real, valid, and updated Developing AI Apps and Agents on Azure (AI-103)exam practice test questions in three high in demand formats. These formats are Microsoft AI-103 PDF dumps files, desktop practice test software, and web-based practice test software. All these AI-103 Exam Questions formats contain the real Developing AI Apps and Agents on Azure (AI-103) exam practice test questions that assist you in preparation and you will feel condiment to pass the final Microsoft AI-103 exam easily.
Test AI-103 Quiz: https://www.examdiscuss.com/Microsoft/exam/AI-103/
BTW, DOWNLOAD part of ExamDiscuss AI-103 dumps from Cloud Storage: https://drive.google.com/open?id=1XmCJODzf_x6CMI11Uvk3Sgw4F35pJIP_