Microsoft DP-600시험대비최신버전자료 - DP-600최신버전덤프

그리고 PassTIP DP-600 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1ynT0ppzyoYyf2NLu7Xfk5VJcXtNSxZwN
PassTIP에서 판매하고 있는 Microsoft DP-600인증시험자료는 시중에서 가장 최신버전으로서 시험적중율이 100%에 가깝습니다. Microsoft DP-600덤프자료를 항상 최신버전으로 보장해드리기 위해Microsoft DP-600시험문제가 변경되면 덤프자료를 업데이트하도록 최선을 다하고 있습니다. PassTIP는 여러분이 자격증을 취득하는 길에서 없어서는 안되는 동반자로 되어드릴것을 약속해드립니다.
Microsoft DP-600 시험요강:
| 주제 | 소개 |
|---|
| 주제 1 | - Prepare data: This section of the exam measures the skills of engineers and covers essential data preparation tasks. It includes establishing data connections and discovering sources through tools like the OneLake data hub and the real-time hub. Candidates must demonstrate knowledge of selecting the appropriate storage type—lakehouse, warehouse, or eventhouse—depending on the use case. It also includes implementing OneLake integrations with Eventhouse and semantic models. The transformation part involves creating views, stored procedures, and functions, as well as enriching, merging, denormalizing, and aggregating data. Engineers are also expected to handle data quality issues like duplicates, missing values, and nulls, along with converting data types and filtering. Furthermore, querying and analyzing data using tools like SQL, KQL, and the Visual Query Editor is tested in this domain.
|
| 주제 2 | - Maintain a data analytics solution: This section of the exam measures the skills of administrators and covers tasks related to enforcing security and managing the Power BI environment. It involves setting up access controls at both workspace and item levels, ensuring appropriate permissions for users and groups. Row-level, column-level, object-level, and file-level access controls are also included, alongside the application of sensitivity labels to classify data securely. This section also tests the ability to endorse Power BI items for organizational use and oversee the complete development lifecycle of analytics assets by configuring version control, managing Power BI Desktop projects, setting up deployment pipelines, assessing downstream impacts from various data assets, and handling semantic model deployments using XMLA endpoint. Reusable asset management is also a part of this domain.
|
| 주제 3 | - Implement and manage semantic models: This section of the exam measures the skills of architects and focuses on designing and optimizing semantic models to support enterprise-scale analytics. It evaluates understanding of storage modes and implementing star schemas and complex relationships, such as bridge tables and many-to-many joins. Architects must write DAX-based calculations using variables, iterators, and filtering techniques. The use of calculation groups, dynamic format strings, and field parameters is included. The section also includes configuring large semantic models and designing composite models. For optimization, candidates are expected to improve report visual and DAX performance, configure Direct Lake behaviors, and implement incremental refresh strategies effectively.
|
>> Microsoft DP-600시험대비 최신버전 자료 <<
DP-600최신버전덤프 & DP-600시험자료
Microsoft인증DP-600시험을 위하여 최고의 선택이 필요합니다. PassTIP 선택으로 좋은 성적도 얻고 하면서 저희 선택을 후회하지 않을것니다.돈은 적게 들고 효과는 아주 좋습니다.우리PassTIP여러분의 응시분비에 많은 도움이 될뿐만아니라Microsoft인증DP-600시험은 또 일년무료 업데이트서비스를 제공합니다.작은 돈을 투자하고 이렇게 좋은 성과는 아주 바람직하다고 봅니다.
최신 Microsoft Certified DP-600 무료샘플문제 (Q16-Q21):
질문 # 16
You have a Fabric workspace that uses the default Spark starter pool and runtime version 1,2.
You plan to read a CSV file named Sales.raw.csv in a lakehouse, select columns, and save the data as a Delta table to the managed area of the lakehouse. Sales_raw.csv contains 12 columns.
You have the following code.
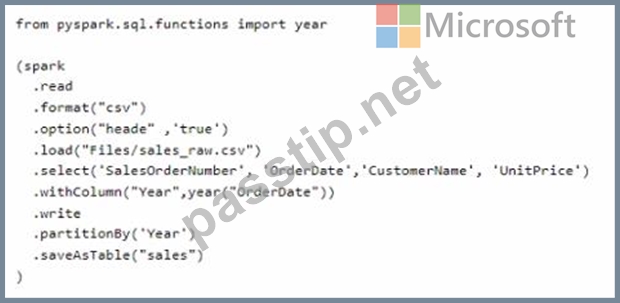
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
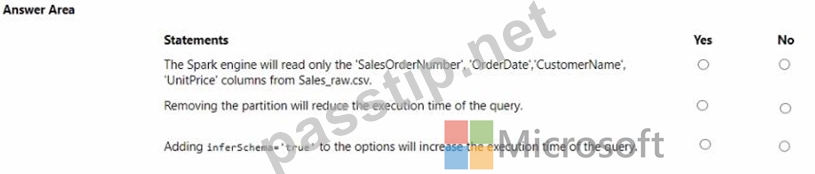
정답:
설명:
질문 # 17
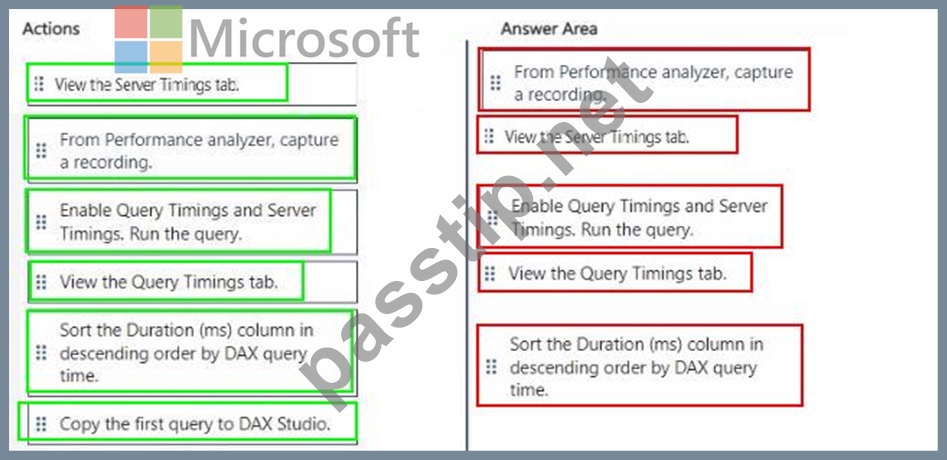
You have a Fabric tenant that contains a Microsoft Power Bl report named Report 1.
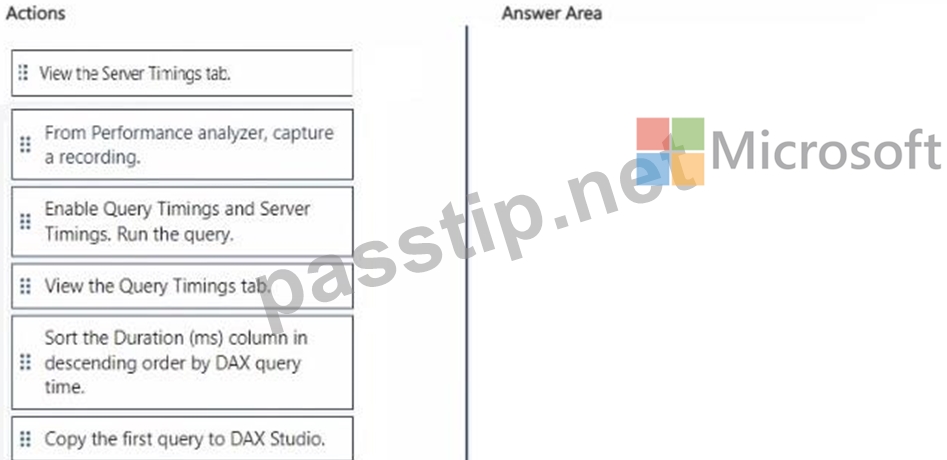
Report1 is slow to render. You suspect that an inefficient DAX query is being executed.
You need to identify the slowest DAX query, and then review how long the query spends in the formula engine as compared to the storage engine.
Which five actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
정답:
설명:
질문 # 18
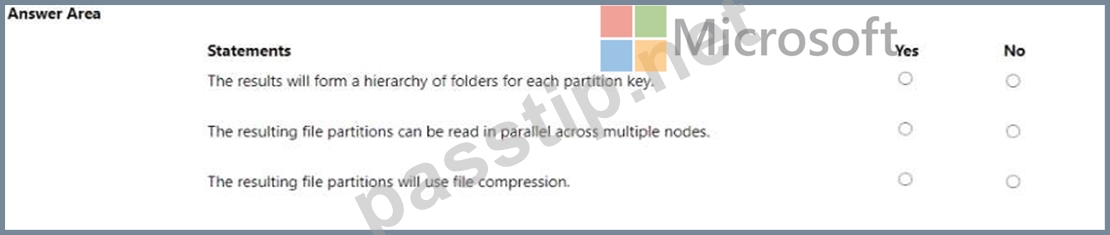
You have a Fabric tenant that contains a lakehouse.
You are using a Fabric notebook to save a large DataFrame by using the following code.

For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
정답:
설명:
Explanation:
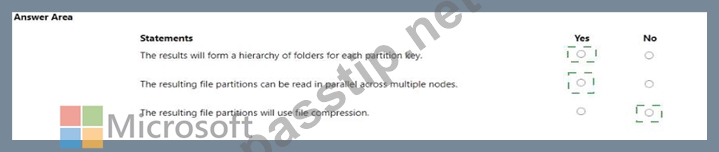
* The results will form a hierarchy of folders for each partition key. - Yes
* The resulting file partitions can be read in parallel across multiple nodes. - Yes
* The resulting file partitions will use file compression. - No
Partitioning data by columns such as year, month, and day, as shown in the DataFrame write operation, organizes the output into a directory hierarchy that reflects the partitioning structure. This organization can improve the performance of read operations, as queries that filter by the partitioned columns can scan only the relevant directories. Moreover, partitioning facilitates parallelism because each partition can be processed independently across different nodes in a distributed system like Spark. However, the code snippet provided does not explicitly specify that file compression should be used, so we cannot assume that the output will be compressed without additional context.
References =
* DataFrame write partitionBy
* Apache Spark optimization with partitioning
질문 # 19
You have a Fabric deployment pipeline that includes three stages named Development, Test, and Production.
Each stage is assigned to its own workspace on a Fabric capacity.
A paginated report in the Development workspace connects to a semantic model in the same workspace.
You deploy both the paginated report and the semantic model from the Development workspace to the Test workspace.
After the deployment, users report that the paginated report in Test still returns data from the semantic model in Development.
You need to ensure that the paginated report in the Test workspace queries the semantic model in the same workspace after deployments.
What should you do?
- A. Configure a data source rule for the paginated report.
- B. Configure a data source rule on the semantic model.
- C. Configure selective deployment.
- D. Reassign the Test workspace.
정답:A
질문 # 20
You have a Fabric tenant tha1 contains a takehouse named Lakehouse1. Lakehouse1 contains a Delta table named Customer.
When you query Customer, you discover that the query is slow to execute. You suspect that maintenance was NOT performed on the table.
You need to identify whether maintenance tasks were performed on Customer.
Solution: You run the following Spark SQL statement:
EXPLAIN TABLE customer
Does this meet the goal?
정답:A
설명:
No, the EXPLAIN TABLE statement does not identify whether maintenance tasks were performed on a table. It shows the execution plan for a query. References = The usage and output of the EXPLAIN command can be found in the Spark SQL documentation.
질문 # 21
......
PassTIP의 Microsoft 인증 DP-600시험덤프공부자료는 pdf버전과 소프트웨어버전 두가지 버전으로 제공되는데 Microsoft 인증 DP-600실제시험예상문제가 포함되어있습니다.덤프의 예상문제는 Microsoft 인증 DP-600실제시험의 대부분 문제를 적중하여 높은 통과율과 점유율을 자랑하고 있습니다. PassTIP의 Microsoft 인증 DP-600덤프를 선택하시면 IT자격증 취득에 더할것 없는 힘이 될것입니다.
DP-600최신버전덤프: https://www.passtip.net/DP-600-pass-exam.html
- DP-600시험대비 최신버전 자료 100% 유효한 최신버전 덤프 😙 오픈 웹 사이트[ www.itdumpskr.com ]검색▛ DP-600 ▟무료 다운로드DP-600최신 업데이트 시험덤프
- 최신버전 DP-600시험대비 최신버전 자료 퍼펙트한 덤프로 시험패스하여 자격증을 취득하기 ✊ ▷ www.itdumpskr.com ◁을 통해 쉽게「 DP-600 」무료 다운로드 받기DP-600최신 인증시험 기출문제
- 최신 DP-600시험대비 최신버전 자료 덤프데모문제 🐋 무료 다운로드를 위해 지금( www.dumptop.com )에서▷ DP-600 ◁검색DP-600최신 인증시험 대비자료
- DP-600최신 업데이트버전 덤프공부자료 🩺 DP-600시험패스 가능 덤프 🌃 DP-600최신 인증시험 대비자료 🐺 ▶ www.itdumpskr.com ◀에서 검색만 하면➤ DP-600 ⮘를 무료로 다운로드할 수 있습니다DP-600최신 인증시험
- DP-600시험대비 최신버전 자료 시험준비에 가장 좋은 인기덤프 👴 무료로 다운로드하려면⏩ www.dumptop.com ⏪로 이동하여➥ DP-600 🡄를 검색하십시오DP-600유효한 공부문제
- DP-600시험대비 최신버전 자료 100% 합격 보장 가능한 최신 공부자료 🦔 ⇛ www.itdumpskr.com ⇚을(를) 열고➤ DP-600 ⮘를 입력하고 무료 다운로드를 받으십시오DP-600인증시험덤프
- 최신버전 DP-600시험대비 최신버전 자료 완벽한 시험덤프 😉 시험 자료를 무료로 다운로드하려면➽ www.exampassdump.com 🢪을 통해⏩ DP-600 ⏪를 검색하십시오DP-600유효한 최신덤프자료
- 최신버전 DP-600시험대비 최신버전 자료 퍼펙트한 덤프로 시험패스하여 자격증을 취득하기 🔘 “ www.itdumpskr.com ”에서[ DP-600 ]를 검색하고 무료 다운로드 받기DP-600최신 업데이트버전 덤프공부자료
- 최신버전 DP-600시험대비 최신버전 자료 퍼펙트한 덤프로 시험패스하여 자격증을 취득하기 🐖 오픈 웹 사이트⏩ www.koreadumps.com ⏪검색▷ DP-600 ◁무료 다운로드DP-600최신버전 시험자료
- DP-600시험문제모음 🤾 DP-600최신버전 시험자료 🥁 DP-600최신버전 덤프문제 🔪 ➡ www.itdumpskr.com ️⬅️웹사이트에서▛ DP-600 ▟를 열고 검색하여 무료 다운로드DP-600높은 통과율 시험공부자료
- DP-600시험대비 최신버전 자료 100% 유효한 최신버전 덤프 🍞 무료 다운로드를 위해 지금➤ www.pass4test.net ⮘에서➥ DP-600 🡄검색DP-600시험패스 가능 덤프
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, experiment.com, www.stes.tyc.edu.tw, Disposable vapes
BONUS!!! PassTIP DP-600 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=1ynT0ppzyoYyf2NLu7Xfk5VJcXtNSxZwN