BTW, DOWNLOAD part of Exam4Free Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1476QY1M1_makcSF1ABScCuedbjQZrBwW
You can download our Professional-Machine-Learning-Engineer guide torrent immediately after you pay successfully. After you pay successfully you will receive the mails sent by our system in 10-15 minutes. Then you can click on the links and log in and you will use our software to learn our Professional-Machine-Learning-Engineer prep torrent immediately. Not only our Professional-Machine-Learning-Engineer Test Prep provide the best learning for them but also the purchase is convenient because the learners can immediately learn our Professional-Machine-Learning-Engineer prep torrent after the purchase. So the using and the purchase are very fast and convenient for the learners
Google Professional Machine Learning Engineer Certification Exam is considered to be one of the most challenging and comprehensive exams in the field of machine learning. Candidates who pass the exam are recognized as experts in their field and are highly sought-after by employers worldwide. Earning this certification can open up a wide range of career opportunities, including roles such as machine learning engineer, data scientist, and artificial intelligence specialist. Moreover, it also demonstrates a candidate's commitment to ongoing learning and professional development, which is highly valued by employers in today's rapidly evolving technology landscape.
To be eligible for the Google Professional Machine Learning Engineer certification exam, candidates must have a minimum of three years of experience in the field of machine learning. Candidates should also have experience in designing and implementing machine learning solutions using Google Cloud technologies such as Google Cloud ML Engine, BigQuery, and TensorFlow. In addition to these requirements, candidates should have a strong understanding of machine learning algorithms and data structures.
>> Professional-Machine-Learning-Engineer Visual Cert Test <<
If you still worried about whether or not you pass exam; if you still doubt whether it is worthy of purchasing our software, what can you do to clarify your doubts that is to download free demo of Professional-Machine-Learning-Engineer. Once you have checked our demo, you will find the study materials we provide are what you want most. Our target is to reduce your pressure and improve your learning efficiency from preparing exam. Professional-Machine-Learning-Engineer effective exam dumps are significance for studying and training. As a rich experienced exam dump provider, we will provide you with one of the best tools available to you for pass Professional-Machine-Learning-Engineer exam. You can find different types of Professional-Machine-Learning-Engineer dumps on our website, which is a best choice.
Google Professional-Machine-Learning-Engineer Certification Exam is a professional-level certification exam that tests your proficiency in building and deploying machine learning models on Google Cloud Platform. It is designed for individuals with a solid understanding of machine learning concepts and experience in developing and deploying machine learning models on Google Cloud Platform. If you are a machine learning engineer, data scientist, or software developer looking to demonstrate your expertise in machine learning, this certification exam is an excellent way to showcase your skills and knowledge.
NEW QUESTION # 78
You are training a custom language model for your company using a large dataset. You plan to use the Reduction Server strategy on Vertex Al. You need to configure the worker pools of the distributed training job. What should you do?
Answer: D
NEW QUESTION # 79
You work for an online retail company that is creating a visual search engine. You have set up an end-to-end ML pipeline on Google Cloud to classify whether an image contains your company's product. Expecting the release of new products in the near future, you configured a retraining functionality in the pipeline so that new data can be fed into your ML models. You also want to use AI Platform's continuous evaluation service to ensure that the models have high accuracy on your test dataset. What should you do?
Answer: C
Explanation:
By extending your test dataset with images of the newer products, you can ensure that your ML models are still able to classify images of the older products accurately, even after they have been retrained with data from the newer products. This will help you to maintain a high level of accuracy for your visual search engine.
NEW QUESTION # 80
You work at a bank You have a custom tabular ML model that was provided by the bank ' s vendor. The training data is not available due to its sensitivity. The model is packaged as a Vertex Al Model serving container which accepts a string as input for each prediction instance. In each string the feature values are separated by commas. You want to deploy this model to production for online predictions, and monitor the feature distribution over time with minimal effort What should you do?
Answer: D
Explanation:
The best option for deploying a custom tabular ML model to production for online predictions, and monitoring the feature distribution over time with minimal effort, using a model that was provided by the bank's vendor, the training data is not available due to its sensitivity, and the model is packaged as a Vertex AI Model serving container which accepts a string as input for each prediction instance, is to upload the model to Vertex AI Model Registry and deploy the model to a Vertex AI endpoint, create a Vertex AI Model Monitoring job with feature drift detection as the monitoring objective, and provide an instance schema. This option allows you to leverage the power and simplicity of Vertex AI to serve and monitor your model with minimal code and configuration. Vertex AI is a unified platform for building and deploying machine learning solutions on Google Cloud. Vertex AI can deploy a trained model to an online prediction endpoint, which can provide low-latency predictions for individual instances. Vertex AI can also provide various tools and services for data analysis, model development, model deployment, model monitoring, and model governance.
A Vertex AI Model Registry is a resource that can store and manage your models on Vertex AI. A Vertex AI Model Registry can help you organize and track your models, and access various model information, such as model name, model description, and model labels. A Vertex AI Model serving container is a resource that can run your custom model code on Vertex AI. A Vertex AI Model serving container can help you package your model code and dependencies into a container image, and deploy the container image to an online prediction endpoint. A Vertex AI Model serving container can accept various input formats, such as JSON, CSV, or TFRecord. A string input format is a type of input format that accepts a string as input for each prediction instance. A string input format can help you encode your feature values into a single string, and separate them by commas. By uploading the model to Vertex AI Model Registry and deploying the model to a Vertex AI endpoint, you can serve your model for online predictions with minimal code and configuration. You can use the Vertex AI API or the gcloud command-line tool to upload the model to Vertex AI Model Registry, and provide the model name, model description, and model labels. You can also use the Vertex AI API or the gcloud command-line tool to deploy the model to a Vertex AI endpoint, and provide the endpoint name, endpoint description, endpoint labels, and endpoint resources. A Vertex AI Model Monitoring job is a resource that can monitor the performance and quality of your deployed models on Vertex AI. A Vertex AI Model Monitoring job can help you detect and diagnose issues with your models, such as data drift, prediction drift, training/serving skew, or model staleness. Feature drift is a type of model monitoring metric that measures the difference between the distributions of the features used to train the model and the features used to serve the model over time. Feature drift can indicate that the online data is changing over time, and the model performance is degrading. By creating a Vertex AI Model Monitoring job with feature drift detection as the monitoring objective, and providing an instance schema, you can monitor the feature distribution over time with minimal effort. You can use the Vertex AI API or the gcloud command-line tool to create a Vertex AI Model Monitoring job, and provide the monitoring objective, the monitoring frequency, the alerting threshold, and the notification channel. You can also provide an instance schema, which is a JSON file that describes the features and their types in the prediction input data. An instance schema can he lp Vertex AI Model Monitoring parse and analyze the string input format, and calculate the feature distributions and distance scores 1 .
The other options are not as good as option A, for the following reasons:
* Option B: Uploading the model to Vertex AI Model Registry and deploying the model to a Vertex AI endpoint, creating a Vertex AI Model Monitoring job with feature skew detection as the monitoring objective, and providing an instance schema would not help you monitor the changes in the online data over time, and could cause errors or poor performance. Feature skew is a type of model monitoring metric that measures the difference between the distributions of the features used to train the model and the features used to serve the model at a given point in time. Feature skew can indicate that the model is not trained on the representative data, or that the data is changing over time. By creating a Vertex AI Model Monitoring job with feature skew detection as the monitoring objective, and providing an instance schema, you can monitor the feature distribution at a given point in time with minimal effort.
However, uploading the model to Vertex AI Model Registry and deploying the model to a Vertex AI endpoint, creating a Vertex AI Model Monitoring job with feature skew detection as the monitoring objective, and providing an instance schema would not help you monitor the changes in the online data over time, and could cause errors or poor performance. You would need to use the Vertex AI API or the gcloud command-line tool to upload the model to Vertex AI Model Registry, deploy the model to a Vertex AI endpoint, create a Vertex AI Model Monitoring job, and provide an instance schema. Moreover, this option would not monitor the feature drift, which is a more direct and relevant metric for measuring the changes in the online data over time, and the model pe rformance and quality
1 .
* Option C: Refactoring the serving container to accept key-value pairs as input format, uploading the model to Vertex AI Model Registry and deploying the model to a Vertex AI endpoint, creating a Vertex AI Model Monitoring job with feature drift detection as the monitoring objective would require more skills and steps than uploading the model to Vertex AI Model Registry and deploying the model to a Vertex AI endpoint, creating a Vertex AI Model Monitoring job with feature drift detection as the monitoring objective, and providing an instance schema. A key-value pair input format is a type of input format that accepts a key-value pair as input for each prediction instance. A key-value pair input format can help you specify the feature names and values in a JSON object, and separate them by colons. By refactoring the serving container to accept key-value pairs as input format, uploading the model to Vertex AI Model Registry and deploying the model to a Vertex AI endpoint, creating a Vertex AI Model Monitoring job with feature drift detection as the monitoring objective, you can serve and monitor your model with minimal code and configuration. You can write code to refactor the serving container to accept key-value pairs as input format, and use the Vertex AI API or the gcloud command- line tool to upload the model to Vertex AI Model Registry, deploy the model to a Vertex AI endpoint, and create a Vertex AI Model Monitoring job. However, refactoring the serving container to accept key- value pairs as input format, uploading the model to Vertex AI Model Registry and deploying the model to a Vertex AI endpoint, creating a Vertex AI Model Monitoring job with feature drift detection as the monitoring objective would require more skills and steps than uploading the model to Vertex AI Model Registry and deploying the model to a Vertex AI endpoint, creating a Vertex AI Model Monitoring job with feature drift detection as the monitoring objective, and providing an instance schema. You would need to write code, refactor the serving container, upload the model to Vertex AI Model Registry, deploy the model to a Vertex AI endpoint, and create a Vertex AI Model Monitoring job. Moreover, this option would not use the instance schema, which is a JSON file that can help Vertex AI Model Monitoring parse and analyze the string input format, and calcula te the feature distributions and distance scores 1 .
* Option D: Refactoring the serving container to accept key-value pairs as input format, uploading the model to Vertex AI Model Registry and deploying the model to a Vertex AI endpoint, creating a Vertex AI Model Monitoring job with feature skew detection as the monitoring objective would require more skills and steps than uploading the model to Vertex AI Model Registry and deploying the model to a Vertex AI endpoint, creating a Vertex AI Model Monitoring job with feature drift detection as the monitoring objective, and providing an instance schema, and would not help you monitor the changes in the online data over time, and could cause errors or poor performance. Feature skew is a type of model monitoring metric that measures the difference between the distributions of the features used to train the model and the features used to serve the model at a given point in time. Feature skew can indicate that the model is not trained on the representative data, or that the data is changing over time.
By creating a Vertex AI Model Monitoring job with feature skew detection as the monitoring objective, you can monitor the feature distribution at a given point in time with minimal effort. However, refactoring the serving container to accept key-value pairs as input format, uploading the model to Vertex AI Model Registry and deploying the model to a Vertex AI endpoint, creating a Vertex AI Model Monitoring job with feature skew detection as the monitoring objective would require more skills and steps than uploading the model to Vertex AI Model Registry and deploying the model to a Vertex AI endpoint, creating a Vertex AI Model Monitoring job with feature drift detection as the monitoring objective, and providing an instance schema, and would not help you monitor the changes in the online data over time, and could cause errors or poor performance. You would need to write code, refactor the serving container, upload the model to Vertex AI Model Registry, deploy the model to a Vertex AI endpoint, and create a Vertex AI Model Monitoring job. Moreover, this option woul d not monitor the feature drift, which is a more direct and relevant metric for measuring the changes in the online data over time, and the model performance and quality 1 .
References:
Using Model Monitoring | Vertex AI | Google Cloud
NEW QUESTION # 81
You recently deployed a model lo a Vertex Al endpoint and set up online serving in Vertex Al Feature Store.
You have configured a daily batch ingestion job to update your featurestore During the batch ingestion jobs you discover that CPU utilization is high in your featurestores online serving nodes and that feature retrieval latency is high. You need to improve online serving performance during the daily batch ingestion. What should you do?
Answer: A
Explanation:
Vertex AI Feature Store provides two options for online serving: Bigtable and optimized online serving. Both options support autoscaling, which means that the number of online serving nodes can automatically adjust to the traffic demand. By enabling autoscaling, you can improve the online serving performance and reduce the feature retrieval latency during the daily batch ingestion. Autoscaling also helps you optimize the cost and resource utilization of your featurestore. References:
* Online serving | Vertex AI | Google Cloud
* New Vertex AI Feature Store: BigQuery-Powered, GenAI-Ready | Google Cloud Blog
NEW QUESTION # 82
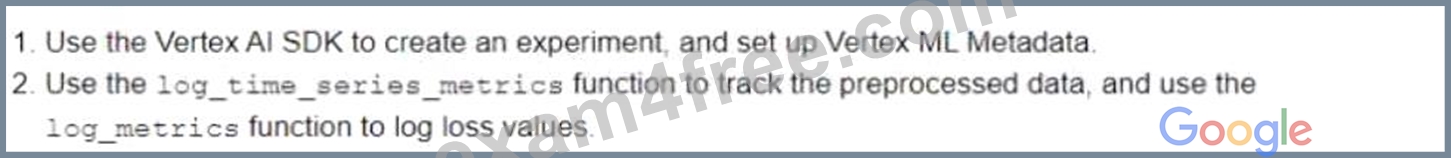
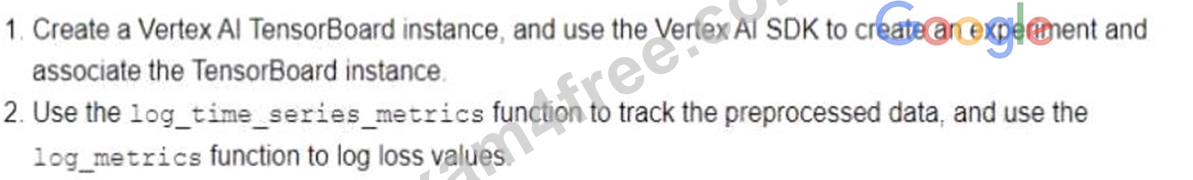
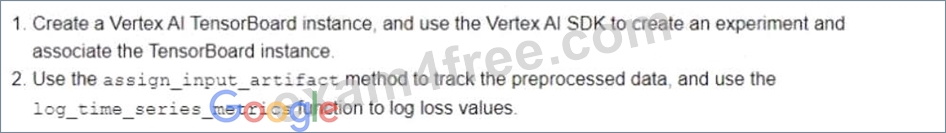
You are developing a model to predict whether a failure will occur in a critical machine part. You have a dataset consisting of a multivariate time series and labels indicating whether the machine part failed You recently started experimenting with a few different preprocessing and modeling approaches in a Vertex Al Workbench notebook. You want to log data and track artifacts from each run. How should you set up your experiments?
Answer: B
Explanation:
The option A is the most suitable solution for logging data and tracking artifacts from each run of a model development experiment in a Vertex AI Workbench notebook. Vertex AI Workbench is a service that allows you to create and run interactive notebooks on Google Cloud. You can use Vertex AI Workbench to experiment with different preprocessing and modeling approaches for your time series prediction problem.
You can also use the Vertex AI TensorBoard instance and the Vertex AI SDK to create an experiment and associate the TensorBoard instance. TensorBoard is a tool that allows you to visualize and monitor the metrics and artifacts of your ML experiments. You can use the Vertex AI SDK to create an experiment object, which is a logical grouping of runs that share a common objective. You can also use the Vertex AI SDK to associate the experiment object with a TensorBoard instance, which is a managed service that hosts a TensorBoard web app. By using the Vertex AI TensorBoard instance and the Vertex AI SDK, you can easily set up and manage your experiments, and access the TensorBoard web app from the Vertex AI console. You can also use the log_time_series_metrics function and the log_metrics function to log data and track artifacts from each run.
The log_time_series_metrics function is a function that allows you to log the time series data, such as the multivariate time series and the labels, to the TensorBoard instance. The log_metrics function is a function that allows you to log the scalar metrics, such as the loss values, to the TensorBoard instance. By using these functions, you can record the data and artifacts from each run of your experiment, and compare them in the TensorBoard web app. You can also use the TensorBoard web app to visualize the data and artifacts, such as the time series plots, the scalar charts, the histograms, and the distributions. By using the Vertex AI TensorBoard instance, the Vertex AI SDK, and the log functions, you can log data and track artifacts from each run of your experiment in a Vertex AI Workbench notebook. References:
* Vertex AI Workbench documentation
* Vertex AI TensorBoard documentation
* Vertex AI SDK documentation
* log_time_series_metrics function documentation
* log_metrics function documentation
* [Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate]
NEW QUESTION # 83
......
Professional-Machine-Learning-Engineer Valid Exam Objectives: https://www.exam4free.com/Professional-Machine-Learning-Engineer-valid-dumps.html
2026 Latest Exam4Free Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1476QY1M1_makcSF1ABScCuedbjQZrBwW