雖然有其他的線上Microsoft的DP-800考試培訓資源在市場上,但我們Testpdf Microsoft的DP-800考試培訓資料是最好的。因為我們會定期更新,始終提供準確的Microsoft的DP-800考試認證資料,我們Testpdf Microsoft的DP-800考試培訓資料提供一年的免費更新,你會得到最新的更新了的Testpdf Microsoft的DP-800考試培訓資料。
| Section | Weight | Objectives |
|---|---|---|
| Implement AI capabilities in database solutions | 25-30% | - Integrate AI models and services
|
| Secure, optimize, and deploy database solutions | 35-40% | - Deploy and maintain solutions
|
| Design and develop database solutions | 35-40% | - Develop database solutions
|
在現在這個人才濟濟的社會裏,還是有很多行業是缺乏人才的,比如IT行業就相當缺乏技術性的人才。而Microsoft DP-800 認證考試就是個檢驗IT技術的認證考試之一。Testpdf是一個給你培訓Microsoft DP-800 認證考試相關技術知識的網站。
問題 #33
You need to recommend a solution that will resolve the ingestion pipeline failure issues. Which two actions should you recommend? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
答案:A,C
解題說明:
The two correct actions are D and E because the ingestion failures are caused by malformed JSON and duplicate payloads , and these two controls address those two problems directly. Microsoft's JSON documentation states that SQL Server and Azure SQL support validating JSON with ISJSON , and Microsoft specifically recommends using a CHECK constraint to ensure JSON text stored in a column is properly formatted.
For the duplicate-payload issue, creating a unique index on a hash of the payload is the appropriate design.
Microsoft documents using hashing functions such as HASHBYTES to hash column values, and SQL Server allows a deterministic computed column to be used as a key column in a UNIQUE constraint or unique index . That makes a persisted hash-based computed column plus a unique index a practical and exam- consistent way to reject duplicate payloads efficiently.
The other options do not solve the stated root causes:
* Snapshot isolation addresses concurrency behavior, not malformed JSON or duplicate payload detection.
* A trigger to rewrite malformed JSON is not the right integrity control and is brittle.
* Foreign key constraints enforce referential integrity, not JSON validity or duplicate-payload prevention
問題 #34
You have an Azure SQL database that contains a table named Sales.Orders. Sales.Orders contains the following columns.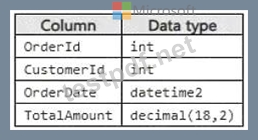
Reporting queries frequently repeat logic to calculate the number of days since an order was placed.
You need to create a scalar user-defined function (UDF) that returns the number of days between an input value of @OrderDate and the current date and time.
How should you complete the Transact-SQL code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.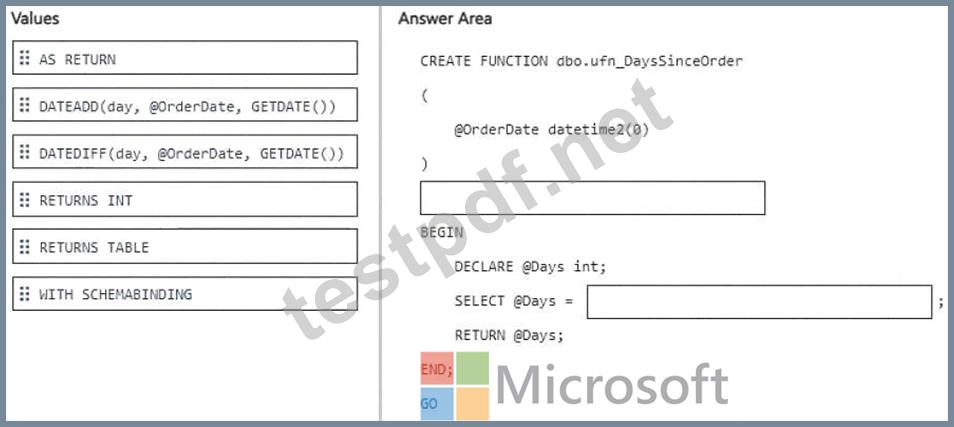
答案:
解題說明: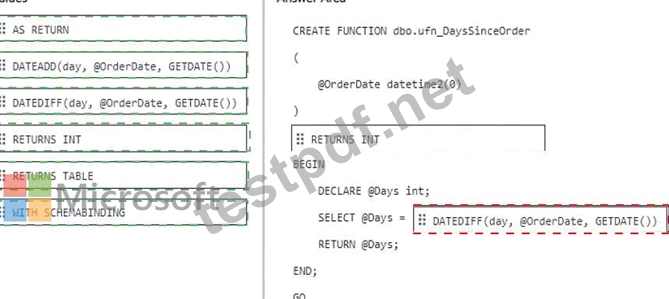
Explanation:
* Function return type # RETURNS INT
* Calculation # DATEDIFF(day, @OrderDate, GETDATE())
Comprehensive and Detailed Explanation with all Developing AI-Enabled Database Solutions documents : = The first correct selection is RETURNS INT because the requirement is to create a scalar UDF that returns a single integer representing the number of days since the order date. Microsoft documents that scalar user- defined functions return a single scalar value, and DATEDIFF returns an int value.
The second correct selection is:
DATEDIFF(day, @OrderDate, GETDATE())
Microsoft defines DATEDIFF(datepart, startdate, enddate) as returning the number of specified datepart boundaries crossed between two dates. Therefore, placing @OrderDate as the start date and GETDATE() as the end date returns the number of elapsed day boundaries from the order date to the current date and time.
GETDATE() is valid inside a Transact-SQL UDF. Microsoft explicitly lists GETDATE among the nondeterministic built-in functions that can be used in T-SQL user-defined functions . Its nondeterministic nature means the result changes over time, but it does not prevent creation of this scalar UDF.
The completed code is:
CREATE FUNCTION dbo.ufn_DaysSinceOrder
(
@OrderDate datetime2(0)
)
RETURNS INT
BEGIN
DECLARE @Days int;
SELECT @Days =
DATEDIFF(day, @OrderDate, GETDATE());
RETURN @Days;
END;
GO
So the drag-and-drop answers are:
* First target: RETURNS INT
* Second target: DATEDIFF(day, @OrderDate, GETDATE())
問題 #35
You have a database named db1. The schema is stored in a Git repository as an SDK-style SQL database project The repository Contains the following GitHub Action workflow.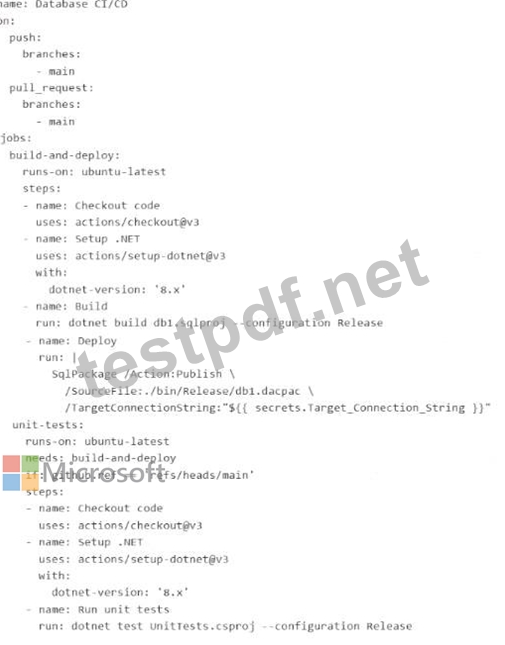
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.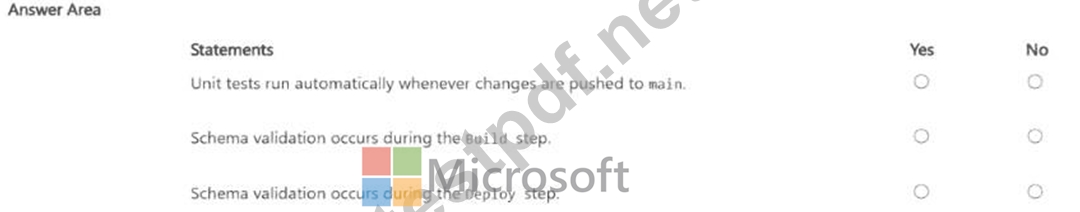
答案:
解題說明: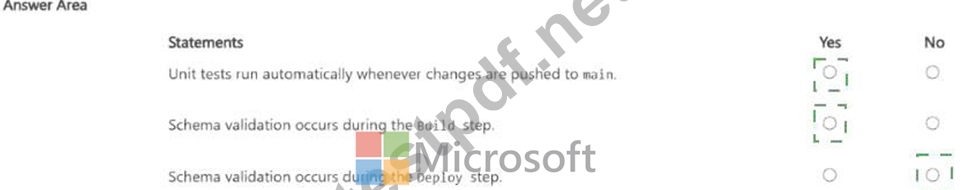
Explanation:
* Unit tests run automatically whenever changes are pushed to main. # Yes
* Schema validation occurs during the Build step. # Yes
* Schema validation occurs during the Deploy step. # No
The first statement is Yes . The workflow is configured to trigger on both push to main and pull_request targeting main. The unit-tests job has this condition:
if: github.ref == ' refs/heads/main '
On a push to main , GitHub sets github.ref to refs/heads/main, so the condition is true and the unit-tests job runs. GitHub's workflow syntax documentation confirms that push.branches: [main] triggers on pushes to main, and the github.ref value for branch pushes is the fully qualified ref such as refs/heads/main.
The second statement is Yes . The Build step runs:
dotnet build db1.sqlproj --configuration Release
For an SDK-style SQL database project, the build process produces a .dacpac and validates the database project model as part of compilation/build. Microsoft's SQL database project documentation describes SDK- style SQL projects as the project format used for SQL Database Projects, and Microsoft's command-line build documentation is specifically about building a .dacpac from that SQL project. That means schema-level project validation happens during build.
The third statement is No . The Deploy step uses:
SqlPackage /Action:Publish ...
Microsoft documents that SqlPackage Publish incrementally updates the target database schema to match the source .dacpac. That is a deployment operation, not the primary schema-validation stage of the SQL project source itself. In this workflow, the schema is validated when the SQL project is built into the .dacpac; the deploy step applies that built artifact to the target database.
問題 #36
You have a SQL database in Microsoft Fabric named Sales BD that contains a table named dbo.Products. You need to modify SalesBD to meet the following requirements:
* Create a vector index on the appropriate column.
* Use a supplied natural language query vector.
How should you complete the Transact-SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.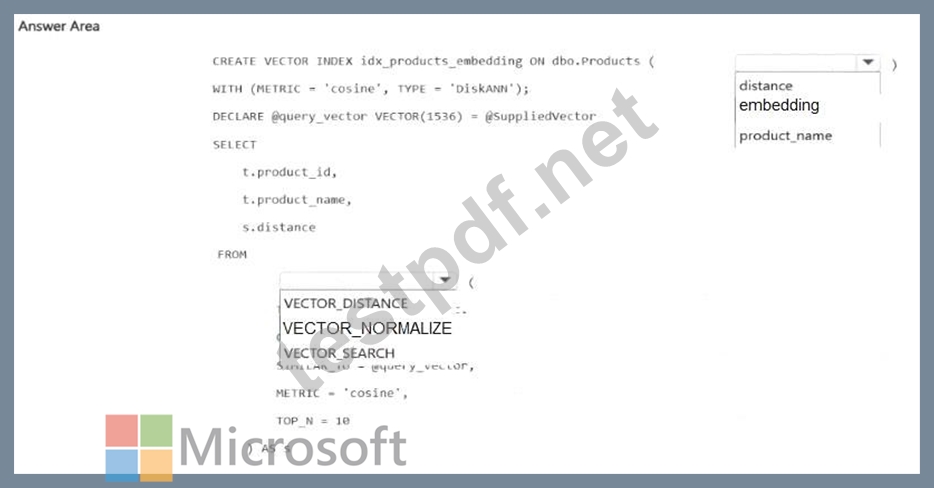
答案:
解題說明: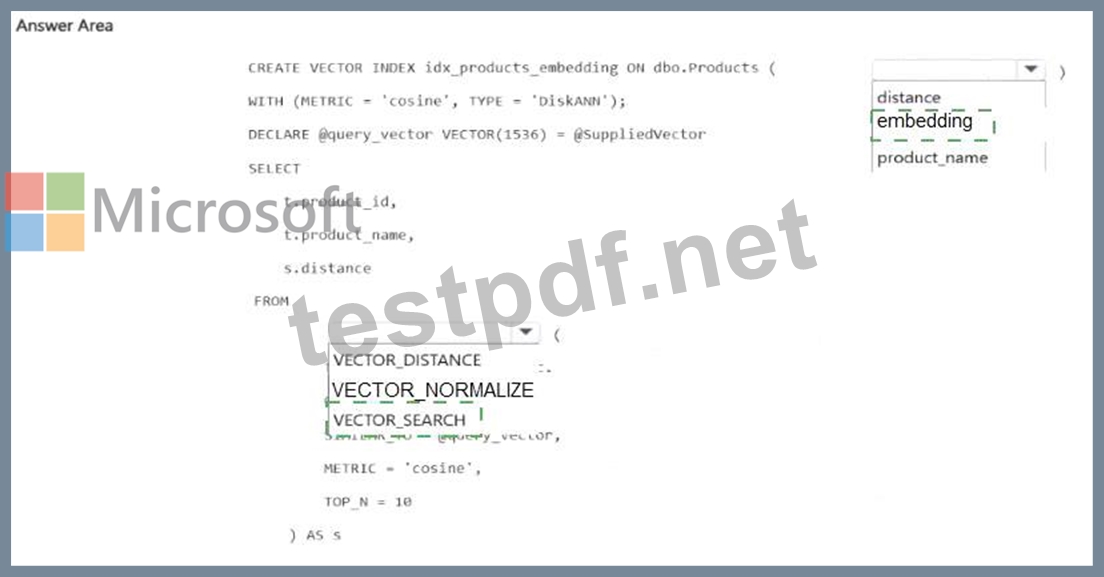
Explanation: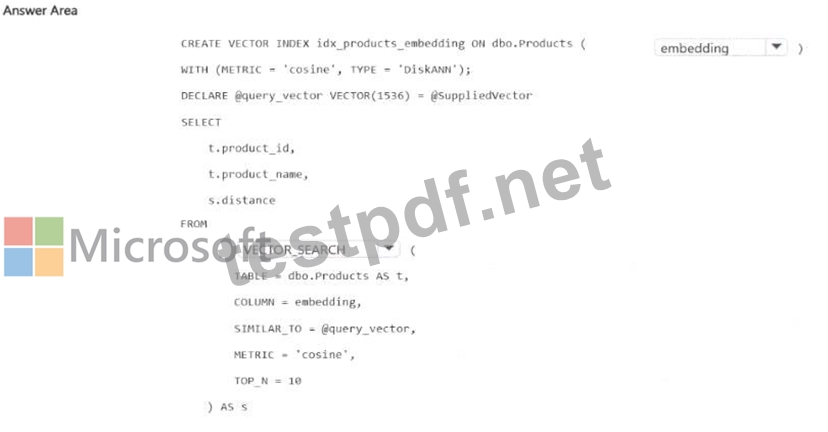
The first correct selection is embedding because a vector index must be created on the vector column , not on a scalar distance column or a text column such as product_name. Microsoft's CREATE VECTOR INDEX documentation shows that the index is created directly on the vector-valued column, for example ON product_embeddings(embedding).
The second correct selection is VECTOR_SEARCH because the requirement is to use a supplied natural language query vector and search against the indexed embeddings. Microsoft documents that VECTOR_SEARCH is the Transact-SQL function for approximate nearest neighbor vector retrieval and that it applies to SQL database in Microsoft Fabric as well as other supported SQL platforms.
This also matches the shown code pattern:
* declare a vector variable such as @query_vector VECTOR(1536),
* create a vector index on dbo.Products(embedding),
* query with VECTOR_SEARCH(... SIMILAR_TO = @query_vector, METRIC = ' cosine ' , TOP_N =
10).
問題 #37
You have an Azure SQL database That contains a table named dbo.Products, dbo.Products contains three columns named Embedding Category, and Price. The Embedding column is defined as VECTOR(1536).
You use Ai_GENERME_EMBEDOINGS and VECTOR_SEARCH to support semantic search and apply additional filters on two columns named Category and Price.
You plan to change the embedding model from text-embedding-ada-002 to text-embedding-3-smalL Existing rows already contain embeddings in the Embedding column.
You need to implement the model change. Applications must be able to use VECTOR_SEARCH without runtime errors.
What should you do first?
答案:D
問題 #38
......
如果你想購買Microsoft的DP-800學習指南線上服務,那麼我們Testpdf是領先用於此目的的網站之一,本站提供最好的品質和最新的培訓資料,我們網站所提供成的所有的學習資料及其它的培訓資料都是符合成本效益的,可以在網站上享受一年的免費更新設施,所以這些培訓產品如果沒有幫助你通過考試,我們將保證退還全部購買費用。
DP-800最新考證: https://www.testpdf.net/DP-800.html