Our DP-750 free demo provides you with the free renewal in one year so that you can keep track of the latest points happening in the world. As the questions of exams of our exam torrent are more or less involved with heated issues and customers who prepare for the exams must haven’t enough time to keep trace of exams all day long, our DP-750 Practice Test can serve as a conducive tool for you make up for those hot points you have ignored. Apart from the advantage of free renewal in one year, our exam prep offers you constant discounts so that you can save a large amount of money concerning buying our DP-750 training materials.
| Section | Weight | Objectives |
|---|---|---|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
>> Valid Exam DP-750 Blueprint <<
If you want to understand our DP-750 exam prep, you can download the demo from our web page. You do not need to spend money; because our DP-750 test questions provide you with the demo for free. You just need to download the demo of our DP-750 exam prep according to our guiding; you will get the demo for free easily before you purchase our products. By using the demo, we believe that you will have a deeply understanding of our DP-750 Test Torrent. We can make sure that you will like our products; because you will it can help you a lot.
NEW QUESTION # 35
Which SCD type should you use to support the planned data modeling changes? To answer, drag the appropriate types to the correct issues. Each type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: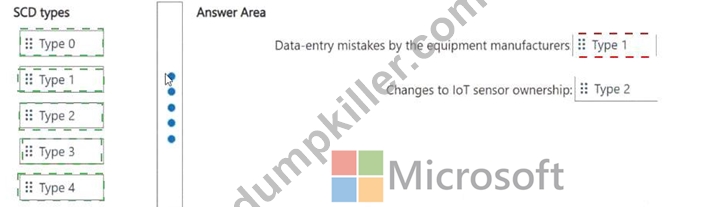
Explanation:
The correct mapping is SCD Type 1 for equipment metadata and SCD Type 2 for IoT sensor ownership history.
SCD Type 1 overwrites the existing record whenever an attribute changes - no history is kept. Contoso's requirement for equipment metadata (name, manufacturer, model, commissioning date) states 'historical values are NOT required,' which is the textbook definition of Type 1. A MERGE INTO with WHEN MATCHED THEN UPDATE handles this cleanly in Delta Lake.
SCD Type 2 creates a new row for each change, preserving the full history through effective-date or version columns. Contoso requires that 'analysts must track the full history of ownership' as sensors change hands over time - that full audit trail is only possible with Type 2. Type 3 (keeping just the previous value in an extra column) would lose earlier ownership records, so it doesn't satisfy the 'full history' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/merge
NEW QUESTION # 36
What ensures failure recovery in Databricks Structured Streaming?
Answer: A
Explanation:
Checkpointing stores streaming state and progress, allowing recovery after failures without data loss or duplication. Auto scaling adjusts compute resources but does not ensure reliability.
Partition pruning improves query performance. Broadcast joins optimize joins but are unrelated to recovery.
NEW QUESTION # 37
You need to ingest real-time IoT data into Delta Lake with exactly-once guarantees. Which approach should you use?
Answer: B
Explanation:
Structured Streaming with checkpointing ensures fault tolerance and exactly-once processing semantics in Databricks. It tracks processed offsets and recovers from failures automatically.
Batch ingestion cannot guarantee real-time processing. Copy activity is not designed for streaming workloads and manual ingestion is not scalable or reliable.
NEW QUESTION # 38
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 processes raw data files stored in Azure Storage.
New files arrive at unpredictable intervals.
You need to ensure that Job1 starts automatically when new files arrive and does NOT consume compute resources when no data is available.
Which type of job trigger should you use?
Answer: D
Explanation:
A file arrival trigger starts Job1 when new files are detected in the monitored Azure Storage location. Because the job is launched only after a qualifying arrival, compute does not remain active while the source is idle.
This is well suited to unpredictable file-delivery patterns and avoids the unnecessary executions produced by a fixed schedule. A continuous trigger keeps the workload running and therefore consumes compute even when no files are available. A scheduled trigger starts the job at predetermined times whether or not new data exists. A manual trigger cannot provide automatic processing. File arrival triggers consequently provide the required event-driven behavior while improving resource utilization and controlling cost during inactive periods. Microsoft Learn
NEW QUESTION # 39
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes curated Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
Answer: D
Explanation:
The best choice is a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
Low Development Effort: Lakeflow SDP (formerly known as Delta Live Tables or DLT) is a completely declarative ETL framework. You simply define the target schemas and data transformations using standard SQL or Python. Databricks automatically manages the underlying operational complexities, state maintenance, task orchestration, and DAG dependencies for you.
Built-in Quality & Monitoring: It offers out-of-the-box data monitoring capabilities via Expectations, which allow you to specify data cleansing policies (like drop, retain, or fail on bad rows) with zero custom validation code. It also captures complete, automatic end-to-end data lineage and operational stats straight into Unity Catalog.
Built-in Resilience: Infrastructure failure handling and automatic retries are natively managed by the Lakeflow runtime.
Native Storage Ingestion: Using read_files() (Auto Loader) within SDP allows effortless, incremental ingestion of files from cloud object storage directly into curated Delta tables.
Reference:
https://docs.databricks.com/aws/en/ldp/
NEW QUESTION # 40
......
If you are looking for a good learning site that can help you to pass the Microsoft DP-750 exam, Dumpkiller is the best choice. Dumpkiller will bring you state-of-the-art skills in the IT industry as well as easily pass the Microsoft DP-750 exam. We all know that this exam is tough, but it is not impossible if you want to pass it. You can choose learning tools to pass the exam. I suggest you choose Dumpkiller Microsoft DP-750 Exam Questions And Answers. I suggest you choose Dumpkiller Microsoft DP-750 exam questions and answers. The training not only complete but real wide coverage. The test questions have high degree of simulation. This is the result of many exam practice. If you want to participate in the Microsoft DP-750 exam, then select the Dumpkiller, this is absolutely right choice.
DP-750 Valid Exam Camp Pdf: https://www.dumpkiller.com/DP-750_braindumps.html