100% Pass Quiz 2026 Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Pass-Sure Reliable Braindumps Pdf

The passing rate of our Certified-Data-Engineer-Professional exam materials are very high and about 99% and so usually the client will pass the exam successfully. But in case the client fails in the exam unfortunately we will refund the client immediately in full at one time. The refund procedures are very simple if you provide the Certified-Data-Engineer-Professional exam proof of the failure marks we will refund you immediately. If any questions or doubts exist, the client can contact our online customer service or send mails to contact us and we will solve them as quickly as we can. We always want to let the clients be satisfied and provide the best Certified-Data-Engineer-Professional Test Torrent and won’t waste their money and energy.
| Section | Objectives |
|---|
| Topic 1: Debugging and Deploying | - Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
|
| Topic 2: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Topic 3: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 2. Apply Change Data Feed to address streaming table limitations and improve latency
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 5. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
|
| Topic 4: Data Modeling | - Design and optimize data models
- 1. Design dimensional models for analytical workloads with efficient querying and aggregation
- 2. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 3. Simplify data layout decisions and optimize query performance using liquid clustering
- 4. Design and implement scalable data models using Delta Lake to manage large datasets
|
| Topic 5: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 3. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 4. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 5. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 6. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 7. Create pipeline components using control flow operators such as if/else and foreach
- 8. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
|
| Topic 6: Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
|
| Topic 7: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Topic 8: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 9: Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Topic 10: Monitoring and Alerting | - Monitoring
- 1. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 2. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 3. Use Query Profile and Spark UI to monitor workloads
- 4. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
|
>> Reliable Certified-Data-Engineer-Professional Braindumps Pdf <<
Real Certified-Data-Engineer-Professional Exam | Valid Certified-Data-Engineer-Professional Exam Papers
Generally speaking, Certified-Data-Engineer-Professional certification has become one of the most authoritative voices speaking to us today. Let us make our life easier by learning to choose the proper Certified-Data-Engineer-Professional study materials, pass the exam, obtain the certification, and be the master of your own life, not its salve. There are so many of them that they make you believe that their product is what you are looking for. With one type of Certified-Data-Engineer-Professional Study Materials are often shown one after another so that you are confused as to which product you should choose.
Databricks Certified Data Engineer Professional Sample Questions (Q154-Q159):
NEW QUESTION # 154
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.
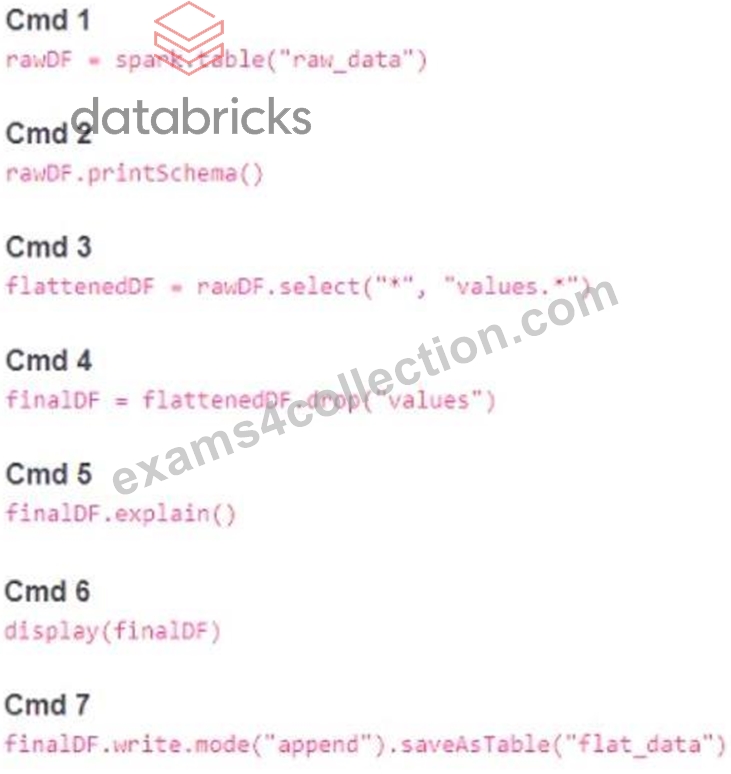
Which command should be removed from the notebook before scheduling it as a job?
- A. Cmd 4
- B. Cmd 5
- C. Cmd 3
- D. Cmd 6
- E. Cmd 2
Answer: D
Explanation:
When scheduling a Databricks notebook as a job, it's generally recommended to remove or modify commands that involve displaying output, such as using the display() function. Displaying data using display() is an interactive feature designed for exploration and visualization within the notebook interface and may not work well in a production job context.
The finalDF.explain() command, which provides the execution plan of the DataFrame transformations and actions, is often useful for debugging and optimizing queries. While it doesn't display interactive visualizations like display(), it can still be informative for understanding how Spark is executing the operations on your DataFrame.
NEW QUESTION # 155
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).
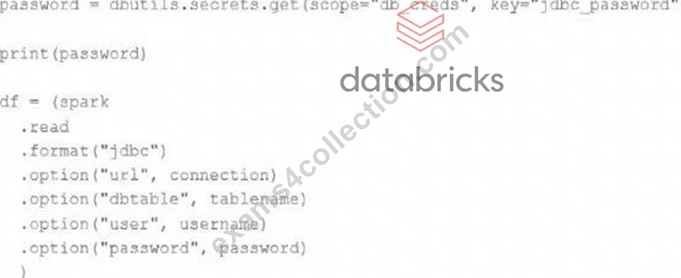
Which statement describes what will happen when the above code is executed?
- A. The connection to the external table will fail; the string "redacted" will be printed.
- B. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the password will be printed in plain text.
- C. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the encoded password will be saved to DBFS.
- D. The connection to the external table will succeed; the string "redacted" will be printed.
- E. The connection to the external table will succeed; the string value of password will be printed in plain text.
Answer: D
Explanation:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks.
NEW QUESTION # 156
A data engineer is optimizing a managed Delta table that suffers from data skew and frequently changing query filter columns. The engineer wants to avoid costly data rewrites when query patterns evolve. The table size is under 1 TB. How should the data engineer meet this requirement?
- A. Use Hive-style partitioning, as it provides efficient data skipping and is easy to change partition columns at any time.
- B. Apply Z-ordering, since it allows flexible reorganization of data layout without rewriting existing files and adapts easily to new filter columns.
- C. Enable liquid clustering, as it efficiently handles data skew, allows clustering keys to be changed without rewriting existing data, and adapts to evolving query patterns.
- D. Combine partitioning and Z-ordering to maximize flexibility and minimize maintenance as query patterns change.
Answer: C
Explanation:
Liquid clustering is designed for managed tables under 1TB with evolving query patterns. It efficiently addresses data skew, continuously optimizes data layout, and allows clustering keys to be changed without requiring full data rewrites, making it well suited for frequently changing filter columns while minimizing maintenance overhead.
NEW QUESTION # 157
A data engineer is using the AUTO CDC API in Lakeflow Spark Declarative Pipeline to propagate deletions from a source table (orders_source) to a target table (orders_target). The source has Change Data Feed (CDF) enabled, but some delete events arrive out of order due to upstream delays. How does the AUTO CDC API internally ensure deletions are applied correctly despite out-of-order events?
- A. It manually sorts incoming events by timestamp before applying changes.
- B. It uses sequence_by to order events and retains tombstones for deleted rows until older sequences are processed.
- C. It ignores deletions if they arrive after updates for the same key.
- D. It runs VACUUM on the target table to purge conflicting records.
Answer: B
Explanation:
AUTO CDC uses the sequence_by column to deterministically order change events for each key.
Delete operations create tombstones that are retained until all earlier sequence values have been processed, ensuring that out-of-order delete events are still applied correctly and consistently in the target table.
NEW QUESTION # 158
The data architect has mandated that all tables in the Lakehouse should be configured as external (also known as "unmanaged") Delta Lake tables.
Which approach will ensure that this requirement is met?
- A. When configuring an external data warehouse for all table storage, leverage Databricks for all ELT.
- B. When data is saved to a table, make sure that a full file path is specified alongside the Delta format.
- C. When the workspace is being configured, make sure that external cloud object storage has been mounted.
- D. When a database is being created, make sure that the LOCATION keyword is used.
- E. When tables are created, make sure that the EXTERNAL keyword is used in the CREATE TABLE statement.
Answer: E
Explanation:
To create an external or unmanaged Delta Lake table, you need to use the EXTERNAL keyword in the CREATE TABLE statement. This indicates that the table is not managed by the catalog and the data files are not deleted when the table is dropped. You also need to provide a LOCATION clause to specify the path where the data files are stored.
For example:
CREATE EXTERNAL TABLE events ( date DATE, eventId STRING, eventType STRING, data STRING) USING DELTA LOCATION `/mnt/delta/events'; This creates an external Delta Lake table named events that references the data files in the
`/mnt/delta/events' path. If you drop this table, the data files will remain intact and you can recreate the table with the same statement.
NEW QUESTION # 159
......
We boost a professional expert team to undertake the research and the production of our Certified-Data-Engineer-Professional learning file. We employ the senior lecturers and authorized authors who have published the articles about the test to compile and organize the Certified-Data-Engineer-Professional prep guide materials. Our expert team boosts profound industry experiences and they use their precise logic to verify the test. They provide comprehensive explanation and integral details of the answers and questions to help you pass the Certified-Data-Engineer-Professional Exam easily.
Real Certified-Data-Engineer-Professional Exam: https://www.exams4collection.com/Certified-Data-Engineer-Professional-latest-braindumps.html
- Well-Prepared Reliable Certified-Data-Engineer-Professional Braindumps Pdf - Professional Real Certified-Data-Engineer-Professional Exam - Excellent Valid Certified-Data-Engineer-Professional Exam Papers 🧖 Easily obtain ➥ Certified-Data-Engineer-Professional 🡄 for free download through ➡ www.exam4labs.com ️⬅️ 🤵Certified-Data-Engineer-Professional Reliable Dumps Pdf
- Reliable Certified-Data-Engineer-Professional Braindumps Pdf | High Pass-Rate Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional 100% Pass 🌷 The page for free download of “ Certified-Data-Engineer-Professional ” on 《 www.pdfvce.com 》 will open immediately 📎Certified-Data-Engineer-Professional Latest Test Cram
- Well-Prepared Reliable Certified-Data-Engineer-Professional Braindumps Pdf - Professional Real Certified-Data-Engineer-Professional Exam - Excellent Valid Certified-Data-Engineer-Professional Exam Papers 🦨 Search on ☀ www.troytecdumps.com ️☀️ for ➠ Certified-Data-Engineer-Professional 🠰 to obtain exam materials for free download 🤶Certified-Data-Engineer-Professional Latest Exam Pass4sure
- Reliable Certified-Data-Engineer-Professional Braindumps Pdf | High Pass-Rate Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional 100% Pass ↔ The page for free download of ▷ Certified-Data-Engineer-Professional ◁ on 「 www.pdfvce.com 」 will open immediately 🦌Certified-Data-Engineer-Professional Actual Exam
- Well-Prepared Reliable Certified-Data-Engineer-Professional Braindumps Pdf - Professional Real Certified-Data-Engineer-Professional Exam - Excellent Valid Certified-Data-Engineer-Professional Exam Papers 🥳 Search for ➡ Certified-Data-Engineer-Professional ️⬅️ and obtain a free download on ➥ www.practicevce.com 🡄 🌷Real Certified-Data-Engineer-Professional Dumps
- Certified-Data-Engineer-Professional Latest Exam Discount 🐍 Real Certified-Data-Engineer-Professional Dumps 🆚 Learning Certified-Data-Engineer-Professional Mode 🥴 Open website ✔ www.pdfvce.com ️✔️ and search for ➠ Certified-Data-Engineer-Professional 🠰 for free download 🕎Certified-Data-Engineer-Professional Reliable Dumps Pdf
- Certified-Data-Engineer-Professional Actual Exam 🚅 Certified-Data-Engineer-Professional Test Result 🅿 New Certified-Data-Engineer-Professional Exam Sample 🎼 Copy URL ▷ www.prep4away.com ◁ open and search for ⇛ Certified-Data-Engineer-Professional ⇚ to download for free 🦃New Certified-Data-Engineer-Professional Exam Discount
- Free PDF 2026 Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional –The Best Reliable Braindumps Pdf 🤛 Simply search for ➥ Certified-Data-Engineer-Professional 🡄 for free download on ▛ www.pdfvce.com ▟ 🎴Latest Certified-Data-Engineer-Professional Exam Labs
- Certified-Data-Engineer-Professional Latest Exam Cram ✡ Certified-Data-Engineer-Professional Latest Exam Cram 🪔 Certified-Data-Engineer-Professional Actual Exam 👐 Easily obtain free download of ( Certified-Data-Engineer-Professional ) by searching on ➤ www.examcollectionpass.com ⮘ 💖New Certified-Data-Engineer-Professional Test Forum
- 100% Pass Quiz 2026 Newest Databricks Reliable Certified-Data-Engineer-Professional Braindumps Pdf 🗺 Go to website { www.pdfvce.com } open and search for ➤ Certified-Data-Engineer-Professional ⮘ to download for free 🌒Certified-Data-Engineer-Professional Pass Test Guide
- Reliable Certified-Data-Engineer-Professional Braindumps Pdf | High Pass-Rate Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional 100% Pass 🦪 ➽ www.prepawaypdf.com 🢪 is best website to obtain ➽ Certified-Data-Engineer-Professional 🢪 for free download 🙉Certified-Data-Engineer-Professional Latest Test Cram
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, portfolium.com, Disposable vapes