We all have the right to pursue happiness. Also, we have the chance to generate a golden bowl for ourselves. Now, our Certified-Data-Engineer-Professional practice materials can help you achieve your goals. As we all know, the pace of life is quickly in the modern society. So we must squeeze time to learn and become better. With the Certified-Data-Engineer-Professional Certification, your life will be changed thoroughly for you may find better jobs and gain higher incomes to lead a better life style. And our Certified-Data-Engineer-Professional exam questions will be your best assistant.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Developing Code for Data Processing using Python and SQL | ~22% | - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Implement scalable Python/SQL code and project structures - Manage dependencies, libraries, and UDFs |
| Topic 2: Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables - Diagnose common pipeline and job failures |
| Topic 3: CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines - Deploy with Declarative Automation Bundles, CLI, and REST API |
| Topic 4: Data Modeling | ~10% | - Apply dimensional modeling techniques - Design scalable Delta Lake schemas and clustering |
| Topic 5: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Topic 6: Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data - Apply advanced Spark transformations |
| Topic 7: Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines - Apply AUTO CDC APIs and exactly-once semantics |
| Topic 8: Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| Topic 9: Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage - Leverage system tables and observability tools |
>> Certified-Data-Engineer-Professional Latest Practice Materials <<
What is the measure of competence? Of course, most companies will judge your level according to the number of qualifications you have obtained. It may not be comprehensive, but passing the qualifying exam is a pretty straightforward way to hire an employer. Our Certified-Data-Engineer-Professional exam practice questions on the market this recruitment phenomenon, tailored for the user the fast pass the Certified-Data-Engineer-Professional examination method of study. The quality of our Certified-Data-Engineer-Professional learning guide is absolutely superior, which can be reflected from the annual high pass rate of our Certified-Data-Engineer-Professional exam questions.
NEW QUESTION # 247
A company wants to implement Lakehouse Federation across multiple data sources but is concerned about data consistency and ensuring that all teams access the same authoritative version of their data. Which statement is applicable for Lakehouse Federations to maintain data consistency?
Answer: D
Explanation:
Lakehouse Federation allows Databricks to query and manage external data sources through a single governance layer, without moving or copying data. The documentation specifies that
"Federated queries provide read-only access to data, reflecting the current state of the underlying source system." This ensures consistency across teams since all users access the same source of truth directly from the external system through Unity Catalog. Federation does not perform CDC replication or local caching; it queries live data on demand. Hence, option A accurately represents how Lakehouse Federation maintains consistency across federated sources.
NEW QUESTION # 248
Which Python variable contains a list of directories to be searched when trying to locate required modules?
Answer: C
Explanation:
sys. path is a built-in variable within the sys module. It contains a list of directories that the interpreter will search in for the required module.
NEW QUESTION # 249
A transactions table has been liquid clustered on the columns product_id, user_id, and event_date. Which operation lacks support for cluster on write?
Answer: C
Explanation:
Delta Lake's Liquid Clustering is an advanced feature that improves query performance by dynamically clustering data without requiring costly compaction steps like traditional Z-ordering.
When performing writes to a Liquid Clustered table, some write operations automatically maintain clustering, while others do not.
NEW QUESTION # 250
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Incremental state information should be maintained for 10 minutes for late-arriving data.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block: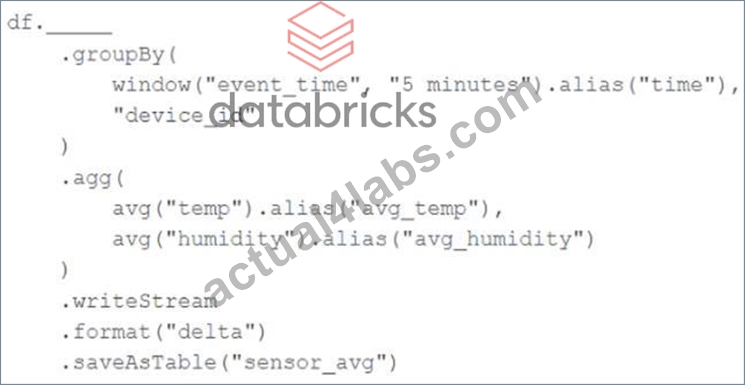
Choose the response that correctly fills in the blank within the code block to complete this task.
Answer: A
Explanation:
This is because the question asks for incremental state information to be maintained for 10 minutes for late-arriving data. The withWatermark method is used to define the watermark for late data. The watermark is a timestamp column and a threshold that tells the system how long to wait for late data. In this case, the watermark is set to 10 minutes. The other options are incorrect because they are not valid methods or syntax for watermarking in Structured Streaming.
NEW QUESTION # 251
A data engineer is designing a Lakeflow Declarative Pipeline to process streaming order data.
The pipeline uses Auto Loader to ingest data and must enforce data quality by ensuring customer_id and amount are greater than zero. Invalid records should be dropped. Which Lakeflow Declarative Pipelines configurations implement this requirement using Python?
Answer: A
Explanation:
Lakeflow Declarative Pipelines (LDP), formerly Delta Live Tables (DLT), supports enforcing data quality using expectations. Expectations can either:
Track violations (expect) -> records that do not meet conditions are flagged but still included in the pipeline.
Drop violations (expect_or_drop) -> records that do not meet conditions are excluded from downstream tables.
Fail pipeline on violations (expect_or_fail) -> records that fail conditions stop the pipeline.
In this scenario, the requirement explicitly states that invalid records (where customer_id is null or amount < 0) must be dropped. According to the official documentation, the correct method is .expect_or_drop("expectation_name", "SQL_predicate") applied on the streaming input.
Option A is correct: It uses .expect_or_drop directly within the transformation chain for both rules, ensuring records that fail are removed before writing to the silver table.
Option B incorrectly uses @dlt.expect decorators, which only track violations but do not drop invalid rows.
Option C uses .expect, which also only flags rows, not drop them.
Option D uses @dlt.expect_or_drop decorator syntax, which is not supported in Python API; expect_or_drop must be applied as a method on the DataFrame, not as a decorator.
Therefore, the correct solution is Option A, which ensures compliance by enforcing data quality and dropping invalid rows programmatically during ingestion.
NEW QUESTION # 252
......
Despite the complex technical concepts, our Certified-Data-Engineer-Professional exam questions have been simplified to the level of average candidates, posing no hurdles in understanding the various ideas. It is also the reason that our Certified-Data-Engineer-Professional study guide is famous all over the world. We also have tens of thousands of our loyal customers who support us on the Certified-Data-Engineer-Professional Learning Materials. Just look at the feedbacks on our website, they all praised our Certified-Data-Engineer-Professional practice engine.
Certified-Data-Engineer-Professional Test Practice: https://www.actual4labs.com/Databricks/Certified-Data-Engineer-Professional-actual-exam-dumps.html