To make this task easier for you, Microsoft provides you with the most reliable and concise practice material, to pass the Microsoft AI-200 in the first go. We make sure that a more confident and well-prepared student enters the Microsoft AI-200. This is a convenient and manageable e-book format that contains actual Microsoft AI-200 questions.
| Section | Objectives |
|---|---|
| Topic 1: Develop containerized solutions on Azure | - Implement containerized applications
|
| Topic 2: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Topic 3: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Topic 4: Connect to and consume Azure services | - Integrate Azure services
|
A Microsoft AI-200 practice questions is a helpful, proven strategy to crack the Microsoft AI-200 exam successfully. It helps candidates to know their weaknesses and overall performance. DumpTorrent software has hundreds of Microsoft exam dumps that are useful to practice in real time. The Developing AI Cloud Solutions on Azure (AI-200) practice questions have a close resemblance with the actual AI-200 exam.
NEW QUESTION # 24
You need to deploy a batch retraining workload.
How should you complete the scaling configuration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.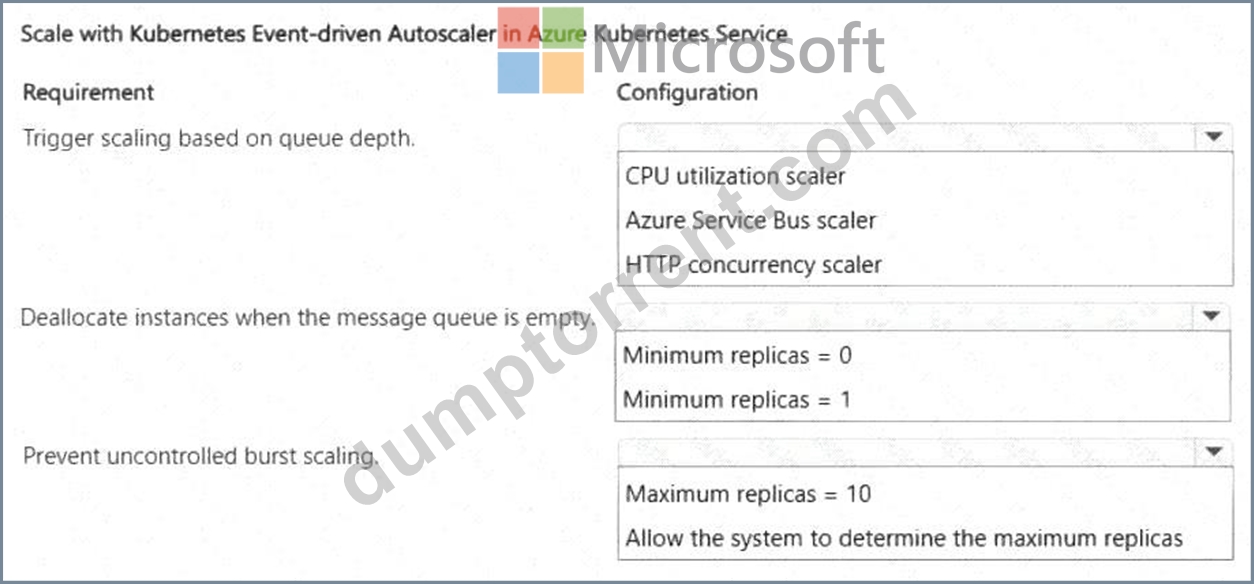
Answer:
Explanation: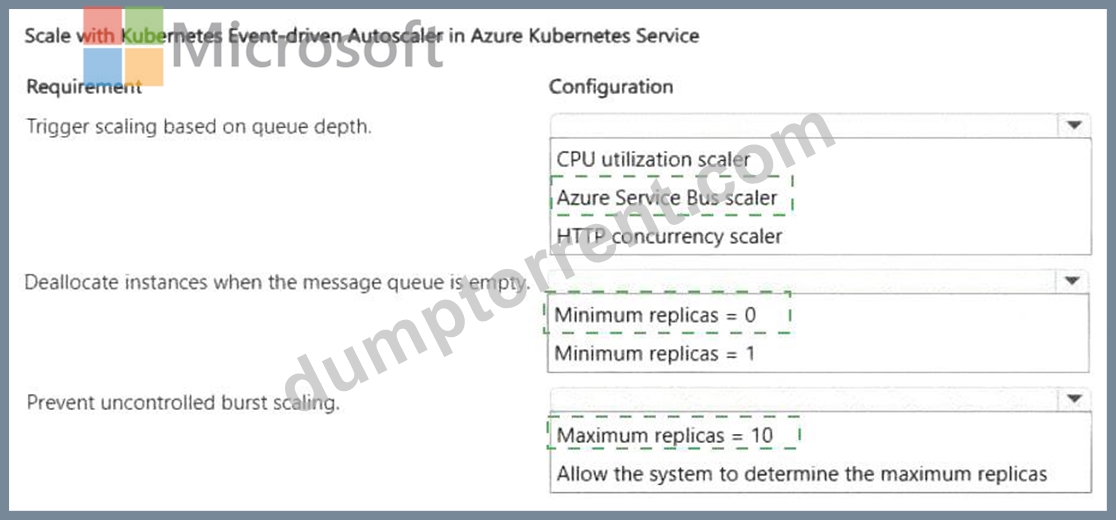
Explanation:
* Trigger scaling based on queue depth: Azure Service Bus scaler
* Deallocate instances when the message queue is empty: Minimum replicas = 0
* Prevent uncontrolled burst scaling: Maximum replicas = 10
The batch retraining workload must scale according to queue length , so the correct KEDA trigger is the Azure Service Bus scaler . KEDA integrates with Azure Service Bus and monitors queue or subscription metrics, allowing AKS workloads to scale according to the number of pending messages rather than CPU utilization or HTTP request concurrency. Microsoft documents KEDA as the event-driven autoscaling mechanism for AKS and specifically supports Azure-based scalers for queue-driven workloads.
To meet the requirement to deallocate workload instances when no messages remain, configure minimum replicas = 0 . KEDA supports scale-to-zero for event-driven workloads, which is particularly appropriate for intermittent batch or machine-learning processing because no pods need to remain running while the queue is empty. Microsoft specifically identifies scale-to-zero as a KEDA capability and recommends it for sporadic ML workloads where cost optimization is important.
Finally, configure maximum replicas = 10 . A finite maximum replica count establishes an explicit upper scaling boundary, preventing large queue bursts from creating an uncontrolled number of worker replicas and protecting both infrastructure cost and downstream services.
Study Guide references: AKS # KEDA; Azure Service Bus event-driven scaling; minReplicaCount; maxReplicaCount; scale-to-zero; autoscaling limits.
NEW QUESTION # 25
You need to secure an Azure OpenAI resource so that it is only reachable from your virtual network and not from the public internet. What should you configure?
Answer: D
NEW QUESTION # 26
You are developing an AI search API that caches semantic search results in Redis.
Search results must remain cached for 10 minutes. If the underlying data changes, cached entries must NOT be returned.
You need to implement a cache-aside strategy to ensure data consistency.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,C
Explanation:
Delete keys on mutation. Implement an event-driven or database-hook system to purge related Redis keys the moment the source data updates.
Use absolute expiration. Set a strict, un-extendable Time-To-Live (TTL) of 10 minutes when writing to the cache, ensuring the data naturally expires even if a deletion event is missed.
Incorrect:
[Not C]
Implementing a sliding expiration is not a good step for this specific architecture because it violates the requirement that entries must not be returned if the underlying data changes.
Reference:
https://medium.com/real-world-net/net-caching-strategies-compared-redis-vs-memory-vs-hybrid-b8b8be1e708d
NEW QUESTION # 27
You are developing a .NET application that uses Azure Cosmos DB for NoSQL to store application data The application uses the Azure Cosmos DB for NoSQL SDK to interact with the database account. The application must perform the following tasks
* Initialize the connection by using the account endpoint and key.
* Define shared throughput.
* Perform create, read, update, and delete (CRUD) operations on items stored in a container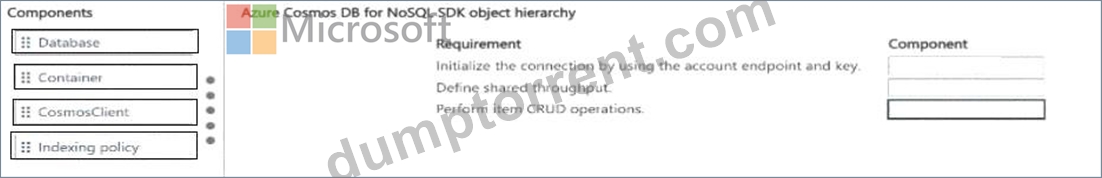
Answer:
Explanation: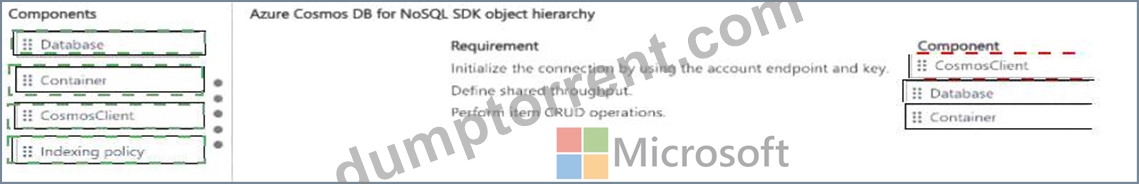
Explanation: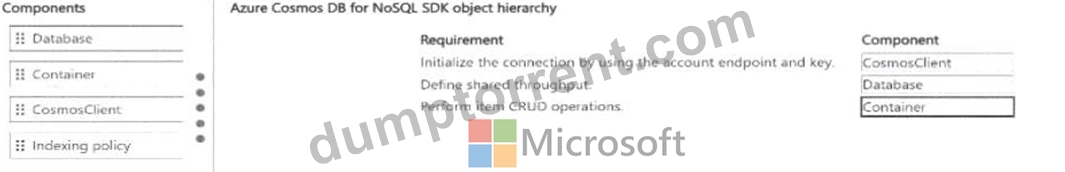
Verified answer: Initialize connection: CosmosClient. Define shared throughput: Database. Perform item CRUD: Container.
Detailed Explanation: The Cosmos DB SDK follows the service resource hierarchy. CosmosClient represents the account connection and is initialized with the account endpoint and credential. Shared throughput is configured at the database level when multiple containers share database throughput. Item create, read, update, and delete operations are performed through a container object because containers hold items and define partitioning/indexing behavior. An indexing policy is configuration attached to a container, not the SDK object used for CRUD.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Cosmos DB databases, containers, and items
NEW QUESTION # 28
A large retail company operates online and physical stores. The company tracks inventory levels in real time to manage stock efficiently across all locations. You develop an Azure Event Grid solution to handle events generated by the inventory management system deployed to Azure.
You need to implement a subscription filter that dynamically adjusts to seasonal changes in product demand.
Which event filter should you use?
Answer: B
Explanation:
To handle dynamic, seasonal changes in product demand within Azure Event Grid, you should use Advanced Filters with a string or numeric comparison that evaluates event data attributes, typically paired with an automated external process (like an Azure Function or Logic App) to dynamically update the subscription filter rules via the Event Grid management API as seasons change Reference:
https://techcommunity.microsoft.com/blog/analyticsonazure/a-technical-implementation-guide-for-multi-store-retail-environments/4488418
NEW QUESTION # 29
......
Are you ready to take your career to the next level with the Developing AI Cloud Solutions on Azure (AI-200)? Look no further than DumpTorrent for all of your Developing AI Cloud Solutions on Azure (AI-200) exam needs. Our comprehensive and cost-effective solution includes regularly updated Microsoft AI-200 Exam Questions, available in a convenient PDF format that can be downloaded on any device, including PC, laptop, mac, tablet, and smartphone.
AI-200 Reliable Cram Materials: https://www.dumptorrent.com/AI-200-braindumps-torrent.html