BTW, DOWNLOAD part of ValidTorrent DAA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1Fd_O4LwHsJ0h7_RojMuVKUZbnw8w9F5x
You can get prepared with our Snowflake DAA-C01 exam materials only for 20 to 30 hours before you go to attend your exam. we can claim that you will achieve guaranteed success with our DAA-C01 study guide for that our high pass rate is unmarched 98% to 100%. And all the warm feedback from our clients proved our strength, you can totally relay on us with our Snowflake DAA-C01 practice quiz!
| Section | Objectives |
|---|---|
| Data Modeling and Performance Optimization | - Modeling approaches in Snowflake
|
| Security, Governance, and Data Sharing | - Data sharing and governance
|
| Snowflake Architecture and Data Platform Fundamentals | - Snowflake architecture concepts
|
| Data Transformation and Analysis | - SQL-based transformations
|
| Data Loading and Unloading | - Data ingestion methods
|
>> Pdf Snowflake DAA-C01 Version <<
We regard the customer as king so we put a high emphasis on the trust of every users, therefore our security system can protect you both in payment of DAA-C01 guide braindumps and promise that your computer will not be infected during the process of payment on our DAA-C01 Study Materials. Moreover, if you end up the cooperation between us,we have the responsibility to delete your personal information on DAA-C01 exam prep. In a word, Wwe have data protection act for you to avoid information leakage!
NEW QUESTION # 29
You have a Snowflake table named 'sensor_data' with a column 'reading' containing JSON data'. The JSON structure varies, but you want to extract a specific nested value, 'temperature', using a UDE The path to 'temperature' might be different depending on the 'sensor_type'. Some sensors have the temperature at '$.metrics.temperature' , others at '$.reading.temp_c'. The sensor type is stored in the 'sensor_type' column. You want to create a UDF named which takes the JSON 'reading' and the 'sensor_type' as input and extracts the temperature, returning NULL if the path does not exist in the JSON. How can you implement this using a JavaScript UDF and Snowflake's JSON parsing functions for optimal performance?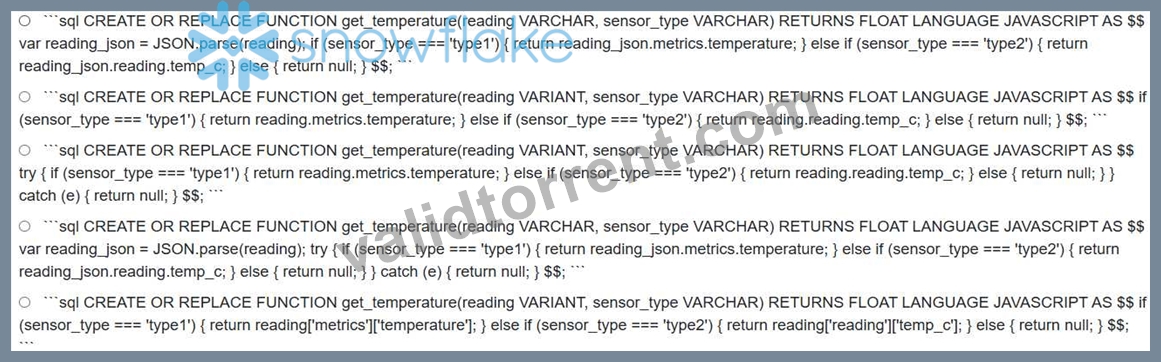
Answer: C
Explanation:
Option C is the MOST optimal. It uses 'VARIANT as the input data type for 'reading' , which avoids the unnecessary parsing of JSON using as Snowflake automatically parses JSON data into a VARIANT type. It also includes a 'try...catch' block to handle cases where the specified path does not exist within the JSON, returning 'NULL' as required. This prevents errors from halting the query. Using 'VARIANT directly and exception handling offers superior performance. Option A and D parse VARIANT as String, leading to parsing overhead. B misses the try catch block and is prone to failure when temp is not available for a given sensor. Option E is less efficient than option C due to using array notation.
NEW QUESTION # 30
You are designing a data pipeline to ingest JSON data from an external stage (AWS S3) into a Snowflake table called 'ORDERS' Some of the JSON files contain nested arrays that need to be flattened and transformed during the loading process. You have already defined a VARIANT column in the 'ORDERS table to store the raw JSON data'. However, occasionally, some files fail to load completely, and the 'SYSTEM$PIPE STATUS' shows a 'LOAD FAILED' status without providing granular details about the specific records causing the failure. Which of the following strategies, used IN COMBINATION, would be MOST effective in troubleshooting and resolving these failures while minimizing the impact on the overall data ingestion process?
Answer: A,C
Explanation:
ERROR INTEGRATION' allows you to inspect individual error records and identify patterns in those failing files. The 'VALIDATE' function allows you to perform a COPY INTO using similar parameters as your copy into statement to validate the record, and helps you tune your data pipeline for errors. Option B is viable, but has increased maintenance overhead compared to VALIDATE, because you would need to write code for the preprocessing. Option D focuses on resource allocation, which doesn't directly address data quality issues. Option E by itself only attempts to continue, and doesn't do any validation. 'ON is a good idea when paired with validating the data after the load.
NEW QUESTION # 31
A Data Analyst wants to transform query results. Which transformation option will incur compute costs?
Answer: D
Explanation:
In the Snowflake Snowsight interface, it is critical to distinguish between UI-level formatting and engine- level processing. Snowsight provides several client-side features that allow an analyst to change how data is displayed without re-executing the underlying SQL query or utilizing virtual warehouse credits.
Client-Side (No Compute Cost):
Formatting options such as adding thousand separators (Option A), adjusting the visible decimal precision (Option C), or changing the display format of dates and timestamps (Option D) are typically handled by the Snowsight web interface itself. These transformations are applied to the data that has already been retrieved into the browser's local result cache. Because they do not require the virtual warehouse to scan micro- partitions or perform new calculations, they do not incur additional compute costs.
Engine-Level (Incurs Compute Cost):
Sorting a column (Option B) is fundamentally different. While Snowsight allows you to click a column header to sort, this action frequently triggers a re-query or a secondary processing step if the entire result set is not already fully cached in the browser's memory. When you use "column options" to perform operations like sorting, filtering, or grouping on large datasets, Snowflake often has to leverage the virtual warehouse to reorganize the data. In the context of the Snowflake Data Analyst exam, sorting is identified as a transformation that requires active compute resources because the engine must evaluate the entire dataset to determine the new order of records.
Furthermore, even if a small result set is cached, complex sorting across large volumes of data necessitates warehouse involvement to ensure accuracy and handle "spilling" to local or remote storage if the sort operation exceeds available memory. Therefore, while visual "masks" are free, structural data reorganization like sorting is a compute-intensive task.
NEW QUESTION # 32
Configuring subscriptions and updates in a dashboard tool primarily helps in:
Answer: B
NEW QUESTION # 33
Your company is using Snowflake to store customer transaction data'. You want to enrich this data with demographic information from a Snowflake Marketplace data provider. The provider offers a secure data share with a view called 'CUSTOMER DEMOGRAPHICS. You need to join the customer transaction data in your 'TRANSACTIONS' table with the demographic data from the 'CUSTOMER DEMOGRAPHICS' view. Which of the following SQL queries is the MOST efficient and secure way to achieve this, assuming you have already created a database from the share?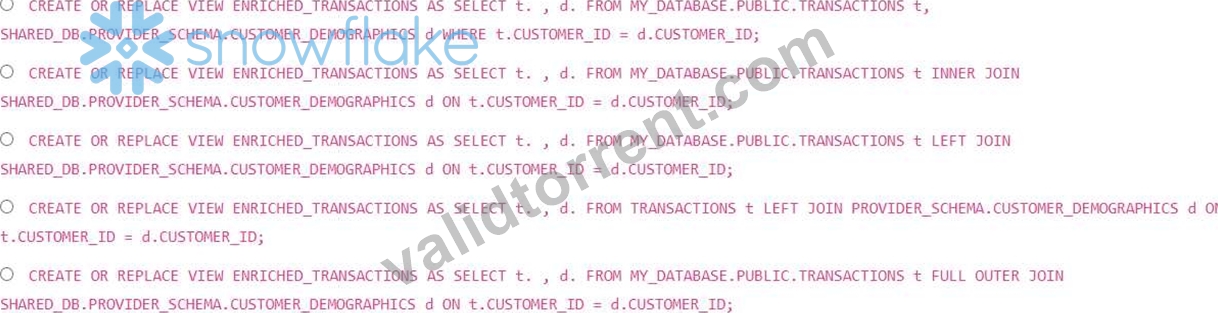
Answer: B
Explanation:
Option B is the most efficient and secure because it explicitly uses an INNER JOIN, ensuring that only matching records between the TRANSACTION table and the Customer Demographics view are included. Using INNER JOIN improves performance compared to implicit joins (Option A). Options C and E uses LEFT and FULL OUTER joins which might result in unnecessary nulls and impacting the perfromance. Option D will not work because the schema name is missing.
NEW QUESTION # 34
......
Our DAA-C01 exam dumps strive for providing you a comfortable study platform and continuously explore more functions to meet every customer’s requirements. We may foresee the prosperous talent market with more and more workers attempting to reach a high level through the Snowflake certification. To deliver on the commitments of our DAA-C01 test prep that we have made for the majority of candidates, we prioritize the research and development of our DAA-C01 Test Braindumps, establishing action plans with clear goals of helping them get the Snowflake certification. You can totally rely on our products for your future learning path. Full details on our DAA-C01 test braindumps are available as follows.
Test DAA-C01 Pdf: https://www.validtorrent.com/DAA-C01-valid-exam-torrent.html
DOWNLOAD the newest ValidTorrent DAA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1Fd_O4LwHsJ0h7_RojMuVKUZbnw8w9F5x