그 외, DumpTOP MLA-C01 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=1qNlpXZ00F3yqa0iKU5TLMmvcj9v82TWa
DumpTOP는 Amazon인증관련덤프를 제공하는 최고의 업체입니다, 덤프들은 DumpTOP의 베터랑의 전문가들이 오랜 풍부한 경험과 MLA-C01지식으로 만들어낸 최고의 제품입니다. 그리고 우리는 온라인무료 서비스도 제공되어 제일 빠른 시간에 소통 상담이 가능합니다.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Exam Price: | 150 USD |
| Available Languages: | Japanese, English, Simplified Chinese, Korean |
| Exam Duration: | 130 minutes |
| Certificate Validity Period: | 3 years |
| Related Certifications: | AWS Certified AI Practitioner AWS Certified Machine Learning - Specialty |
| Exam Format: | Matching, Case study, Ordering, Multiple choice, Multiple response |
| Real Exam Qty: | 65 (50 scored, 15 unscored) |
| Passing Score: | 720 (scaled score 100–1000) |
| Recommended Training: | AWS Training and Certification AWS Certified Machine Learning Engineer - Associate Official Exam Guide |
| Exam Registration: | AWS Certification Portal Pearson VUE Registration |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored or onsite at Pearson VUE testing centers |
| Pre Condition: | Recommended: 1+ year hands-on experience with AWS services and machine learning engineering; familiarity with Amazon SageMaker and related ML services. No mandatory prerequisite exams. |
| Official Syllabus URL: | https://docs.aws.amazon.com/aws-certification/latest/machine-learning-engineer-associate-01/machine-learning-engineer-associate-01.html |
안심하시고DumpTOP 를 선택하게 하기 위하여, DumpTOP에서는 이미Amazon MLA-C01인증시험의 일부 문제와 답을 사이트에 올려놨으니 체험해보실 수 있습니다. 그러면 저희한테 신뢰가 갈 것이며 또 망설임 없이 선택하게 될 것입니다. 저희 덤프로 여러분은 한번에 시험을 패스할 수 있으며 또 개인시간도 절약하고 무엇보다도 금전상으로 절약이 제일 크다고 봅니다. DumpTOP는 여러분들한테 최고의Amazon MLA-C01문제와 답을 제공함으로 100%로의 보장 도를 자랑합니다, 여러분은Amazon MLA-C01인증시험의 패스로 IT업계여서도 또 직장에서도 한층 업그레이드되실 수 있습니다. 여러분의 미래는 더욱더 아름다울 것입니다.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
| 주제 4 |
|
질문 # 186
A company needs to give its ML engineers appropriate access to training data. The ML engineers must access training data from only their own business group. The ML engineers must not be allowed to access training data from other business groups.
The company uses a single AWS account and stores all the training data in Amazon S3 buckets.
All ML model training occurs in Amazon SageMaker.
Which solution will provide the ML engineers with the appropriate access?
정답:D
질문 # 187
A company stores historical data in .csv files in Amazon S3. Only some of the rows and columns in the .csv files are populated. The columns are not labeled. An ML engineer needs to prepare and store the data so that the company can use the data to train ML models.
Select and order the correct steps from the following list to perform this task. Each step should be selected one time or not at all. (Select and order three.)
* Create an Amazon SageMaker batch transform job for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
* Use Amazon Athena to infer the schemas and available columns.
* Use AWS Glue crawlers to infer the schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.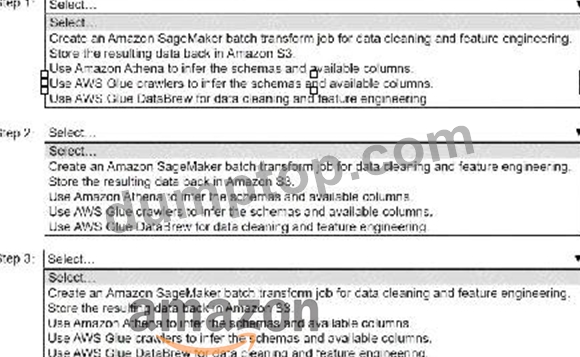
정답:
설명: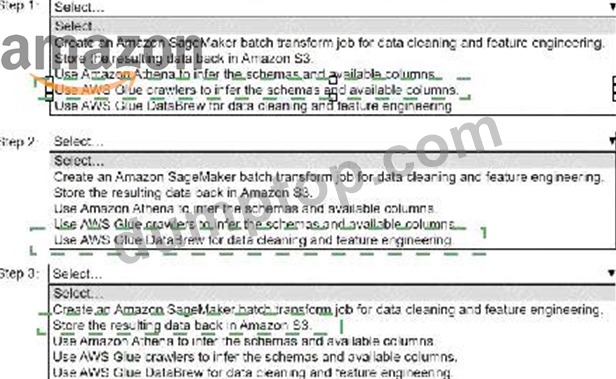
Explanation:
Step 1: Use AWS Glue crawlers to infer the schemas and available columns.Step 2: Use AWS Glue DataBrew for data cleaning and feature engineering.Step 3: Store the resulting data back in Amazon S3.
* Step 1: Use AWS Glue Crawlers to Infer Schemas and Available Columns
* Why?The data is stored in .csv files with unlabeled columns, and Glue Crawlers can scan the raw data in Amazon S3 to automatically infer the schema, including available columns, data types, and any missing or incomplete entries.
* How?Configure AWS Glue Crawlers to point to the S3 bucket containing the .csv files, and run the crawler to extract metadata. The crawler creates a schema in the AWS Glue Data Catalog, which can then be used for subsequent transformations.
* Step 2: Use AWS Glue DataBrew for Data Cleaning and Feature Engineering
* Why?Glue DataBrew is a visual data preparation tool that allows for comprehensive cleaning and transformation of data. It supports imputation of missing values, renaming columns, feature engineering, and more without requiring extensive coding.
* How?Use Glue DataBrew to connect to the inferred schema from Step 1 and perform data cleaning and feature engineering tasks like filling in missing rows/columns, renaming unlabeled columns, and creating derived features.
* Step 3: Store the Resulting Data Back in Amazon S3
* Why?After cleaning and preparing the data, it needs to be saved back to Amazon S3 so that it can be used for training machine learning models.
* How?Configure Glue DataBrew to export the cleaned data to a specific S3 bucket location. This ensures the processed data is readily accessible for ML workflows.
Order Summary:
* Use AWS Glue crawlers to infer schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
This workflow ensures that the data is prepared efficiently for ML model training while leveraging AWS services for automation and scalability.
질문 # 188
A company uses Amazon SageMaker Studio to develop an ML model. The company has a single SageMaker Studio domain. An ML engineer needs to implement a solution that provides an automated alert when SageMaker compute costs reach a specific threshold.
Which solution will meet these requirements?
정답:A
설명:
Adding resource tagging to the SageMaker user profile enables tracking and monitoring of costs associated with specific SageMaker resources.
AWS Budgets allows setting thresholds and automated alerts for costs and usage, making it the ideal service to notify the ML engineer when compute costs reach a specified limit.
This solution is efficient and integrates seamlessly with SageMaker and AWS cost management tools.
질문 # 189
A company is using an ML model to classify motion in videos. The data is stored in MP4 format in Amazon S3. When the company created the model, the company needed 4 months to label all the video frames.
The company needs to retrain the model with an existing training workflow in Amazon SageMaker AI. An ML engineer must implement a solution that decreases the labeling time.
Which solution will meet these requirements?
정답:B
설명:
Option A is correct because Amazon SageMaker Ground Truth is the AWS service specifically designed to build labeled datasets for machine learning, including video classification and video frame labeling use cases. AWS documentation states that Ground Truth can take video files in MP4 format stored in Amazon S3 , automatically connect to that data, and extract video frames for labeling. This directly matches the scenario in the question, where the source data is MP4 in S3 and the company needs to relabel or expand training data for retraining an existing SageMaker workflow.
Ground Truth is also the best choice because AWS documents explain that it can reduce labeling time and cost through automated data labeling (active learning) for supported built-in task types. Instead of relying only on manual human labeling for every item, Ground Truth can use ML-assisted labeling to lower the total amount of human work needed, which is exactly what the company wants after previously spending four months labeling frames.
The other options do not fit as well. JumpStart provides pretrained models and solution templates, but AWS documentation does not position it as the service for running a video-frame labeling operation. Data Wrangler is for data preparation, transformation, and feature engineering, not human labeling of video frames. Amazon A2I with Rekognition is mainly documented for human review workflows such as Rekognition moderation outputs, not as the primary service for large-scale MP4 video-frame annotation used to create training datasets.
질문 # 190
A machine learning engineer is preparing a data frame for a supervised learning task with the Amazon SageMaker Linear Learner algorithm. The ML engineer notices the target label classes are highly imbalanced and multiple feature columns contain missing values. The proportion of missing values across the entire data frame is less than 5%.
What should the ML engineer do to minimize bias due to missing values?
정답:B
설명:
Use supervised learning to predict missing values based on the values of other features. Different supervised learning approaches might have different performances, but any properly implemented supervised learning approach should provide the same or better approximation than mean or median approximation, as proposed in responses A and C. Supervised learning applied to the imputation of missing values is an active field of research.
질문 # 191
......
MLA-C01최고품질 덤프문제모음집: https://www.dumptop.com/Amazon/MLA-C01-dump.html
그 외, DumpTOP MLA-C01 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=1qNlpXZ00F3yqa0iKU5TLMmvcj9v82TWa