We will provide high quality assurance of CCAR-P exam questions for our customers with dedication to ensure that we can develop a friendly and sustainable relationship. First of all, we have security and safety guarantee, which mean that you cannot be afraid of virus intrusion and information leakage since we have data protection acts, even though you end up studying CCAR-P test guide of our company, we will absolutely delete your personal information and never against ethic code to sell your message to the third parties. Secondly, our CCAR-P Exam Questions will spare no effort to perfect after-sales services. Thirdly countless demonstration and customer feedback suggest that our Claude Certified Architect - Professional study question can help them get the certification as soon as possible, thus becoming the elite, getting a promotion and a raise and so forth.
| Section | Weight | Objectives |
|---|---|---|
| Developer Productivity & Operational Enablement | 7% | - Improve developer workflows with AI-assisted tooling - Support debugging, monitoring, and operational resolution - Configure Claude tools and environments for teams |
| Evaluation, Testing & Optimization | 16% | - Define evaluation metrics and success criteria - Test accuracy, reliability, latency, and cost - Optimize performance, prompting, and model selection - Implement iterative improvement pipelines |
| Governance, Safety & Risk Management | 14% | - Ensure regulatory compliance (GDPR, HIPAA, etc.) - Manage data privacy and security compliance - Implement guardrails and safety controls - Address ethical AI considerations and bias mitigation |
| Integration | 19% | - Implement Model Context Protocol (MCP) integrations - Design authentication, authorization, and observability - Integrate with data pipelines and RAG systems - Integrate Claude with enterprise systems, APIs, and tools |
| Stakeholder Communication & Lifecycle Management | 14% | - Document architectures and support full lifecycle phases - Manage stakeholder feedback and expectation alignment - Communicate architectural decisions and trade-offs - Conduct structured discovery and requirement gathering |
| Claude Models, Prompting & Context Engineering | 13% | - Select appropriate Claude models based on trade-offs - Design system prompts, templates, and guardrails - Mitigate prompt injection, leaks, and jailbreak risks - Apply context engineering and context management techniques |
| Solution Design & Architecture | 17% | - Design end-to-end architectures and feedback loops - Translate business problems into Claude-based AI solutions - Design multi-agent systems and orchestration strategies - Align solutions to business value pillars - Select architectural patterns: workflow, agentic, augmented LLM |
>> Latest CCAR-P Exam Pattern <<
There is plenty of skilled and motivated staff to help you obtain the Claude Certified Architect - Professional exam certificate that you are looking forward. We have faith in our professional team and our CCAR-P Study Tool, and we also wish you trust us wholeheartedly. Because of this function, you can easily grasp how the practice system operates and be able to get hold of the core knowledge about the Claude Certified Architect - Professional exam. In addition, when you are in the real exam environment, you can learn to control your speed and quality in answering questions and form a good habit of doing exercise, so that you’re going to be fine in the Claude Certified Architect - Professional exam.
NEW QUESTION # 81
You are operating an interactive assistant whose dominant performance constraint is per-turn latency. Quality on routine turns is already acceptable.
Which configuration adjustment most directly improves latency without disproportionately damaging quality?
Answer: C
Explanation:
Option B targets two major contributors to per-turn latency: retrieved-context size and repeated prompt processing. Reducing retrieval to an empirically validated top- k limits the tokens Claude must process while preserving the passages that historically provide sufficient answer coverage. Caching the stable system- prompt prefix avoids repeatedly processing identical instructions.
Anthropic's latency guidance recommends choosing an appropriate model and reducing unnecessary input and output tokens. Its prompt-caching documentation explains that caching reusable prompt prefixes can reduce both repeated processing cost and latency. Reducing Latency , Prompt Caching The retrieval depth must be selected through evaluation rather than arbitrary truncation. The team should compare answer quality, retrieval recall, latency, and failure rates across candidate values and retain escalation logic for complex queries requiring deeper retrieval.
Option A removes an applicable latency optimization. Option C maximizes context consumption regardless of demonstrated benefit. Option D deliberately selects the slowest model class even though routine-turn quality already meets requirements.
Study Guide references/topics: Latency optimization; top- k retrieval; prompt caching; token reduction; quality-latency evaluation; adaptive retrieval.
NEW QUESTION # 82
You are designing a content moderation classifier that processes high volumes of user-generated comments under a tight per-message latency budget using well-defined classification labels.
Which model selection best aligns with the workload?
Answer: A
Explanation:
Haiku is the appropriate starting point because the workload is high-volume, latency-sensitive, and based on a stable closed set of moderation labels. These characteristics favor a fast, cost-efficient model capable of consistent classification without incurring the additional inference time and expense associated with deeper reasoning.
Anthropic's model-selection guidance requires architects to balance capability, speed, and cost rather than automatically selecting the most capable model. Its content-moderation guidance specifically identifies Haiku as a cost-effective option for processing moderation workloads at substantial scale. Choosing the Right Model
, Content Moderation
Opus is disproportionate to a routine closed-set classification problem. Sonnet may become justified if evaluation demonstrates that Haiku fails materially on complex policy distinctions, multilingual ambiguity, or adversarial edge cases, but it should not be selected merely because it is larger. Enabling extended thinking on every request would further increase latency and token consumption without evidence that the additional reasoning improves the defined success metrics. The correct architectural practice is to establish a representative moderation evaluation set, validate Haiku against accuracy and safety thresholds, and escalate only the cases that genuinely need deeper reasoning.
Study Guide references/topics: Model selection; capability-latency-cost trade-offs; classification workloads; evaluation-driven routing; moderation architecture.
NEW QUESTION # 83
You are comparing patterns for a batch document-classification job that follows fixed steps: extract metadata, classify, summarize, and persist.
Which pattern is the best fit and why?
Answer: B
Explanation:
A workflow is appropriate when processing stages and transitions are known in advance. Metadata extraction, classification, summarization, and persistence can be represented as deterministic nodes with explicit schemas, validation rules, retry policies, and failure handling. This provides predictable execution, cost, observability, and testability without paying for repeated model-driven planning. Anthropic's Building Effective AI Agents distinguishes workflows, where predefined code paths control execution, from agents, where the model dynamically determines its process. Option A reaches the correct pattern for an incorrect reason: workflows and agents can both invoke tools. Options B and C introduce unnecessary autonomy and make unsupported claims about consistency or universal accuracy.
Study Guide references/topics: Workflow versus agentic patterns; deterministic orchestration; batch processing; structured outputs; predictable cost; error handling.
NEW QUESTION # 84
You are a solution architect evaluating candidate use cases for a Claude-based program.
For each scenario, select Yes if Claude is appropriate as the primary solution at the architectural level.
Otherwise, select No.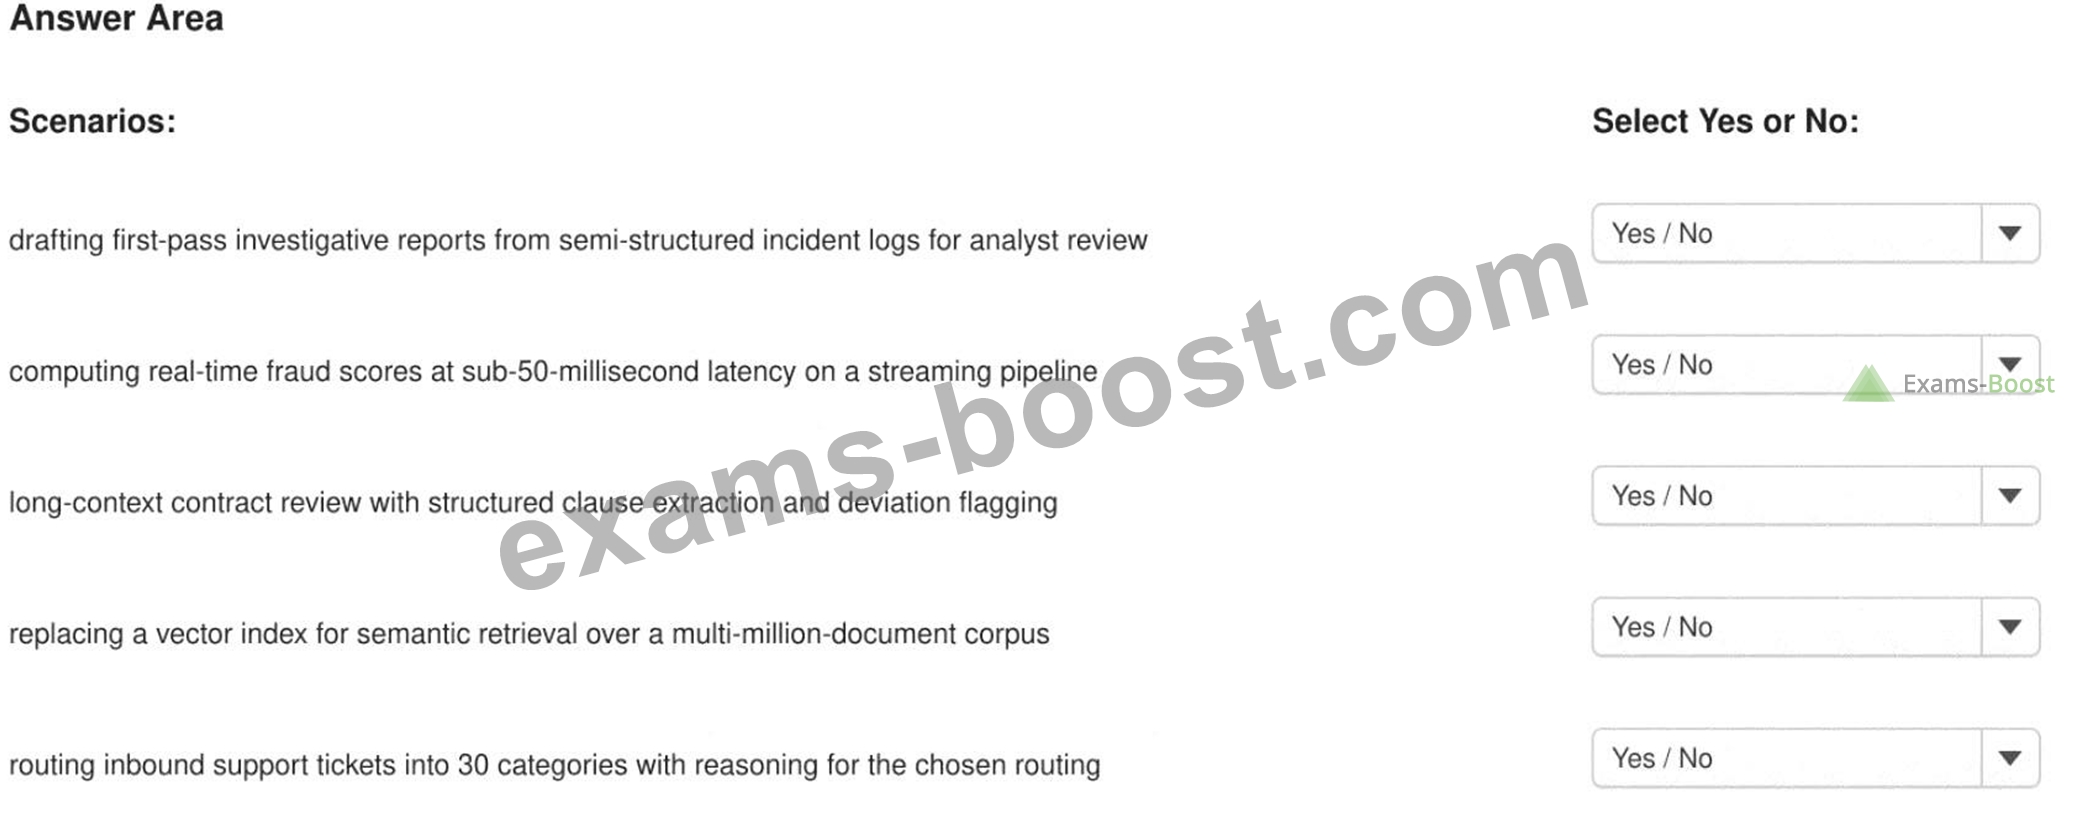
Answer:
Explanation: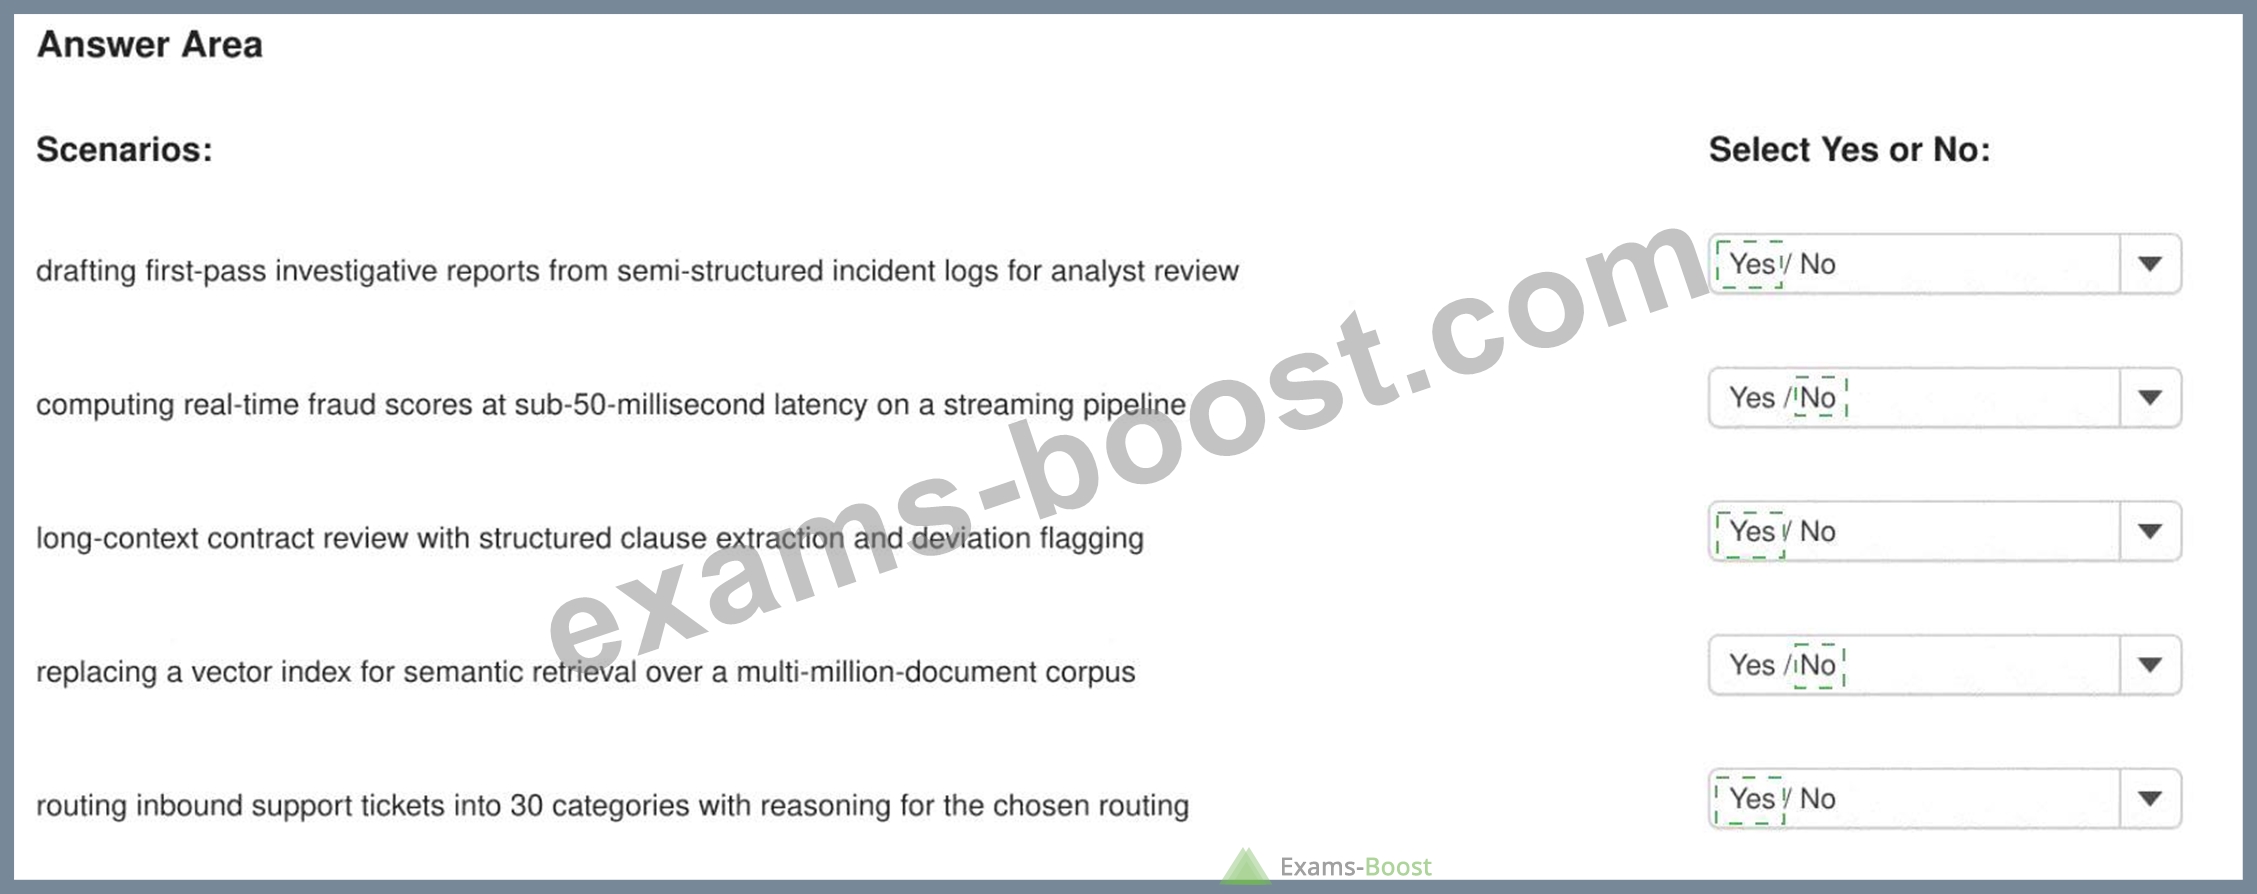
Explanation:
* Drafting first-pass investigative reports from semi-structured incident logs for analyst review - Yes
* Computing real-time fraud scores at sub-50-millisecond latency on a streaming pipeline - No
* Long-context contract review with structured clause extraction and deviation flagging - Yes
* Replacing a vector index for semantic retrieval over a multi-million-document corpus - No
* Routing inbound support tickets into 30 categories with reasoning for the selected route - Yes Claude is well suited to language-intensive analysis, summarization, extraction, classification, and drafting.
Investigative-report drafting, contract analysis, and support-ticket routing all require interpretation of unstructured or semi-structured language and can incorporate human review. A sub-50-millisecond fraud- scoring path requires deterministic, specialized real-time processing and should not place LLM inference on the critical path. Claude also does not replace the retrieval index used to search millions of documents; it consumes the results produced by that infrastructure. The correct architectural decision separates tasks requiring semantic language reasoning from deterministic computation and information-retrieval infrastructure. Model selection and evaluation must then confirm that the chosen Claude model satisfies quality, latency, and cost requirements.
NEW QUESTION # 85
You are building an evaluation pipeline for a Claude-based deployment and must complete the specification steps before running the deployment against the dataset.
Which two steps must be completed BEFORE running the deployment against the evaluation dataset? (Select two.) Each correct answer presents part of the solution.
Answer: B,E
Explanation:
The evaluation specification must exist before inference begins. Option D defines what the evaluation will measure and how results will be segmented. Representative cases measure normal workload performance, edge cases test boundary behavior, and adversarial cases examine safety, security, or robustness under hostile inputs.
Option B then supplies the correctly curated and labeled dataset corresponding to those slices. Labels, expected outcomes, grading rubrics, provenance, and dataset versions must be established before the deployment generates outputs. Otherwise, evaluators risk modifying criteria after seeing results and introducing confirmation bias.
Anthropic defines an evaluation as an input combined with grading logic used to measure success. Its evaluation guidance distinguishes tasks, trials, graders, traces, outcomes, and the harness that runs and aggregates them. Demystifying Evals for AI Agents Option E occurs after model execution because outputs must exist before they can be scored. Option A follows scoring and aggregation. Option C is an iterative improvement step performed after failure cases become available, although rubric calibration may also be conducted on separate development data.
Study Guide references/topics: Evaluation specification; metrics and slices; representative and adversarial datasets; labeling; scoring; aggregation; release gates.
NEW QUESTION # 86
......
If you are still a student, you must have learned from the schoolmaster how difficult it is to go out to work now. If you have already taken part in the work, you must have felt deeply the pressure of competition in society. CCAR-P exam materials can help you stand out in the fierce competition. After using our CCAR-P Study Materials, you have a greater chance of passing the CCAR-Pcertification, which will greatly increase your soft power and better show your strength.
CCAR-P Testing Center: https://www.exams-boost.com/CCAR-P-valid-materials.html