What's more, part of that PDFDumps MLA-C01 dumps now are free: https://drive.google.com/open?id=1hqn2xW-gdRcwr1PtuYjlPtViyLeMdeOk
We provide the best resources for the preparation of all the MLA-C01 exams. We have curated guides for MLA-C01 certifications. MLA-C01 practice exam questions can be challenging and technical for sure. However, we have MLA-C01 certified experts who curated the best study and practice materials for passing the MLA-C01 exams with higher success rate. Our MLA-C01 answers are verified and up to date products will help you prepare for the MLA-C01 exams. All those professional who looking to find the best practice material for passing the MLA-C01 exams should consider checking out our test products for better understanding.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Relevant MLA-C01 Answers <<
A whole new scope opens up to you and you are immediately hired by reputed firms. Even though the Amazon MLA-C01 certification boosts your career options, you have to pass the MLA-C01 Exam. This Amazon MLA-C01 exam serves to filter out the capable from incapable candidates.
NEW QUESTION # 69
A company wants to host an ML model on Amazon SageMaker. An ML engineer is configuring a continuous integration and continuous delivery (Cl/CD) pipeline in AWS CodePipeline to deploy the model. The pipeline must run automatically when new training data for the model is uploaded to an Amazon S3 bucket.
Select and order the pipeline ' s correct steps from the following list. Each step should be selected one time or not at all. (Select and order three.)
* An S3 event notification invokes the pipeline when new data is uploaded.
* S3 Lifecycle rule invokes the pipeline when new data is uploaded.
* SageMaker retrains the model by using the data in the S3 bucket.
* The pipeline deploys the model to a SageMaker endpoint.
* The pipeline deploys the model to SageMaker Model Registry.
Answer:
Explanation: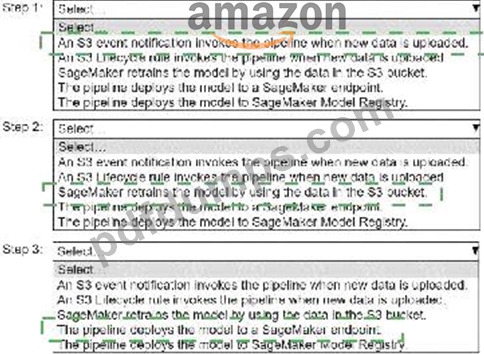
Explanation:
Step 1: An S3 event notification invokes the pipeline when new data is uploaded.
Step 2: SageMaker retrains the model by using the data in the S3 bucket.
Step 3: The pipeline deploys the model to a SageMaker endpoint.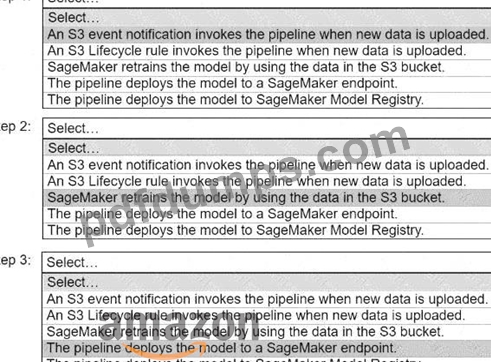
Step 1: An S3 Event Notification Invokes the Pipeline When New Data is Uploaded Why? The CI/CD pipeline should be triggered automatically whenever new training data is uploaded to Amazon S3. S3 event notifications can be configured to send events to AWS services like Lambda, which can then invoke AWS CodePipeline.
How? Configure the S3 bucket to send event notifications (e.g., s3:ObjectCreated:*) to AWS Lambda, which in turn triggers the CodePipeline.
Step 2: SageMaker Retrains the Model by Using the Data in the S3 Bucket Why? The uploaded data is used to retrain the ML model to incorporate new information and maintain performance. This step is critical to updating the model with fresh data.
How? Define a SageMaker training step in the CI/CD pipeline, which reads the training data from the S3 bucket and retrains the model.
Step 3: The Pipeline Deploys the Model to a SageMaker Endpoint
Why? Once retrained, the updated model must be deployed to a SageMaker endpoint to make it available for real-time inference.
How? Add a deployment step in the CI/CD pipeline, which automates the creation or update of the SageMaker endpoint with the retrained model.
Order Summary:
An S3 event notification invokes the pipeline when new data is uploaded.
SageMaker retrains the model by using the data in the S3 bucket.
The pipeline deploys the model to a SageMaker endpoint.
This configuration ensures an automated, efficient, and scalable CI/CD pipeline for continuous retraining and deployment of the ML model in Amazon SageMaker.
NEW QUESTION # 70
A company is using an Amazon S3 bucket to collect data that will be used for ML workflows. The company needs to use AWS Glue DataBrew to clean and normalize the data.
Which solution will meet these requirements?
Answer: C
Explanation:
AWS Glue DataBrew supports datasets sourced directly from Amazon S3 paths. To clean and normalize data, AWS documentation specifies using DataBrew recipes, which define transformation steps such as standardization, deduplication, and formatting.
A profile job is used only for data analysis and statistics generation, not for transformation. A recipe job applies actual transformations to the data and writes the output to Amazon S3.
JDBC connections are used for relational databases, not S3 buckets. Therefore, options C and D are invalid.
AWS clearly documents that the correct workflow is:
* Create a DataBrew dataset from an S3 path
* Define transformations using a recipe
* Run a recipe job to produce cleaned data
Thus, Option B is the correct and AWS-aligned answer.
NEW QUESTION # 71
A company has built more than 50 models and deployed the models on Amazon SageMaker Al as real-time inference endpoints. The company needs to reduce the costs of the SageMaker Al inference endpoints. The company used the same ML framework to build the models. The company ' s customers require low-latency access to the models.
Select and order the correct steps from the following list to reduce the cost of inference and keep latency low.
Select each
step one time or not at all. (Select and order FIVE.)
Create an endpoint configuration that references a multi-model container.
. Create a SageMaker Al model with multi-model endpoints enabled.
. Deploy a real-time inference endpoint by using the endpoint configuration.
. Deploy a serverless inference endpoint configuration by using the endpoint configuration.
Spread the existing models to multiple different Amazon S3 bucket paths.
. Upload the existing models to the same Amazon S3 bucket path.
. Update the models to use the new endpoint ID. Pass the model IDs to the new endpoint.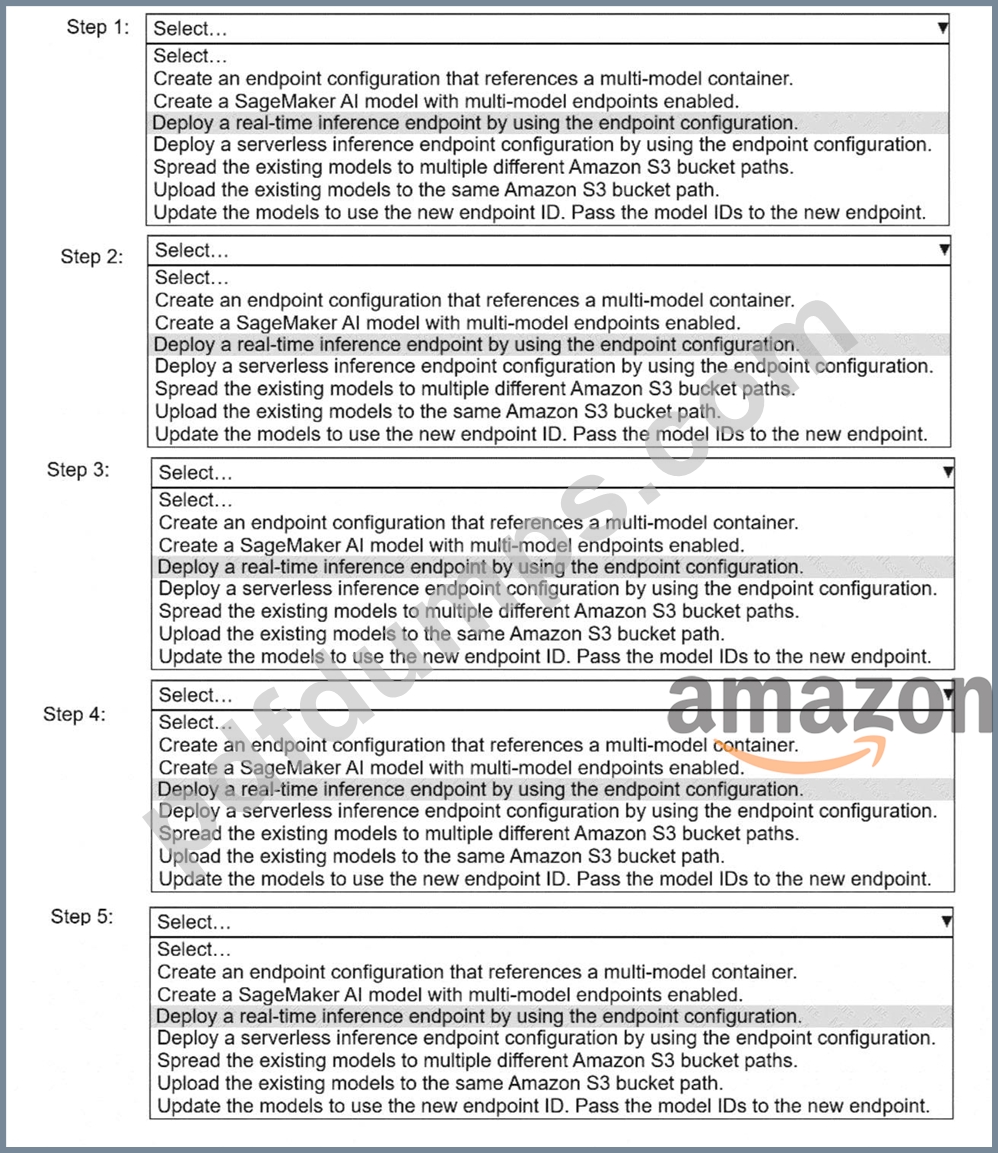
Answer:
Explanation: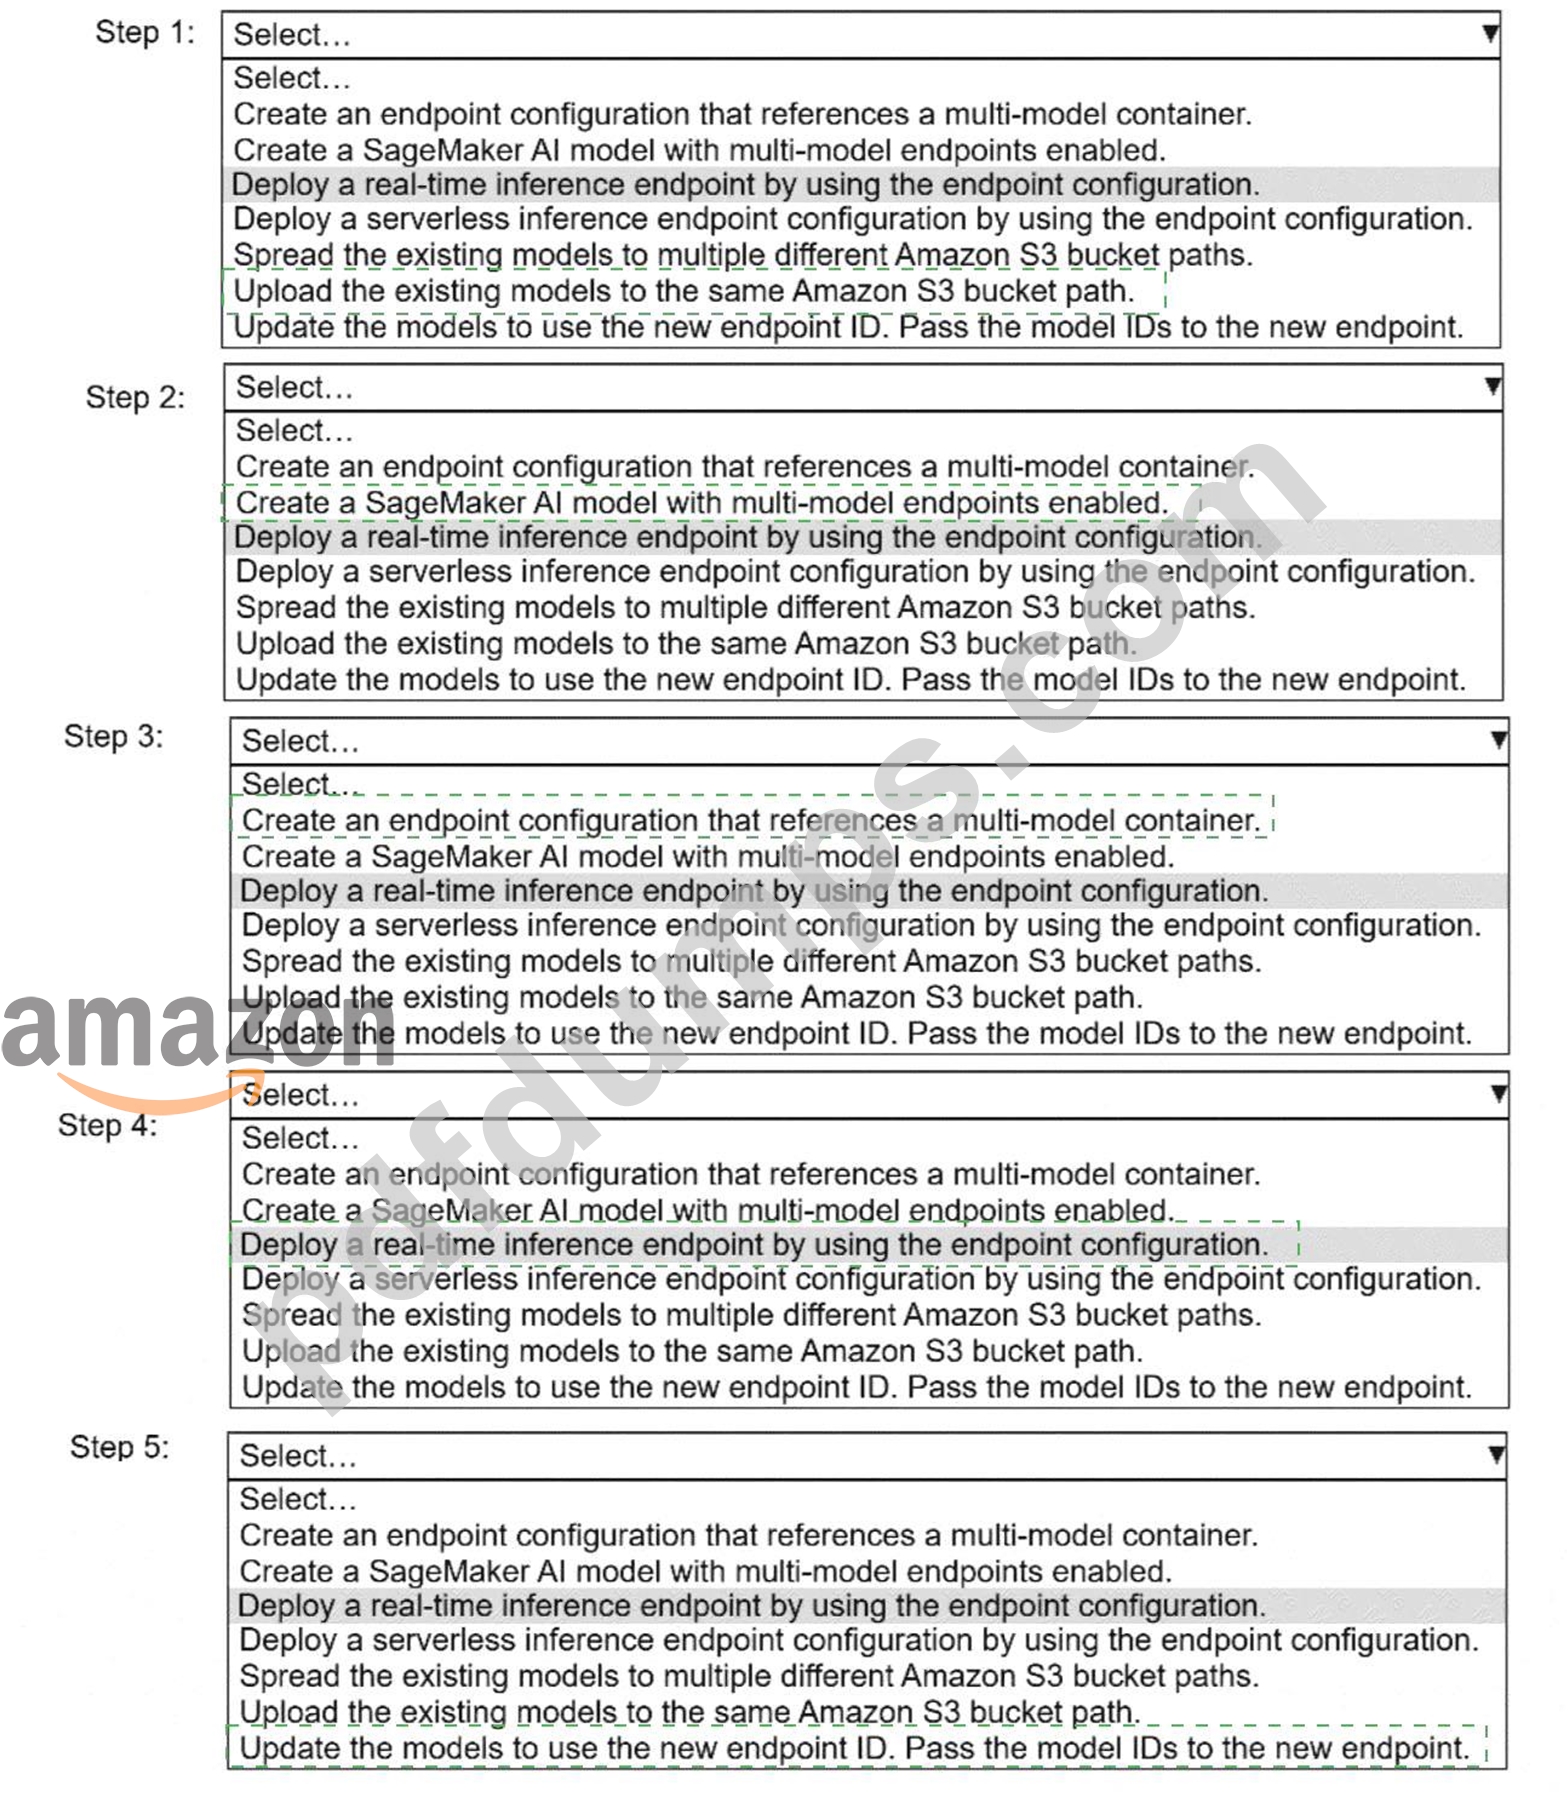
Explanation:
Step 1
Upload the existing models to the same Amazon S3 bucket path.
Multi-model endpoints require all models to be stored under a single S3 prefix so SageMaker can dynamically load them on demand.
Step 2
Create a SageMaker AI model with multi-model endpoints enabled.
This creates a SageMaker model resource that uses a multi-model-capable container (for example, XGBoost, PyTorch, or TensorFlow MME-compatible containers).
Step 3
Create an endpoint configuration that references a multi-model container.
The endpoint configuration defines:
Instance type
Initial instance count
The multi-model container reference
Step 4
Deploy a real-time inference endpoint by using the endpoint configuration.
Real-time endpoints ensure low-latency inference, which is a strict customer requirement.
Step 5
Update the models to use the new endpoint ID. Pass the model IDs to the new endpoint.
Each inference request specifies a model ID so SageMaker knows which model to load from S3.
NEW QUESTION # 72
An ML engineer normalized training data by using min-max normalization in AWS Glue DataBrew. The ML engineer must normalize production inference data in the same way before passing the data to the model.
Which solution will meet this requirement?
Answer: B
Explanation:
AWS ML best practices state that data preprocessing applied during training must be applied identically during inference. For min-max normalization, this requires reusing the minimum and maximum values calculated from the training dataset.
If production data is normalized using different statistics, the feature distributions will differ from what the model learned, leading to degraded prediction accuracy. AWS documentation explicitly warns against recomputing normalization parameters on inference data.
Options A, C, and D introduce data leakage or inconsistent feature scaling. Option B ensures consistency between training and inference pipelines and preserves model integrity.
Therefore, Option B is the correct and AWS-aligned solution.
NEW QUESTION # 73
An ML engineer needs to run intensive model training jobs each month that can take 48-72 hours. The jobs can be interrupted and resumed. The engineer has a fixed budget and needs the most cost-effective compute option.
Which solution will meet these requirements?
Answer: A
Explanation:
Amazon EC2 Spot Instances provide unused compute capacity at discounts of up to 90%. AWS documentation strongly recommends Spot Instances for interruptible workloads such as long-running ML training jobs that can resume from checkpoints.
By enabling automatic checkpointing, SageMaker saves model state periodically to Amazon S3. If the Spot Instance is interrupted, training can resume with minimal loss of progress.
Reserved Instances and Savings Plans require long-term commitment and are not as cost-effective for sporadic workloads. On-Demand Instances are the most expensive option.
Therefore, Option D is the most cost-effective solution.
NEW QUESTION # 74
......
The PDFDumps recognizes that Amazon MLA-C01 aspirants are constantly juggling multiple responsibilities, so questions are ideal for quick preparation. Applicants can access these questions anywhere and at any time, using any smart device, which allows them to learn at their own pace. The AWS Certified Machine Learning Engineer - Associate (MLA-C01) Questions are portable and you can also print them.
Exam MLA-C01 Answers: https://www.pdfdumps.com/MLA-C01-valid-exam.html
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by PDFDumps: https://drive.google.com/open?id=1hqn2xW-gdRcwr1PtuYjlPtViyLeMdeOk