当社Fast2testは常に業界標準を順守しています。最新のCCAR-P実際のダンプの定期的な試験問題に精通している専門家の助けを借りて。彼らはあなたの知識に飢えた心を満たすことができます。また、CCAR-P試験クイズは品質保証されています。ここ数年、お客様に高品質のCCAR-P実践教材を提供することに専念することで、すべてのコンテンツが実践と記憶に不可欠な部分であることを保証できます。
| Section | Weight | Objectives |
|---|---|---|
| Governance, Safety & Risk Management | 14% | - Address ethical AI considerations and bias mitigation - Manage data privacy and security compliance - Implement guardrails and safety controls - Ensure regulatory compliance (GDPR, HIPAA, etc.) |
| Developer Productivity & Operational Enablement | 7% | - Support debugging, monitoring, and operational resolution - Configure Claude tools and environments for teams - Improve developer workflows with AI-assisted tooling |
| Stakeholder Communication & Lifecycle Management | 14% | - Communicate architectural decisions and trade-offs - Manage stakeholder feedback and expectation alignment - Conduct structured discovery and requirement gathering - Document architectures and support full lifecycle phases |
| Evaluation, Testing & Optimization | 16% | - Optimize performance, prompting, and model selection - Test accuracy, reliability, latency, and cost - Implement iterative improvement pipelines - Define evaluation metrics and success criteria |
| Claude Models, Prompting & Context Engineering | 13% | - Apply context engineering and context management techniques - Mitigate prompt injection, leaks, and jailbreak risks - Design system prompts, templates, and guardrails - Select appropriate Claude models based on trade-offs |
| Solution Design & Architecture | 17% | - Design multi-agent systems and orchestration strategies - Align solutions to business value pillars - Select architectural patterns: workflow, agentic, augmented LLM - Translate business problems into Claude-based AI solutions - Design end-to-end architectures and feedback loops |
| Integration | 19% | - Integrate Claude with enterprise systems, APIs, and tools - Design authentication, authorization, and observability - Integrate with data pipelines and RAG systems - Implement Model Context Protocol (MCP) integrations |
CCAR-P試験資料の更新は1年以内に無料で提供され、1年後にクライアントは50%の割引を受けることができます。古いクライアントは、CCAR-PのAnthropic試験トレントを購入すると、特定の割引を利用できます。当社の専門家は、テストバンクの更新が毎日あるかどうかを確認し、CCAR-P学習ガイドの更新版がある場合、システムはそれを自動的にクライアントに送信します。それが、CCAR-P学習教材が非常に人気がある理由の1つであり、お客様により有利な価格とより多くのサービスを提供しています。
質問 # 37
You are diagnosing a Claude Code session whose subagent uses 50,000 tokens of context before the engineer types a single message.
Which root cause is most likely?
正解:D
解説:
Claude Code constructs the model context before the first user message. That initial context can include the system prompt, project instructions, subagent configuration, MCP server instructions, and tool definitions expressed as JSON schemas. When numerous MCP servers expose many tools and Tool Search is disabled, those schemas must be loaded upfront. A large collection of verbose tool descriptions and parameter schemas can therefore consume tens of thousands of tokens before the engineer enters any text.
Tool Search is specifically designed to prevent this form of context inflation. With Tool Search enabled, Claude initially receives only server instructions and compact tool-identification information; full tool schemas are deferred until a relevant tool is discovered and required. Anthropic consequently describes Tool Search as the mechanism for keeping MCP context consumption low as integrations scale.
Keyboard layouts, font rendering, and display scaling operate outside the language-model context and cannot generate API input tokens. Likewise, model behavior does not silently reserve 50,000 tokens for personal preferences. The diagnostic action is to inspect configured MCP servers and tool counts, determine whether Tool Search has been disabled, and remove or defer unnecessary definitions.
Study Guide references/topics: [MCP Tool Search and context scaling](https://docs.anthropic.com/en/docs
/claude-code/mcp); MCP server configuration; subagent context budgeting; tool-schema optimization.
質問 # 38
You are configuring tool permissions for a Claude-based assistant. The assistant's defined responsibilities require read access to a knowledge base and write access to a draft queue, and nothing else.
Which scoping design best applies least privilege?
正解:C
解説:
Least privilege means granting the exact capabilities required for the defined responsibility-no more and no less. Option B permits the assistant to read the approved knowledge base and write only to the draft queue.
Enforcing the allow-list at the orchestration layer creates a deterministic authorization boundary outside the model's prompt and reasoning.
The rule should also be role-specific so different users or operational roles receive only the tools and data scopes they require. The knowledge-base tool should remain read-only, while the draft-queue tool should be restricted to draft creation rather than external sending, approval, or production publication.
Option A exposes every globally readable tool, creating unnecessary access to unrelated information. Option C relies on voluntary model behavior instead of enforceable authorization. A mistaken tool selection or successful prompt injection could therefore invoke an inappropriate capability. Option D minimizes permissions by eliminating the assistant's required functionality and is not a viable least-privilege implementation.
Anthropic's permission guidance distinguishes allow, ask, and deny rules and confirms that these controls are enforced by Claude Code rather than by model instructions. Configure Permissions Study Guide references/topics: Least privilege; per-role authorization; orchestration-layer enforcement; capability scoping; read/write separation; tool allow-lists.
質問 # 39
An architect is reviewing a set of architecture documentation packages before handing off a Claude-based pipeline to an implementation team.
Which two characteristics indicate that a documentation package is sufficient to support implementation without ongoing architect involvement? (Select two.)
正解:A、D
解説:
Implementation-ready documentation must provide both executable specifications and preserved architectural reasoning. Option A supplies the contracts an implementation team needs to build components independently:
configuration schemas, accepted inputs, produced outputs, validation requirements, and integration boundaries. These details prevent teams from inventing incompatible assumptions about data structures, tool behavior, error handling, or component ownership.
Option B complements the technical contracts with a decision log. Recording the selected design, underlying constraints, alternatives considered, and reasons for rejection enables implementers to distinguish deliberate architectural decisions from accidental omissions. It also prevents previously rejected approaches from being reintroduced without new evidence.
A high-level business narrative in Option C may explain purpose but cannot direct component-level implementation. Contact information in Option D provides an escalation route, but documentation is not sufficient if routine progress still depends on the architect's availability. Option E records activity rather than a decision; a model list without the selected model and selection rationale leaves critical cost, latency, capability, and evaluation assumptions unresolved.
A strong handoff package should permit implementation, testing, and support teams to proceed while escalating only genuinely new architectural questions.
Study Guide references/topics: Architecture documentation; interface contracts; configuration schemas; Architecture Decision Records; implementation handoff; decision traceability.
質問 # 40
You are classifying token-management tactics by where each tactic applies in the request lifecycle: "Input Preparation," "Prompt Construction," or "Output Handling."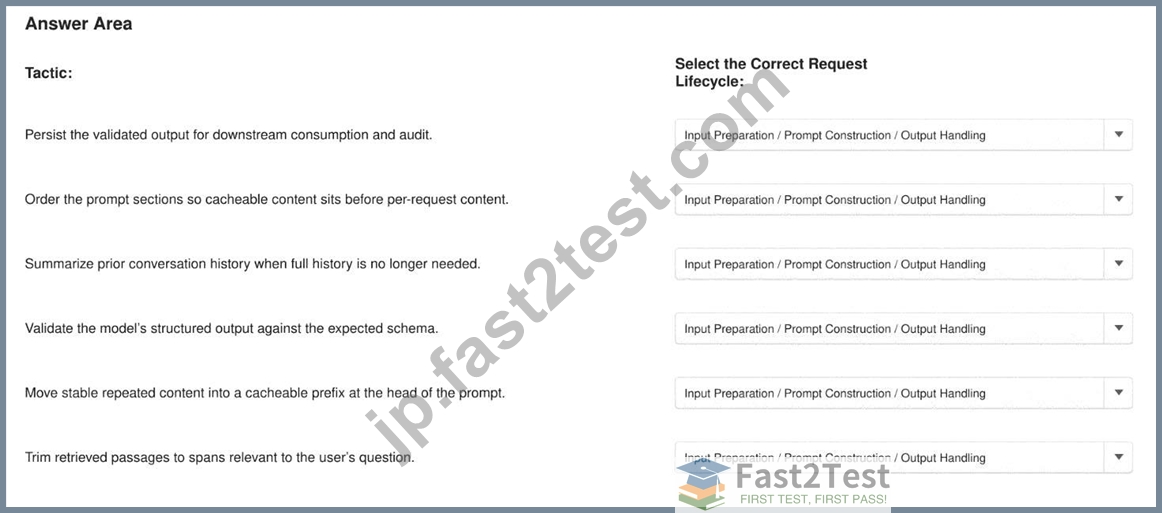
正解:
解説:
Explanation:
* Persist the validated output for downstream consumption and audit - Output Handling
* Order prompt sections so cacheable content appears before per-request content - Prompt Construction
* Summarize prior conversation history when full history is no longer needed - Input Preparation
* Validate the model's structured output against the expected schema - Output Handling
* Move stable repeated content into a cacheable prefix at the beginning of the prompt - Prompt Construction
* Trim retrieved passages to spans relevant to the user's question - Input Preparation Input preparation determines what evidence and history should enter the request, so summarization and retrieval trimming belong there. Prompt construction determines ordering and cache boundaries; stable repeated instructions must precede dynamic per-request content to maximize cache reuse. Output handling begins after generation and includes schema validation, persistence, auditing, and downstream delivery.
Mixing these responsibilities creates inefficient prompts and weak validation boundaries. Anthropic's context guidance emphasizes curating the smallest useful context because unnecessary tokens can reduce recall and accuracy. Prompt caching similarly depends on a stable reusable prefix, while structured outputs or schema validation protect downstream systems from malformed responses. Context windows; prompt caching
質問 # 41
You are an architect supporting the iteration phase of a deployed Claude-based system.
Which activity most directly fits this phase?
正解:B
解説:
Iteration is an evidence-driven lifecycle phase. Option D combines three essential inputs: production telemetry, sampled output evaluation, and stakeholder feedback. Telemetry exposes latency, cost, errors, tool failures, retrieval behavior, and operational anomalies. Output sampling identifies quality, safety, grounding, or consistency failures that infrastructure metrics may not reveal. Stakeholder feedback establishes whether the system continues to satisfy real business and user needs.
The architect should prioritize the highest-impact validated problem, define the intended improvement, and test the proposed change against the existing evaluation framework and reference set. Anthropic emphasizes that evaluations make behavioral changes visible before they affect users and that their value compounds throughout an agent's lifecycle. Demystifying Evals for AI Agents Option A replaces targeted iteration with unnecessary redesign. Option B incorrectly treats deployment as the end of measurement. Option C removes the baseline needed to distinguish genuine improvement from regression or noise.
A mature iteration cycle preserves evaluation continuity, adds production failures as new test cases, validates changes offline, conducts controlled rollout, monitors results, and updates documentation and known limitations.
Study Guide references/topics: Production iteration; telemetry; sampled evaluation; stakeholder feedback; regression testing; evaluation continuity; change prioritization.
質問 # 42
......
急速に発展している世界で、CCAR-P認定試験資格証明書はあなたの仕事の不可欠なものです。CCAR-P復習資料を勉強したら、CCAR-P認定試験資格証明書を取得するだけでなく、自分の能力を向上できます。それは一挙両得です。そうすれば、早くCCAR-P復習資料を入手しましょう!
CCAR-P試験攻略: https://jp.fast2test.com/CCAR-P-premium-file.html