With the popularization of wireless network, those who are about to take part in the Databricks-Certified-Professional-Data-Engineer exam guide to use APP on the mobile devices as their learning tool, because as long as entering into an online environment, they can instantly open the learning material from their appliances. Our Databricks-Certified-Professional-Data-Engineer study materials provide such version for you. The online test engine is a kind of online learning, you can enjoy the advantages of APP version of our Databricks-Certified-Professional-Data-Engineer Exam Guide freely. And you can have free access to our Databricks-Certified-Professional-Data-Engineer exam questions in the offline condition if you don’t clear cache.
Databricks is a leading company in the field of data engineering and machine learning. The company offers a wide range of services and tools to help organizations manage and analyze their data more effectively. One of the key offerings from Databricks is the Databricks Certified Professional Data Engineer (Databricks-Certified-Professional-Data-Engineer) certification exam. Databricks-Certified-Professional-Data-Engineer exam is designed to test the skills and knowledge of data engineers who work with Databricks.
Databricks Certified Professional Data Engineer certification exam is a rigorous and challenging exam that requires a deep understanding of data engineering concepts and the Databricks platform. Candidates must have a strong foundation in computer science and data engineering, as well as practical experience using the Databricks platform. Databricks-Certified-Professional-Data-Engineer Exam consists of multiple-choice questions and hands-on exercises that test a candidate's ability to design, build, and maintain data pipelines using the Databricks platform.
>> VCE Databricks-Certified-Professional-Data-Engineer Exam Simulator <<
Our Databricks-Certified-Professional-Data-Engineer guide torrent is compiled by experts and approved by the experienced professionals. The language is easy to be understood to make any learners have no learning obstacles and our Databricks-Certified-Professional-Data-Engineer study questions are suitable for any learners. The software boosts varied self-learning and self-assessment functions to check the results of the learning. The software can help the learners find the weak links and deal with them. Our Databricks-Certified-Professional-Data-Engineer Exam Torrent boosts timing function and the function to stimulate the exam. It is very easy to pass the Databricks-Certified-Professional-Data-Engineer exam with our Databricks-Certified-Professional-Data-Engineer learning guide.
Passing the Databricks Certified Professional Data Engineer exam is a valuable achievement for data professionals who work with the Databricks platform. Databricks Certified Professional Data Engineer Exam certification demonstrates that candidates have the skills and knowledge needed to perform data engineering tasks effectively using Databricks. It also provides a competitive advantage in the job market, as employers are increasingly looking for candidates with data engineering certifications.
NEW QUESTION # 178
A data team is implementing an append-only Delta Lake pipeline that processes both batch and streaming data . They want to ensure that schema changes in the source data are automatically incorporated without breaking the pipeline.
Which configuration should the team use when writing data to the Delta table?
Answer: D
NEW QUESTION # 179
A platform team is creating a standardized template for Databricks Asset Bundles to support CI/CD. The template must specify defaults for artifacts, workspace root paths, and a run identity, while allowing a "dev" target to be the default and override specific paths.
How should the team use databricks.yml to satisfy these requirements?
Answer: D
Explanation:
In Databricks Asset Bundles, the databricks.yml file defines all top-level configuration keys, including bundle, artifacts, workspace, run_as, and targets. The targets section defines specific deployment contexts (for example, dev, test, prod). Setting default: true for a target marks it as the default environment. Overrides for workspace paths and artifact configurations can be defined inside each target while keeping defaults at the top level.
Reference Source: Databricks Asset Bundle Configuration Guide - "Structure of databricks.yml and target overrides."
NEW QUESTION # 180
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.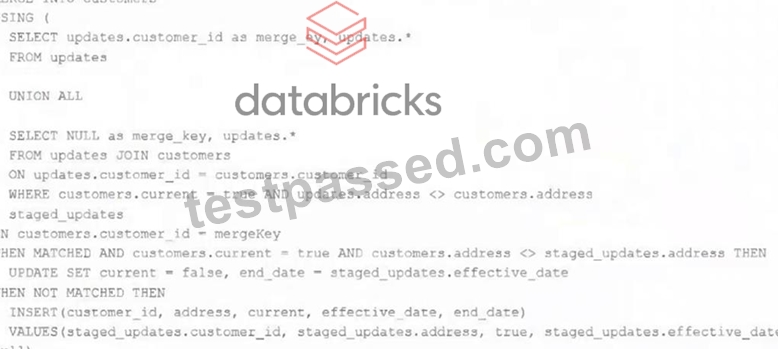
Which statement describes this implementation?
Answer: E
Explanation:
The logic uses the MERGE INTO command to merge new records from the view updates into the table customers. The MERGE INTO command takes two arguments: a target table and a source table or view. The command also specifies a condition to match records between the target and the source, and a set of actions to perform when there is a match or not. In this case, the condition is to match records by customer_id, which is the primary key of the customers table. The actions are to update the existing record in the target with the new values from the source, and set the current_flag to false to indicate that the record is no longer current; and to insert a new record in the target with the new values from the source, and set the current_flag to true to indicate that the record is current. This means that old values are maintained but marked as no longer current and new values are inserted, which is the definition of a Type 2 table. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Merge Into (Delta Lake on Databricks)" section.
NEW QUESTION # 181
A security analytics pipeline must enrich billions of raw connection logs with geolocation data. The join hinges on finding which IPv4 range each event's address falls into.
Table 1: network_events (# 5 billion rows)
event_id ip_int
42 3232235777
Table 2: ip_ranges (# 2 million rows)
start_ip_int end_ip_int country
3232235520 3232236031 US
The query is currently very slow:
SELECT n.event_id, n.ip_int, r.country
FROM network_events n
JOIN ip_ranges r
ON n.ip_int BETWEEN r.start_ip_int AND r.end_ip_int;
Question:
Which change will most dramatically accelerate the query while preserving its logic?
Answer: A
Explanation:
The query joins billions of rows (network_events) with millions of rows (ip_ranges) using a range predicate (BETWEEN). Unlike equality joins (=), range joins are not efficiently handled by broadcast or sort- merge joins because:
* Broadcast Join (D): Effective for small tables but only for equality joins. Since this query uses a range condition , broadcast will not reduce the complexity of scanning billions of records across non-equality conditions.
* Sort-Merge Join (C): Works for ordered joins but is inefficient on range conditions. Sorting billions of records adds excessive overhead and will not resolve the bottleneck.
* Increasing Shuffle Partitions (A): Only spreads out shuffle work but does not address the fundamental inefficiency of range-based lookups at scale.
Range Joins in Spark (RANGE_JOIN hint):
Databricks provides range join optimizations specifically for conditions such as BETWEEN. By applying a RANGE_JOIN hint , Spark can build optimized data structures (such as interval indexes or partition pruning strategies) that map billions of input rows to ranges much faster. This avoids brute-force scans and unnecessary shuffle costs.
Thus, Option B is the correct solution because:
* It leverages range-join optimization , which is purpose-built for queries joining massive event logs to smaller lookup tables with IP ranges.
* This ensures Spark can evaluate billions of rows against millions of ranges with optimized matching logic, drastically improving query performance while preserving correctness.
Reference: Databricks SQL Performance Tuning Guide - Range Joins and Join Hints (RANGE_JOIN, BROADCAST, MERGE).
NEW QUESTION # 182
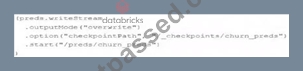
The data science team has created and logged a production model using MLflow. The following code correctly imports and applies the production model to output the predictions as a new DataFrame named preds with the schema "customer_id LONG, predictions DOUBLE, date DATE".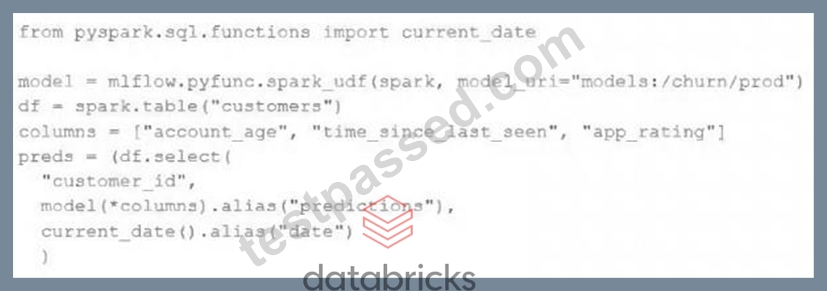
The data science team would like predictions saved to a Delta Lake table with the ability to compare all predictions across time. Churn predictions will be made at most once per day.
Which code block accomplishes this task while minimizing potential compute costs?
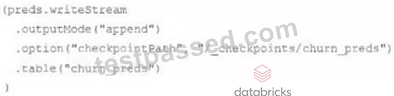
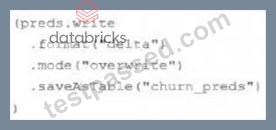
Answer: D
NEW QUESTION # 183
......
Databricks-Certified-Professional-Data-Engineer Practice Tests: https://www.testpassed.com/Databricks-Certified-Professional-Data-Engineer-still-valid-exam.html