Free PDF Quiz 2026 Databricks-Certified-Professional-Data-Engineer: High Pass-Rate Exam Dumps Databricks Certified Professional Data Engineer Exam Demo

DOWNLOAD the newest DumpsMaterials Databricks-Certified-Professional-Data-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1rsgGu1bwRfMHJIB_FYFwleZVjDlGHvFY
New Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer study guide and latest learning materials and practice materials have been provide for customers. DumpsMaterials is a good platform that has been providing reliable, true, updated, and free Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer Exam Questions. The Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer exam fee is affordable, in order to success in your career, you need to pass Databricks Certified Professional Data Engineer Exam exam.
Databricks Certified Professional Data Engineer certification is a valuable credential for data engineers who want to validate their skills and expertise in using Databricks. Databricks Certified Professional Data Engineer Exam certification demonstrates to employers and clients that the candidate has the knowledge and skills required to design and implement data solutions using Databricks. It also helps data engineers differentiate themselves in a competitive job market and provides opportunities for career advancement.
Databricks Certified Professional Data Engineer certification is recognized by leading companies in the tech industry as a benchmark of excellence in the field of data engineering. It is a valuable credential for individuals who are looking to advance their careers in this field and are seeking to demonstrate their expertise in Databricks technologies. Additionally, companies that employ Databricks Certified Professional Data Engineers can be assured that they have the necessary skills to build and maintain complex data pipelines and analytics systems.
>> Exam Dumps Databricks-Certified-Professional-Data-Engineer Demo <<
Databricks Databricks-Certified-Professional-Data-Engineer Valid Exam Experience & Databricks-Certified-Professional-Data-Engineer Latest Test Pdf
DumpsMaterials is obliged to give you 1 year of free update checks to ensure the validity and accuracy of the Databricks Databricks-Certified-Professional-Data-Engineer exam dumps. We also offer you a 100% money-back guarantee, in the very rare case of failure or unsatisfactory results. This puts your mind at ease when you are Databricks Databricks-Certified-Professional-Data-Engineer Exam preparing with us.
| Topic | Details |
|---|
| Topic 1 | - Monitoring & Logging: This topic includes understanding the Spark UI, inspecting event timelines and metrics, drawing conclusions from various UIs, designing systems to control cost and latency SLAs for production streaming jobs, and deploying and monitoring both streaming and batch jobs.
|
| Topic 2 | - Data Processing: The topic covers understanding partition hints, partitioning data effectively, controlling part-file sizes, updating records, leveraging Structured Streaming and Delta Lake, implementing stream-static joins and deduplication. Additionally, it delves into utilizing Change Data Capture and addressing performance issues related to small files.
|
| Topic 3 | - Security & Governance: It discusses creating Dynamic views to accomplishing data masking and using dynamic views to control access to rows and columns.
|
Databricks Certified Professional Data Engineer Exam Sample Questions (Q57-Q62):
NEW QUESTION # 57
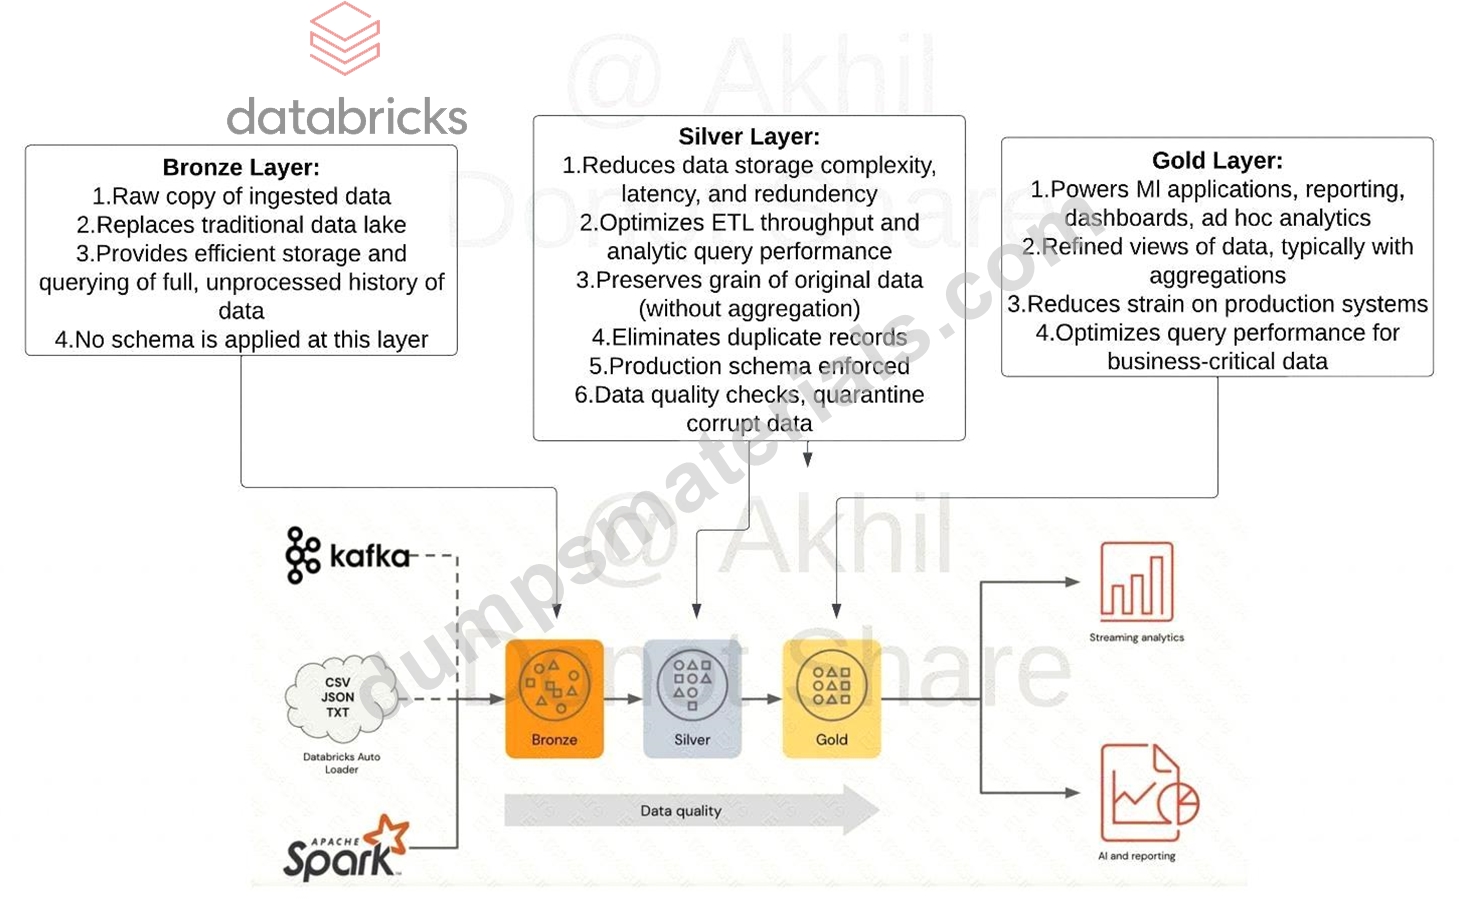
What is the main difference between the bronze layer and silver layer in a medallion architecture?
- A. Duplicates are removed in bronze, schema is applied in silver
- B. Bad data is filtered in Bronze, silver is a copy of bronze data
- C. Silver may contain aggregated data
- D. Bronze is raw copy of ingested data, silver contains data with production schema and optimized for ELT/ETL throughput
Answer: D
Explanation:
Explanation
Medallion Architecture - Databricks
Exam focus: Please review the below image and understand the role of each layer(bronze, silver, gold) in medallion architecture, you will see varying questions targeting each layer and its purpose.
Sorry I had to add the watermark some people in Udemy are copying my content.
A diagram of a house Description automatically generated with low confidence
NEW QUESTION # 58
A table in the Lakehouse namedcustomer_churn_paramsis used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours.
Which approach would simplify the identification of these changed records?
- A. Replace the current overwrite logic with a merge statement to modify only those records that have changed; write logic to make predictions on the changed records identified by the change data feed.
- B. Apply the churn model to all rows in the customer_churn_params table, but implement logic to perform an upsert into the predictions table that ignores rows where predictions have not changed.
- C. Modify the overwrite logic to include a field populated by calling
spark.sql.functions.current_timestamp() as data are being written; use this field to identify records written on a particular date. - D. Convert the batch job to a Structured Streaming job using the complete output mode; configure a Structured Streaming job to read from the customer_churn_params table and incrementally predict against the churn model.
- E. Calculate the difference between the previous model predictions and the current customer_churn_params on a key identifying unique customers before making new predictions; only make predictions on those customers not in the previous predictions.
Answer: D
Explanation:
Explanation
This is the correct answer because the JSON posted to the Databricks REST API endpoint 2.0/jobs/create defines a new job with an existing cluster id and a notebook task, but also specifies a new cluster spec with some configurations. According to the documentation, if both an existing cluster id and a new cluster spec are provided, then a new cluster will be created for each run of the job with those configurations, and then terminated after completion. Therefore, the logic defined in the referenced notebook will be executed three times on new clusters with those configurations. Verified References: [Databricks Certified Data Engineer Professional], under "Monitoring & Logging" section; Databricks Documentation, under
"JobsClusterSpecNewCluster" section.
NEW QUESTION # 59
The data science team has created and logged a production using MLFlow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, load the customer table containing the customer_id key column into a Dataframe, and defines the feature columns needed for the model.

Which code block will output DataFrame with the schema'' customer_id LONG, predictions DOUBLE''?
- A. Df.apply(model, columns). Select (''customer_id, prediction''
- B. Df. Select (''customer_id''.
Model (''columns) alias (''predictions'') - C. Model, predict (df, columns)
- D. Df, map (lambda k:midel (x [columns]) ,select (''customer_id predictions'')
Answer: C
Explanation:
Given the information that the model is registered with MLflow and assumingpredictis the method used to apply the model to a set of columns, we use themodel.predict()function to apply the model to the DataFrame dfusing the specifiedcolumns. Themodel.predict()function is designed to take in a DataFrame and a list of column names as arguments, applying the trained model to these features to produce a predictionscolumn.
When working with PySpark, this predictions column needs to be selected alongside thecustomer_idto create a new DataFrame with the schemacustomer_id LONG, predictions DOUBLE.
References:
* MLflow documentation on using Python function models: https://www.mlflow.org/docs/latest/models.
html#python-function-python
* PySpark MLlib documentation on model prediction:https://spark.apache.org/docs/latest/ml-pipeline.
html#pipeline
NEW QUESTION # 60
You are currently working on a production job failure with a job set up in job clusters due to a data issue, what cluster do you need to start to investigate and analyze the data?
- A. A Job cluster can be used to analyze the problem
- B. Existing job cluster can be used to investigate the issue
- C. Databricks SQL Endpoint can be used to investigate the issue
- D. All-purpose cluster/ interactive cluster is the recommended way to run commands and view the data.
Answer: D
Explanation:
Explanation
Answer is All-purpose cluster/ interactive cluster is the recommended way to run commands and view the data.
A job cluster can not provide a way for a user to interact with a notebook once the job is submitted, but an Interactive cluster allows to you display data, view visualizations write or edit quries, which makes it a perfect fit to investigate and analyze the data.
NEW QUESTION # 61
A data engineer created a daily batch ingestion pipeline using a cluster with the latest DBR version to store banking transaction data, and persisted it in a MANAGED DELTA table called prod.gold.
all_banking_transactions_daily. The data engineer is constantly receiving complaints from business users who query this table ad hoc through a SQL Serverless Warehouse about poor query performance. Upon analysis, the data engineer identified that these users frequently use high-cardinality columns as filters. The engineer now seeks to implement a data layout optimization technique that is incremental, easy to maintain, and can evolve over time.
Which command should the data engineer implement?
- A. Alter the table to use Hive-Style Partitions + Z-ORDER and implement a periodic OPTIMIZE command.
- B. Alter the table to use Z-ORDER and implement a periodic OPTIMIZE command.
- C. Alter the table to use Liquid Clustering and implement a periodic OPTIMIZE command.
- D. Alter the table to use Hive-Style Partitions and implement a periodic OPTIMIZE command.
Answer: C
Explanation:
Databricks recommends Liquid Clustering for optimizing data layout in large Delta tables where query filters involve high-cardinality columns. Liquid Clustering automatically manages file organization and supports incremental maintenance without the need to rewrite data when clustering keys evolve. This is a key advantage over static partitioning or Z-ordering, which require costly file rewrites whenever optimization keys change. By combining Liquid Clustering with a periodic OPTIMIZE command, Databricks automatically compacts small files and maintains efficient data skipping performance. As stated in the Delta Lake optimization guide, Liquid Clustering is designed for scalability, minimal maintenance, and adaptability for analytical workloads with evolving query patterns-making B the correct answer.
NEW QUESTION # 62
......
Databricks-Certified-Professional-Data-Engineer Valid Exam Experience: https://www.dumpsmaterials.com/Databricks-Certified-Professional-Data-Engineer-real-torrent.html
- Quiz 2026 Databricks Databricks-Certified-Professional-Data-Engineer: Updated Exam Dumps Databricks Certified Professional Data Engineer Exam Demo 🐘 Search for ➽ Databricks-Certified-Professional-Data-Engineer 🢪 on ⇛ www.practicevce.com ⇚ immediately to obtain a free download 🥵Databricks-Certified-Professional-Data-Engineer Latest Braindumps Ppt
- Free PDF Trustable Databricks-Certified-Professional-Data-Engineer - Exam Dumps Databricks Certified Professional Data Engineer Exam Demo 😝 Enter ( www.pdfvce.com ) and search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ to download for free 😬Test Databricks-Certified-Professional-Data-Engineer Assessment
- Free PDF 2026 Databricks-Certified-Professional-Data-Engineer: Marvelous Exam Dumps Databricks Certified Professional Data Engineer Exam Demo ⚜ Search for ➽ Databricks-Certified-Professional-Data-Engineer 🢪 and download it for free on ⏩ www.troytecdumps.com ⏪ website 💘Valid Databricks-Certified-Professional-Data-Engineer Exam Test
- Databricks-Certified-Professional-Data-Engineer PDF VCE ♿ New Databricks-Certified-Professional-Data-Engineer Test Voucher 😝 Databricks-Certified-Professional-Data-Engineer Latest Test Bootcamp ⚾ Download ➽ Databricks-Certified-Professional-Data-Engineer 🢪 for free by simply searching on ▷ www.pdfvce.com ◁ 🦮Databricks-Certified-Professional-Data-Engineer Authorized Test Dumps
- Quiz 2026 Databricks Databricks-Certified-Professional-Data-Engineer: Updated Exam Dumps Databricks Certified Professional Data Engineer Exam Demo 🐼 Easily obtain free download of 「 Databricks-Certified-Professional-Data-Engineer 」 by searching on ▛ www.vce4dumps.com ▟ 🧁Exam Databricks-Certified-Professional-Data-Engineer Passing Score
- New Databricks-Certified-Professional-Data-Engineer Test Voucher 🚴 Valid Databricks-Certified-Professional-Data-Engineer Exam Test 🧞 Databricks-Certified-Professional-Data-Engineer Valid Exam Vce Free 🎾 Search for ▶ Databricks-Certified-Professional-Data-Engineer ◀ and download it for free immediately on 《 www.pdfvce.com 》 ⚪Authentic Databricks-Certified-Professional-Data-Engineer Exam Questions
- New Databricks-Certified-Professional-Data-Engineer Braindumps Pdf 🚔 Authentic Databricks-Certified-Professional-Data-Engineer Exam Questions 🎫 Databricks-Certified-Professional-Data-Engineer Latest Test Bootcamp 🌰 Search for { Databricks-Certified-Professional-Data-Engineer } and download it for free on ▷ www.testkingpass.com ◁ website 👼Reliable Databricks-Certified-Professional-Data-Engineer Braindumps
- Exam Databricks-Certified-Professional-Data-Engineer Passing Score 🎇 Exam Databricks-Certified-Professional-Data-Engineer Book 🕒 Latest Databricks-Certified-Professional-Data-Engineer Exam Review 🏆 Simply search for ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ for free download on ☀ www.pdfvce.com ️☀️ 🤼Databricks-Certified-Professional-Data-Engineer Valid Exam Vce Free
- Databricks-Certified-Professional-Data-Engineer Latest Braindumps Ppt ↔ Databricks-Certified-Professional-Data-Engineer PDF VCE 🥱 Exam Databricks-Certified-Professional-Data-Engineer Book 🎍 Search for 【 Databricks-Certified-Professional-Data-Engineer 】 and download exam materials for free through ➠ www.troytecdumps.com 🠰 🎣Databricks-Certified-Professional-Data-Engineer Latest Exam
- Free PDF 2026 Databricks-Certified-Professional-Data-Engineer: Marvelous Exam Dumps Databricks Certified Professional Data Engineer Exam Demo 📋 Easily obtain free download of ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ by searching on ➡ www.pdfvce.com ️⬅️ 🔈Databricks-Certified-Professional-Data-Engineer Latest Braindumps Ppt
- New Databricks-Certified-Professional-Data-Engineer Test Voucher 🦱 Databricks-Certified-Professional-Data-Engineer PDF VCE 🦔 Reliable Databricks-Certified-Professional-Data-Engineer Braindumps 🦍 Search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ and download it for free immediately on ⏩ www.dumpsmaterials.com ⏪ 😍Databricks-Certified-Professional-Data-Engineer Reliable Dumps Book
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
What's more, part of that DumpsMaterials Databricks-Certified-Professional-Data-Engineer dumps now are free: https://drive.google.com/open?id=1rsgGu1bwRfMHJIB_FYFwleZVjDlGHvFY