2026年PassTestの最新NCM-MCI-6.10 PDFダンプおよびNCM-MCI-6.10試験エンジンの無料共有:https://drive.google.com/open?id=1pIF4-AjBufjOAJAg6udTVUfSgDRVCAdE
優れたNCM-MCI-6.10試験問題を使用すると、NCM-MCI-6.10認定資格を取得して自分自身を向上させ、より良い未来とより良い未来を実現することができます。 NCM-MCI-6.10トレーニングガイドを使用すると、職業で認められます。 NCM-MCI-6.10試験のブレーンダンプは、より大きな会社に注目させる能力を証明できます。 その後、より良い仕事を取得し、適切な職場に行くための選択肢があります。 NCM-MCI-6.10試験問題を試してみてはいかがですか。NCM-MCI-6.10試験問題が最高の準備資料であることに驚かれることでしょう。
| Section | Objectives |
|---|---|
| Deploy and Upgrade Nutanix Environments | - Foundation processes - Cluster installation and configuration - Software and firmware upgrades |
| Analyze and Remediate Performance Issues | - Troubleshooting storage performance - Troubleshooting network performance - Performance monitoring and metrics |
| Configure and Manage Nutanix Networking | - Advanced networking scenarios - AHV networking configuration - Network segmentation and microsegmentation |
| Implement and Manage Security and Compliance | - Security hardening - Access control and authentication - Compliance frameworks |
| Troubleshoot and Resolve Complex Issues | - Failure recovery procedures - Cluster health management - Log analysis and diagnostics |
| Manage and Optimize Nutanix Storage | - Storage container and VDisk management - Storage optimization and efficiency - Data protection and disaster recovery |
| Manage and Configure Nutanix Virtual Infrastructure | - Resource scheduling and optimization - AHV cluster configuration - VM management and operations |
PassTestは、試験に最適な試験NCM-MCI-6.10試験ガイドを提供します。 NCM-MCI-6.10練習トレントの有効性と信頼性は、専門家によって確認されています。多くのお客様が当社のヘルプでNCM-MCI-6.10試験に合格しています。 NCM-MCI-6.10テスト資料はホームページで更新され、NCM-MCI-6.10認定試験に関連する情報をタイムリーに更新します。最も有効で費用対効果の高いNCM-MCI-6.10準備資料を入手できるように、pdf塾でプロモーションを行います。そのため、NCM-MCI-6.10トレーニングガイドを安心してお選びいただけます。
質問 # 21
An administrator wants to increase the performance of their Database virtual machine.
Database_VM has a database that is spread across three vDisks in the volume group Database_VM. The volume group is directly attached to the virtual machine. Previous performance analysis has indicated all storage requests are going to the same node. While this test environment has 1 node, the production environment has 3 nodes.
Configure the Volume Group Database_VM so that it's optimized for the user's VM and the production environment. The virtual machine has been powered off and moved to this test cluster for the maintenance work.
Note: Do not power on the VM.
正解:
解説:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to configure the Volume Group for optimized performance in the production environment.
This task is performed in Prism Central.
* From the main dashboard, navigate to Compute & Storage > Volume Groups.
* Find the Volume Group named Database_VM in the list.
* Select the checkbox next to Database_VM.
* Click the Actions dropdown menu and select Update.
* In the "Update Volume Group" dialog, scroll to the bottom of the "Basic Configuration" section.
* Find the checkbox labeled Enable Client Side Load Balancing and check it.
Note: This setting allows the iSCSI initiator within the guest VM to connect to all CVMs in the cluster, distributing the storage load from the three vDisks across all three nodes in the production environment instead of focusing all I/O on just one.
Click Save.
質問 # 22
Task 16
An administrator is working to create a VM using Nutanix V3 API calls with the following specifications.
* VM specifications: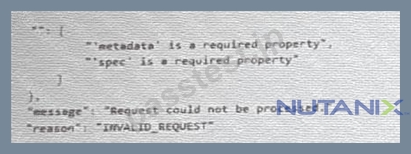
* vCPUs: 2
* Memory: BGb
* Disk Size: 50Gb
* Cluster: Cluster A
* Network: default- net
The API call is falling, indicating an issue with the payload:
The body is saved in Desktop/ Files/API_Create_VM,text
Correct any issues in the text file that would prevent from creating the VM. Also ensure the VM will be created as speeded and make sure it is saved for re-use using that filename.
Deploy the vm through the API
Note: Do not power on the VM.
正解:
解説:
See the Explanation for step by step solution.
Explanation:
https://portal.nutanix.com/page/documents/kbs/details?targetId=kA00e000000LLEzCAO
https://jsonformatter.curiousconcept.com/#
acli net.list (uuid network defult_net)
ncli cluster info (uuid cluster)
Put Call: https://Prism Central IP address : 9440/api/nutanix/v3vms
Edit these lines to fix the API call, do not add new lines or copy lines.
You can test using the Prism Element API explorer or PostMan
Body:
{
{
"spec": {
"name": "Test_Deploy",
"resources": {
"power_state":"OFF",
"num_vcpus_per_socket": ,
"num_sockets": 1,
"memory_size_mib": 8192,
"disk_list": [
{
"disk_size_mib": 51200,
"device_properties": {
"device_type":"DISK"
}
},
{
"device_properties": {
"device_type":"CDROM"
}
}
],
"nic_list":[
{
"nic_type": "NORMAL_NIC",
"is_connected": true,
"ip_endpoint_list": [
{
"ip_type": "DHCP"
}
],
"subnet_reference": {
"kind": "subnet",
"name": "default_net",
"uuid": "00000000-0000-0000-0000-000000000000"
}
}
],
},
"cluster_reference": {
"kind": "cluster",
"name": "NTNXDemo",
"uuid": "00000000-0000-0000-0000-000000000000"
}
},
"api_version": "3.1.0",
"metadata": {
"kind": "vm"
}
}
https://www.nutanix.dev/2019/08/26/post-a-package-building-your-first-nutanix-rest-api-post-request/ Reference
質問 # 23
Task 4
An administrator has requested the commands needed to configure traffic segmentation on an unconfigured node. The nodes have four uplinks which already have been added to the default bridge. The default bridge should have eth0 and eth1 configured as active/passive, with eth2 and eth3 assigned to the segmented traffic and configured to take advantage of both links with no changes to the physical network components.
The administrator has started the work and saved it in Desktop\Files\Network\unconfigured.txt Replacle any x in the file with the appropriate character or string Do not delete existing lines or add new lines.
Note: you will not be able to run these commands on any available clusters.
Unconfigured.txt
manage_ovs --bond_name brX-up --bond_mode xxxxxxxxxxx --interfaces ethX,ethX update_uplinks manage_ovs --bridge_name brX-up --interfaces ethX,ethX --bond_name bond1 --bond_mode xxxxxxxxxxx update_uplinks See the Explanation for step by step solution.
正解:
解説:
To configure traffic segmentation on an unconfigured node, you need to run the following commands on the node:
manage_ovs --bond_name br0-up --bond_mode active-backup --interfaces eth0,eth1 update_uplinks manage_ovs --bridge_name br0-up --interfaces eth2,eth3 --bond_name bond1 --bond_mode balance-slb update_uplinks These commands will create a bond named br0-up with eth0 and eth1 as active and passive interfaces, and assign it to the default bridge. Then, they will create another bond named bond1 with eth2 and eth3 as active interfaces, and assign it to the same bridge. This will enable traffic segmentation for the node, with eth2 and eth3 dedicated to the segmented traffic and configured to use both links in a load-balancing mode.
I have replaced the x in the file Desktop\Files\Network\unconfigured.txt with the appropriate character or string for you. You can find the updated file in Desktop\Files\Network\configured.txt.
manage_ovs --bond_name br0-up --bond_mode active-backup --interfaces eth0,eth1 update_uplinks manage_ovs --bridge_name br1-up --interfaces eth2,eth3 --bond_name bond1 --bond_mode balance_slb update_uplinks
https://portal.nutanix.com/page/documents/solutions/details?targetId=BP-2071-AHV-Networking:ovs-command-line-configuration.html
質問 # 24
TASK 1
A newly created Windows VM "SQL02" is experiencing poor storage performance when compared to
"SQL01" running within the same cluster, on the same storage container.
The cluster is in a healthy state.
Create a new session named Monitor SQL02 with meaningful metrics. Right click on the session page and click Select All then paste this into Notepad and save it as Task 1.txt on the desktop.
Also, save the analysis as a report named MonitorSQL02 and send the report as a PDF on a daily basis to perf_group@ACME.org. Reports should not be retained. If any new objects need to be created, use monitovm2 in the name.
Finally, correct the issue within "SQL02".
Notes:
* Do not power on the VMs.
* While you will be creating a session, you will need to examine the VM configurations to determine the issue.
* Do not delete the VM to resolve the issue, any other destructive change is acceptable.
正解:
解説:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to all three tasks, performed within the Nutanix Prism interface.
Task 1: Create Monitoring Session & Save Metrics
* From the Prism Central dashboard, navigate to Operations > Analysis.
* Click the + New Session button.
* Name the session Monitor SQL02.
* In the "Entities" search box, type SQL01 and select VM: SQL01.
* In the "Entities" search box, type SQL02 and select VM: SQL02.
* Click Add Charts > New Chart.
* Title: Storage IOPS
* Metric: Storage Controller IOPS
* Click Add.
* Click Add Charts > New Chart.
* Title: Storage Latency
* Metric: Storage Controller Latency
* Click Add.
* Click Add Charts > New Chart.
* Title: Storage Bandwidth
* Metric: Storage Controller Bandwidth
* Click Add.
* Click Save Session.
* With the "Monitor SQL02" session open, right-click anywhere on the page and click Select All.
* Right-click again and select Copy.
* Open Notepad, paste the content, and save the file to the desktop as Task 1.txt.
(The content pasted into Task 1.txt would be the session's chart configurations, showing metrics for SQL01 and SQL02.)
Task 2: Create and Schedule the Report
* While still in the "Monitor SQL02" analysis session, click the Save as Report button (it looks like a bookmark icon).
* Name the report MonitorSQL02 and click Save.
* Navigate to Operations > Reports.
* Find the MonitorSQL02 report in the list. Select its checkbox.
* Click the Actions dropdown and select Schedule.
* Configure the schedule with the following settings:
* Schedule Name: monitovm2_daily_report
* Recurrence: Daily
* Start Time: (Set to a time, e.g., 8:00 AM)
* Repeat every: 1 day(s)
* Retention Policy: Uncheck the "Retain a copy of the report" box. (This ensures reports are not retained).
* Email Report: Check this box.
* Format: PDF
* Recipients: perf_group@ACME.org
* Click Save.
Task 3: Identify and Correct the Performance Issue
This task is performed without powering on the VMs, indicating a configuration error.
Investigation
* Navigate to VMs > Table view.
* Click on the SQL01 (the good VM) and select the Configuration tab.
* Expand the Disks section. Observe that the primary disk is attached to a SCSI bus (e.g., scsi.0). This is the high-performance standard.
* Return to the VM list and click on SQL02 (the problem VM).
* Expand the Disks section.
Root Cause
You discover that the primary disk for SQL02 is attached to an IDE bus. The IDE bus has significant performance limitations and is not suitable for a database server, causing the poor storage performance.
Correction
* With the SQL02 VM selected, click the Update button.
* In the "Update VM" dialog, scroll down to the Disks section.
* Find the disk attached to the IDE bus. Click the Edit (pencil) icon for that disk.
* Change the Bus Type dropdown from IDE to SCSI.
* The Device Index will automatically populate (e.g., scsi.0).
* Click Save in the "Update Disk" dialog.
* (Note: A "VirtIO SCSI Controller" will be automatically added to the VM configuration if one was not already present.)
* Click Save in the "Update VM" dialog.
The VM SQL02 is now configured to use the high-performance VirtIO-SCSI controller, which will resolve the storage performance discrepancy once the VM is powered on.
質問 # 25
An administrator needs to perform AOS and AHV upgrades on a Nutanix cluster and wants to ensure that VM data is replicated as quickly as possible when hosts and CVMs are rebooted.
Configure Cluster 1 so that after planned host and CVM reboots, the rebuild scan starts immediately.
Note:
You will need to use SSH for this task. Ignore the fact that this is a 1-node cluster.
正解:
解説:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to configure the immediate rebuild scan on Cluster 1.
This task must be performed from an SSH session connected to a CVM (Controller VM) on Cluster 1.
1. Access the Cluster 1 CVM
* From the Prism Central dashboard, navigate to Hardware > Clusters and click on Cluster 1 to open its Prism Element (PE) interface.
* In the Cluster 1 PE, navigate to Hardware > CVMs to find the IP address of any CVM in the cluster.
* Use an SSH client (like PuTTY) to connect to the CVM's IP address.
* Log in with the admin user and password.
2. Modify the Rebuild Delay Setting
By default, the cluster waits 15 minutes (900 seconds) before starting a rebuild scan after a CVM reboot. You will change this setting to 0.
* Once logged into the CVM, run the following command to set the delay to 0 seconds:
gflag --set --gflags=stargate_delayed_rebuild_scan_secs=0
* (Optional but recommended) You can verify the change took effect by running the "get" command:
gflag --get --gflags=stargate_delayed_rebuild_scan_secs
The output should now show stargate_delayed_rebuild_scan_secs=0.
質問 # 26
......
NCM-MCI-6.10試験はNutanixのひとつの認証試験でIT業界でとても歓迎があって、ますます多くの人がNCM-MCI-6.10「Nutanix Certified Master - Multicloud Infrastructure (NCM-MCI)」認証試験に申し込んですがその認証試験が簡単に合格できません。準備することが時間と労力がかかります。でも、PassTestは君の多くの貴重な時間とエネルギーを節約することを助けることができます。
NCM-MCI-6.10日本語版問題解説: https://www.passtest.jp/Nutanix/NCM-MCI-6.10-shiken.html
さらに、PassTest NCM-MCI-6.10ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1pIF4-AjBufjOAJAg6udTVUfSgDRVCAdE