If you are quite worried about you exam and want to pass the exam successfully, you can choose us. AI-300 training materials is high quality and valid. They can help you prepare for and pass your exam easily. We have experienced experts compile AI-300 exam braindumps, therefore the quality can be guaranteed. Besides, AI-300 Training Materials cover most knowledge points for the exam, and you can master most knowledge for the exam. We provide you with free update for one year for AI-300 exam dumps, that is to say, you can obtain the latest information for the exam timely.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Topic 2: Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Topic 3: Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Topic 4: Implement machine learning model lifecycle and operations | 25–30% | - Orchestrate model training and experimentation
|
| Topic 5: Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
>> Reliable AI-300 Test Duration <<
In today’s global market, tens of thousands of companies and business people are involved in this line of AI-300 exam. It is of utmost importance to inquire into the status of exam candidates’ wills to figure out what are the AI-300 practice materials you really needed. According to your requirements we made our AI-300 Study Materials for your information, and for our pass rate of the AI-300 exam questions is high as 98% to 100%, we can claim that you will pass the exam for sure.
NEW QUESTION # 20
You create a workspace by using Azure Machine Learning Studio.
You must run a Python SDK v2 notebook in the workspace by using Azure Machine Learning Studio.
You need to reset the state of the notebook.
Which three actions should you use? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
Answer: B,D,E
Explanation:
To reset the state of a Python SDK v2 notebook in Azure Machine Learning Studio, you can perform any of the following three individual actions:
Stop the current kernel
Reset the compute instance
Change the current kernel
Each of these steps acts as a standalone solution to clear the current runtime memory, variables, and overall execution state of your notebook.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-run-jupyter-notebooks
NEW QUESTION # 21
Drag and Drop Question
You manage an Microsoft Foundry project.
You deploy a large language model from the model catalog.
You need to manually evaluate the model, collect the statistics, and be able to review the results later.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.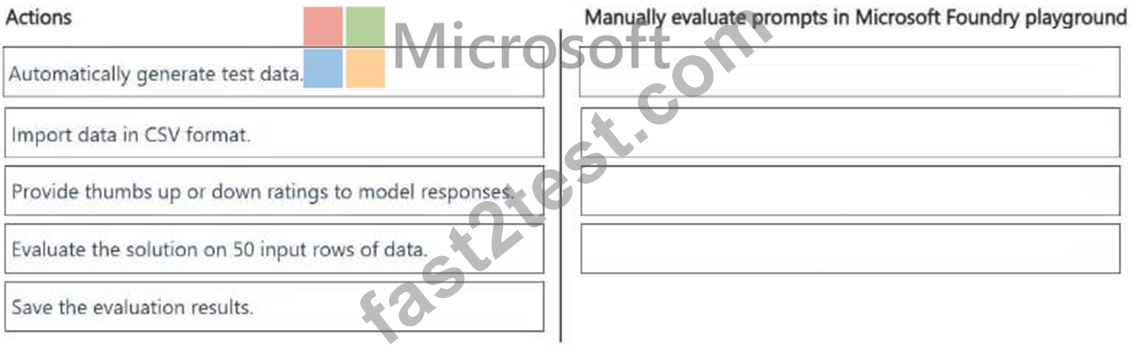
Answer:
Explanation: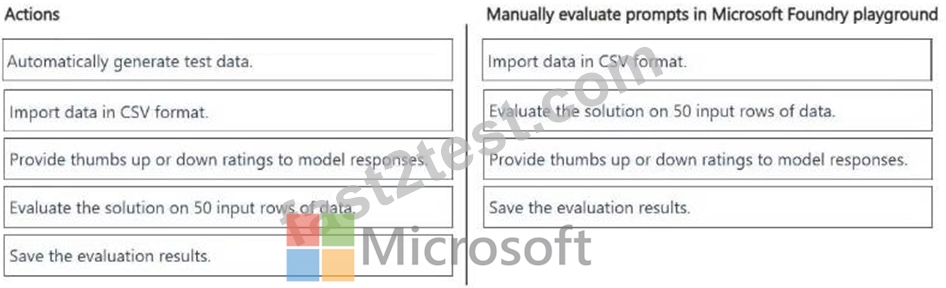
Explanation:
Step 1: Import Data in CSV Format
Supported formats: Azure AI Studio natively accepts .csv and .jsonl files for evaluation datasets.
Requirement: Your file must contain the input columns (e.g., user prompts) that you want to test against the model.
Step 2: Evaluate the Solution on 50 input Rows
Sample size: 50 rows is an excellent size for a manual, qualitative test baseline.
Execution: You will upload this dataset into the Evaluation blade of your project and map your data fields to the model's inputs.
Step 3: Provide thumbs up or down ratings to model responses
Manual UI: The platform features a manual review interface (often called human-in-the-loop evaluation).
Feedback: You can view the model's generated response for each of the 50 rows side-by-side with the input and log your binary (thumbs up/down) or detailed feedback.
Step 4: Save the evaluation results
Persistence: Once completed, the session is saved to your project's run history.
Review: You can return to the dashboard later to view aggregate statistics, check pass/fail rates, and export the annotated data for your records.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-perform-azure-migrate-at-scale-using-csv-import-for-large-datacenter-inventories/view
NEW QUESTION # 22
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to recommend an experiment-tracking strategy that ensures consistent experiment results. What should you recommend?
Answer: A
Explanation:
Scenario:
The current challenges faced by the data science team include the following: Experiment tracking is inconsistent To support the business goals, Fabrikam Inc. identifies these technical requirements: Implement experiment tracking and model versioning for all training jobs.
In Azure-based AI operations, integrating MLflow with Azure Machine Learning (Azure ML) provides a unified interface to track experiments, version models, and manage the lifecycle of both traditional ML and Generative AI workloads.
Direct Implementation Strategy
To ensure consistent experiment results and comparison of prompt strategies versus fine-tuned models, use the following architectural approach:
Centralized Tracking: Configure the MLflow tracking URI to point to your Azure ML Workspace.
This allows all logs (from local notebooks, remote training jobs, or Prompt Flow) to aggregate in a single "Experiments" dashboard.
Prompt Strategy Comparison: Use Azure ML Prompt Flow to develop and test prompt variants.
Prompt Flow automatically logs metrics (like groundedness and relevance) which can be viewed alongside fine-tuned model metrics in the Azure ML Studio.
Model Versioning: Use the MLflow Model Registry hosted within Azure ML. Each successful training or fine-tuning run should be registered as a new version of a named model, providing a clear lineage from data to deployment.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-use-mlflow-cli-runs
NEW QUESTION # 23
A team is validating a generative AI assistant for a company. The assistant generates responses by using internal knowledge sources.
The company requires assurance that responses are accurate, supported by sources, and related to the user prompts before enabling production access.
You need to implement quality metrics that confirm the assistant produces reliable and meaningful responses.
Which two evaluation metrics should you use? Each correct answer presents part of the solution.
Answer: B,C
Explanation:
Groundedness and Relevance directly measure the two quality characteristics specified in the requirement.
Groundedness evaluates whether the generated response is supported by the supplied knowledge context rather than introducing unsupported or fabricated information. Microsoft Foundry defines the Groundedness evaluator as measuring how well a generated response aligns with the provided context without fabricating content. For an assistant that relies on internal knowledge sources, this is the primary metric for determining whether its claims are traceable to retrieved evidence.
Relevance evaluates whether the generated response actually addresses the user ' s query. Microsoft defines the Relevance evaluator as measuring how relevant the response is to the query, including whether it appropriately and accurately responds to the user ' s request. This detects responses that may be factually grounded yet tangential or insufficiently focused.
Harmfulness and Fairness are safety-oriented dimensions rather than measures of factual support or query alignment. Tone assesses communication characteristics but does not establish whether a response is supported by source material or relevant to the prompt.
Therefore, the required pair is Groundedness + Relevance .
Study Guide Reference: Implement generative AI quality assurance and observability - Foundry quality evaluators, groundedness, relevance, RAG evaluation, and pre-production validation.
NEW QUESTION # 24
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to recommend a solution to address Fabrikam Inc.'s limited rollback capability. Which deployment approach should you recommend?
Answer: C
Explanation:
Scenario:
Current Environment: Deployment is performed manually by data scientists, with limited rollback capability.
The correct deployment type to address this problem is Managed online endpoints with traffic splitting.
Native traffic control: Managed online endpoints naturally support native blue-green deployments under a single HTTP endpoint.
Granular traffic splitting: You can deploy a new model version (e.g., green) with 0% live traffic, safely test it, and then incrementally shift traffic from the old version (e.g., blue).Instant rollbacks:
If the new model shows bugs or degrades performance, you can immediately change the traffic percentage configuration back to 100% for the old deployment. This eliminates the risks of limited rollback capabilities.
No infrastructure overhead: Unlike setting up manual routing, Azure handles the underlying infrastructure and routing mechanisms in a turnkey fashion.
Incorrect:
[Not A]
VM-hosted REST APIs: This forces you to build, maintain, and configure your own custom load balancers and deployment scripts to handle routing and rollbacks, which increases operational risk and complexity.
[Not B]
Azure Kubernetes Service with blue-green switching: While it supports blue-green deployments, it requires you to manage complex Kubernetes infrastructure, service meshes, or ingress controllers manually to handle the traffic switching.
[Not D]
Batch endpoints: These are designed for long-running, asynchronous processing of large data batches rather than real-time requests where instant live-traffic rollback is required.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-safely-rollout-online-endpoints
NEW QUESTION # 25
......
Services like quick downloading within five minutes, convenient and safe payment channels made for your convenience. Even newbies will be tricky about this process. Unlike product from stores, quick browse of our AI-300 practice materials can give you the professional impression wholly. So, they are both efficient in practicing and downloading process. By the way, we also have free demo of AI-300 practice materials as freebies for your reference to make your purchase more effective.
Latest AI-300 Exam Bootcamp: https://www.fast2test.com/AI-300-premium-file.html