2026 Latest Actual4test Databricks-Generative-AI-Engineer-Associate PDF Dumps and Databricks-Generative-AI-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1K7fgqR3KkD4xzkr3LLPdoYSNNRVPSCoz
Databricks-Generative-AI-Engineer-Associate exam dumps are famous for high-quality, since we have a professional team to collect and research the first-hand information. We have reliable channel to ensure you that Databricks-Generative-AI-Engineer-Associate exam braindumps you receive is the latest information of the exam. We are strict with the quality and answers of Databricks-Generative-AI-Engineer-Associate Exam Materials, we can guarantee you that what you receive are the best and most effective. In addition, online and offline chat service stuff are available, and if you have any questions for Databricks-Generative-AI-Engineer-Associate exam dumps, you can consult us.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Valid Databricks-Generative-AI-Engineer-Associate Exam Camp Pdf <<
Actual4test Databricks-Generative-AI-Engineer-Associate even guarantees that you will crack the Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) test on the first try by using our dumps. If you fail to achieve success in the Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) examination, then you can get a full refund according to terms and conditions. You can immediately start using our dumps after purchasing them. For better understanding of our three formats, read this article further.
NEW QUESTION # 89
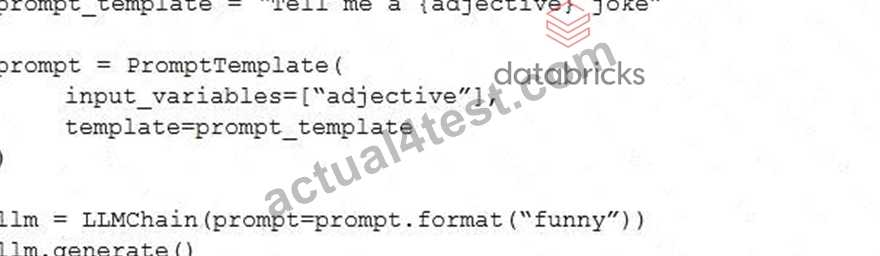
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.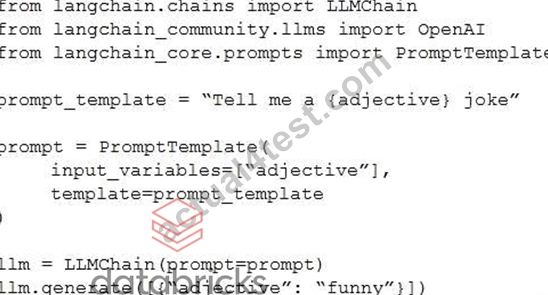
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
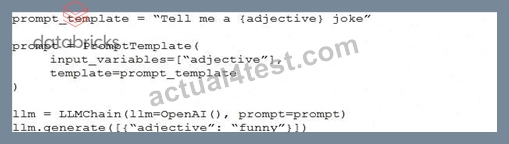
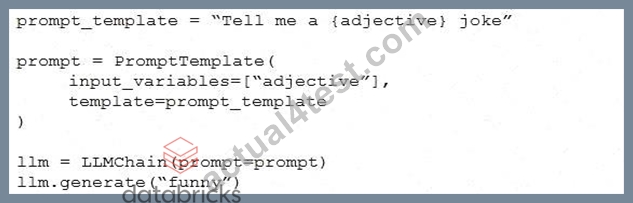
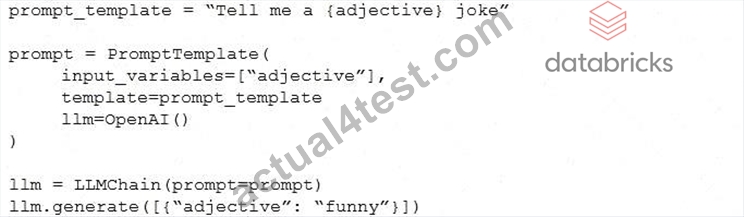
Answer: C
Explanation:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods:
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
* Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
* Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
* Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 90
A Generative Al Engineer is building a system that will answer questions on currently unfolding news topics.
As such, it pulls information from a variety of sources including articles and social media posts. They are concerned about toxic posts on social media causing toxic outputs from their system.
Which guardrail will limit toxic outputs?
Answer: D
Explanation:
The system answers questions on unfolding news topics using articles and social media, with a concern about toxic outputs from toxic inputs. A guardrail must limit toxicity in the LLM's responses. Let's evaluate the options.
* Option A: Use only approved social media and news accounts to prevent unexpected toxic data from getting to the LLM
* Curating input sources (e.g., verified accounts) reduces exposure to toxic content at the data ingestion stage, directly limiting toxic outputs. This is a proactive guardrail aligned with data quality control.
* Databricks Reference:"Control input data quality to mitigate unwanted LLM behavior, such as toxicity"("Building LLM Applications with Databricks," 2023).
* Option B: Implement rate limiting
* Rate limiting controls request frequency, not content quality. It prevents overload but doesn't address toxicity in social media inputs or outputs.
* Databricks Reference: Rate limiting is for performance, not safety:"Use rate limits to manage compute load"("Generative AI Cookbook").
* Option C: Reduce the amount of context items the system will include in consideration for its response
* Reducing context might limit exposure to some toxic items but risks losing relevant information, and it doesn't specifically target toxicity. It's an indirect, imprecise fix.
* Databricks Reference: Context reduction is for efficiency, not safety:"Adjust context size based on performance needs"("Databricks Generative AI Engineer Guide").
* Option D: Log all LLM system responses and perform a batch toxicity analysis monthly
* Logging and analyzing responses is reactive, identifying toxicity after it occurs rather than preventing it. Monthly analysis doesn't limit real-time toxic outputs.
* Databricks Reference: Monitoring is for auditing, not prevention:"Log outputs for post-hoc analysis, but use input filters for safety"("Building LLM-Powered Applications").
Conclusion: Option A is the most effective guardrail, proactively filtering toxic inputs from unverified sources, which aligns with Databricks' emphasis on data quality as a primary safety mechanism for LLM systems.
NEW QUESTION # 91
An AI developer team wants to fine-tune an open-weight model to have exceptional performance on a code generation use case. They are trying to choose the best model to start with. They want to minimize model hosting costs and are using Hugging Face model cards and spaces to explore models. Which TWO model attributes and metrics should the team focus on to make their selection?
Answer: B,E
Explanation:
To optimize for code generation performance and hosting costs, a Generative AI engineer must look at specific metrics.
Big Code Models Leaderboard (A): This is the industry-standard benchmark for code-specific LLMs (like StarCoder or CodeLlama). It measures performance on tasks like HumanEval and MBPP, providing a direct indicator of how well the model handles programming logic.
Number of model parameters (B): This is the primary driver of hosting costs. Larger models (e.g., 70B) require more GPU memory (VRAM) and more expensive compute instances (like A100s/H100s) than smaller models (e.g., 7B or 13B). To minimize costs, the team should look for the smallest model that achieves a high score on the Big Code Leaderboard.
Note: MTEB (C) is for embeddings, and Chatbot Arena (D) is for general-purpose chat, neither of which is the primary metric for specialized code generation fine-tuning.
NEW QUESTION # 92
A Generative Al Engineer has created a RAG application to look up answers to questions about a series of fantasy novels that are being asked on the author's web forum. The fantasy novel texts are chunked and embedded into a vector store with metadata (page number, chapter number, book title), retrieved with the user' s query, and provided to an LLM for response generation. The Generative AI Engineer used their intuition to pick the chunking strategy and associated configurations but now wants to more methodically choose the best values.
Which TWO strategies should the Generative AI Engineer take to optimize their chunking strategy and parameters? (Choose two.)
Answer: C,D
Explanation:
To optimize a chunking strategy for a Retrieval-Augmented Generation (RAG) application, the Generative AI Engineer needs a structured approach to evaluating the chunking strategy, ensuring that the chosen configuration retrieves the most relevant information and leads to accurate and coherent LLM responses. Here
' s why C and E are the correct strategies:
Strategy C: Evaluation Metrics (Recall, NDCG)
* Define an evaluation metric : Common evaluation metrics such as recall, precision, or NDCG (Normalized Discounted Cumulative Gain) measure how well the retrieved chunks match the user ' s query and the expected response.
* Recall measures the proportion of relevant information retrieved.
* NDCG is often used when you want to account for both the relevance of retrieved chunks and the ranking or order in which they are retrieved.
* Experiment with chunking strategies : Adjusting chunking strategies based on text structure (e.g., splitting by paragraph, chapter, or a fixed number of tokens) allows the engineer to experiment with various ways of slicing the text. Some chunks may better align with the user ' s query than others.
* Evaluate performance : By using recall or NDCG, the engineer can methodically test various chunking strategies to identify which one yields the highest performance. This ensures that the chunking method provides the most relevant information when embedding and retrieving data from the vector store.
Strategy E: LLM-as-a-Judge Metric
* Use the LLM as an evaluator : After retrieving chunks, the LLM can be used to evaluate the quality of answers based on the chunks provided. This could be framed as a " judge " function, where the LLM compares how well a given chunk answers previous user queries.
* Optimize based on the LLM ' s judgment : By having the LLM assess previous answers and rate their relevance and accuracy, the engineer can collect feedback on how well different chunking configurations perform in real-world scenarios.
* This metric could be a qualitative judgment on how closely the retrieved information matches the user ' s intent.
* Tune chunking parameters : Based on the LLM ' s judgment, the engineer can adjust the chunk size or structure to better align with the LLM ' s responses, optimizing retrieval for future queries.
By combining these two approaches, the engineer ensures that the chunking strategy is systematically evaluated using both quantitative (recall/NDCG) and qualitative (LLM judgment) methods. This balanced optimization process results in improved retrieval relevance and, consequently, better response generation by the LLM.
NEW QUESTION # 93
A small and cost-conscious startup in the cancer research field wants to build a RAG application using Foundation Model APIs.
Which strategy would allow the startup to build a good-quality RAG application while being cost-conscious and able to cater to customer needs?
Answer: C
Explanation:
For a small, cost-conscious startup in the cancer research field, choosing a domain-specific and smaller LLM is the most effective strategy. Here's whyBis the best choice:
* Domain-specific performance: A smaller LLM that has been fine-tuned for the domain of cancer research will outperform a general-purpose LLM for specialized queries. This ensures high-quality responses without needing to rely on a large, expensive LLM.
* Cost-efficiency: Smaller models are cheaper to run, both in terms of compute resources and API usage costs. A domain-specific smaller LLM can deliver good quality responses without the need for the extensive computational power required by larger models.
* Focused knowledge: In a specialized field like cancer research, having an LLM tailored to the subject matter provides better relevance and accuracy for queries, while keeping costs low.Large, general- purpose LLMs may provide irrelevant information, leading to inefficiency and higher costs.
This approach allows the startup to balance quality, cost, and customer satisfaction effectively, making it the most suitable strategy.
NEW QUESTION # 94
......
The community has a lot of talent, people constantly improve their own knowledge to reach a higher level. But the country's demand for high-end IT staff is still expanding, internationally as well. So many people want to pass Databricks Databricks-Generative-AI-Engineer-Associate certification exam. But it is not easy to pass the exam. However, in fact, as long as you choose a good training materials to pass the exam is not impossible. We Actual4test Databricks Databricks-Generative-AI-Engineer-Associate Exam Training materials in full possession of the ability to help you through the certification. Actual4test website training materials are proved by many candidates, and has been far ahead in the international arena. If you want to through Databricks Databricks-Generative-AI-Engineer-Associate certification exam, add the Actual4test Databricks Databricks-Generative-AI-Engineer-Associate exam training to Shopping Cart quickly!
Databricks-Generative-AI-Engineer-Associate Discount: https://www.actual4test.com/Databricks-Generative-AI-Engineer-Associate_examcollection.html
2026 Latest Actual4test Databricks-Generative-AI-Engineer-Associate PDF Dumps and Databricks-Generative-AI-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1K7fgqR3KkD4xzkr3LLPdoYSNNRVPSCoz