P.S. Free & New NCM-MCI-6.10 dumps are available on Google Drive shared by PDFBraindumps: https://drive.google.com/open?id=1qzoTjpFRMnckkG0lprlDexBRbTKt76Xl
Nobody wants to be stranded in the same position in his or her company and be a normal person forever. Maybe you want to get the NCM-MCI-6.10 certification, but daily work and long-time traffic make you busier to improve yourself. There is a piece of good news for you. Thanks to our NCM-MCI-6.10 Training Materials, you can learn for your NCM-MCI-6.10 certification anytime, everywhere. With our NCM-MCI-6.10 study materials, you will easily pass the NCM-MCI-6.10 examination and gain more confidence. Now let's see our products together.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Analyze and Optimize Storage Performance | 20% | - Understand storage internals and I/O patterns - Evaluate and resolve competing workload requirements - Troubleshoot storage performance bottlenecks - Optimize storage configuration and settings |
| Topic 2: Virtualization and VM Performance Optimization | 15% | - AHV administration and workload management - Performance metrics analysis and tuning - VM resource adjustment and optimization - High availability and migration management |
| Topic 3: Advanced Platform Configuration and Troubleshooting | 25% | - Security configuration and compliance - Cluster management, expansion and maintenance - Integration with third-party systems - API and CLI-based operations - Prism Central and Prism Element configuration |
| Topic 4: Business Continuity and Disaster Recovery | 15% | - Replication and recovery configuration - Failover and failback operations - Disaster recovery strategy implementation - BCDR testing and validation |
| Topic 5: Monitoring, Automation and Operational Efficiency | 5% | - Operational process optimization - Automation workflows and tools - Monitoring and alerting configuration |
| Topic 6: Network Performance and Security | 20% | - Tune overlay networking and traffic flow - Optimize physical and virtual network configurations - Network troubleshooting and optimization - Implement and analyze Flow security policies |
>> NCM-MCI-6.10 Valid Exam Tips <<
After cracking the Nutanix Certified Master - Multicloud Infrastructure (NCM-MCI) (NCM-MCI-6.10) exam you will receive the credential badge. It will pave your way toward well-paying jobs or promotions in any reputed tech company. At PDFBraindumps have customizable Nutanix Certified Master - Multicloud Infrastructure (NCM-MCI) (NCM-MCI-6.10) practice exams for the students to review and improve their preparation. The Nutanix Certified Master - Multicloud Infrastructure (NCM-MCI) (NCM-MCI-6.10) practice test material product of PDFBraindumps are created by experts with the dedication to help customers crack the Nutanix Certified Master - Multicloud Infrastructure (NCM-MCI) (NCM-MCI-6.10) exam on the first attempt.
NEW QUESTION # 19
Task 13
An administrator found a CentOS VM, Cent_Down, on the cluster with a corrupted network stack. To correct the issue, the VM will need to be restored from a previous snapshot to become reachable on the network again.
VM credentials:
Username: root
Password: nutanix/4u
Restore the VM and ensure it is reachable on the network by pinging 172.31.0.1 from the VM.
Power off the VM before proceeding.
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To restore the VM and ensure it is reachable on the network, you can follow these steps:
Log in to the Web Console of the cluster where the VM is running.
Click on Virtual Machines on the left menu and find Cent_Down from the list. Click on the power icon to power off the VM.
Click on the snapshot icon next to the power icon to open the Snapshot Management window.
Select a snapshot from the list that was taken before the network stack was corrupted. You can use the date and time information to choose a suitable snapshot.
Click on Restore VM and confirm the action in the dialog box. Wait for the restore process to complete.
Click on the power icon again to power on the VM.
Log in to the VM using SSH or console with the username and password provided.
Run the command ping 172.31.0.1 to verify that the VM is reachable on the network. You should see a reply from the destination IP address.
Go to VMS from the prism central gui
Select the VMand go to More -> Guest Shutdown
Go to Snapshots tab and revert to latest snapshot available
power on vm and verify if ping is working
NEW QUESTION # 20
Task 9
The application team has requested several mission-critical VMs to be configured for disaster recovery. The remote site (when added) will not be managed by Prism Central. As such, this solution should be built using the Web Console.
Disaster Recovery requirements per VM:
Mkt01
RPO: 2 hours
Retention: 5 snapshots
Fin01
RPO: 15 minutes
Retention: 7 days
Dev01
RPO: 1 day
Retention: 2 snapshots
Configure a DR solution that meets the stated requirements.
Any objects created in this item must start with the name of the VM being protected.
Note: the remote site will be added later
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To configure a DR solution that meets the stated requirements, you can follow these steps:
Log in to the Web Console of the source cluster where the VMs are running.
Click on Protection Domains on the left menu and click on Create Protection Domain.
Enter a name for the protection domain, such as PD_Mkt01, and a description if required. Click Next.
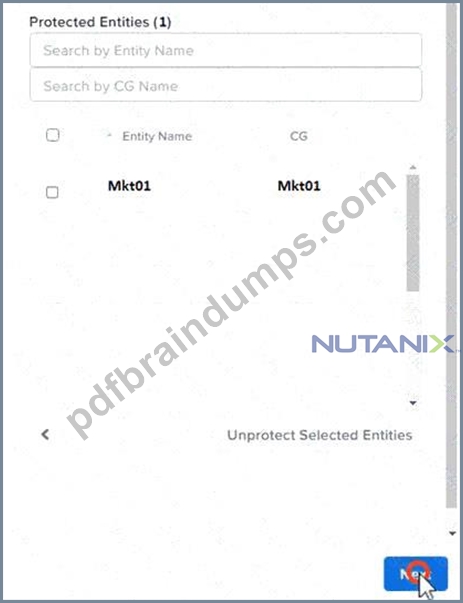
Select Mkt01 from the list of VMs and click Next.
Select Schedule Based from the drop-down menu and enter 2 hours as the interval. Click Next.
Select Remote Site from the drop-down menu and choose the remote site where you want to replicate the VM.
Click Next.
Enter 5 as the number of snapshots to retain on both local and remote sites. Click Next.
Review the protection domain details and click Finish.
Repeat the same steps for Fin01 and Dev01, using PD_Fin01 and PD_Dev01 as the protection domain names, and adjusting the interval and retention values according to the requirements.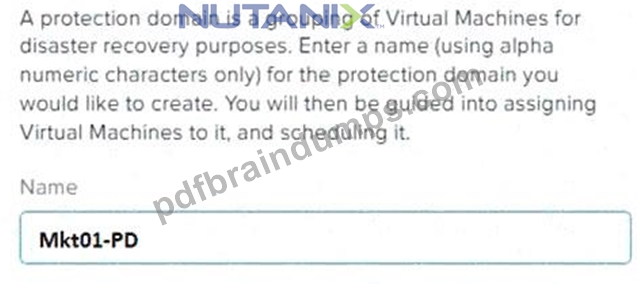
NEW QUESTION # 21
The Database team is reporting performance degradation for a business-critical application on Saturdays.
The team is requesting monitoring of processor, memory and storage utilization for the cluster for the application: SQL01, SQL02.
The report should contain views for the following:
* At the cluster level, only for the Cluster 1: The maximum percentage of CPU used
* At the VM level, including any future VM with the prefix SQL: The maximum time taken, maximum percentage of time a VM waits to use the physical CPU, out of the total CPU The report should run on Sundays at 12:00 AM for the previous 7 days. The report should show when completed.
Create a report named SQL_Batch_Saturday that meets these requirements.
Generate an instance of the report named SQL_Batch_Saturday as a CSV and save the file.
Note: You must name the report SQL_Batch_Saturday to receive any credit. Any other name will not be accepted. SMTP is not configured.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to create and run the report, performed entirely within Prism Central.
1. Create the Analysis Session
First, we will build the charts and entities for the report using the Analysis tool.
* From the Prism Central main menu, navigate to Operations > Analysis.
* Click the + New Session button.
* Add the required entities:
* In the "Entities" search box, type Cluster 1 and select Cluster: Cluster 1.
* In the "Entities" search box, type SQL01 and select VM: SQL01.
* In the "Entities" search box, type SQL02 and select VM: SQL02.
* Click Add Charts > New Chart to add the Cluster CPU chart:
* Title: Cluster 1 Max CPU Usage
* Entity Type: Cluster
* Metric: Cluster CPU Usage %
* Aggregation: Select Maximum.
* Click Add.
* Click Add Charts > New Chart to add the VM CPU Ready Time chart:
* Title: VM Max CPU Ready Time
* Entity Type: VM
* Metric: CPU Ready Time %
* Aggregation: Select Maximum.
* Click Add.
2. Save and Configure the Report
Now, save the session as a report and configure it to dynamically include all VMs with the SQL prefix.
* Click the Save as Report icon (the bookmark icon in the upper right).
* Name the report SQL_Batch_Saturday and click Save.
* Navigate to Operations > Reports.
* Find the SQL_Batch_Saturday report you just created and click its name to open the report editor.
* In the Entities tile, click the Edit (pencil) icon.
* By default, it will list "Cluster 1", "SQL01", and "SQL02".
* Change the VM selection:
* Select the radio button for All VMs prefixed with.
* In the text box, enter SQL.
* Ensure "Cluster 1" is still listed under "Clusters".
* Click Save.
3. Schedule the Report
* While still in the report editor for SQL_Batch_Saturday, click the Schedule button.
* Configure the schedule:
* Recurrence: Weekly
* Repeat on: Sunday
* Start Time: 12:00 AM
* Time Range: Previous 7 Days
* Configure the notification (as SMTP is not available):
* Expand the Notification Settings section.
* Check the box for Notify when ready (this enables the bell icon notification).
* Ensure "Email Report" is not checked.
* Click Save.
4. Generate and Save the CSV Instance
Finally, run the report now and download the CSV as requested.
* Navigate back to the main Operations > Reports list.
* Select the checkbox next to SQL_Batch_Saturday.
* Click the Actions dropdown and select Run Now.
* In the dialog, confirm the time range (e.g., "Last 7 Days") and click Run.
* Click the Report Instances tab.
* Wait for the report instance "SQL_Batch_Saturday" to finish running (the status will change from
"Running" to Succeeded).
* Once it has succeeded, click the Download (arrow) icon for that instance.
* Select the CSV format.
* Save the file to the desktop.
NEW QUESTION # 22
An administrator needs to perform AOS and AHV upgrades on a Nutanix cluster and wants to ensure that VM data is replicated as quickly as possible when hosts and CVMs are rebooted.
Configure Cluster 1 so that after planned host and CVM reboots, the rebuild scan starts immediately.
Note:
You will need to use SSH for this task. Ignore the fact that this is a 1-node cluster.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to configure the immediate rebuild scan on Cluster 1.
This task must be performed from an SSH session connected to a CVM (Controller VM) on Cluster 1.
1. Access the Cluster 1 CVM
* From the Prism Central dashboard, navigate to Hardware > Clusters and click on Cluster 1 to open its Prism Element (PE) interface.
* In the Cluster 1 PE, navigate to Hardware > CVMs to find the IP address of any CVM in the cluster.
* Use an SSH client (like PuTTY) to connect to the CVM's IP address.
* Log in with the admin user and password.
2. Modify the Rebuild Delay Setting
By default, the cluster waits 15 minutes (900 seconds) before starting a rebuild scan after a CVM reboot. You will change this setting to 0.
* Once logged into the CVM, run the following command to set the delay to 0 seconds:
gflag --set --gflags=stargate_delayed_rebuild_scan_secs=0
* (Optional but recommended) You can verify the change took effect by running the "get" command:
gflag --get --gflags=stargate_delayed_rebuild_scan_secs
The output should now show stargate_delayed_rebuild_scan_secs=0.
NEW QUESTION # 23
Task 7
An administrator has been informed that a new workload requires a logically segmented network to meet security requirements.
Network configuration:
VLAN: 667
Network: 192.168.0.0
Subnet Mask: 255.255.255.0
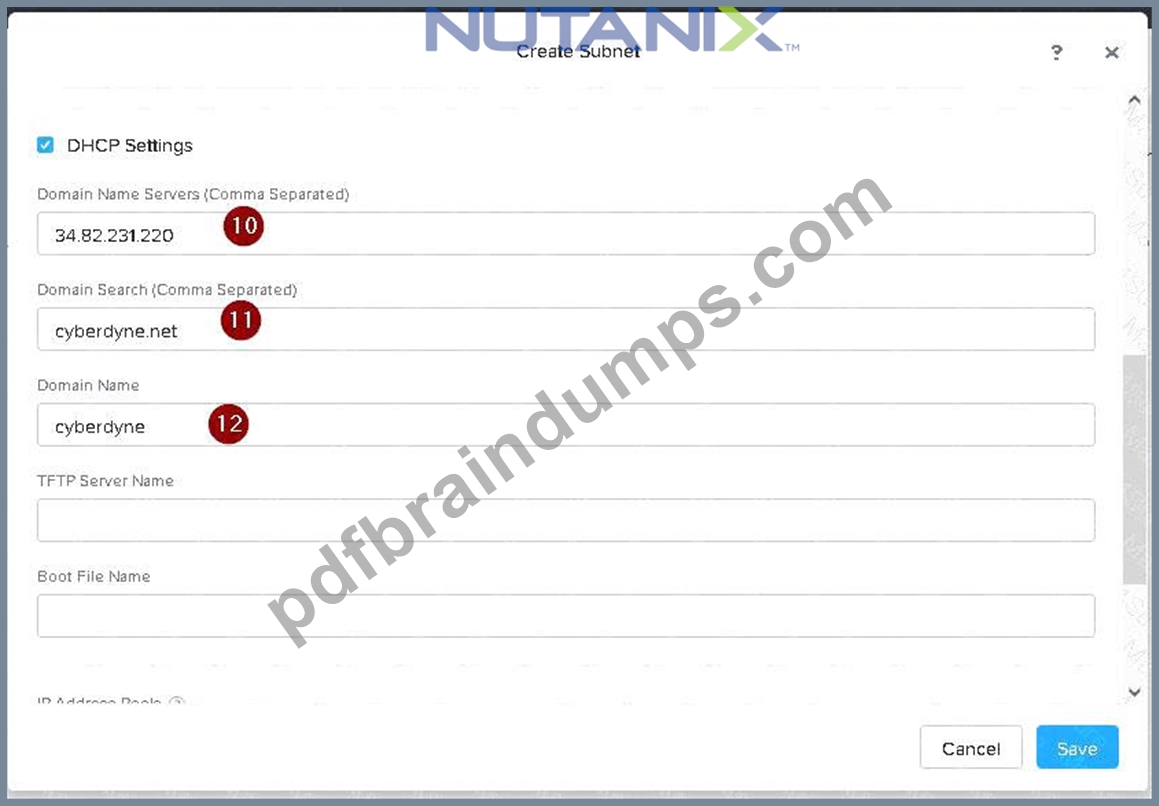
DNS server: 34.82.231.220
Default Gateway: 192.168.0.1
Domain: cyberdyne.net
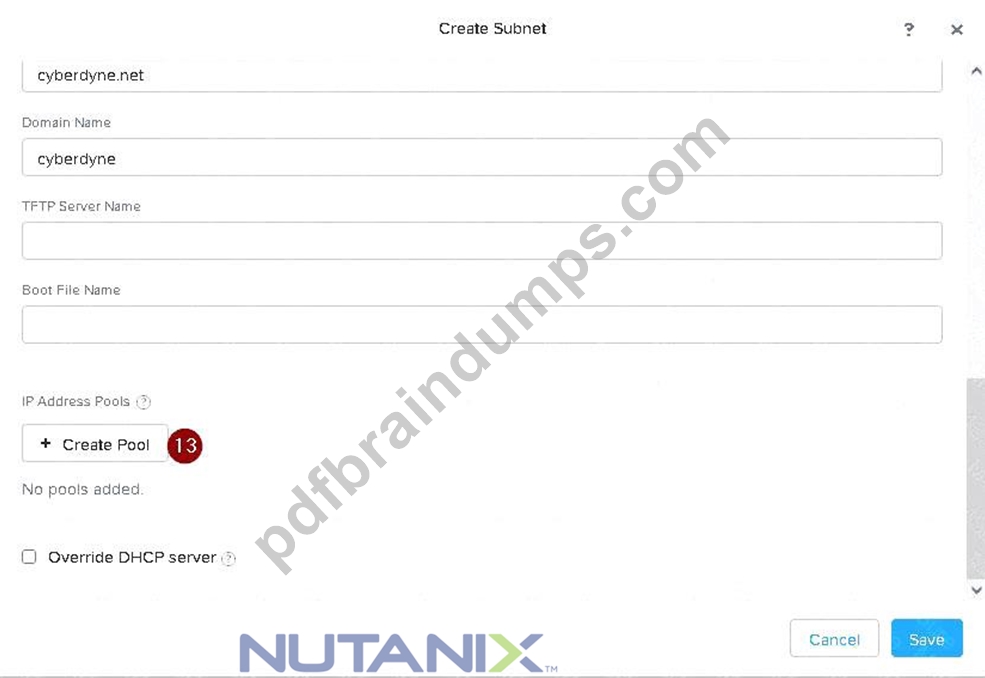
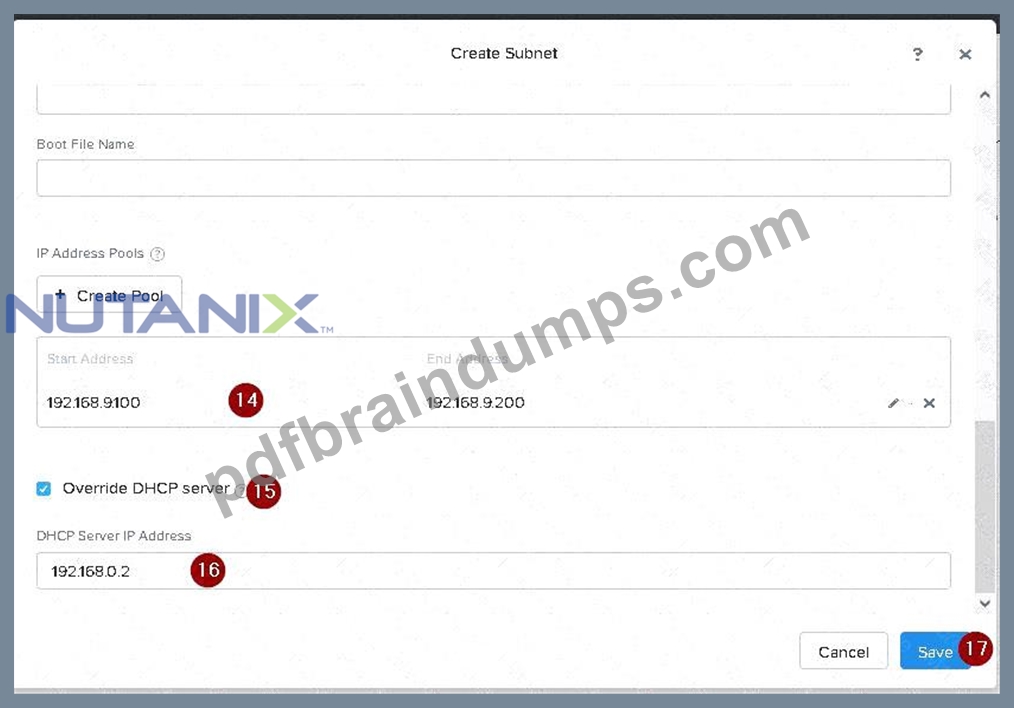
IP Pool: 192.168.9.100-200
DHCP Server IP: 192.168.0.2
Configure the cluster to meet the requirements for the new workload if new objects are required, start the name with 667.
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To configure the cluster to meet the requirements for the new workload, you need to do the following steps:
Create a new VLAN with ID 667 on the cluster. You can do this by logging in to Prism Element and going to Network Configuration > VLANs > Create VLAN. Enter 667 as the VLAN ID and a name for the VLAN, such as 667_VLAN.
Create a new network segment with the network details provided. You can do this by logging in to Prism Central and going to Network > Network Segments > Create Network Segment. Enter a name for the network segment, such as 667_Network_Segment, and select 667_VLAN as the VLAN. Enter 192.168.0.0 as the Network Address and 255.255.255.0 as the Subnet Mask. Enter 192.168.0.1 as the Default Gateway and
34.82.231.220 as the DNS Server. Enter cyberdyne.net as the Domain Name.
Create a new IP pool with the IP range provided. You can do this by logging in to Prism Central and going to Network > IP Pools > Create IP Pool. Enter a name for the IP pool, such as 667_IP_Pool, and select
667_Network_Segment as the Network Segment. Enter 192.168.9.100 as the Starting IP Address and
192.168.9.200 as the Ending IP Address.
Configure the DHCP server with the IP address provided. You can do this by logging in to Prism Central and going to Network > DHCP Servers > Create DHCP Server. Enter a name for the DHCP server, such as
667_DHCP_Server, and select 667_Network_Segment as the Network Segment. Enter 192.168.0.2 as the IP Address and select 667_IP_Pool as the IP Pool.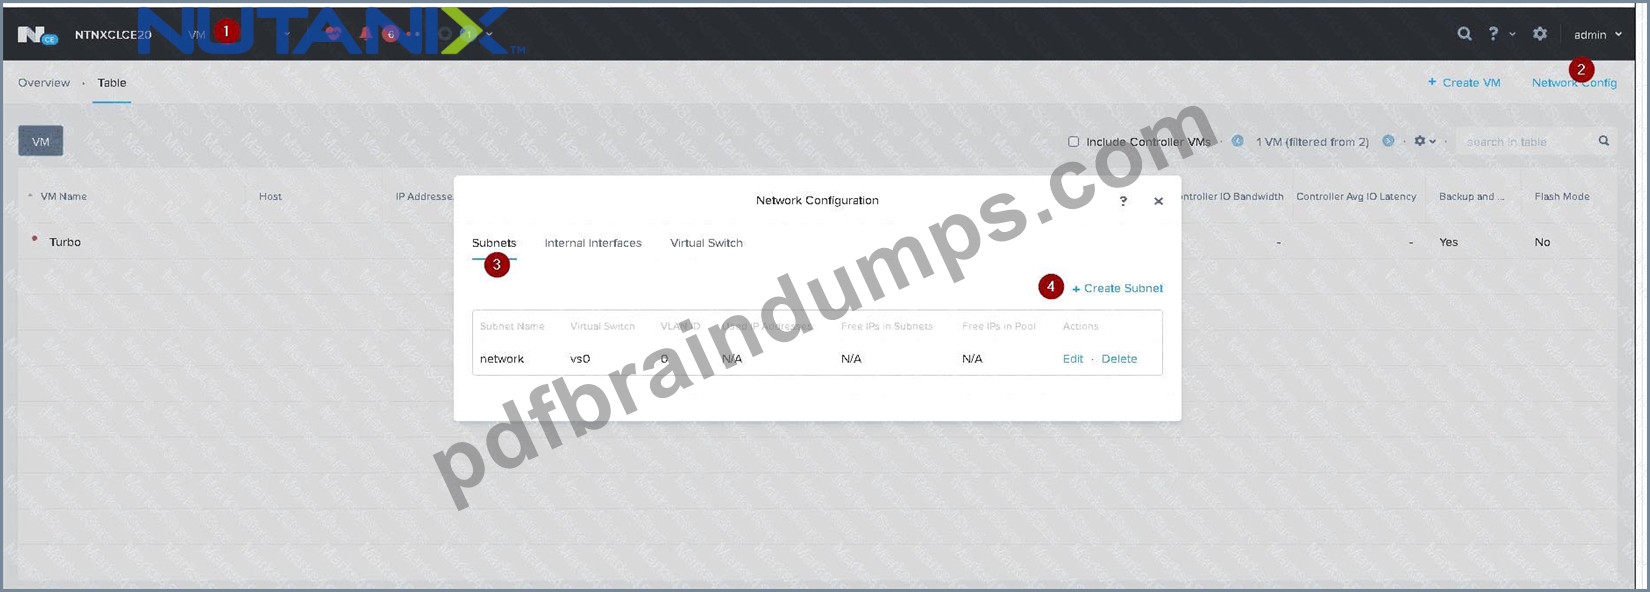
NEW QUESTION # 24
......
Our NCM-MCI-6.10 guide questions are suitable for various people. No matter you are students, office workers or common people, you can have a try. For our NCM-MCI-6.10 practice braindumps are famous for th e reason that they are high-effective. We can claim that if you study with them for 20 to 30 hours, then you can take part in the NCM-MCI-6.10 Exam confidently if you finish all learning tasks. The NCM-MCI-6.10 certificate issued by official can inspire your enthusiasm.
NCM-MCI-6.10 Questions Pdf: https://www.pdfbraindumps.com/NCM-MCI-6.10_valid-braindumps.html
2026 Latest PDFBraindumps NCM-MCI-6.10 PDF Dumps and NCM-MCI-6.10 Exam Engine Free Share: https://drive.google.com/open?id=1qzoTjpFRMnckkG0lprlDexBRbTKt76Xl