Databricks-Certified-Data-Analyst-Associate Quiz Guide - Databricks-Certified-Data-Analyst-Associate Exam Prep & Databricks-Certified-Data-Analyst-Associate Test Braindumps
P.S. Free 2026 Databricks Databricks-Certified-Data-Analyst-Associate dumps are available on Google Drive shared by Free4Torrent: https://drive.google.com/open?id=1SCFkq57sSRAap0L76-5LMSF3Tb73vrEo
Moreover, you do not need an active internet connection to utilize Free4Torrent desktop Databricks Certified Data Analyst Associate Exam practice exam software. It works without the internet after software installation on Windows computers. The Free4Torrent web-based Databricks Databricks-Certified-Data-Analyst-Associate Practice Test requires an active internet and it is compatible with all operating systems.
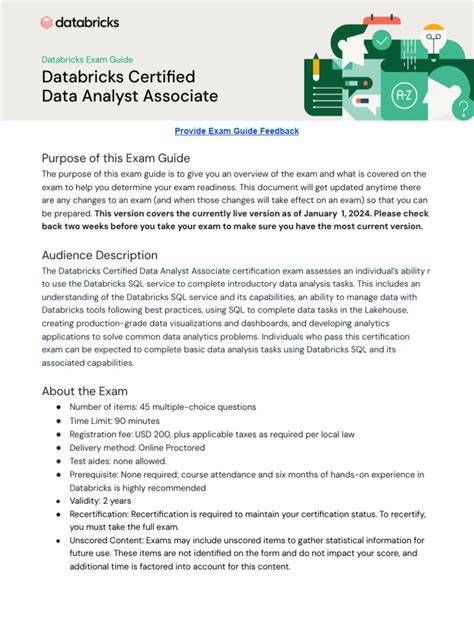
Databricks Databricks-Certified-Data-Analyst-Associate Exam Overview:
>> Databricks-Certified-Data-Analyst-Associate Reliable Dump <<
Databricks Databricks-Certified-Data-Analyst-Associate Exam Dumps Provider | Databricks-Certified-Data-Analyst-Associate New Dumps
These Databricks Databricks-Certified-Data-Analyst-Associate practice tests simulate the real Databricks Certified Data Analyst Associate Exam (Databricks-Certified-Data-Analyst-Associate) exam pattern, track your progress, and help you overcome mistakes. Our Databricks Certified Data Analyst Associate Exam (Databricks-Certified-Data-Analyst-Associate) desktop software is compatible with Windows. Whereas, the web-based Databricks Databricks-Certified-Data-Analyst-Associate Practice Exam works online on iOS, Linux, Android, Windows, and Mac. Additionally, the web-based Databricks Certified Data Analyst Associate Exam (Databricks-Certified-Data-Analyst-Associate) practice exam is also compatible with MS Edge, Internet Explorer, Opera, Firefox, Safari, and Chrome.
| Topic | Details |
|---|
| Topic 1 | - Data Management: The topic describes Delta Lake as a tool for managing data files, Delta Lake manages table metadata, benefits of Delta Lake within the Lakehouse, tables on Databricks, a table owner’s responsibilities, and the persistence of data. It also identifies management of a table, usage of Data Explorer by a table owner, and organization-specific considerations of PII data. Lastly, the topic it explains how the LOCATION keyword changes, usage of Data Explorer to secure data.
|
| Topic 2 | - SQL in the Lakehouse: It identifies a query that retrieves data from the database, the output of a SELECT query, a benefit of having ANSI SQL, access, and clean silver-level data. It also compares and contrasts MERGE INTO, INSERT TABLE, and COPY INTO. Lastly, this topic focuses on creating and applying UDFs in common scaling scenarios.
|
| Topic 3 | - Analytics applications: It describes key moments of statistical distributions, data enhancement, and the blending of data between two source applications. Moroever, the topic also explains last-mile ETL, a scenario in which data blending would be beneficial, key statistical measures, descriptive statistics, and discrete and continuous statistics.
|
| Topic 4 | - Data Visualization and Dashboarding: Sub-topics of this topic are about of describing how notifications are sent, how to configure and troubleshoot a basic alert, how to configure a refresh schedule, the pros and cons of sharing dashboards, how query parameters change the output, and how to change the colors of all of the visualizations. It also discusses customized data visualizations, visualization formatting, Query Based Dropdown List, and the method for sharing a dashboard.
|
| Topic 5 | - Databricks SQL: This topic discusses key and side audiences, users, Databricks SQL benefits, complementing a basic Databricks SQL query, schema browser, Databricks SQL dashboards, and the purpose of Databricks SQL endpoints
- warehouses. Furthermore, the delves into Serverless Databricks SQL endpoint
- warehouses, trade-off between cluster size and cost for Databricks SQL endpoints
- warehouses, and Partner Connect. Lastly it discusses small-file upload, connecting Databricks SQL to visualization tools, the medallion architecture, the gold layer, and the benefits of working with streaming data.
|
Databricks Certified Data Analyst Associate Exam Sample Questions (Q89-Q94):
NEW QUESTION # 89
A data analyst at an e-commerce company needs to process daily sales data. The data consists of approximately 50,000 records stored in a single CSV file, totaling about 20 MB. The analyst needs to perform aggregations and generate a summary report.
Which approach could the data analyst use in this situation?
- A. Use a local Python script with the pandas library to read and analyze the CSV file.
- B. Set up a Hadoop ecosystem with HDFS and MapReduce for distributed processing.
- C. Deploy a real-time streaming solution using Spark Streaming to process incoming data.
- D. Implement Apache Spark with a distributed cluster to process the data in parallel.
Answer: A
Explanation:
Option B is correct. A 20 MB CSV file with about 50,000 records is small enough for a local pandas workflow. A real-time streaming solution, a distributed Spark cluster, or Hadoop MapReduce would add unnecessary complexity for a small single-file batch analysis. Databricks documentation explains that pandas is available in Databricks Runtime and can be used for data analysis, while pandas API on Spark is useful when pandas-style workloads need to scale beyond smaller datasets. Databricks also notes that pandas does not scale out to big data, which is exactly why Spark or pandas API on Spark is used for larger workloads, not for a small 20 MB file.
NEW QUESTION # 90
A data engineer is running code in a Databricks Repo that is cloned from a central Git repository. A colleague informs them that changes have been made and synced to the central Git repository. The data engineer now needs to sync their Databricks Repo to get the changes from the central Git repository.
Which of the following Git operations does the data engineer need to run to accomplish this task?
- A. Pull
- B. Merge
- C. Clone
- D. Commit
- E. Push
Answer: A
Explanation:
Option C is correct. To retrieve changes from a remote central Git repository into a local Databricks Git folder
/Repo, the correct Git operation is Pull. Push sends local commits to the remote repository. Commit records local changes. Clone creates a new local copy. Merge combines branches but is not the operation described here. Official Databricks extract: "To pull changes from the remote Git repository, click Pull."
NEW QUESTION # 91
A data analyst has created a Query in Databricks SQL, and now wants to create two data visualizations from that Query and add both of those data visualizations to the same Databricks SQL Dashboard.
Which step will the data analyst need to take when creating and adding both data visualizations to the Databricks SQL Dashboard?
- A. Alter the Query to return two separate sets of results.
- B. Decide on a single data visualization to add to the dashboard.
- C. Add two separate visualizations to the dashboard based on the same Query.
- D. Copy the Query and create one data visualization per query.
Answer: C
Explanation:
Databricks SQL allows you to create multiple visualizations from a single query result. These visualizations can be customized independently and each can be added to a dashboard. This feature is explicitly supported and recommended in Databricks' documentation on dashboards and visualization workflows, enabling flexible reporting without duplicating queries.
NEW QUESTION # 92
A data analyst has created a user-defined function using the following line of code:
CREATE FUNCTION price(spend DOUBLE, units DOUBLE)
RETURNS DOUBLE
RETURN spend / units;
Which of the following code blocks can be used to apply this function to the customer_spend and customer_units columns of the table customer_summary to create column customer_price?
- A. SELECT price(customer_spend, customer_units) AS customer_price FROM customer_summary
- B. SELECT price FROM customer_summary
- C. SELECT double(price(customer_spend, customer_units)) AS customer_price FROM customer_summary
- D. SELECT PRICE customer_spend, customer_units AS customer_price FROM customer_summary
- E. SELECT function(price(customer_spend, customer_units)) AS customer_price FROM customer_summary
Answer: A
Explanation:
A user-defined function (UDF) is a function defined by a user, allowing custom logic to be reused in the user environment1. To apply a UDF to a table, the syntax is SELECT udf_name(column_name) AS alias FROM table_name2. Therefore, option E is the correct way to use the UDF price to create a new column customer_price based on the existing columns customer_spend and customer_units from the table customer_summary. Reference:
What are user-defined functions (UDFs)?
User-defined scalar functions - SQL
V
NEW QUESTION # 93
A data analyst creates a Databricks SQL Query where the result set has the following schema:
region STRING
number_of_customer INT
When the analyst clicks on the "Add visualization" button on the SQL Editor page, which of the following types of visualizations will be selected by default?
- A. There is no default. The user must choose a visualization type.
- B. IBar Chart
- C. Line Chart
- D. Histogram
- E. Violin Chart
Answer: B
Explanation:
According to the Databricks SQL documentation, when a data analyst clicks on the "Add visualization" button on the SQL Editor page, the default visualization type is Bar Chart. This is because the result set has two columns: one of type STRING and one of type INT. The Bar Chart visualization automatically assigns the STRING column to the X-axis and the INT column to the Y-axis. The Bar Chart visualization is suitable for showing the distribution of a numeric variable across different categories. Reference: Visualization in Databricks SQL, Visualization types
NEW QUESTION # 94
......
Databricks-Certified-Data-Analyst-Associate Exam Dumps Provider: https://www.free4torrent.com/Databricks-Certified-Data-Analyst-Associate-braindumps-torrent.html
- Test Databricks-Certified-Data-Analyst-Associate Dumps Pdf 📉 Databricks-Certified-Data-Analyst-Associate Valid Braindumps 🤙 Reliable Databricks-Certified-Data-Analyst-Associate Exam Blueprint 🦼 Search for ✔ Databricks-Certified-Data-Analyst-Associate ️✔️ and download it for free on ▷ www.dumpsmaterials.com ◁ website 🎱Questions Databricks-Certified-Data-Analyst-Associate Pdf
- 2026 Realistic Databricks Databricks-Certified-Data-Analyst-Associate Reliable Dump 🍆 Search for { Databricks-Certified-Data-Analyst-Associate } and download it for free on ( www.pdfvce.com ) website 📀Valid Test Databricks-Certified-Data-Analyst-Associate Test
- www.prepawayete.com Databricks Databricks-Certified-Data-Analyst-Associate Desktop Practice Exam Software 🌎 Search for 【 Databricks-Certified-Data-Analyst-Associate 】 and download it for free on “ www.prepawayete.com ” website 🎩Latest Databricks-Certified-Data-Analyst-Associate Exam Review
- Use Databricks Databricks-Certified-Data-Analyst-Associate Dumps To Deal With Exam Anxiety 📱 Copy URL 【 www.pdfvce.com 】 open and search for 「 Databricks-Certified-Data-Analyst-Associate 」 to download for free 🛕Databricks-Certified-Data-Analyst-Associate Test Cram
- Databricks-Certified-Data-Analyst-Associate Valid Braindumps 📱 Valid Databricks-Certified-Data-Analyst-Associate Exam Pattern 👕 Databricks-Certified-Data-Analyst-Associate Reliable Exam Pass4sure 🎦 Download ➥ Databricks-Certified-Data-Analyst-Associate 🡄 for free by simply searching on ⇛ www.dumpsquestion.com ⇚ 🎇Valid Test Databricks-Certified-Data-Analyst-Associate Test
- 2026 The Best Databricks-Certified-Data-Analyst-Associate – 100% Free Reliable Dump | Databricks-Certified-Data-Analyst-Associate Exam Dumps Provider 🔈 Open ➠ www.pdfvce.com 🠰 and search for ▛ Databricks-Certified-Data-Analyst-Associate ▟ to download exam materials for free 🧜Databricks-Certified-Data-Analyst-Associate VCE Exam Simulator
- www.examdiscuss.com Databricks Databricks-Certified-Data-Analyst-Associate Desktop Practice Exam Software 🎁 Copy URL ⏩ www.examdiscuss.com ⏪ open and search for ➠ Databricks-Certified-Data-Analyst-Associate 🠰 to download for free 😽Databricks-Certified-Data-Analyst-Associate Reliable Exam Pass4sure
- Databricks Certified Data Analyst Associate Exam practice certkingdom dumps - Databricks-Certified-Data-Analyst-Associate pdf training torrent ☣ Download ▷ Databricks-Certified-Data-Analyst-Associate ◁ for free by simply searching on ⏩ www.pdfvce.com ⏪ 💥Trustworthy Databricks-Certified-Data-Analyst-Associate Pdf
- Pass Guaranteed Quiz 2026 Databricks Databricks-Certified-Data-Analyst-Associate: Databricks Certified Data Analyst Associate Exam Perfect Reliable Dump 🏫 The page for free download of ➠ Databricks-Certified-Data-Analyst-Associate 🠰 on ⮆ www.vce4dumps.com ⮄ will open immediately 💌Latest Test Databricks-Certified-Data-Analyst-Associate Discount
- Questions Databricks-Certified-Data-Analyst-Associate Pdf 🚃 Test Databricks-Certified-Data-Analyst-Associate Dumps Pdf 📃 Databricks-Certified-Data-Analyst-Associate Authorized Test Dumps 😛 Simply search for ▶ Databricks-Certified-Data-Analyst-Associate ◀ for free download on 【 www.pdfvce.com 】 🧉Databricks-Certified-Data-Analyst-Associate Training Tools
- Use www.verifieddumps.com Databricks Databricks-Certified-Data-Analyst-Associate Desktop Practice Exam Software Without Internet 🤬 Search on ➠ www.verifieddumps.com 🠰 for ⏩ Databricks-Certified-Data-Analyst-Associate ⏪ to obtain exam materials for free download 🦑Reliable Databricks-Certified-Data-Analyst-Associate Exam Pdf
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, rare-books.library.sites.carleton.edu, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, gracebook.app, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, rare-books.library.sites.carleton.edu, schoolido.lu, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.dibiz.com, Disposable vapes
What's more, part of that Free4Torrent Databricks-Certified-Data-Analyst-Associate dumps now are free: https://drive.google.com/open?id=1SCFkq57sSRAap0L76-5LMSF3Tb73vrEo