As for the Databricks-Certified-Professional-Data-Engineer study materials themselves, they boost multiple functions to assist the learners to learn the study materials efficiently from different angles. For example, the function to stimulate the Databricks-Certified-Professional-Data-Engineer exam can help the exam candidates be familiar with the atmosphere and the pace of the Real Databricks-Certified-Professional-Data-Engineer Exam and avoid some unexpected problem occur such as the clients answer the questions in a slow speed and with a very anxious mood which is caused by the reason of lacking confidence.
Databricks Certified Professional Data Engineer Exam is a certification program designed for data professionals who want to demonstrate their expertise in building, deploying, and maintaining data engineering solutions using Databricks. Databricks-Certified-Professional-Data-Engineer exam covers a wide range of topics related to data engineering and requires a thorough understanding of Databricks data engineering concepts and techniques. Databricks-Certified-Professional-Data-Engineer exam is challenging and requires the candidate to demonstrate their ability to perform specific tasks using Databricks.
Databricks Certified Professional Data Engineer (Databricks-Certified-Professional-Data-Engineer) Exam is a certification exam designed to test the knowledge and skills of data engineers who use Databricks to build and manage data pipelines. Databricks is a cloud-based data processing and analytics platform that provides a unified workspace for data scientists, data engineers, and business analysts to collaborate and work with large-scale data. Databricks-Certified-Professional-Data-Engineer Exam is intended for data engineers who have experience in developing and maintaining data pipelines using Databricks and are looking to validate their skills and knowledge.
>> New APP Databricks-Certified-Professional-Data-Engineer Simulations <<
Generally speaking, passing the exam is what the candidates wish. Our Databricks-Certified-Professional-Data-Engineer exam braindumps can help you pass the exam just one time. And in this way, your effort and time spend on the practicing will be rewarded. Databricks-Certified-Professional-Data-Engineer training materials offer you free update for one year, so that you can know the latest information for the exam timely. In addition, Databricks-Certified-Professional-Data-Engineer Exam Dumps cover most of the knowledge point for the exam, and you can pass the exam as well as improve your ability in the process of learning. Online and offline chat service is available for Databricks-Certified-Professional-Data-Engineer learning materials, if you have any questions for Databricks-Certified-Professional-Data-Engineer exam dumps, you can have a chat with us.
Databricks Certified Professional Data Engineer exam is a practical and hands-on exam that requires candidates to demonstrate their ability to design and implement data pipelines using Databricks. Databricks-Certified-Professional-Data-Engineer exam consists of multiple-choice questions and hands-on exercises that test the candidate's ability to apply their knowledge to real-world scenarios. Databricks-Certified-Professional-Data-Engineer Exam is designed to be challenging, but fair, and it is intended to accurately assess a candidate's skills and knowledge.
NEW QUESTION # 139
The data engineering team maintains the following code:
Assuming that this code produces logically correct results and the data in the source tables has been de- duplicated and validated, which statement describes what will occur when this code is executed?
Answer: D
Explanation:
The provided PySpark code performs the following operations:
* Reads Data from silver_customer_sales Table:
* The code starts by accessing the silver_customer_sales table using the spark.table method.
* Groups Data by customer_id:
* The .groupBy("customer_id") function groups the data based on the customer_id column.
* Aggregates Data:
* The .agg() function computes several aggregate metrics for each customer_id:
* F.min("sale_date").alias("first_transaction_date"): Determines the earliest sale date for the customer.
* F.max("sale_date").alias("last_transaction_date"): Determines the latest sale date for the customer.
* F.mean("sale_total").alias("average_sales"): Calculates the average sale amount for the customer.
* F.countDistinct("order_id").alias("total_orders"): Counts the number of unique orders placed by the customer.
* F.sum("sale_total").alias("lifetime_value"): Calculates the total sales amount (lifetime value) for the customer.
* Writes Data to gold_customer_lifetime_sales_summary Table:
* The .write.mode("overwrite").table("gold_customer_lifetime_sales_summary") command writes the aggregated data to the gold_customer_lifetime_sales_summary table.
* The mode("overwrite") specifies that the existing data in the
gold_customer_lifetime_sales_summary table will be completely replaced by the new aggregated data.
Conclusion:
When this code is executed, it reads all records from the silver_customer_sales table, performs the specified aggregations grouped by customer_id, and then overwrites the entire gold_customer_lifetime_sales_summary table with the aggregated results. Therefore, option D accurately describes this process: "The gold_customer_lifetime_sales_summary table will be overwritten by aggregated values calculated from all records in the silver_customer_sales table as a batch job." References:
* PySpark DataFrame groupBy
* PySpark Basics
NEW QUESTION # 140
A Delta Lake table was created with the below query: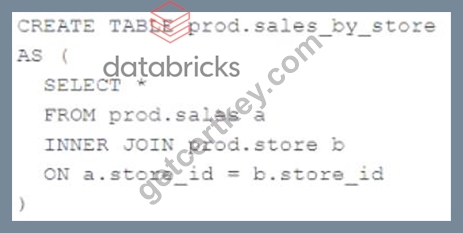
Consider the following query:
DROP TABLE prod.sales_by_store -
If this statement is executed by a workspace admin, which result will occur?
Answer: C
Explanation:
When a table is dropped in Delta Lake, the table is removed from the catalog and the data is deleted. This is because Delta Lake is a transactional storage layer that provides ACID guarantees. When a table is dropped, the transaction log is updated to reflect the deletion of the table and the data is deleted from the underlying storage. References:
* https://docs.databricks.com/delta/quick-start.html#drop-a-table
* https://docs.databricks.com/delta/delta-batch.html#drop-table
NEW QUESTION # 141
Which of the following section in the UI can be used to manage permissions and grants to tables?
Answer: D
Explanation:
Explanation
The answer is Data Explorer
NEW QUESTION # 142
Two data engineers are working on the same Databricks notebook in separate branches. Both have edited the same section of code. When one tries to merge the other's branch into their own using the Databricks Git folders UI, a merge conflict occurs on that notebook file. The UI highlights the conflict and presents options for resolution.
How should the data engineers resolve this merge conflict using Databricks Git folders?
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
In the Databricks Git folders integration, when merge conflicts arise in notebooks, the UI provides a visual diff editor that highlights conflicting code segments. Users can manually choose which changes to keep from each branch, edit directly in the notebook UI, and remove conflict markers.
After resolving, the engineer must mark the conflict as resolved, save, and commit the final version.
This process ensures that both contributors' valid code segments are merged correctly and version history is maintained.
Forcing a push (C) or deleting notebooks (B) introduces data loss or versioning issues. Aborting without review (A) violates collaborative best practices. Therefore, D is the only correct and Databricks-approved way to resolve notebook merge conflicts.
NEW QUESTION # 143
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).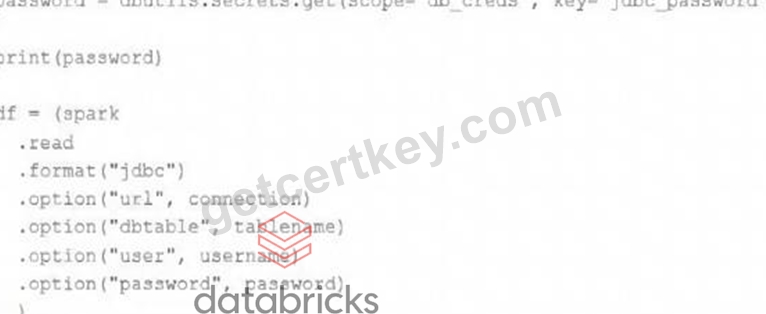
Which statement describes what will happen when the above code is executed?
Answer: D
Explanation:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks. Verified Reference: [Databricks Certified Data Engineer Professional], under "Security & Governance" section; Databricks Documentation, under "Secrets" section.
NEW QUESTION # 144
......
Latest Databricks-Certified-Professional-Data-Engineer Exam Questions: https://www.getcertkey.com/Databricks-Certified-Professional-Data-Engineer_braindumps.html