What's more, part of that Prep4sureGuide AI-200 dumps now are free: https://drive.google.com/open?id=1FG55m-sEoPQuyL4QtsxbO1WKQJYTmQnT
We are living in a good society; everything is changing so fast with the development of technology. So an ambitious person must be able to realize his dreams if he is willing to make efforts. Winners always know the harder they work the luckier they are. Our AI-200 practice materials are prepared for the diligent people craving for success. Almost all people pursuit a promising career, the reality is not everyone acts quickly and persistently. That is the reason why success belongs to few people.
| Section | Weight | Objectives |
|---|---|---|
| Secure, monitor, and optimize AI solutions | 20% | - Manage security and configuration
|
| Develop containerized AI solutions on Azure | 25% | - Implement container hosting environments
|
| Integrate backend services and build event-driven architectures | 25% | - Build serverless APIs and workflows
|
| Develop AI solutions using Azure data services | 30% | - Design and optimize data access and retrieval
|
You can run the Developing AI Cloud Solutions on Azure AI-200 PDF Questions file on any device laptop, smartphone or tablet, etc. You just need to memorize all AI-200 exam questions in the pdf dumps file. Microsoft AI-200 practice test software (Web-based and desktop) is specifically useful to attempt the AI-200 Practice Exam. It has been a proven strategy to pass professional exams like the Microsoft AI-200 exam in the last few years. Developing AI Cloud Solutions on Azure AI-200 practice test software is an excellent way to engage candidates in practice.
NEW QUESTION # 125
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You plan to deploy a container to an Azure App Service API app named api1. You host the source code for api1 in a GitHub repository. The container uses the API key at runtime to connect to a backend service.
The container must be able to retrieve the API key at runtime without exposing it in the source repository or Git commit history.
You need to ensure that the API key remains outside of Git commit history and is available to the container at runtime.
Solution: Store the API key in Azure Key Vault and reference it from an App Service application setting.
Does the solution meet the goal?
Answer: B
Explanation:
Correct:
* Store the API key in Azure Key Vault and reference it from an App Service application setting.
Storing the API key in Azure Key Vault and referencing it via App Service application settings is the recommended, secure approach. This strategy completely removes sensitive credentials from your GitHub repository and Git commit history while injecting them safely into your container environment at runtime.
Incorrect:
* Embed the API key as a hardcoded environment variable in the Dockerfile.
* Store the API key as a GitHub repository secret.
Reference:
https://www.qservicesit.com/full-stack-applications-on-azure
NEW QUESTION # 126
You need to configure vector embedding updates according to the business and technical requirements.
Which information should you use? To answer, select the appropriate option in the answer area.
NOTE: Each correct selection is worth one point.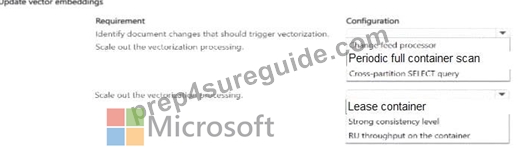
Answer:
Explanation: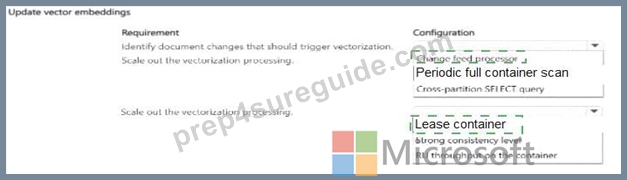
Explanation: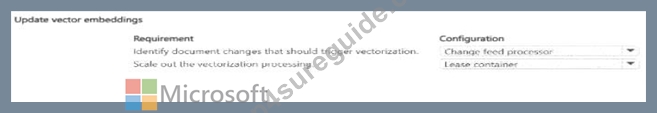
Verified Answer: Identify document changes: Change feed processor. Scale out vectorization processing:
Lease container.
Detailed Explanation: The change feed processor is designed to react to inserts and updates in a monitored Cosmos DB container, which directly matches the requirement to generate embeddings for new or changed documents. Its lease container stores processing state and coordinates work across multiple workers, allowing the processing workload to scale out without duplicating ownership of change-feed ranges. A periodic full scan would consume unnecessary RUs, and neither strong consistency nor container RU throughput is the coordination mechanism for distributed change-feed workers.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Azure Cosmos DB change feed processor
NEW QUESTION # 127
Hotspot Question
You are troubleshooting latency issues by using the requests table in Azure Monitor.
You need to calculate the average request duration grouped by cloud role name and also limit results to the past 30 minutes.
Which code elements should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.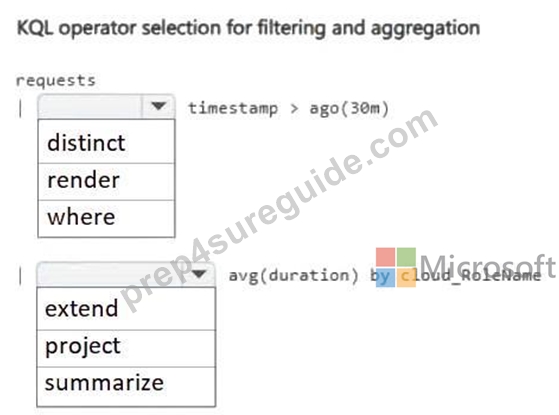
Answer:
Explanation: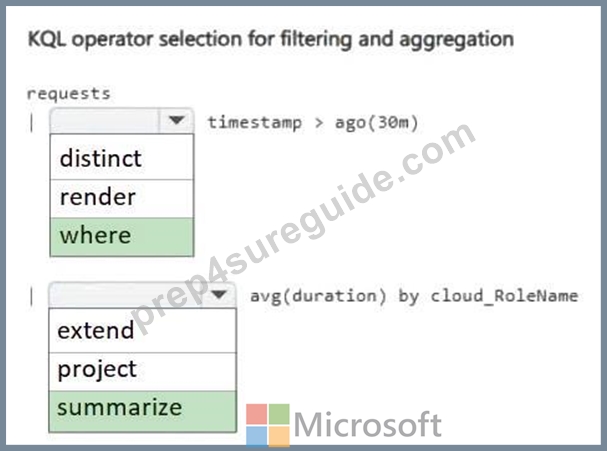
Explanation:
Box 1: where
In Kusto Query Language (KQL), the where operator filters the rows of a table to only include records that satisfy a specific predicate or condition.
Box 2: summarize
summarize is used for aggregations (count, avg, percentiles).
Reference:
https://world.optimizely.com/blogs/K-Khan-/Dates/2025/12/troubleshooting-with-azure-application-insights-using-kql
NEW QUESTION # 128
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
You need to configure Azure Functions to generate vector embeddings according to planned environment application architecture.
Which trigger type should you use?
Answer: A
Explanation:
The most appropriate trigger type for this architecture is the Azure Cosmos DB Trigger.
This trigger monitors your NoSQL container's underlying change feed. When a document is created or modified, the function fires automatically, processes the data, generates the embedding, and places a message in Azure Service Bus.
Scenario, Planned Application Architecture
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/integrated-embeddings
NEW QUESTION # 129
You need to configure vector embedding updates according to the business and technical requirements.
Which information should you use? To answer, select the appropriate option in the answer area.
NOTE: Each correct selection is worth one point.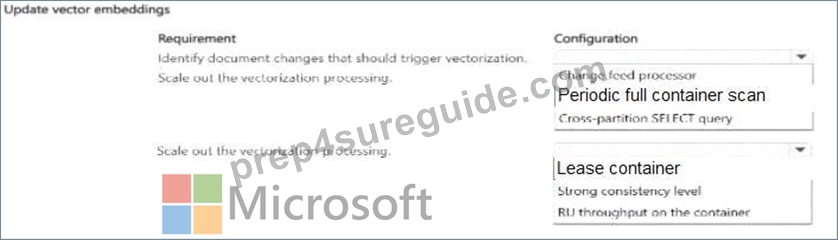
Answer:
Explanation: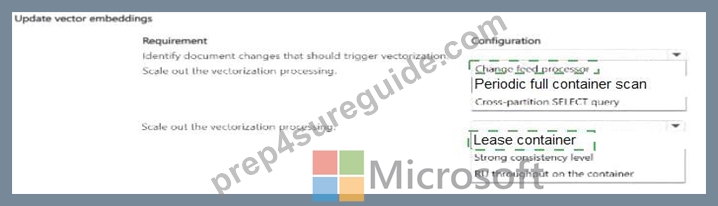
Explanation: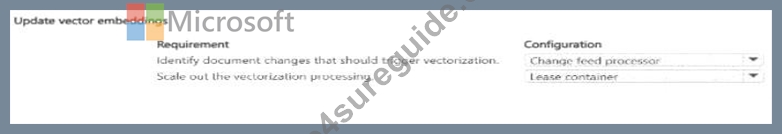
Verified answer: Identify document changes: Change feed processor. Scale out vectorization processing:
Lease container.
Detailed Explanation: The change feed processor is designed to react to inserts and updates in a monitored Cosmos DB container, which directly matches the requirement to generate embeddings for new or changed documents. Its lease container stores processing state and coordinates work across multiple workers, allowing the processing workload to scale out without duplicating ownership of change-feed ranges. A periodic full scan would consume unnecessary RUs, and neither strong consistency nor container RU throughput is the coordination mechanism for distributed change-feed workers.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Azure Cosmos DB change feed processor
NEW QUESTION # 130
......
How to get to heaven? Shortcart is only one. Which is using Prep4sureGuide's Microsoft AI-200 Exam Training materials. This is the advice to every IT candidate, and hope you can reach your dream of paradise.
AI-200 Valid Exam Book: https://www.prep4sureguide.com/AI-200-prep4sure-exam-guide.html
2026 Latest Prep4sureGuide AI-200 PDF Dumps and AI-200 Exam Engine Free Share: https://drive.google.com/open?id=1FG55m-sEoPQuyL4QtsxbO1WKQJYTmQnT