BTW, DOWNLOAD part of PrepAwayETE HPE7-J01 dumps from Cloud Storage: https://drive.google.com/open?id=1f2OW52Wiv1d8gqQ0fNwkXGwQLL8c0rh8
For HP HPE7-J01 certification test, are you ready? The exam comes in sight, but can you take the test with confidence? If you have not confidence to sail through your exam, here I will recommend the most excellent reference materials for you. The latest HPE7-J01 Certification Training dumps that can pass your exam in a short period of studying have appeared. The dumps are provided by PrepAwayETE.
| Section | Objectives |
|---|---|
| Topic 1: Data Protection and Availability | - High availability design considerations - Backup, replication, and disaster recovery concepts |
| Topic 2: HPE Storage Architecture Overview | - Enterprise storage fundamentals and architectures - HPE storage portfolio positioning |
| Topic 3: Performance and Capacity Planning | - Workload analysis and sizing - Performance optimization techniques |
| Topic 4: Storage Security and Best Practices | - Data encryption and access control - Secure storage architecture design |
| Topic 5: SAN and NAS Technologies | - Fibre Channel and iSCSI fundamentals - NAS protocols and file services |
| Topic 6: Hybrid Cloud and Data Mobility | - Data migration and mobility strategies - Hybrid cloud storage integration |
| Topic 7: HPE Storage Platforms and Solutions | - HPE Primera and Nimble storage solutions - HPE Alletra storage systems - Legacy HPE 3PAR architecture concepts |
>> HPE7-J01 Cost Effective Dumps <<
With HPE7-J01 practice test questions you can not only streamline your exam HP HPE7-J01 exam preparation process but also feel confident to pass the challenging HPE7-J01 Exam easily. One of the top features of HP HPE7-J01 valid dumps is their availability in different formats.
NEW QUESTION # 38
A customer has a diverse NoSQL big data and data analytics workload implementation. This workload runs on bare-metal servers to achieve the most efficient performance. The customer requires a new storage solution to meet their growing data needs. Which solution will be best for the customer?
Answer: B
Explanation:
For workloads like NoSQL databases (e.g., MongoDB, Cassandra), Big Data analytics (e.g., Hadoop, Spark), and high-throughput data lakes, the primary performance bottleneck is often the latency and bandwidth between the compute and the storage media. When a customer specifies they are running on bare- metal servers to achieve "most efficient performance," they are looking for a solution that minimizes the overhead of hypervisors and provides direct, high-speed access to storage.
The HPE Alletra Storage Server 4000 series, and specifically the Alletra 4110, is purposefully engineered for this "Data-First" server-based storage market. The Alletra 4110 is a 1U, all-NVMe ultra-dense storage server that supports dual 4th or 5th Gen Intel Xeon Scalable processors and PCIe Gen5 throughput. Unlike traditional storage arrays that connect via a SAN, the Alletra 4110 functions as high-performance Software- Defined Storage (SDS) infrastructure. It is designed to run the application and the data storage on the same high-density nodes, or to act as a high-speed storage tier for bare-metal clusters.
Other options are less suitable for this specific "bare-metal NoSQL" requirement:
* HPE SimpliVity (B) is a Hyperconverged Infrastructure (HCI) solution that is inherently tied to a hypervisor (VMware or Hyper-V), which contradicts the customer's bare-metal requirement.
* HPE Alletra dHCI (C) is a disaggregated HCI solution that automates a SAN environment but is also centered around VMware virtualization.
* HPE GreenLake for Private Cloud Business Edition (A) is a service-oriented offering primarily for managing virtualized private clouds.
The Alletra 4110 provides the massive I/O throughput (up to 315 GB/s of PCIe Gen5 bandwidth to SSDs) and the low-latency NVMe performance that NoSQL and analytics workloads demand, making it the superior architectural choice for bare-metal, data-intensive environments.
NEW QUESTION # 39
An HPE customer purchased an HPE B-Series SN7000B SAN fabric switch. QoS is currently not enabled.
Which two statements are correct regarding buffer-to-buffer (BB) credits and the operation of the switch?
(Choose two.)
Answer: B,C
Explanation:
The HPE B-Series SN7000B is a high-performance Director based on Brocade Gen 7 (G7) technology.
Buffer-to-Buffer (BB) credits are the fundamental flow-control mechanism used in Fibre Channel to prevent frame loss and manage congestion.
Statement D is a foundational principle of SAN architecture: BB credits are based on link speed and frame size. In an FC fabric, the number of credits required to "fill the pipe" (keep data moving without waiting for acknowledgments) is a direct function of the Round Trip Time (RTT), which is determined by the physical distance, the speed of the link (e.g., 64Gb/s vs 32Gb/s), and the size of the frames being sent (typically 2KB).
As link speeds increase, more buffer credits are required to maintain full throughput over the same distance.
Statement C reflects a specific technical default in the Brocade Fabric OS (FOS) for Gen 7 hardware. To ensure that ports can initialize and handle basic traffic immediately upon being enabled, the switch reserves a default number of credits from the ASIC's global buffer pool. For user ports on these high-density blades, the system reserves eight buffer credits per port, regardless of whether the port is currently online or offline.
This reservation ensures that the port has the minimum resources necessary to complete a fabric login (FLOGI) or negotiate a link without competing for pool resources.
Option E is incorrect because the entire pool is not reserved; a significant portion of the ASIC's buffers remains in a "shared pool" that can be dynamically allocated for long-distance links or high-demand ports via the "Extended Fabrics" feature. Option B is incorrect as it confuses the TCP windowing concept with FC credit-based flow control. Option A is incorrect because BB credits are a local port-to-port negotiation (link- level) and do not need a fabric-wide global "agreement" to form the fabric.
NEW QUESTION # 40
A customer is concerned about the long distances between their data centers and significant latencies that might exist between the SAN fabrics at the two data centers. Since SCSI write operations can involve multiple handshake messages between the target and initiator, which Brocade feature should be used to double the recommended distance, but maintain the same latency as a shorter haul link?
Answer: B
Explanation:
Standard SCSI write operations are inherently sensitive to distance because they require multiple round-trip handshakes before data is actually transmitted. A typical write involves: 1) the Command, 2) a Transfer Ready (XFER_RDY) response from the target, 3) the Data, and 4) the Status. In a long- distance SAN, each of these round trips adds significant "latency wait time," severely degrading performance as distance increases.
To solve this, Brocade (HPE B-series) utilizes a protocol optimization feature known as FastWrite.
FastWrite works by creating a Proxy Target (PT) local to the initiator host and a Proxy Initiator (PI) local to the target storage device. When the host issues a SCSI write command, the local Brocade switch (acting as the Proxy Target) immediately sends the XFER_RDY back to the host without waiting for the signal to travel across the long-distance link. This allows the host to send the data segment immediately. By eliminating the need for every handshake message to traverse the distance multiple times, FastWrite significantly reduces the aggregate latency felt by the application. Architecturally, this enables customers to extend their SAN fabrics over double the distance (and often much further) while maintaining performance comparable to a significantly shorter link. This is critical for asynchronous replication and remote copy applications that issue large I/O blocks.
NEW QUESTION # 41
An administrator has implemented automatic switchover (ASO) with Peer Persistence on a pair of HPE Alletra 6000 storage arrays. Which statement is correct regarding the ASO feature?
Answer: A
Explanation:
HPE Peer Persistence for the Alletra 6000 (and Nimble) provides synchronous replication and automatic transparent failover (ATF) using the Automatic Switchover (ASO) feature. This process is governed by a Quorum Witness that monitors the health of both arrays in a group. A fundamental design principle of HPE high-availability storage is to prevent "flapping"--a condition where a workload repeatedly bounces between two sites due to an unstable connection.
Consequently, the ASO process is designed to be unidirectional and sticky. When a primary site failure occurs and the Quorum Witness authorizes an automatic switchover, the secondary array becomes the "Upstream" (active) array and begins serving I/O. Once the original primary site is restored and the replication link is re-established, the arrays will automatically begin a resynchronization to ensure data consistency. However, even after the data is fully synced, the system will not automatically move the workload back to the original array. The administrator must perform a manual handover to return the volume collection to its preferred primary site.
NEW QUESTION # 42
An HPE Partner is sizing an Alletra MP B10000 array for a customer using the HPE Ninja Sizer online tool.
When tuning the solution, the partner is not getting the best read and write performance from the array.
Use your cursor to place a + where the partner can click in the web GUI to begin to determine how to correct this Issue and appropriately size the solution for the customer.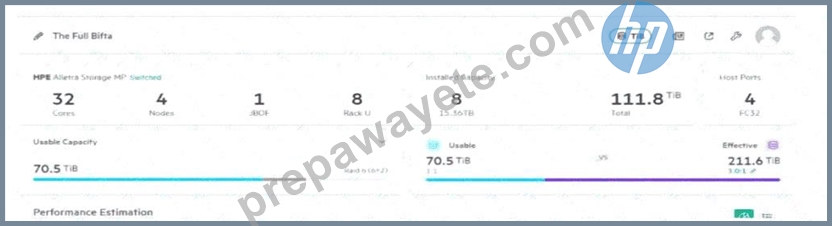
Answer:
Explanation: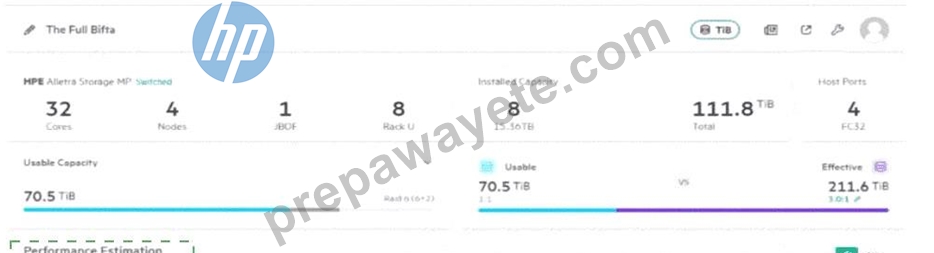
Explanation:
Performance Estimation
The HPE Ninja Sizer is a vital tool for storage architects to model the "Performance vs. Capacity" trade-offs of the HPE Alletra MP B10000 disaggregated architecture. In this scenario, the current configuration (as shown in the exhibit) consists of 4 nodes and 1 JBOF (with 8 drives of 15.36TB each).
To address poor read/write performance in Ninja Sizer, the partner must analyze the Performance Estimation pane. By clicking the chart/graph icon in the bottom right of the summary dashboard, the tool opens a detailed breakdown of the IOPS, throughput, and latency limits for the selected hardware. In a disaggregated shared-everything (DASE) architecture like the Alletra MP, performance is a direct function of the "node-to- drive" ratio. A configuration with only 8 drives (as seen in image_6491d0.png) may be "disk-bound," meaning the controllers have more compute power than the backend drive count can support in parallel.
By accessing the performance details, the partner can see if the bottleneck is at the node level (CPU/Cores) or the drive level (Flash bandwidth). To "correct this issue" and optimize the sizing, the partner would typically need to increase the drive count within the JBOF to allow for more parallel I/O streams or add additional JBOFs to scale the backend bandwidth. The Ninja Sizer provides real-time feedback; as the partner adds more
15.36TB drives, they will see the Performance Estimation bars move from yellow/red toward green, indicating an appropriately balanced solution that meets the customer's latency and throughput SLAs.
NEW QUESTION # 43
......
PrepAwayETE's HP Certification HPE7-J01 Exam testing exercises is very similar with real exam questions. If you choose PrepAwayETE's testing practice questions and answers, we will provide you with a year of free online update service. PrepAwayETE can 100% guarantee you to pass the exam, if you fail to pass the exam, we will full refund to you.
Test HPE7-J01 Valid: https://www.prepawayete.com/HP/HPE7-J01-practice-exam-dumps.html
2026 Latest PrepAwayETE HPE7-J01 PDF Dumps and HPE7-J01 Exam Engine Free Share: https://drive.google.com/open?id=1f2OW52Wiv1d8gqQ0fNwkXGwQLL8c0rh8